18 Nov 2026
 Drupal.org aggregator
DDEV Blog: SQL Sync for DDEV: Drush-Style Database Sync for Any SSH Server
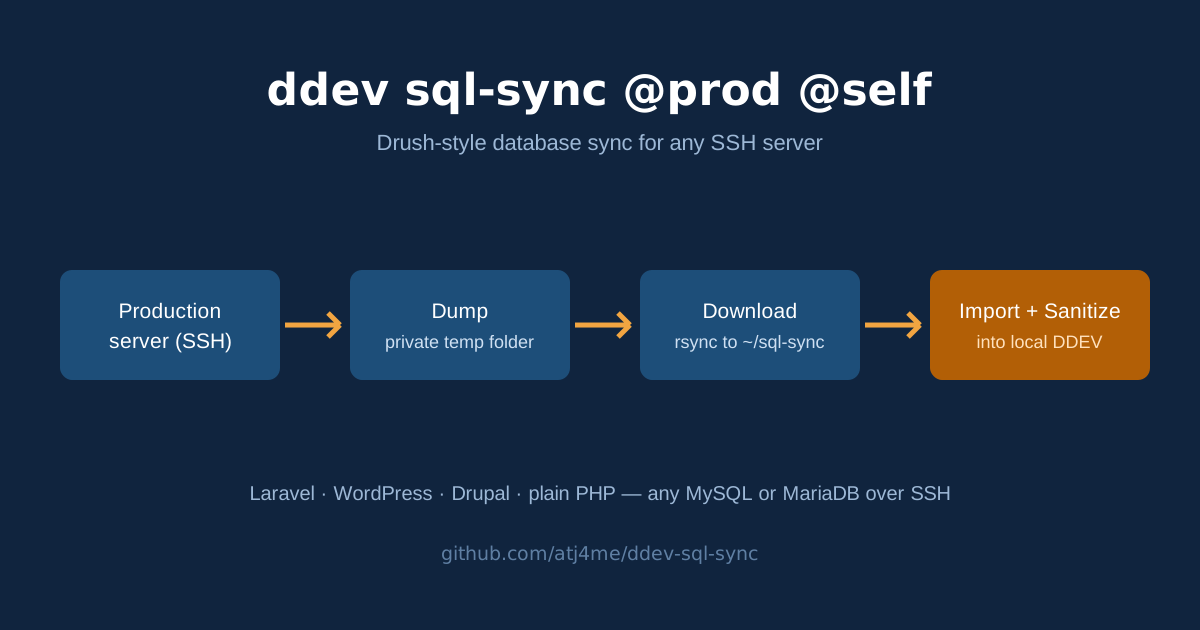
Anyone who has worked with Drupal knows this command:
drush sql-sync @prod @self
One command, and the local site has a copy of the production database.
I use Drush a lot, so I wanted the same thing for my personal projects. They are Laravel, WordPress and plain PHP sites, and they live on all sorts of hosting: shared accounts, VPSs, dedicated boxes - a good number of them running cPanel, which itself runs on shared and dedicated hosting alike. What I had instead was the usual mix of phpMyAdmin exports and one-off scripts that I had to remember each time.
DDEV does have pull providers. The ready-made ones are for hosted platforms like Pantheon and Acquia, but the examples it ships also include an rsync one, for pulling a dump down from a plain server over SSH. I do not want to overstate the gap: that example works. But it is a starting point you adapt, not a finished tool. Every project needs its own provider file, written and kept up to date separately, and sanitize is on you. I kept missing the Drush shape: one aliases file, the same command in every project, and sanitize taken care of. So this add-on is that shape, packaged: ddev-sql-sync.
One thing to state up front: I designed this add-on, and it was built and tested with the help of an AI agent, Ryan (Muse), working under my direction. There is a bit more about that at the end.
Where I use it:
- Refreshing local data. I can bring a local site up to date with production content before I start work on it.
- Debugging with real data. I can reproduce a production issue locally, with user emails and passwords already scrubbed.
- Any server I can SSH into. Shared hosting, a VPS, a dedicated server, with or without cPanel - if it runs MySQL or MariaDB, it works. There is no platform account or API in between.
How it Works
The configuration is one YAML file of named aliases, much like Drush site aliases. A run of ddev sql-sync @prod @self then does four things:
- Dump - SSH to the server and make a database dump in a private temp folder there.
- Download - rsync the dump to a local folder (by default
~/sql-sync), then delete the copy on the server. - Import -
ddev import-dbinto this project. You are asked to confirm first. The current local database is replaced. - Sanitize - scrub user emails and passwords in the local database. On by default.
Note the target in the command. cp, rsync, scp and Drush's own sql-sync all take a source and a destination, so this one does too. @self is the only target it accepts; anything else is refused. The add-on only ever reads from the server, and having the target in the command keeps that in front of you.
Prerequisites
Two things to sort out first:
-
SSH from your own machine. The add-on is a host command. It runs
sshandrsyncon your computer, using your~/.ssh/configand your keys, the same way you would by hand. It does not useddev auth ssh, and nothing SSHes from inside the web container. So this has to work first:ssh your-server-alias 'echo ok'If that asks for a password, set up key login first (
ssh-copy-id). If the host uses a different SSH port, which is common on shared hosting (most cPanel accounts, for instance), put the port in the~/.ssh/configentry for that alias. -
A way to dump the database on the server. If the app has an export tool of its own, the add-on uses that (see Dump strategies below). Otherwise the server needs
mysqldump. You do not have to guess: the--dry-runcheck further down will tell you if it is missing.
You also need DDEV v1.24.10 or later.
Installation
-
Install the add-on:
ddev add-on get atj4me/ddev-sql-sync -
Restart DDEV:
ddev restart
Installing the add-on creates .ddev/sql-sync/aliases.yml from the example that ships with it, if you do not have one yet. Add-on updates never overwrite your aliases.yml, and removing the add-on does not remove it either.
Configuration: .ddev/sql-sync/aliases.yml
This file is the whole configuration:
local:
  dir: ~/sql-sync # where downloaded dumps are kept

prod:
  host: myserver # an ~/.ssh/config alias or a hostname
  user: deploy # optional; ssh target becomes user@host
  root: /var/www/example # the app's path on the server
  tmp: /tmp # optional; temp folder on the server
Define as many aliases as you like (prod, staging, and so on) and pick one per run: ddev sql-sync @staging @self.
Each alias needs two keys, host and root. The optional keys:
| Key | Purpose |
|---|---|
platform: |
laravel, wordpress, drupal or php. Usually unset - see Platforms below. |
options: |
Extra SSH options, e.g. options: -i ~/.ssh/prod_key. |
jump: |
A jump host (bastion) passed to SSH as -J. Prefer ProxyJump in your ~/.ssh/config - that is the durable place; this key is for one-off syncs. |
dump: |
A command on the server whose output is the dump. Replaces the dump strategies below; works for any platform. |
database: |
Explicit database credentials, for setups where the app's config cannot supply them (see below). |
sanitize: |
Path, relative to the project root, to your own SQL file to sanitize with after import. |
Where the database credentials come from
Normally you do not configure any credentials at all. When it is time to dump, the add-on reads them from the app's own config on the server: .env for Laravel, wp-config.php for WordPress, sites/default/settings.php for Drupal.
For setups where that cannot work - a managed database host, or credentials split across files - an alias can pin the values itself:
prod:
  # ...
  database:
    name: example_db
    username: example_user
    password: example_password
    host: 127.0.0.1 # from the app server's perspective
    port: 3306
Any field you leave out falls back to the app's config, field by field. You can pin just the password, or just the host and port for an RDS-style endpoint.
Treat a filled-in
password:as a secret.aliases.ymlsits under.ddev/, which many projects gitignore - check yours - andchmod 600 .ddev/sql-sync/aliases.ymlis a good idea if you use this block. The password is passed to mysqldump through theMYSQL_PWDenvironment variable only, never as a command-line argument, and it is never printed.
Usage
ddev sql-sync @prod @self           # source, then target - like cp / rsync / drush sql-sync
ddev sql-sync @prod @self -y        # skip the confirmation prompt
ddev sql-sync @prod @self --dry-run # preflight checks only - nothing is dumped or imported
| Flag | Meaning |
|---|---|
--sanitize / --no-sanitize |
Sanitize after import (on by default), or skip it. Skipping prints a loud warning: the local database then holds real production emails and password hashes. |
--dump-dir=<path> |
Where the dump is downloaded to (overrides local.dir). |
--no-dump |
Do not make a new dump; fetch the dump file an earlier --no-sync run left on the server. It is verified against its completion marker before anything is imported. |
--no-sync |
Only create the dump on the server and leave it there; do not download, import, or sanitize. |
--dry-run |
Preflight only: check SSH, platform, dump strategy, credentials (the password is never shown), database size and disk space, then print the plan. Takes no dump, imports nothing, and writes nothing on the server. |
-y, --yes |
Do not ask for confirmation. |
-h, --help |
Show help. |
Downloaded dumps are saved as <dump-dir>/<alias>.sql - or <alias>.sql.gz, if the dump turns out to be gzipped - and kept after import, which is handy if you want to import the same dump again. They do contain production data, so delete them when you are done with them: rm ~/sql-sync/*.sql*.
Dump Strategies and Platforms
For each alias, the dump is made in one of these ways, in this order:
dump:override - if the alias sets one, it always wins.- The app's own export tool, run on the server in the app root, if the platform has one and it is installed there. If it is missing, the next strategy is used instead of failing:
- WordPress →
wp db export(WP-CLI) - Drupal →
drush sql-dump - Laravel → there is no native data export (
schema:dumpis structure-only), so Laravel always uses strategy 3.
- WordPress →
mysqldump- with credentials resolved as described above.
The run tells you which strategy it used.
The platform is worked out per alias: the alias's platform: key if you set one, else this project's DDEV type from .ddev/config.yaml (the laravel and wordpress types map to themselves, and every Drupal variant - drupal7 through drupal11 - maps to drupal), else php. Some notes per platform:
- Laravel / any
.envapp - credentials come from<root>/.env, under the usual Laravel key names (DB_DATABASE,DB_USERNAME, and so on). One caution: Bedrock-style WordPress uses different key names in its.env(DB_NAME,DB_USER), so for a Bedrock site, pin at least the name and username in the alias'sdatabase:block. - WordPress (classic) - credentials come from the
DB_*defines in<root>/wp-config.php, or one level up, as WordPress allows. The table prefix is read from the config, so sites with a prefix sanitize properly. - PHP (generic) - DDEV's generic
phptype, and the fallback when nothing else matches. No app export tool, so it always uses mysqldump. Credentials come from<root>/.envif there is one, merged under the alias'sdatabase:block - for a generic app, that block is the expected main source. There is no bundled sanitize: asanitize:file is honoured if you set one, otherwise the run reports that no sanitize ran. - Drupal - dump through Drush when it is available. Otherwise credentials are read from the default
$databasesentry insettings.php. That read is best-effort: a settings file that gets its credentials from the environment may not give them up, and then adump:override or a pinneddatabase:block is the way out. Asanitize:file on the alias, if set, takes precedence overdrush sql-sanitize.
Sanitize
Sanitize runs after the import, and only on the local database:
- Laravel - bundled SQL:
users.emailbecomesuser<id>@example.test,users.passwordbecomes a hash ofpassword,remember_tokenbecomesNULL. - WordPress - bundled SQL on the users table, using the site's actual table prefix: email becomes
user<id>@example.test, password becomesMD5('password'), which WordPress accepts at login and rehashes on its own. - Drupal -
ddev drush sql-sanitizewhen the local project has Drush; otherwise asanitize:file from the alias; if neither exists, the run says so. - Any platform - a
sanitize:file set on the alias is always honoured.
If sanitize is switched on but nothing could actually be applied, the run ends with "completed WITHOUT sanitize" and a non-zero exit code. It does not report success and leave live production data sitting in your local database.
What Happens on the Server
Since this runs against production, here is everything a run does there:
- It reads the app's config file to get the credentials.
- It creates one dump file in a subfolder of the alias's temp folder -
/tmp/ddev-dumpsby default. The folder is mode 700 and the dump mode 600, so on a shared server the other accounts cannot read it. If a run fails partway, the partial dump is removed rather than left behind. - On success, it writes a small completion marker next to the dump with the dump's exact size in bytes. The local side checks that size before trusting the file, including on a later
--no-dumprun, so a truncated dump is never imported as if it were whole. - After the download, it deletes the dump and the marker on the server. If the import itself then fails, the server copy is kept, and the run tells you how to retry with
--no-dump.
That is all. Nothing is written to the app or its database: no cache clears, no migrations, no restarts. Before dumping, the run also estimates the database size and stops if the temp filesystem has less free space than that, because a dump filling the disk is the one realistic way a sync could hurt a small server. If the size cannot be estimated, the run says the check was skipped instead of saying nothing.
Testing Safely
New server, or you would rather be careful? Work up in steps:
ddev sql-sync @prod @self --dry-run- preflight only, as above. You get a result per check, plus the plan, and then it stops.ddev sql-sync @prod @self --no-sync- a real dump, made on the server and left there. Nothing is downloaded or imported.ddev sql-sync @prod @self --no-dump- fetch that dump, verify it against its marker, import and sanitize.ddev sql-sync @prod @self- the full run.
Troubleshooting
- "mysqldump is not installed on this server" - the preflight found no
mysqldumpin the SSH session's PATH and no usable app export tool. Install the MariaDB/MySQL client tools on the server, or give the alias adump:command that makes the dump another way. - Credentials look right but authentication fails - check for a stale
~/.my.cnfon the server, in the sync user's home. A[client]password in that file silently overrides theMYSQL_PWDenvironment variable for MariaDB clients, this tool included. I ran into exactly this in my own testing. - The run asks for an SSH password or hangs - the add-on expects SSH without prompts. Test with
ssh your-server-alias 'echo ok'and fix your key setup first. - "unknown alias" - the name after
@has to match a top-level key inaliases.ymlexactly.
Uninstalling the Add-on
ddev add-on remove sql-sync
This removes the command and the files that came with it. Your aliases.yml and any downloaded dumps are left where they are - delete them yourself if you want them gone.
How This Add-on Was Made
My first instinct is usually a workaround with the tools I already know, and Tailscale and Drush have carried me through more situations than I can count. This one started the same way: a personal project needed its production database locally, and the sync had to suit my workflow. As noted at the top, I designed the add-on and an AI agent built and tested it under my direction. Before it was released, the code went through an independent read-only audit and an end-to-end rehearsal against a container standing in for a production server, and what those turned up was fixed. It is here in case it suits someone else's workflow too.
Additional Resources
- ddev-sql-sync on GitHub: source, issues, and the full README.
- Releases: release notes for every version.
- DDEV add-ons: how add-ons work and how to write your own.
- DDEV hosting providers: how
ddev pulland provider files work in DDEV itself. - rsync.yaml.example: DDEV's shipped example rsync provider - it runs inside the web container after
ddev auth ssh, and pulls a database dump and files tarball that already exist on the server. - Example providers: the
git.yaml.exampleandlocalfile.yaml.exampleexamples that ship alongside the rsync one. - Drush sql-sync: the command this add-on is modelled on.
I hope this helps anyone else who has wanted drush sql-sync for the sites they run outside Drupal. If you run into issues or have suggestions, feel free to open an issue on the GitHub repository.
18 Nov 2026 8:10pm GMT
DDEV Blog: Giving an AI Agent Its Own Linux User (Without Breaking DDEV)
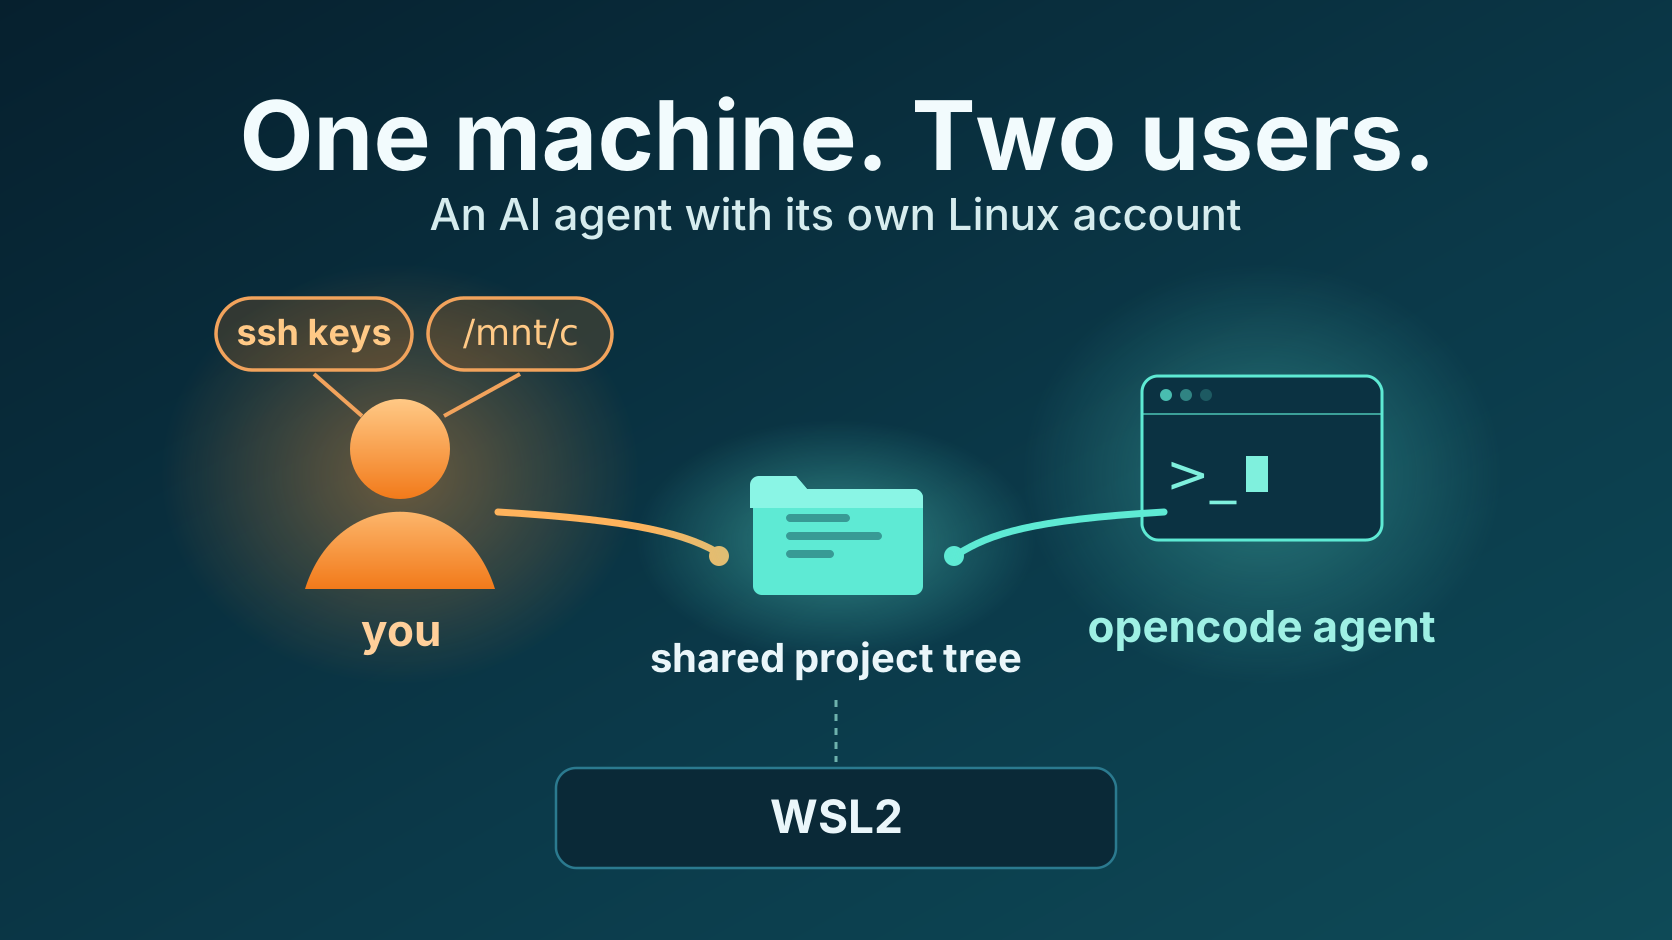
TL;DR: My coding agent runs on my WSL2 machine as its own Linux user, with its own home directory and its own rootless Docker daemon. DDEV runs as that same user, in my terminal and in the agent's. My workflow did not change. This post explains why I did it, what it took, and what broke along the way.
The surprise came quickly: My agent had a terminal open in a client project, about to run ddev composer install, and I wanted to know what it could reach if a task ever went sideways. The answer was: everything. The agent ran as my user, so it could read my SSH keys, push with my Git and gh credentials, reach everything on the Windows side through /mnt/c, and talk to a Docker daemon running as root. Its permission system asked before every Bash command, and I approved commands in five-second intervals, all day. At some point I stopped reading the prompts and clicked allow blindly. That was the moment I knew the agent and I needed a different kind of protection.
What an agent can do to your machine
An agent with a shell can wreck the machine it runs on (delete files, fill the disk), take it over (steal credentials, plant a backdoor, use the Docker socket), write code that does more than the task asked, ship private code and secrets somewhere else, or reach network services it was never meant to touch. Wherever it runs, those risks travel with it.
This post is about the second one: taking over the machine, through everything the agent can reach because it runs as my user. A separate Linux user shrinks exactly that blast radius. It does not stop malicious code from being written or project files from leaving; reviews and network policy are the answers there, and the end of this post is honest about what remains unsolved.
So I turned the question around. Instead of asking what I could withhold from the agent, I asked what the smallest identity is that still lets it do the job.
What an agent inherits when it runs as you
On a typical WSL2 setup, an agent running as your user inherits the blast radius of your account:
- Your home directory: SSH keys,
.gitconfig, credentials files, everything in~/.ddev, including database snapshots and any keys imported withddev auth ssh. - The Docker socket, which on a default rootful installation is root-equivalent.
- Windows interop:
/mnt/cand the ability to run.exefiles. On WSL2, the Linux side reaches straight into Windows; a shell command is all it takes.
Approval prompts don't solve this, because I stopped reading them. They had become background noise long before the agent got productive. Newer agents don't even ask that much: Claude Code has defaulted to auto mode since August 2026, which approves most commands on its own.
The old answer from Unix
Services on a Linux machine have not run as the admin's personal user for decades. www-data, postgres, deploy: every daemon gets a dedicated account with exactly the access it needs, and nobody considers that exotic. It is the default way to run untrusted or semi-trusted software on a shared machine.
An agent that edits my code, runs my tests, and starts my containers is a new coworker on the machine, and coworkers get their own account.
The obvious alternative, especially for DDEV users, is to run the agent inside the web container. I ruled that out, for a DDEV-specific reason. An agent inside the container cannot execute host commands itself, but it does not have to: through the shared project tree it stays writable for the agent, so it can plant a custom command in .ddev/commands/host/ and register it as a hook in .ddev/config.yaml. The next time I start the project, DDEV runs that hook on the host, as my user, with no container around it. The boundary has to hold on the host itself.
The other escape is the cloud: coder.ddev.com runs DDEV in a cloud workspace, not on your machine at all.
So that is what I did: the agent, opencode, now runs as a dedicated opencode user on my WSL2 box, and I kept the rest of the machine mine.
The setup, in four decisions
The whole architecture fits on a napkin:
       WSL2 machine: one machine, two users

  me (uid 1000)                opencode (uid N)
  shell, IDE, git              opencode agent
  browser, Windows interop     DDEV, rootless dockerd
        │                             │
        └──── ddev runs as opencode ──┘
                       ▼
     one DDEV home: /home/opencode/.ddev
     one rootless Docker daemon
     one working tree per project, shared
     through a group (setgid + default ACLs)
One: the agent gets its own user. My home directory is mode 750 and not group-shared, so the agent cannot read my keys or dotfiles. The agent user gets no Windows interop at all: no /mnt/c, no .exe execution. When a task needs to open something in my browser, the agent cannot do it. Only I can run that command, and then it works.
Two: DDEV runs as exactly one user, the agent's. This is the decision that makes or breaks the setup, and it is counterintuitive. DDEV is not multi-user aware; it expects one ~/.ddev, one Docker daemon, one project list. So the agent user owns DDEV. When I type ddev start in my own terminal, a shell function and a small sudoers helper re-exec it as opencode, with the right HOME and DOCKER_HOST. The sudoers file has four rules, all targeting opencode, none targeting root, none running anything as me. The result: ddev list in my terminal and in an agent session show the same projects, docker ps lists the same containers. There is one DDEV home, one daemon, no split-brain.
Three: the Docker backend is rootless and owned by the agent user. DDEV has supported Docker Rootless since v1.25.0 (blog post, docs). The daemon socket lives under /run/user/<uid>/, owned by opencode. The agent can start and stop containers for our projects, but it never touches a root-equivalent socket, because there isn't one on the machine anymore.
Four: we share the working tree through a group, not through an identity. Both users need to read and write the same project files. A shared group with setgid directories, default ACLs, and umask 002 does that. The agent edits a file, I edit the same file, git pull works from both sides, and nothing needs to run as the other person.
What it is like day to day
The agent can do every project task I do: ddev start, ddev composer, make tests, vendor/bin/runTests.sh -s [cgl|phpstan|unit|functional], and commit. It cannot read my SSH keys, cannot reach my home directory, cannot touch Windows, and has no path to root. Browser-opening commands like ddev launch and ddev mailpit still work, but only from my terminal.
The part I did not expect: permissions inside the agent became more meaningful, not less. As long as the agent ran as my user, my answer to every risk was bash: {"*": "ask"}. Every command needed approval, because a single one of them could read my SSH keys in my WSL home directory or on the Windows side. On its own user it cannot get there, so I could flip the rules: allow Bash by default, and ask only for the few sensitive paths, like auth.json. The prompts that remain are the ones worth reading, because they are about the task, not about the keys to the building.
What still hurts
Two UIDs, one working tree: most tools are not designed for that. The concept hangs on group permissions: every file belongs to whoever created it, the agent or me, and the group-write bit decides whether the other one can still write to it. Whenever a tool sets an explicit file mode, it bypasses umask and ACLs, and then a git pull or an edit dies with permission denied until someone re-asserts the group write. These things are solvable. A short find … chmod g+w after the tree-changing commands puts them right, but they will happen, and you should know that going in.
Where the operating system actually protects me is everything outside the project trees. Credentials under /home/dev/private/credentials.json, or on the Windows side under /mnt/c/Users/steffenmaechtel/.ssh/, are unreachable for the agent: a cat fails at the filesystem, no matter which command I approve. Inside the project tree, protection stays soft-only. I deny reads on auth.json in the agent's configuration; if I blindly approve a Bash command like cat auth.json, the content ends up in the prompt anyway. That is deliberate: auth.json holds the credentials for external private Composer repositories, and even that file cannot carry an operating-system deny. ddev composer install runs Composer inside the web container, as the same host UID as the agent, and Composer needs it to reach those repositories. The hard boundary is my home directory. Inside the projects, the agent's own rules and my reading of the prompts do the work.
What this setup protects against, and what it does not
| Risk of an agent with a shell | Covered by this setup? |
|---|---|
| Wrecking the machine | Partly. Your home, the system, and the Windows side survive; disk, CPU, and the project trees stay shared. |
| Taking over the machine | Yes. That is what the separate user, rootless Docker, and the missing Windows interop are for. |
| Writing code that does more than the task asked | No. Reviews and CI are the answer. |
| Exfiltrating code and secrets | Partly. What the agent cannot read, it cannot leak. Project files can still leave. |
| Unwanted network access | No. Nothing here restricts the network. |
Most of these risks are triggered by injected instructions in content the agent reads. An identity boundary does not fix that; it only shrinks what a hijacked agent can reach.
If you want this
This is a WSL2, Linux, and macOS approach. It leans on users, groups, and filesystem ACLs, so it does not carry over to traditional Windows.
You can build the whole thing by hand: useradd, dockerd-rootless-setuptool.sh, recursive ACLs, four sudoers rules, a wrapper script, and a shell function. When I started, I estimated three days, agent-assisted. It took longer than that; there is more to it than a second user and a rootless daemon. That is the reason I packed the result into opencode-permissions-kit (MIT, community project in beta): so nobody else spends a weekend on it.
Resources
- Podman and Docker Rootless in DDEV - how DDEV supports rootless container backends
- Docker Rootless setup in the DDEV docs - installation and requirements
- coder.ddev.com - DDEV in a cloud workspace, an alternative boundary
- opencode - the agent used in this post
- opencode-permissions-kit - the setup from this post, ready to run (MIT, community project in beta)
18 Nov 2026 8:10pm GMT
Security advisories: Drupal core - Moderately critical - Gadget chain - SA-CORE-2026-018
drupalDrupal core contains a chain of methods that could be exploitable when an insecure deserialization vulnerability exists on the site. This so-called "gadget chain" presents no direct threat, but is a vector that can be used to achieve remote code execution if the application deserializes untrusted data due to another vulnerability.
This issue is not directly exploitable.
This issue is mitigated by the fact that in order for it to be exploitable, a separate vulnerability must be present to allow an attacker to pass unsafe input to unserialize().
Install the latest version:
Drupal 11
- If you use Drupal 11.4.x, update to Drupal 11.4.13.
- If you use Drupal 11.3.x, update to Drupal 11.3.22.
- Drupal 11.2.x and below are end-of-life and do not receive security coverage.
Drupal 10
- If you use Drupal 10.6.x, update to Drupal 10.6.22.
- Drupal 10.5.x and below are end-of-life and do not receive security coverage.
- Drew Webber (mcdruid) of the Drupal Security Team
- Alex Pott (alexpott) of the Drupal Security Team
- catch (catch) of the Drupal Security Team
- Lee Rowlands (larowlan) of the Drupal Security Team
- Drew Webber (mcdruid) of the Drupal Security Team
- Stephen Mustgrave (smustgrave), provisional member of the Drupal Security Team
- Jess (xjm) of the Drupal Security Team
- Jess (xjm) of the Drupal Security Team
18 Nov 2026 5:50pm GMT