22 Nov 2026
 LXer Linux News
KDE Releases Kwi 0.1, Its New GPU-Accelerated Terminal Emulator
KDE's new Kwi terminal emulator reaches version 0.1 with improved tabs, global menu support, interface refinements, and a Flatpak release.
22 Nov 2026 11:48am GMT
Linux 7.4 To Remove NVMe Namespaces In Parallel For Faster Results
As part of this week's block subsystem fixes for the Linux 7.4-rc4 kernel release due out on Sunday are many bug fixes plus also a nice NVMe namespaces optimization…
22 Nov 2026 10:05am GMT
Sashiko AI Introducing Linux Performance Specialist Review Stage
The Google-developed Sashiko for agentic AI code review initially focused on the Linux kernel continues helping to uncover new bugs and issues as new patches hit the kernel mailing list as well as those manually running this open-source AI software. In addition to recently introducing an experimental patch series design assessment, they are introducing another new skill for helping with…
22 Nov 2026 8:09am GMT
Planet Python
Mark Dufour: Shed Skin restricted-Python to C++ transpiler v1.0 released!
I have just released version 1.0 of Shed Skin, a restricted-Python to C++ transpiler. It has taken a long time, in fact more than 20 years, to get to this point. I want to start by thanking all the people that have contributed over time. Leonardo Maffi helped out by testing in the first few years. IIRC, Harri Pasanen contributed extension module support. Johan Kristensen was instrumental in the move to Python 3. Jeremy Roquet and others helped to keep the project alive in my absense of several years. And in recent years, Shakeeb Alireza has been the main contributor, adding CMake (and hence good Windows) support, cleaning up the code and tests, and also contributing many good ideas.
So why release 1.0 now? Well, let's say that many things have finally come together. From a much improved type inference engine, to Unicode support, to much improved performance of generated code, to basically catching up with Python 3.15, a lot has happened over the past few months. Another thing that has happened (over the past few years?) is that C++ compilers have started to optimize away object allocations where possible. This has always been an achilles heel of Shed Skin, making it slower than for example PyPy for certain allocation-heavy programs. Regular allocations also seem to have become faster over time (under Linux at least). For my standard (of course highly biased!) performance plot, Shed Skin is now on average 5.0 times faster than PyPy, and in no case slower.

Something that I have to acknowledge also is the help of AI, more specifically Claude, to develop Shed Skin at a much more rapid speed than possible before. It has also been able to identify (and in many cases fix) about 500 bugs. We are all wondering about the future impact of AI of course, but let's hope that programming will remain a human hobby for a long time (the way chess is still enjoyable for humans, even though we totally suck at it.. :-)). But AI doesn't only help with development of Shed Skin, it can also help users to make their code Shed Skin compatible, and/or even submit issues/contributions. The following new example (an 'Another World' engine), was changed by AI in a few places, so that it worked with Shed Skin (while of course remaining valid CPython code, with no added type annotations!):

Thanks again to everyone who has contributed to the project, which has turned out to be my "life's work". Now that 1.0 has been reached, and with the advent of AI in programming, I don't know if I will continue to work on it intensively anymore though, without more/any community feedback or financial support, and spend more of my free time on other interesting projects. I will certainly try to keep it working, and do a yearly update for every new CPython release. I probably won't be able to help myself, but we will see! :-)
22 Nov 2026 12:57am GMT
Graham Dumpleton: Muru: when lazy imports help
Lazy imports are having a moment. Python 3.15 adds a lazy import statement, from PEP 810, and a module can name imports it wants deferred in a __lazy_modules__ list. A deferred import binds its name straight away, but the module isn't loaded until the code first uses it. Most of the excitement is about command line tools. A tool which imports everything it might ever need, just to print its --help, can start in a fraction of the time when most of those imports are deferred.
A web application served by a pre-forking server is a different calculation, and deferring imports there can make things worse rather than better. Whether it helps depends on the application, on how it is deployed, and on what its requests actually use, which is why Muru measures imports rather than leaving it to guesswork.
Where import time goes under Muru
As covered in the import once, fork many post, Muru imports an application once in a host process, and forks the workers from it. Everything the host imported is shared by the workers through copy on write memory, and is paid for once.
Under the Muru daemon, a deploy starts a new release beside the one serving, as covered in the releases, not restarts post, and traffic only moves to it once it is ready. However long the new release takes to import the application, nobody visiting the site waits for it. Deferring an import doesn't save anyone any time there. What it does is move the cost into the first request in each worker which uses the module, and since each worker then loads the module itself, its memory is no longer shared.
Under muructl serve in a container, a new release is a new container, and the import is part of how long it takes to start. A shorter start makes a rollout or a scale-out finish sooner. Even so, as covered in the working with Kubernetes post, Muru's readiness probe doesn't pass until the application is loaded and the workers are ready, so a new pod still gets no requests before it can serve them.
There are times when someone does wait for the import. A release scaled to zero with its host stopped makes the next request wait for the host to start and import the application. And muructl run in development loads the application again every time a file changes.
So a deferred import can help or hurt, depending on how the application is run and how often its requests use what was deferred. To decide, it helps to know what each import costs, and what the workers end up loading anyway.
A shop with two slow imports
The example for this post is a small Flask shop with two features that need large libraries. A stock report uses pandas:
# shop/reports.py
import pandas

from shop.data import BOOKS


def stock_value():
    frame = pandas.DataFrame(BOOKS, columns=["title", "author", "stock", "price"])
    frame["value"] = frame["stock"] * frame["price"]
    return frame.groupby("author")["value"].sum().to_string()
and a download of the stock list as a spreadsheet uses openpyxl:
# shop/export.py
import io

import openpyxl

from shop.data import BOOKS


def workbook():
    book = openpyxl.Workbook()
    ...
Someone has already tried to keep start-up fast, so the view for the report imports shop.reports inside the function, while shop.export is imported at the top of the application's module like everything else:
from flask import Flask, Response, render_template_string

from shop import export
from shop.data import BOOKS

app = Flask(__name__)

...

@app.route("/report")
def report():
    from shop import reports

    return render_template_string(REPORT, report=reports.stock_value())
It runs under muructl run with two worker processes, on Python 3.14.
What the host's load costs
Muru can record every import the host makes while it loads the application, using the profile recorder of unwrapt, a package for lazy imports which I wrote alongside Muru. With unwrapt added to the project's dependencies, import_report turns it on:
[tool.muru]
entrypoint = "shop.app:app"
import_report = true
muructl debug imports then prints a report of the host's load:
$ muructl debug imports
Import report of the host's load of shop@r1: outcome fork, Python 3.14.8, 2 workers
  113.8 ms importing, 397 modules loaded, 4046 import calls; deferring what can be deferred would save about 75.2 ms

Advice
  defer: shop imported by shop.app, 71.2 ms, loading entrypoint
    paid by the host, once before the fork, shared by the 2 workers; deferred, each worker that uses it loads it on first use
    add 'shop' to __lazy_modules__ in shop.app; it defers natively from Python 3.15, and below it only once rewritten as import shop (from-import)
      __lazy_modules__ = ['shop']
  defer: openpyxl imported by shop.export, 70.9 ms, loading entrypoint
    paid by the host, once before the fork, shared by the 2 workers; deferred, each worker that uses it loads it on first use
    add 'openpyxl' to __lazy_modules__ in shop.export
      __lazy_modules__ = ['openpyxl']

Imports that loaded a module, by cumulative time
  CUM MS SAVES MS IMPORTED IMPORTED BY         LOADING    3.15 UNWRAPT NOTES
    71.2      0.0 shop     shop.app            entrypoint yes  no
    70.9     70.9 openpyxl shop.export         entrypoint yes  yes
     5.0      0.0 click    flask.app           entrypoint yes  yes     also imported eagerly by flask.cli
     0.8      0.8 html     http.server         entrypoint yes  yes
     0.7      0.0 decimal  flask.json.provider entrypoint yes  yes     also imported eagerly by openpyxl.compat.numbers
  126 more rows with nothing to act on; --all lists them

The 2 workers that answered have loaded no module for the first time since the fork.
Most of the load was openpyxl. The advice for each import says what deferring it would mean, and the configuration to write. For the shop's own code, that is a __lazy_modules__ list in the module making the import. For an import inside a package the project depends on, where nobody wants to edit the package's source, it is an entry of unwrapt's [tool.unwrapt.lazy_modules] table, naming the importing module and what to defer in it.
The first piece of advice is about the application's own from shop import export, and nearly all of its 71.2 milliseconds is the openpyxl which shop.export imports, so the two are different ways of deferring the same cost. The 3.15 and UNWRAPT columns say whether each way of deferring can defer that import as written, since Python 3.15 can defer a from import while unwrapt can only defer a plain import. On the Python 3.14 the shop runs on, deferring the from import would save nothing unless it were rewritten, which is why its SAVES column is zero.
The report lists by default only the imports there is something to do about. With --all it lists the rest, among them the numpy which openpyxl imports in turn, for 28.6 of openpyxl's milliseconds:
  CUM MS SAVES MS IMPORTED IMPORTED BY             LOADING    3.15 UNWRAPT NOTES
    28.6      0.0 numpy    openpyxl.compat.numbers entrypoint yes  yes     used at load, deferring saves nothing, ...
It isn't advised, because openpyxl.compat.numbers uses numpy at the top level, straight after importing it, to build a tuple of numeric types. A deferred import that is used the moment it is made is loaded straight away anyway, so deferring it would save nothing.
The same report comes from muructl check --imports, which loads the application once without serving anything, so it can be run before and after a change, or in CI.
Deferring an import
The spreadsheet export is used rarely, so deferring openpyxl looks worthwhile. That takes two changes. The module names the import in __lazy_modules__, before the import itself:
# shop/export.py
__lazy_modules__ = ["openpyxl"]

import io

import openpyxl
and the project turns on lazy_imports:
[tool.muru]
entrypoint = "shop.app:app"
import_report = true
lazy_imports = true
Python 3.15 and later act on __lazy_modules__ by themselves. Python 3.11 to 3.14 ignore it, and with lazy_imports on, Muru has unwrapt defer the imports it names instead, so the same code defers on every version of Python Muru supports. The lazy import statement can't be used that way, since it is a syntax error before 3.15.
As the host forks, it says what was deferred, and whether anything used a deferred import before the fork anyway, in which case deferring it saved nothing:
muru.host[74803]: lazy_imports: 1 import deferred, none of them used before the fork
How much this saved needs more than one measurement, since a load's time varies from one start to the next by about as much as the difference being measured. A muru.local.toml beside the project overrides the project's settings for my own runs only, so lazy_imports = false in it turns deferral off without changing pyproject.toml. With import_report = false there as well, since recording the imports adds to the load, I started the run five times each way. The host took a median of 83 milliseconds to load the application without deferral, and 35 milliseconds with it.
The cost hasn't gone away though, it has moved. The first request for the spreadsheet in a worker now loads openpyxl, and the numpy it imports in turn:
server-timing: queue;dur=0.00, app;dur=56.89, import;dur=52.03, muru;desc="01M7TS44DGPY87CQSBXYXS7D83"
The import entry in Server-Timing is the time the request spent loading modules for the first time in its worker. The request's Timing panel, on the dashboard here since a spreadsheet has no page for the toolbar, shows it as an "importing modules" row, and its list of the modules loaded marks the one that resolved a deferred import, with the line of code that first used it:
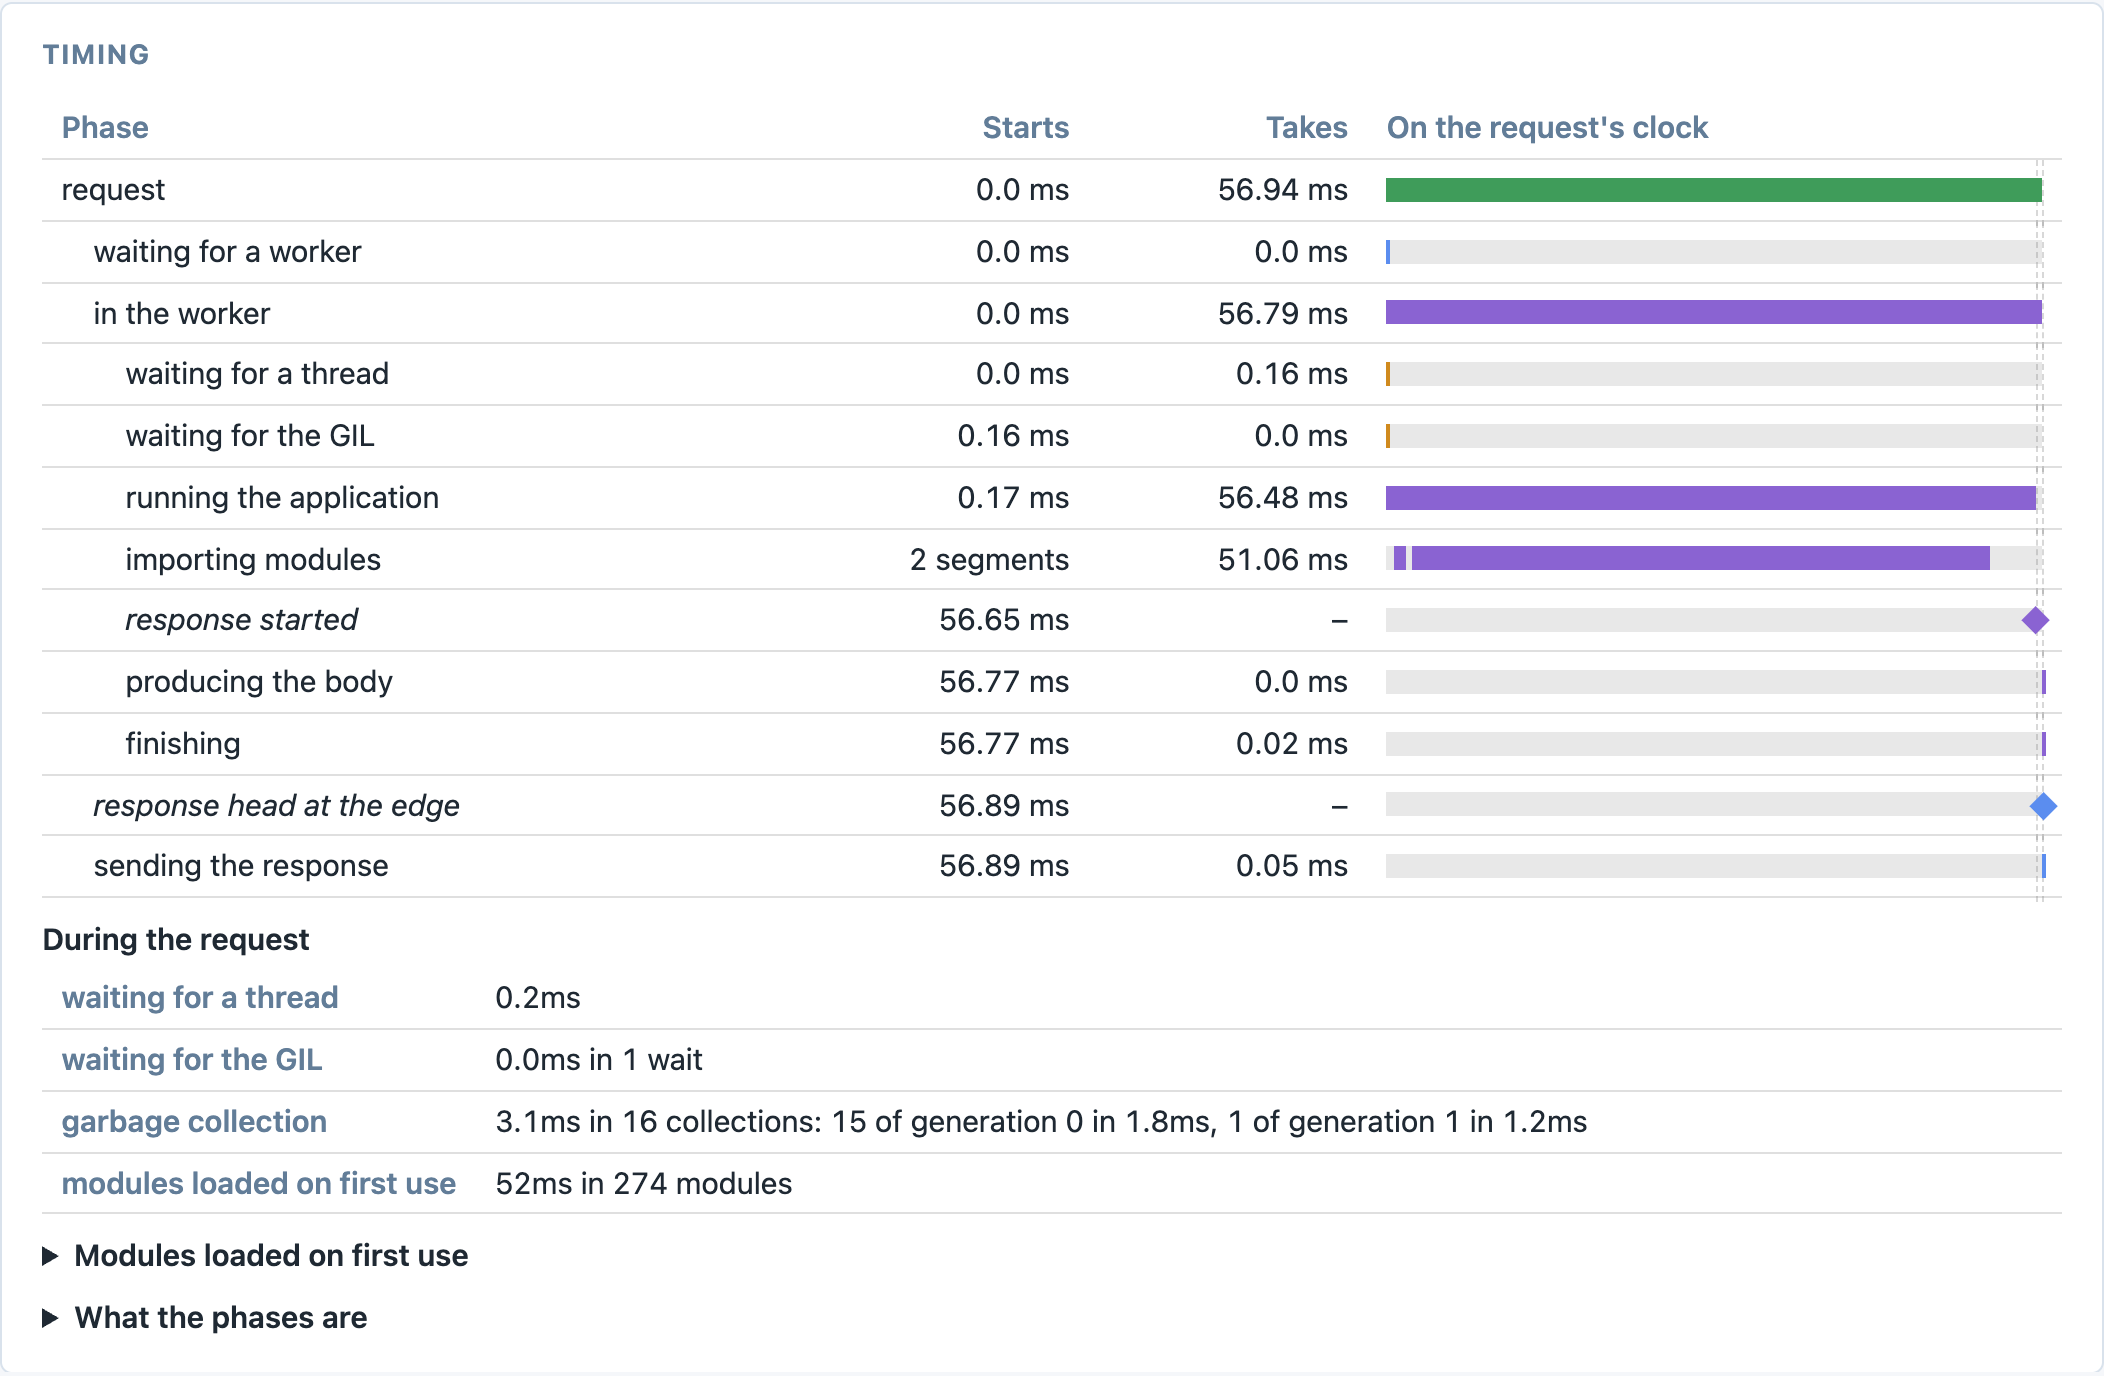
  Modules loaded on first use
    encodings.idna  0.7ms  1.0ms  encodings/__init__.py:100
      stringprep  1.0ms  0.3ms  encodings/idna.py:3
    openpyxl (deferred)  2.1ms  50ms  shop/export.py:11
      openpyxl.compat  2.3ms  21ms  openpyxl/__init__.py:5
        openpyxl.compat.numbers  2.4ms  21ms  openpyxl/compat/__init__.py:3
          numpy  2.5ms  21ms  openpyxl/compat/numbers.py:9
...
Line 11 of shop/export.py is book = openpyxl.Workbook(), the first use of the module.
Since numpy was a good part of that, I tried deferring it inside openpyxl anyway, to see what the report's reason for not advising it looks like in practice, with an entry of [tool.unwrapt.lazy_modules]:
[tool.unwrapt.lazy_modules]
"openpyxl.compat.numbers" = ["numpy"]
The list of modules for the next first download showed numpy (deferred) being loaded from line 16 of openpyxl/compat/numbers.py, while openpyxl itself was still loading. That is the line which builds the tuple of numeric types, so the deferred import was used the moment it was made. The workers' part of muructl debug imports, which comes up next, said the same of it, "used as openpyxl.compat.numbers loads, at openpyxl/compat/numbers.py:16; deferring it saves nothing, remove the entry", so I took the entry out again.
Asking the workers
Whether moving that cost was worth it depends on how many workers end up paying it, and that depends on the traffic. After the run had served some pages, several stock reports and one spreadsheet, the last part of muructl debug imports asked each worker what it had loaded for the first time since the fork:
Modules loaded for the first time since the fork, by the 2 workers that answered
  MODULE                      LOADED BY FIRST REQUEST                 MS ADVICE
  shop.reports                2 of 2    01M7TS5XN33J2YHXVA5EYVR7RN 134.0 every worker loads it: load it before the fork with preload_modules = ["shop.reports"]
  openpyxl (deferred)         1 of 2    01M7TS5XV33J2YHXVA5EYVR7RX  28.7 deferred in the host; loaded by 1 of 2 workers: loading on first use pays off: only some workers load it
  encodings.idna              2 of 2    01M7TS5XMM3J2YHXVA5EYVR7RM   1.4 every worker loads it: load it before the fork with preload_modules = ["encodings.idna"]
  openpyxl.packaging.extended 1 of 2    01M7TS5XV33J2YHXVA5EYVR7RX   0.1 loading on first use pays off: only some workers load it
  The counts cover the requests served so far; read them after representative traffic.
The two features come out on opposite sides. Only one worker had needed openpyxl, so the other was spared both the time and the memory, and the deferral paid off. Every worker had needed shop.reports, and each loaded pandas itself, about 135 milliseconds a time, which the function level import in the view had pushed into the first report each worker served.
That first report is also worse than it looks. With three requests for the report sent at once, two of them went to the same worker on different threads, and both took about 140 milliseconds. Only one of them was loading pandas. The other was waiting on Python's import lock for it to finish, and their Server-Timing headers tell the two apart:
server-timing: queue;dur=0.01, app;dur=140.39, import;dur=137.67, muru;desc="01M7TS5YW93J2YHXVA5EYVR7RZ"
server-timing: queue;dur=0.40, app;dur=140.80, import_wait;dur=138.92, muru;desc="01M7TS5YW93J2YHXVA5EYVR7S2"
The second request's Timing panel has a "waiting for an import" row in place of "importing modules", and names the module and the request it was waiting on:
waiting for an import: 139ms in 1 wait: shop.reports, loaded by request 01M7TS5YW93J2YHXVA5EYVR7RZ
The first requests after a deploy, or after a scale-out adds workers, are exactly when that happens.
Loading before the fork
A module that every worker loads is better loaded once, in the host, before the fork. preload_modules lists modules for the host to import after the application, as part of the same load:
[tool.muru]
entrypoint = "shop.app:app"
import_report = true
lazy_imports = true
preload_modules = ["shop.reports"]
The host's load now includes pandas, and the first reports in each worker took from four and a half to nine milliseconds, rather than more than a hundred. The import report gives the entry's own cost on a line of its own, preload_modules entry shop.reports: 145.5 ms in the host, and doesn't advise deferring anything the entry loads, since that would only undo it.
preload_modules is also the way to undo a deferral you don't want. Once Python 3.15 is common, libraries will start using lazy import themselves, for their own command line tools or their own start-up time, and in a web application that may move a library's import into the first request of each worker. Listing the module in preload_modules loads it before the fork regardless, and the deferred import finds it already loaded when the code first uses it.
After more traffic
The advice is only as good as the traffic the workers have seen. After a few more downloads of the spreadsheet, both workers had served one:
Modules loaded for the first time since the fork, by the 2 workers that answered
  MODULE                      LOADED BY FIRST REQUEST                MS ADVICE
  openpyxl (deferred)         2 of 2    01M7TS6PYFJQCRT78JGT5BYKRS 31.1 deferred in the host; loaded by 2 of 2 workers: load it before the fork with preload_modules = ["openpyxl"]
  encodings.idna              2 of 2    01M7TS6CHTJQCRT78JGT5BYKRE  1.6 every worker loads it: load it before the fork with preload_modules = ["encodings.idna"]
  openpyxl.packaging.extended 2 of 2    01M7TS6PYFJQCRT78JGT5BYKRS  0.1 every worker loads it: load it before the fork with preload_modules = ["openpyxl.packaging.extended"]
  The counts cover the requests served so far; read them after representative traffic.
With two workers running for a long time, a module that any request uses at all eventually ends up loaded in all of them, at which point the deferral bought nothing but a slower first request in each. With more workers, workers that are replaced after a number of requests, or an autoscaler which adds and removes workers as load changes, many workers may never get as far as needing it. Which of those describes a production deployment is something only its own traffic can say, so this is a question to ask of a running release rather than a development run. The same counts are kept as metrics, muru_worker_modules_loaded_total and muru_worker_module_load_seconds_total, so they can be watched over time.
What's next
Lazy imports are a useful tool, but in a web application served by a pre-forking server they are a trade between the host's load, the first request in each worker, and how much memory the workers share. Muru gives you the measurements to make that trade for your own application. The Server-Timing header and the Timing panel show what a request paid for imports, the import report shows what the host's load costs and where to cut it, and the workers say what they ended up loading anyway. Deferral through unwrapt works the same from Python 3.11 to 3.15, and preload_modules puts back what shouldn't have been deferred.
The next post, working with coding agents, is about something else doing things through Muru. Coding agents are increasingly the ones running, deploying and debugging applications, and Muru gives them a way in through MCP, so an agent can deploy each change as a release, read the events, logs and worker stacks when something fails, and roll back, using everything the earlier posts covered.
22 Nov 2026 12:00am GMT
21 Nov 2026
Planet Python
Trey Hunner: Python Morsels Lifetime Access Sale (2026)
Through Monday November 30, I'm selling lifetime access to Python Morsels, my Python skill-building service.
I've only offered lifetime access to Python Morsels twice before, and this is the first time it includes Daily Recall, the spaced repetition system I added this year.
Python Morsels is built around exercises
We don't learn by putting information into our heads. We learn by retrieving information from our heads, and when it comes to Python, that means writing Python code.
Python Morsels is designed around the idea of deliberate practice: writing code with the sole purpose of improving our Python skills. That practice mostly comes in the form of exercises… but not the kind of exercises you'll find on HackerRank, LeetCode, or Project Euler.
Python Morsels exercises test your ability to reach for the right tool at the right time. Each exercise includes hints and related resources with short and to the point explanations: they're meant to move you forward, not to get lost in.
New this year: Daily Recall
But exercises aren't appropriate for every concept. For example:
- Which string method removes a substring from the end of a string?
- Which built-in function starts the Python debugger?
- What is the time complexity of the string
joinmethod?
Many concepts can be strengthened through short regular quizzing… not for assessment, but for learning's sake. That's what Daily Recall is for. It's a spaced repetition system for Python programmers, new in Python Morsels this past September.
Daily Recall shows you a few Python questions each day and brings each one back right before you'd forget it. The more you're struggling with a concept, the more frequently it'll appear.
A session takes just a few minutes and it works well on a phone, so you can replace 5 minutes of your daily doomscrolling with 5 minutes of Python skill maintenance. To see what a Daily Recall session is like, try the short demo on the sales page.
I wrote more about why I built Daily Recall, and why I've been recommending spaced repetition for years, in Python Morsels now has spaced repetition.
What lifetime access includes
Lifetime access includes everything that's in Python Morsels today:
- 270+ exercises with tests, hints, and solution walkthroughs (plus 500+ optional bonuses)
- 240+ screencasts, most under 4 minutes
- 300+ articles, including a written version of every screencast
- 500+ Daily Recall questions, with hundreds more coming next year
- 3 courses and 15 exercise paths for diving deep into specific topics
This also includes everything I add in the future. I add new screencasts and exercises every month and I plan to add a new Daily Recall pack every week for at least the next year. I also keep Python Morsels material up-to-date with each new Python release.
You can try Python Morsels for free
If you haven't used Python Morsels before, there's a 7-day free trial that includes everything and doesn't require a credit card. If you start your trial by November 23, you'll have time to decide before the sale ends.
Every purchase also comes with a 30-day money-back guarantee: email me within 30 days of buying and I'll refund you in full.
Lock in lifetime access by November 30
Python Morsels usually costs $240 per year. Over five years, that's $1,200. Through Monday November 30, you can get lifetime access for just $649.
If you're already a Python Morsels subscriber, log in before you buy, because existing subscribers automatically get an extra discount. And if the price is a stretch, I offer income-based discounts.
If you plan to use Python heavily for at least a few more years, I think lifetime access to Python Morsels is one of the best investments you can make in your Python skills. After November 30, lifetime access goes away.
Get lifetime access to Python Morsels
21 Nov 2026 8:30pm GMT
Drupal.org aggregator
Freelock Blog: Procurement Invented AI Decades Ago. It's Called an RFI.
Procurement Invented AI Decades Ago. It's Called an RFI.

21 Nov 2026 1:00am GMT
20 Nov 2026
Drupal.org aggregator
The Drop Times: Drupal Autocomplete Patch Rejects Invalid New Tags in Tests
A proposed Drupal core patch prevents invalid taxonomy terms from being created through autocomplete fields. Tests reveal stricter validation, potential compatibility issues and confusing error messages for editors.
20 Nov 2026 5:10pm GMT
Django community aggregator: Community blog posts
Issue 364: 2027 DSF Board Nominations
News
2026 Malcolm Tredinnick Memorial Prize awarded to Raffaella Suardini
We are pleased to announce that the 2026 Malcolm Tredinnick Memorial Prize has been awarded to Raffaella Suardini!
2027 DSF Board Nominations
Five of the seven board seats are open, four two-year terms plus a one-year seat finishing out Jacob Kaplan-Moss's. You do not need to be a DSF member or to have served before. Nominations close December 2.
Wagtail CMS News
Join us for the Wagtail Space community day
Friday closes out Wagtail Space as an unconference: you bring the topics, the organizers sort out the rooms. Roadmap Q&A, first contributions, UX, AI, packaging, and security are already on the list.
Agent-friendly user docs for Wagtail
Four new documentation formats for AI agents, based on weeks of testing.
Djangonaut Space News
Djangonaut Space Log 3: JS one-liners && backend
Wasif Shahzad shares the latest steps in his journey, exploring JavaScript improvements and backend changes while working on his first PR for Django Debug Toolbar.
Djangonaut Log 4: Avoiding asteroids
"I tend to be the type of person who gets very excited about things I'm passionate about and Djangonaut Space - as you may have noticed through my blog posts - is definitely one of those." - Juha-Matti Santala
Updates to Django
Today, "Updates to Django" is presented by Raffaella from Djangonaut Space! 🚀
Last week we had 17 pull requests merged into Django by 13 different contributors - including 8 first-time contributors! Congratulations to Zishan Kadri, Akshat Gupta, Matthew Newton 🚀, Goodluck Igbokwe 🚀, charlesroelli, Awath Javar Abdat, Kryštof Kopečný and Alisson Silveira for having their first commits merged into Django - welcome on board!
New in Django 6.2:
- Passing table names as command-line arguments to
createcachetableis deprecated. Configure cache tables in theCACHESsetting instead. - The HTML and plain text technical 500 debug pages now display the nested exceptions in
BaseExceptionGroupinstances.
New in Django 6.1:
- Fixed a bug in Django 6.1 where the
models.E050system check did not detect mixedon_deletevariants for models with aGenericRelation(#37471).
Django Fellow Reports
Django Fellow Report - Jacob
Three security PRs of his own, plus review and triage on others. Django's release wheels now build reproducibly, thanks to Charles Roelli, and Jacob paired with Tobias and Colin on moving djangoproject.com to a new OS.
Django Fellow Report - Sarah
A security week, with eight issues in flight. The fellows want as many closed as they can before the end-of-year break. She also accepted a fix for makemessages dropping context from multiline translation tags.
Python Software Foundation
PEP 8108: 2027 Term Steering Council election
Seth Larson's PEP sets the schedule for the Steering Council term covering Python 3.16. Core team members nominate candidates, themselves included, from November 16 to 30, then vote December 2 to 16, with five seats decided by Bloc STAR voting.
Stricter checks for uploaded sdists
PyPI now rejects V7-style tar archives and wheels whose ZIP comments could pass for control structures, closing off parser differentials. Almost nothing is affected, since build backends already emit pax tars. If you pack by hand, pass --format=pax.
Sponsored
Reach 4,300+ Engaged Django Developers
Sponsor this newsletter to reach an active community of Python and Django developers.
Articles
Django race conditions and unique constraints
A UniqueConstraint protects your data and hands the user a 500. Tim Schilling validates the constraint in the form first, then catches IntegrityError inside transaction.atomic() so the savepoint survives, and writes a racing form to prove the test works.
Billing LLM tokens through Stripe from a Django backend
Papan Sarkar billed a meter event inline with the model call and double-billed a retry. The fix: a UsageEvent outbox row in the same transaction, drained with select_for_update(skip_locked=True). Good on the limits that bite, including Stripe's 24-hour window for corrections.
How to find and fix N+1 queries in Django
A thorough look at this common issue, how to spot it, inspect, and fix.
Your Django tests use the wrong media storage
From Marc Gibbons at Lincoln Loop, tldr is fake S3 not your code when testing media storage. An elegant writeup with accompanying gist to explore.
How CPython processes Python source code
Velda Kiara follows a file, a -c string, and a readline() callable into the same struct tok_state, where one underflow function pointer is all that still tells them apart. Ends at the PEG parser pulling tokens one at a time, with the compile step promised next.
Events
IndyPy: Django & FastAPI: What's Next?
Tuesday, November 24 at 7pm ET, hybrid from E-gineering in Indianapolis or over Zoom. Tim Schilling covers what's new in contributing to Django, and Calvin Hendryx-Parker argues batteries-included against speed in the Django/FastAPI debate. Register on Meetup for the in-person seat or the Zoom link.
PyCon US 2027 Call for Proposals
Talks, tutorials, posters, and charlas all close December 19, with the Future of AI and Python Security tracks returning. First-time speakers can get matched with a mentor to shape a proposal, but that sign-up closes November 27.
Podcasts
The Real Python Podcast #319: Mentoring Developers Beyond the Code With Tim Schilling
Tim Schilling, Django Steering Council member and Djangonaut Space administrator, talks with Christopher Bailey about turning his Better Simple blog toward one-on-one mentoring, what a mentee has to bring, and how LLMs changed the questions developers ask.
Django Chat #210: Code Is Not the Bottleneck - Johannes Maron
Johannes Maron is a prolific Django contributor, package maintainer, and startup founder. We discuss FOSS Fridays, the growing importance of code review in the age of AI, and what actually makes software engineering valuable.
Videos
Mentoring Developers Beyond the Code With Tim Schilling
The same conversation on video, running an hour and eight minutes, including segments on Djangonaut Space and on Django Commons filling the gap left by Jazzband.
Django Job Board
Three senior roles this week: Python engineering at Manychat in Barcelona with relocation support, backend Python at Proxify, and a founding forward deployed engineer at Alloy.
Senior Python Engineer (Barcelona-based / Relocation support to Barcelona) at Manychat
Senior Backend Developer (Python) at Proxify AB
Founding Forward Deployed Engineer at Alloy
Projects
aws/aws-emulator
AWS runs the AWS APIs on your laptop. A Rust server on 127.0.0.1:9297 that the AWS CLI and the SDKs talk to with no account and no bill, so tests hit it instead of us-east-1. Per-service fidelity scores ship with each release.
oliverandrich/django-pg-sse
Server-sent events over Postgres LISTEN/NOTIFY. No Redis, no broker, no Channels. Events land in a table and go out after the transaction commits, so a reconnecting client replays what it missed. Built for htmx 4's hx-sse.
Apakottur/unref
A dead code finder built on Ruff's parser, so the options and output read like Ruff and the config lives in pyproject.toml. It sweeps all of CPython in under a second, and ships rules for pytest, Pydantic, and SQLAlchemy to keep the false positives down.
Sponsor Django News
Reach 4,300+ Django developers every Friday. See sponsorship details and rates.
20 Nov 2026 5:00pm GMT
Drupal.org aggregator
The Drop Times: How Drupal Sites Track AI Requests, Token Costs and Budgets
In tests by The DropTimes, AI Metering priced OpenAI calls on write while an observability recipe turned prompt and response logging on by default.
20 Nov 2026 4:24pm GMT
DZone Java Zone
Getting Started With Qdrant: Building Intelligent Search Applications With Java
Enterprise applications seldom rely solely on similarity for information retrieval. For example, e-commerce platforms must recommend products aligned with customer interests while considering availability, pricing, and categories. Document management systems need to retrieve semantically related information while enforcing access permissions. Combining these requirements efficiently is a key challenge in building intelligent search applications. Qdrant, an open-source vector database for similarity search and structured filtering, addresses this challenge effectively.
Qdrant enables Java developers and software architects to build applications that integrate semantic understanding with business constraints. Its support for multiple vector representations, advanced filtering, and hybrid retrieval extends its relevance beyond conversational AI and RAG applications.
20 Nov 2026 1:00pm GMT
19 Nov 2026
Django community aggregator: Community blog posts
Code Is Not the Bottleneck - Johannes Maron
🔗 Links
- Johannes Maron's Website
- GitHub - codingjoe
- PyPI - codingjoe
- Johannes Maron on LinkedIn
- FOSS Fridays on Django Discord
- Official Django Skills for LLMs (Django Forum)
📚 Books
- The Practice of Programming by Brian W. Kernighan and Rob Pike
- Build a Large Language Model (From Scratch) by Sebastian Raschka
- The Mythical Man-Month by Frederick P. Brooks Jr.
📦 Projects
🤝 Sponsor
Thanks again to Laravel Cloud for sponsoring this episode. The team behind Laravel's managed hosting platform has something big in the works, and we'll share more here on the show in the coming weeks.
🎥 YouTube
19 Nov 2026 11:25pm GMT
DZone Java Zone
Getting Started With Milvus: Vector Search for Enterprise Java Applications
Artificial Intelligence is transforming enterprise information retrieval, but deploying semantic search in production involves more than generating embeddings. Applications must efficiently store, index, and retrieve millions of vectors while managing expanding datasets, concurrent requests, and operational demands. Milvus, a leading open-source vector database, addresses these needs. Built for high-performance similarity search, Milvus offers a specialized persistence engine that supports applications from recommendation systems to large-scale AI-powered search.
Java developers and software architects face the challenge of integrating these capabilities without adding complexity or tightly coupling business logic to a specific database. This article explores Milvus integration through Enterprise Java, showing how to connect enterprise Java applications to vector search using familiar persistence concepts. Before writing Java code, we will examine what sets Milvus apart, how its architecture works, and which configuration options matter when moving from local development to production.
19 Nov 2026 1:00pm GMT
18 Nov 2026
Django community aggregator: Community blog posts
Weeknotes (2026 week 47)
Weeknotes (2026 week 47)
I haven't done any blogging in the last 4 weeks. Instead, I've been writing a lot of code and have let the agent write even more code. I have finally managed to implement some tools I would have liked to implement a long time ago.
Working with LLM agents
The relationship with LLM agents doesn't get any easier, I have to admit. That said, the quality argument against LLMs seems less and less plausible to me. Some people (especially on Mastodon) will say that's because I'm losing view of what's actually important. As I see it, human-written code was never perfect either (maybe apart from the Apollo Guidance Computer). I can actually do good and solve more problems for real users with more than acceptable code quality now and that seems like a net benefit to me.
Governance - a Django app for Holacracy
As some people may know, we are using Holacracy as our organizational model at Feinheit. Holacracy One, the company behind Holacracy, also offers a SaaS solution for managing the structure consisting of circles, roles, policies etc. The tool is unfortunately quite buggy and slow, and hasn't improved in recent years - to the contrary.
I have reimplemented the parts we actually use using Django, Bootstrap and htmx while profiting from years and years of product engineering going into the Workbench agency software.
It won't surprise anyone that after the first rush of getting a half-functioning, half-assed prototype out of the agent it was a lot of work to actually make the tool somewhat consistent, usable and correct. The bar to replace the tool we've been using before wasn't that high, so I was able to cross that in a few days of concentrated work.
I think that this project wouldn't have been doable without the deep knowledge of the organizational model (the domain knowledge) and the product engineering and UX background.
An experimental API and CLI for feincms3
The feincms3-api and feincms3-api-cli allow interacting with a feincms3-managed site. The API allows reading and writing pages and other objects with their regions and plugins, django-json-schema-editor data and django-cabinet files. It's meant for scripts, importers and agents, next to the Django admin, not instead of it. The CLI (f3api) makes the API available from the command line. Writes can be tried as a dry run first, and changes show up in the admin's history like any other edit.
Permissions, editable fields etc. are all handled by the Django admin. Since feincms3 and django-content-editor lean heavily on Django's administration interface this was an easy decision to make. Plugins can be arbitrary models and we don't have an obvious way to discover them, or even know what their structure is apart from introspection or manual work. The constraints of working in an agency are such that I cannot spend a lot of time on each individual project; I really need reusable tools which can be applied to many websites and projects at once. It can be acceptable for the result to not be perfect or a little awkward as long as it is simple and understandable.
Releases
feincms3 and django-content-editor
The rendering engine from feincms3 has been ported to django-content-editor and lives there now. Nested sections stay in feincms3 as a backwards compatible implementation, the new implementation in django-content-editor is much nicer because it doesn't require section closing plugins. Instead, all plugins have a depth field and form a tree structure that way; a new level is opened by a plugin which is marked as a container. Many such container plugins can coexist.
Also, the new releases fully build on the importmap DEP API, and include many bugfixes which will not be mentioned in detail here.
feincms3-sites has also received a small update and a few bugfixes.
django-cabinet
The media library now supports moving files with drag'n'drop and has a collapsible folder tree on the left for quicker navigation.
django-json-schema-editor
The proxy models created by JSONPluginBase.proxy() are automatically injected into the Python module now; this allows Django's model autoimporter in ./manage.py shell to discover those models, which avoids many, many warnings.
django-prose-editor
I am always tracking Tiptap and ProseMirror closely. The editor now has a deeper integration with django-cabinet - inserted files keep their ID around. Apart from that, mostly minor changes.
django-js-asset
I have released django-js-asset 5.0 implementing the ImportMap specification which I'm still hoping to bring to Django core.
form-designer
Bugfixes, French, Catalan and Spanish translations, and a small security fix (don't inadvertently add formulas to generated XLSX files, the fix is in xlsxdocument below).
django-authlib
Hardened the Microsoft Entra ID adapter. Fixed a few bugs and improved docs.
django-imagefield
I did finally release a new stable release of django-imagefield containing the still experimental vips backend.
django-translated-fields
TranslatedField now handles model fields with broken^Wcustomized deconstruct methods properly. For example, feincms3's ChoicesCharField hides the choices from Django's migrations, so changing choices doesn't create pointless migrations (they wouldn't produce any SQL anyway). However, the previous implementation required that fields are reconstructible from the return value of deconstruct, which means that such fields could not be used with TranslatedField. Now they can.
django-tree-queries
Fixed an edge case crash, allowed customizing the node moving machinery to reject targets and slightly modernized the code.
feincms3-cookiecontrol
The cookie banner now supports Google's advanced consent mode out of the box, if you opt in to it as the one implementing it (not as a visitor to the website!). I think supporting that mode is good, because while the mode itself is very questionable, having a simple and straightforward implementation for it is better than having to choose one of the really, really complex and user-hostile consent management platforms.
feincms3-forms
The proxy models created by the forms builder are now injected into their module. Same problem as above, in django-json-schema-editor.
Other releases
- I still seem to be maintaining django-mptt, even though it has been marked as unmaintained for years. Fixed some tree corruption bugs and regressions.
- xlsxdocument doesn't insert formulas anymore except if they are tagged using a new
Formulaobject. form-designer uses it for its XLSX export. - speckenv now supports configuring Django's
MAILERSsetting from the environment as well. The format is the same as the one used bydjango_email_urlanddj-email-url. Also includes more fixes for configuration cases I hadn't encountered before. - towel and towel-foundation, two packages from back in the day when I was a stronger believer in the DRY principle. Note that I have been moving away from that for years. I'd rather have some repetition than more indirection these days.
- html-sanitizer now knows how to preserve whitespace within
<pre>tags. - The venerable FeinCMS and feincms-elephantblog are in maintenance mode, but have received updates and releases.
- Fixed a minor bug affecting django-admin-ordering models which handled comparisons with unrelated objects incorrectly.
- Updated the django-sitemaps README and published a new release, just because.
- django-ckeditor now uses the new django-js-asset API.
- django-email-hosts now supports
MAILERS.
18 Nov 2026 6:00pm GMT
17 Nov 2026
DZone Java Zone
Pitching Kotlin: An Engineering Leader's Guide to Legacy Modernization
I've been on both sides of the Kotlin conversation: the engineer making the case, and the architect who reviews it and recommends a direction before a committee decides. On the reviewing side, the pattern is predictable: most Kotlin pitches die in the second meeting. A tech lead shows up with a list of syntax wins, managers or architects ask about migration risk, and the conversation ends with "we'll revisit this next quarter." The technical case for Kotlin is usually sound, but the pitch stalls because it argues from developer preference, while engineering leaders approve migrations based on cost and risk. I've spent a large part of my career on systems where a defect moves real money (I talked about what that means for Kotlin code at KotlinConf 2026), and when I wrote the Kotlin Enterprise Playbook, I ran this exact argument through a financial model across mobile, edge, and backend domains. The proposals that held up were the ones that priced cost and risk honestly, including the cases where the answer was "not here."
This guide is the framework I use when I review these proposals. Decide domain by domain, solution by solution, instead of organization-wide. Make the cost of the status quo measurable. Price the migration, including the parts nobody budgets for. Place gates where decisions stop being reversible. Make sure the people who carry the risk own the outcome. Kotlin is the worked example, but the same framework applies to any large technical migration, whether it's a language, a framework, or a data platform.
17 Nov 2026 4:45pm GMT
07 Nov 2026
Planet Lisp
vindarel: CSV parsing in Common Lisp, data manipulation by columns with data frames
Parsing CSV files is a common task. What are our options? We'll start with cl-csv, add the data-table library, and present lisp-stat's data frames.
This is another contribution to the Common Lisp Cookbook so you should read it there as this is where it will get updates.
With a very simple dataset we could split CSV lines manually (subseq, split-sequence, str:split, cl-ppcre...) but when a column contains the separator, a library starts to be useful.
And a library will be even more so to help us manipulate columns by name, to use tabular data structures, to automatically infer the columns' types, and more.
I recommend:
- for simple use, try
cl-csv - if you'll do statistics or want a good dataframes library, go for
lisp-stats - to work with large datasets, see
cl-csv's:row-fnargument. - for the fastest parsing, maybe
fare-csv, or DuckDB with cl-duckdb, which can also ingest much more file formats than CSV, including Excel.
Table of Contents
- Introduction: our test files
- Parsing with cl-csv
- cl-csv and data-table: column names, column types, columns manipulation
- lisp-stat's Data Frame
- Utilities
- See also
Introduction: our test files
Let's work together with this simple CSV file, persons.csv:
Alice,7,1
Bob,77,0
The separator is , (often the default in libraries).
For simplicity, the file doesn't contain a headers row.
This second file, persons2.csv, contains headers:
name,age,lisper
Alice,7,1
Bob,77,0
Parsing with cl-csv
The cl-csv library is on Quicklisp.
(ql:quicklisp "cl-csv")
It allows to parse data from a string, from a file, or from any stream.
It may not be the fastest, but it has a decent set of quality-of-life features.
Please go read its README, as we don't illustrate some of its features here. For example, it supports multiline quoted data, we can set the quote character, it has good error messages (line and column number, char index), etc.
For reference, this is the function signature of cl-csv:read-csv (C-c-s on Slime):
(cl-csv:read-csv stream-or-string :csv-reader csv-reader
                                             :row-fn row-fn
                                             :map-fn map-fn
                                             :data-map-fn data-map-fn
                                             :sample sample
                                             :skip-first-p skip-first-p
                                             :separator *separator*
                                             :quote *quote*
                                             :escape *quote-escape*
                                             :unquoted-empty-string-is-nil *unquoted-empty-string-is-nil*
                                             :quoted-empty-string-is-nil *quoted-empty-string-is-nil*
                                             :trim-outer-whitespace *trim-outer-whitespace*
                                             :newline *read-newline*
                                             :escape-mode *escape-mode*)
Parsing from a string
To parse from a string, just use cl-csv:read-csv:
(cl-csv:read-csv "Alice,7,1
Bob,77,0")
;; =>
(("Alice" "7" "1") ("Bob" "77" "0"))
It returns a list of lists, values are all strings.
Parsing from a file
Also use cl-csv:read-csv but give a pathname as argument, not only the filename as a string.
(cl-csv:read-csv #P"persons.csv")
;; =>
(("Alice,7,1") ("Bob,77,0"))
What happens if you omit the #P?
(cl-csv:read-csv "persons.csv")
;; =>
(("persons.csv"))
this looks strange and no, there is no bug ;)
To parse from a stream, see the library's documentation.
Using another separator
Is ; the columns separator? Use cl-csv:read-csv's :separator argument, or the global cl-csv:*separator* parameter.
For a Tab, use #\Tab.
(defparameter *csv-string* "Alice;7;1
Bob;77;0")

(cl-csv:read-csv *csv-string* :separator #\;)

;; OR

(let ((cl-csv:*separator* #\;))
  (cl-csv:read-csv *csv-string*))
Skipping the first row of headers
With cl-csv, use :skip-first-p.
However, we'll use this row of headers as soon as we work with dataframes.
(cl-csv:read-csv "name,age,lisper
Alice,7,1
Bob,77,0"
 :skip-first-p t)
Returning a list of objects
So far, we got a list of lists with raw values as strings. We can do whatever we want with them. cl-csv has a :map-fn argument that we can use to create an object while parsing each row.
Let's re-use our class definition from the CLOS chapter:
(defclass person ()
  ((name :initarg :name :initform "")
   (age :initarg :age :initform nil)
   (lisper :initarg :lisper :initform nil)))
We can parse our CSV and return a list of objects at once:
(cl-csv:read-csv #p"persons.csv"
  :map-fn (lambda (values)
             (make-instance 'person :name (nth 0 values)
                                    :age (parse-integer (nth 1 values))
                                    :lisper (if (equal "1" (nth 2 values)) t nil))))
Observe that:
- we had to parse the age from a string to an integer ourselves
- our file doesn't have a headers row.
Streaming reads (for large files)
cl-csv provides the :row-fn parameter, that does something with each row and doesn't return them. This allows us to work with large datasets.
In this example, the :row-fn function has side-effects after each row was read and passed to it. Our function returns a result, the mean of ages.
(let ((sum-ages 0)
      (nb-ages 0))
  (cl-csv:read-csv #p"persons.csv"
                   :row-fn (lambda (values)
                             (incf sum-ages (parse-integer (nth 1 values)))
                             (incf nb-ages)))
  ;; Age mean:
  (/ sum-ages nb-ages))
Using cl-csv's reader information for debugging
cl-csv makes efforts to tell us where it is at its parsing. Here's where to find the bits of information that will help us during debugging.
In this dummy example, we'll observe cl-csv's hints:
;; this is uncomplete CSV, parsing will raise an error:
(cl-csv:read-csv "Alice,7,1
Bob,77,0
Oh?")

;; =>

The value
  NIL
is not of type
  STRING
when binding STRING
   [Condition of type TYPE-ERROR]

Restarts:
 0: [RETRY] Retry SLIME REPL evaluation request.
 1: [*ABORT] Return to SLIME's top level.
 2: [ABORT] Exit debugger, returning to top level.

Backtrace:
  0: (SB-IMPL::PARSE-INTEGER10 NIL 0 NIL NIL) [external]
  1: ((LAMBDA (VALUES)) ("oh?"))
  2: (CL-CSV::READ-CSV-WITH-READER #P"persons.csv" :CSV-READER NIL :ROW-FN #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}> :MAP-FN NIL :DATA-MAP-FN NIL :SKIP-FIRST-P NIL)
      Locals:
        #:.DEFAULTING-TEMP. = NIL
        CSV-READER = #<CL-CSV::CSV-READER LINE-IDX:2 CHARACTER-LINE-IDX:4 CHARACTER-IDX:23 "" {1203B99343}>

        ^^^^^ let's see more about this READER object.

        DATA-MAP-FN-P = NIL
        IN-STREAM = #<SB-SYS:FD-STREAM for "file /home/vindarel/cl-cookbook/persons.csv" {1203B96553}>
        MAP-FN-P = NIL
        #:NEW3 = #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}>
        #:NEW5 = NIL
        #:NEW7 = NIL
        #:NEW9 = NIL
        ROW-FN-P = T
        STREAM-OR-STRING = #P"persons.csv"
  3: (CL-CSV:READ-CSV #P"persons.csv" :ROW-FN #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}>)
We don't see everything. Click or press Enter on the CSV-READER that is on the 2nd backtrace:
#<CL-CSV::CSV-READER {1203B99343}>
--------------------
Class: #<STANDARD-CLASS CL-CSV::CSV-READER>
--------------------
 Group slots by inheritance [ ]
 Sort slots alphabetically  [X]

All Slots:
[ ]  AFTER-QUOTED?      = NIL
[ ]  BUFFER             = ""
[ ]  CHARACTER-IDX      = 23         <------------ useful: character index in the file
[ ]  CHARACTER-LINE-IDX = 4
[ ]  DATA-MAP-FN        = CL-CSV::MAP-EMPTY-STRING-TO-NIL
[ ]  ENTRIES            = #(#<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B98F93}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B99033}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B990D3}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B99173}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B99213}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B992B3}>)
[ ]  LINE-DATA          = #()
[ ]  LINE-IDX           = 2           <------------- useful: line index
[ ]  MAP-FN             = NIL
[ ]  PARSE-STREAM       = #<SB-SYS:FD-STREAM for "file /home/vindarel/cl-cookbook/persons.csv" {1203B96553}>
[ ]  READING-QUOTED?    = NIL
[ ]  ROW-FN             = #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}>
[ ]  ROWS               = #()
[ ]  SKIP-ROW?          = NIL

[set value]  [make unbound]
Knowing the line causing an error and the file position is useful.
cl-csv and data-table: column names, column types, columns manipulation
data-table is a library by the same authors that brings a data structure that represents our CSV data.
A data table has rows of data, associates names to the columns, and guesses columns types.
Then, we can access values by row and column names, and manipulate columns (add data, take a substract etc).
We link cl-csv and data-tables together with the system cl-csv-data-table (defined in cl-csv).
(ql:quickload '("cl-csv" "data-table" "cl-csv-data-table"))
You don't need to go read its README, as it is poorly documented (only in tests).
We'll use the second CSV file, persons2.csv.
Let's parse it:
(cl-csv:get-data-table-from-csv #p"persons2.csv")
;; =>
#<DATA-TABLE:DATA-TABLE {1205D151C3}>
This returns a DATA-TABLE object. What is it? We can inspect it:
(inspect *)

The object is a STANDARD-OBJECT of type DATA-TABLE:DATA-TABLE.
0. COLUMN-NAMES: ("name" "age" "lisper")
1. COLUMN-TYPES: (STRING INTEGER INTEGER)
2. ROWS: (("Alice" 7 1) ("Bob" 77 0))
We observe:
- the data-table used our headers row
- the columns' types were inferred: "name" is a string, "age" and "lisper" are integers.
- in each row, the "age" and "lisper" fields were parsed to an integer.
Let's save our result to a parameter:
(defparameter *dt* **)
Get all rows with:
(data-table:rows *dt*)
Instead of accessing a column by its index, you can access it by its name.
Use data-table:data-table-value dt &key row row-idx col-name col-idx.
For example, what is the "name" of the first row?
(csv:data-table-value *dt* :row-idx 0 :col-name "age")
;; => 7
The library has more functions to manipulate columns and data-tables. We give them as a reference, and then we'll see how lisp-stat does it.
data-table:number-of-rows and data-table:number-of-columns
data-table-to-plists, plists-to-data-table
Add columns together with (csv:add-column dt column-name [default] [column-type] [index]).
Select columns with (csv:select-columns table column-names) to create a new data-table.
In this example, we create a new data-table object with only 2 columns. We also inverted their order.
(csv:select-columns *dt* '("age" "name"))
;; =>
#<DATA-TABLE:DATA-TABLE {1203F88213}>
CL-USER> (inspect *)

The object is a STANDARD-OBJECT of type DATA-TABLE:DATA-TABLE.
0. COLUMN-NAMES: ("age" "name")
1. COLUMN-TYPES: (INTEGER STRING)
2. ROWS: ((7 "Alice") (77 "Bob"))
> q
overlay-region new dt :col-idx col-idx :row-idx row-idx): "puts all values from new-dt into dt starting at row-idx col-idx".
make-sub-table parent :uri uri :lri lri :uci uci :lci lci:
Make a new data table from a subset of another data-table
   lci - low column index
   uci - upper column index (as per subseq 1 beyond the col you want)
   lri - low row index
   uri - upper row index (as per subseq 1 beyond the row you want)
Write a data-table to a file (or any stream) with (data-table-to-csv dt &optional stream)
All this is good, but today lisp-stat does this, and more.
lisp-stat's Data Frame
lisp-stat is a powerful library.
Lisp-Stat provides a statistical computing engine comparable to R, Python, Julia and Matlab. Its major differentiators are a true REPL based development environment, high performance and a single binary image that can be moved through the devops pipeline in a secure, safe and manageable way.
It integrates with Jupyter notebooks, to Quarto, it can load R datasets...
It's pretty good and actively used and developed.
It interests us for its Data Frame. You should go read its documentation ;)
Let's load the library:
(ql:quickload :lisp-stat)
We'll give a brief showcase. For this, we'll go to the ls-user package. It is "the package for you to do statistics work".
(in-package :ls-user)
We can read a CSV file with read-csv. This function is actually not the one we used so far with cl-csv, it is a wrapper around fare-csv.
So, using another separator is different, use fare-csv:*separator*.
(defparameter *persons-df* (read-csv #p"persons2.csv"))
;; => *PERSONS-DF*
It is important we used our file persons2.csv which contains the first row with column names.
We can start working with our data.
How do we get all names of our dataset? Simply like this:
LS-USER> (column *persons-df* 'name)
#("Alice" "Bob")
That's already interesting, isn't it?
Observe that: - the result is not a list, it is an array.
lisp-stat has a notation trick to access data in an even shorter way. For this, we need to define an "environment" with defdf:
LS-USER> (defdf persons (read-csv #p"persons2.csv"))
;; => #<DATA-FRAME (2 observations of 3 variables)>
Observe that: - we deliberately didn't use "*earmuffs*" around "persons" - the environment already gives us information: it saw 2 rows and 3 columns.
Now, we can get all names simply with:
LS-USER> persons:name   <----- you can use auto-completion, of course.
;; => #("Alice" "Bob")
all ages:
LS-USER> persons:age
;; => #(7 77)
We can inspect the shape of our data:
LS-USER> (head persons)

;;   NAME  AGE LISPER
;; 0 Alice   7      1
;; 1 Bob    77      0
Using another function, select, we can get all ages with:
LS-USER> (select persons t 'age)
;;                      ^^^ take the age of all rows
But with select we can get a subset of values:
LS-USER> (select persons '(0 1) 'age)
;;                         ^^^ our subset (it's all our data lol)
;; => #(7 77)
We can get values of some columns:
LS-USER> (columns persons '(age name))
;; => #(#(7 77) #("Alice" "Bob"))
We can get a high-level description of our dataset:
LS-USER> (describe persons)
PERSONS
  A data-frame with 2 observations of 3 variables

Variable | Type | Unit | Label
-------- | ---- | ---- | -----------
NAME     | NIL  | NIL  | NIL
AGE      | NIL  | NIL  | NIL
LISPER   | NIL  | NIL  | NIL
This shows that the columns' types were not inferred. Can we fix this?
LS-USER> (heuristicate-types persons)
NIL

LS-USER> (describe persons)
PERSONS
  A data-frame with 2 observations of 3 variables

Variable | Type    | Unit | Label
-------- | ----    | ---- | -----------
NAME     | STRING  | NIL  | NIL
AGE      | INTEGER | NIL  | NIL
LISPER   | BIT     | NIL  | NIL
Yes, now they are.
We can now manipulate columns: add, remove, rename, replace, transform... as well as rows: add, count, loop over (do-rows), map into, mask, filter...
Everything is in lisp-stat's documentation!
Utilities
Print data in an ascii table
We saw how to do that with lisp-stat's head function.
We have another solution with the cl-ansi-term library.
(ql:quickload '("cl-ansi-term"))
Its global nickname is term (warn: global nicknames are now legacy, prefer package-local nicknames).
We use term:table to print our tabular data.
(let ((csv (cl-csv:read-csv #p"persons2.csv")))
  (term:table csv))

;; =>
+-----+---+------+
|name |age|lisper|
+-----+---+------+
|Alice|7  |1     |
+-----+---+------+
|Bob  |77 |0     |
+-----+---+------+
It has a few more options. With many columns, you could display only a chosen set of columns. You can style cells programmatically, etc.
See also
- acknowldegment: read CSV files in CL on dev.to
- auto-text, automatic detection for text files (encoding, end of line, column width, csv delimiter etc). inquisitor for detection of asian and far eastern languages.
- CLAWK, an AWK implementation embedded into Common Lisp, to parse files line-by-line.
- redditors' feedback about duckdb, SBCL maintainer's fast parsing snippet.
07 Nov 2026 1:12pm GMT
05 Nov 2026
Planet Twisted
Glyph Lefkowitz: Why You Should Care About The Political Project of Twisted
Twisted was originally the network component of a text-based role-playing game engine. In the late 90s when it was first developed, the idea of a video game being able to send you actual emails and instant messages1 seemed pretty neat, rather than the valence that it would have today (nightmare). We never ended up making an actual game, so we eventually removed the "game engine" piece, and just kept the protocol implementations of the email and the AOL Instant Messenger, and the DNS and eventually SSH and so on. The residual pieces of that project have not seen maintenance for a decade.
So it's not really a way to make a text-based game any more.
Then, Twisted was the premier longest-lived and best-maintained event-driven I/O library for Python. If you wanted to make high-performance servers, it was the best and most obvious way to do it. Even if it still acquits itself relatively well in this regard, its claim to fame, and to indispensability, has been somewhat obviated by the inclusion of asyncio in the standard library. Even if it has some stuff to recommend it - better-than-average testing facilities, for example - you can get better-documented and better-integrated low-level asynchronous networking tools without even installing any packages.
So it's not really the premier choice for an event-loop these days.
Twisted does still contain an SSH server and client, an email server and client, a DNS server and client, a web server and client (now including websockets). But you can cobble these together by installing a variety of packages from other sources.
So... it's a bunch of protocols? And I guess it doesn't use AI? But... why would anyone care about that? Why contribute to such a thing?
What is Twisted doing, and who is it doing it for? What is the political project of Twisted, nigh on 30 years into its existence?
Most of all, why should you care about it, or want to contribute?
If you're asking what you could use Twisted for today, it's an excellent choice if you're implementing a new network service and you need more than one protocol. If you need to do HTTP, DNS, packet capture, and a custom SSH server, it would be very hard to arrange a collage of other Python packages to manage this. It's still much better at deterministic testing than most of the standard library. It's a bit easier to hook into a GUI.
But that's not what Twisted is doing.
What I want Twisted to do for the world is still an unfinished project. It's honestly kind of bad at doing what I want it to, but it could be great. The overarching goal of having and maintaining all this stuff is to, as much as possible, demystify networked software operation and let you build Internet facing systems at a human scale.
It's all in a memory-safe language with good error handling, so you can avoid the scariest security pitfalls. It's all integrated into a single paradigm with built-in tools for testing. It's designed to scale down to be runnable on the average laptop, and not require large elaborate server farms or distributed clusters to run. Via the twist command line utility, it provides a Swiss army knife of simple tools that you can use out of the box.
In a world where all of our compute is in massive distant opaque datacenters, where a tiny cartel of gigantic tech companies control nearly the whole supply chain, one of the few things that you still can have agency over is your own server on the Internet.
It's still possible to get a domain name for a few bucks a year, a free-tier or very low-cost VPS, then stick a glue record in and run your own DNS. From that point forward, you can run your own email, your own web server, your own terminal server. But doing this requires deep expertise, and that expertise requirement is massively inflated by the operational concerns that go with running twenty different pieces of software from twenty different projects, probably in twenty different languages, with completely inconsistent aesthetics.
The reason that Twisted is event-driven is because as much as it can be a pain to wrap your head around async/await (or worse yet, Deferred directly), it is much easier for a single person to understand the concurrency requirements of an async I/O multiplexed system than to understand what is going on with an application that requires multiple thread pools. It is possible to understand concurrent code that manages parallel tasks in that idiom. The reason that Twisted integrates so many different protocol implementations and attempts2 to unify them with a common authentication layer is to reduce the overhead required to manage a comprehensive suite of network services.
Even the not-using-AI thing is not an aside due to some accidental personal preference about tools - it's a core part of building an engine that you can personally understand if you dive into it, that's built with a consistent style and layered in a way that you can take apart if you need to. It's not built with AI because we're not building for AI, we're building for people and the entire point is that people are supposed to be able to understand it.
We used to have a tag line, which is somewhat less emphasized these days because its meaning is not immediately clear without this background, but was once quite prominently featured on the home page: "Twisted: Building the Engine of Your Internet". That's what I want to bring to you: an engine for you to build your Internet, that is small enough that you can make it personal, that doesn't require massive investment in management tooling just to get started.
Now, for various reasons, I no longer use twisted.names to host my own DNS (although I did for many years!), and we never wrote enough of a twisted.mail suite for it to be usable for email hosting on its own. But, if you're reading this article, it was probably delivered to you directly via Twisted's own twisted.web HTTP server, using twisted.protocols.tls to configure our own OpenSSL TLS termination. I have run with extremely high reliability for years and next to zero management overhead, in a single simple docker container. Which I then administer and upload files to via Twisted's own twisted.conch SSH server.
If that seems like an appealing project and you'd like to volunteer to help out, drop me a line and maybe I can point you at some tasks to get started. Twisted falls far short of this aspiration despite 30 years of work, and we could use all the help we can get.
Acknowledgments
Thank you to my patrons who are supporting my writing on this blog. If you like what you've read here and you'd like to read more of it, or you'd like to support my various open-source endeavors, you can support my work as a sponsor!
05 Nov 2026 10:51pm GMT
30 Oct 2026
Kernel Planet
Matthew Garrett: Getting Google Cast on my Soundbar
I have a Samsung Q800A soundbar. It ships with built-in support for the Apple Airplay protocol, but I'm not really an Apple kind of guy so that's never been particularly helpful for me. So, instead, I have a Chromecast Audio plugged into it via TOSLINK, and that works fine - except for the fact that there's no way to explicitly pick TOSLINK as the audio input. Instead, there's a "Digital In" option that refers to both the optical in and eARC input from a TV. Not inherently a problem, given I'm unlikely to be watching TV while listening to music, but my TV is a Samsung Frame, a device that's intended to display art whenever someone is standing nearby, and which infuriatingly generates an eARC signal even if it's only in art mode and isn't going to make any noise. This switches the soundbar away from optical and I get sad. I could plug a video cast device into the HDMI port on the soundbar and cast audio to that, but then the art would get replaced with album covers whenever I'm playing music, and again that's not quite the ambience I want. Still, none of this is that important.
Until I learned that the Australian version of the soundbar does have Google Cast support. The firmware image was downloadable from Samsung support, so I grabbed that, but unfortunately found that it was encrypted. However, if I downloaded the firmware image for the US model, the encrypted blob was identical - there's no difference in the underlying firmware between the two of them. So, how come one has support, and the other doesn't?
I'd need an unencrypted copy of the firmware to have a real chance of figuring this out, and the easiest way to get one was to just run an ebay watch for a broken model of the same series. Once I had one in my hands I used hot air to remove the eMMC storage from the device, cleaned up the chip, and then stuck it in one of these adapters to read it on a local system. Samsung uses a weird in-house filesystem called VDFS4 on some of their devices and this was one of them, so I needed to cobble together a kernel that was compatible with their source dump for this device (not all VDFS drivers seem to be able to read all VDFS filesystems), but eventually I had it all extracted, and then I got distracted by other stuff, so let's fast forward to this week.
Samsung makes use of a modified version of the Android Debug Bridge called sdb, which is included in the Tizen SDK. The firmware showed that this device had sdbd on it, and it would be executed if a network device called "huart0" was plugged in. Samsung does, thankfully, provide the source code for their GPLed components, so I could dig through that to discover that drivers/net/usb/usbnet.c had a bunch of references to huart (which apparently stands for "HyperUART"). If CONFIG_SAMSUNG_USBNET_HYPERUART_IFNAME is set, and if the ethernet device is using either the asix or ax88179_178a drivers, and if "/opt/etc/HyperUART_IP_Addr"1 isn't just "0", it sets the interface name to "huart0" and in turn triggers sdbd startup. So now I just needed to figure out how to set /opt/etc/HyperUART_IP_Addr to something else.
Some digging revealed a binary called wap-factory that referenced the file, which then led to /usr/share/mobile-mgr/jsons/com.samsung.audio.waapp-verification-test.json which mentioned a "SetUartOnOff" call, which brought me here2, which led me into a bit of a rabbit hole about the Samsung WAM protocol. Long story short, you connect to either port 55001 or 56001 and make two requests over the same connection:
|
|
and then plug in an asix chipset ethernet adapter into the USB port (which on mine is micro-B, so I needed an OTG adapter), and suddenly it's sitting there on 192.168.250.250 and will speak sdb to you. sdb root on switches it into root mode, and sdb shell now gives you a root shell. I was in, and now I could investigate what was happening.
First up, there was a process called "com.samsung.audio.google-cast-control-app" running, which seemed like a good start. Unfortunately it wasn't doing anything. After some tracing I found that it was making a call to Samsung at startup time, and getting back a response telling it that Cast support wasn't available. The request (which was helpfully dumped to stdout when I ran this by hand) included the country code, in my case "US". Repeating the request by hand with curl and changing the code to "AU" told me it was supported, so now I needed to figure out how to get the soundbar to believe it was Australian. Some digging showed it was reading this from a config variable called db/comss/countrycode, and running
|
|
got me past that gate. Now, however, it was complaining that it couldn't provision a key. /usr/apps/com.samsung.audio.google-cast-control-app/shared/res included a bunch of encrypted blobs and an app called teeStoreKey.elf, and tracing com.samsung.audio.google-cast-control-app showed it was trying to call that, but it seemed like it was failing with a permissions issue. Running com.samsung.audio.google-cast-control-ap directly as root triggered key provisioning successfully, and a few seconds later the rest of the Cast API came up and I could talk to port 8443 with standard Cast API calls. Unfortunately it still wasn't working as a Cast device, though - it wasn't advertising itself via mDNS and so nothing could see it. Querying the /setup/eureka_info endpoint gave me a clue - the 'tos_accepted' field was false. Normally this would be set as part of initial device setup, but the Samsung app wasn't doing that because it didn't think the device had Cast support. It turns out that POSTing some json with {"tos_accepted": true} to setup/set_eureka_info made it work, and suddenly there was an additional Cast device available to me.
(Update: I realised I didn't mention anything about why it was doing key provisioning in the first place! The Cast protocol doesn't enforce cryptographic identity as such, but Google's reference client implementation which is what almost everything uses verifies that the device is presenting an identity that chains back to Google. Unsurprisingly they don't want the private key material to be easily extractable and used to produce clone devices, so it's all supposed to be encrypted and only accessible to some sort of trusted execution environment, which is why keys here need to be loaded into Trustzone and never be visible in the clear to the main OS)
Mission accomplished. Unfortunately the device vanished from my Smartthings home aferwards, presumably because there's a mismatch between its reported country code and my account country. To get around that I'd somehow need to get com.samsung.audio.google-cast-control-app to either change the query without changing the global device country, or to ignore the response from Samsung (it does this every 24 hours, ugh), and that's made more annoying by the fact that this thing will only execute signed binaries. Although, weirdly, one of the signed binaries shipped is a full Python interpreter, so if I cared enough I could probably cobble together enough Python to execute arbitrary binaries. I currently don't.
More modern soundbars don't implement the listener on port 55001 or 56001. I don't know how you get sdb working on them.
30 Oct 2026 6:03pm GMT
28 Oct 2026
Kernel Planet
Linux Plumbers Conference: The sched_ext Microconference
The sched_ext Microconference was very active this year at Linux Plumbers in Prague. It featured
six talks, preceded by an opening discussion on the future direction of sched_ext.
(Written by Andrea Righi)
Three main topics dominated the discussions
- Priority inversion and how to handle it in sched_ext: lock holder and
lock waiter preemption, time slice extension, and making proxy execution
work together with BPF schedulers. - Paravirtualized scheduling: letting the host and guest schedulers
cooperate across the VM boundary, with sched_ext as the policy engine on
the host. - Device and topology-aware scheduling: using hardware feedback (Intel
HFI), device/accelerator locality and cache topology to drive task
placement.
Intro: where sched_ext is going
The opening discussion outlined three directions for sched_ext development:
- Move more into BPF. With BPF arenas, queuing and idle CPU management can
be implemented entirely in BPF, and several schedulers are already
converging on this model. Once they all move, a significant amount of
in-kernel sched_ext code can be removed. - Composability. Long discussed, now a good time to tackle it: reusable
BPF/user-space building blocks (load balancer from one scheduler, idle CPU
selection from another, etc.) that can be combined into new schedulers. - Generate BPF code from Rust. Most schedulers today are Rust in
user space plus C for the BPF part. The trend, aligned with the wider
BPF community, is to generate the BPF code from Rust as well, so a
single language and shared abstractions can be used to access
scheduling data structures from both sides. Prototypes exist but this
is not there yet.
Priority inversion
Making proxy execution compatible with sched_ext
(Andrea Righi and John Stultz)
Proxy execution lets a mutex-blocked task lend its scheduling context to the
lock owner. The work presented makes this compatible with sched_ext, with
support enabled explicitly by each BPF scheduler. Dispatching a blocked task
triggers the core proxy machinery, keeping the BPF scheduler in control.
The compatibility changes and follow-up improvements are queued for Linux v7.4.
Distributions will be able to enable both `CONFIG_SCHED_PROXY_EXEC` and
`CONFIG_SCHED_CLASS_EXT` in the same kernel, removing their previous mutual
exclusion. The follow-up changes will also make proxy migrations transparent to
BPF, without exposing intermediate bookkeeping through extra enqueue callbacks.
Discussion points:
- User-space locks: futexes are not covered since `FUTEX_WAIT` does not
identify the owner. A new futex op that carries ownership is being explored;
passing user-space owner hints (e.g., via BPF maps or futex flags) is
inherently racy. A "directed yield" (timed proxy to a specific task) was
mentioned as future work. - rwsems / semaphores: writer boosting is supported via a patch; boosting
multiple readers is harder and has overhead. Plain semaphores have no owner
and cannot be proxied. - Observability: there are no upstream tracepoints for proxy execution
yet, which makes traces confusing (the owner runs under the donor's
context). Something similar to the existing PI tracepoints was requested.
Taming latency spikes caused by lock holder and lock waiter preemption
(Changwoo Min)
On the Steam Frame VR headset, camera processing must finish within 33ms but
needs only about 7-8ms of CPU time. Under heavy gaming load, preempting a lock
holder or delaying a woken lock waiter can stretch the pipeline enough to miss
that deadline.
LAVD addresses both cases with time slice extension and boosting of lock
waiters. The mitigations reduced scheduling delays above 2ms across four games,
with no missed camera frames observed during an hour of gameplay in the tested
titles.
A common interface for lock ownership and waiting information, covering kernel
and user-space locks, would help replace scheduler-specific heuristics.
Discussion points:
- Abuse of the extension is bounded by fairness: a task that constantly
extends its slice is deprioritized. - Why not just rely on proxy execution? Proxy is reactive (owner scheduled
out, donor scheduled in, owner scheduled in again), with extra overhead.
The consensus was that the two approaches are complementary: slice
extension is like a spinlock (cheap, good for short critical sections),
proxy execution is like a mutex (heavier, but handles long ones).
Paravirtualized scheduling
Bridging the VM Boundary: Scheduling Passthrough via pvsched and sched_ext
(Josh Don and Vineeth Remanan Pillai)
A host scheduler normally sees opaque vCPU threads, without knowing whether
they are running urgent guest work or background jobs. pvsched provides a
bidirectional channel: guests communicate priorities and preemption hints,
while hosts report which vCPUs they can run concurrently.
The proposed v3 design moves negotiation into the VMM through a virtual PCI
device, keeping policy outside KVM. On the host, sched_ext can implement bounded
vCPU boosting and gang scheduling. Guests can concentrate work on the vCPUs the
host can actually run, reducing the cost of double scheduling.
The next revision is still to be posted upstream.
Discussion points:
- BPF arenas as an alternative to a dedicated device: a host scheduler
could allocate an arena, hand out per-guest chunks and get zero-copy
communication with no kernel changes, needing only a way to pin arena
memory. Someone from the audience pointed out that allocating memory on
the host and mapping it into the guest on the fly is slow (memslot
creation, guest notification), which is why guest-initiated allocation was
chosen. However, this cost can be avoided: the host BPF scheduler can
create the arena once when it is started and hand out per-guest chunks
from the preallocated arena, mapping each chunk when the guest is set up
rather than on the fly, which keeps the fast path cheap. It was also
noted that the device model keeps the handshake arch-agnostic and
evolvable without kernel changes. - There is related work from others in this area; the agreement was that
the various efforts should converge on a single kernel module, possibly
alongside a BPF-arena-based path. - Standardization: post the kernel module first, then the QEMU device, then
other VMMs. - The preferred-CPU framework (steal governor) is related, but reactive,
while pvsched allows an explicit policy.
Device and topology-aware scheduling
Automatic placement of accelerator workloads
(Balbir Singh and Lee Trager)
CPU and memory placement can have a large effect on accelerator performance,
but manual pinning requires applications or administrators to know the topology
and device usage in advance. The proposed alternative combines hints about
which device a task is using, sched_ext task placement, and memory-access
telemetry to guide page placement. PMU counters were also suggested as a source
of remote-access and bandwidth telemetry to inform those decisions.
Two interfaces are needed: a generic process-to-device association and BPF
control over NUMA placement preferences. A series enabling NUMA balancing under
sched_ext had recently been posted, together with a kfunc for requesting a
preferred memory node.
Discussion points:
- Exposing PMU telemetry to non-root applications raises side-channel
concerns; IPC is fairly safe, cache/TLB misses are a gray area. An
allowlist of audited events was suggested. - Is a BPF map the right interface, or is a common user-space library needed
so all frameworks can provide hints? - Migrating network-heavy tasks across nodes may interact badly with per-CPU
queues and TCP flows. - NUMA balancing needs improvements, including asynchronous migration and
charging migration work to the right task. Enabling it under sched_ext
reuses the existing mechanism, so that work can proceed in parallel with
those fixes. Telemetry-driven `move_pages()` can serve as an interim solution.
HFI plug-in for sched_ext
(Srinivas Pandruvada)
Intel's Hardware Feedback Interface supplies per-CPU performance and efficiency
hints that reflect the platform's changing power budget. Integrating these
hints into LAVD improved Shadow of the Tomb Raider performance by about three
frames per second on a hybrid Intel handheld at a 10W power limit.
The prototype took less than a month. A Rust user-space thread receives HFI
updates over netlink and passes them to BPF through a map; LAVD then adjusts CPU
selection and effective capacity.
Discussion points:
- Why is HFI not used by the in-kernel scheduler? Older generations were too
noisy, and the firmware was tuned mostly on Windows workloads; the last two
generations treat Linux on equal footing, so it is worth revisiting. - Qualcomm's WALT has a similar CPU isolation feature (thermal and
low-utilization cases), implemented downstream via Android vendor hooks. - The preferred-CPU framework (steal governor) could be a natural in-kernel
hook for HFI exclusion. The thermal pressure signal filter currently only allows
slowing down the reaction time, and patches to make it configurable in both
directions may be revisited given how fast firmware can now report changes. - The HFI code is structured as a library and was proposed for inclusion in
the scx library so other schedulers can reuse it.
Stickiness: keeping tasks cache-warm in the work-conserving LAVD scheduler
(Gavin Guo)
Keeping a task on a cache-warm CPU can improve performance, but waiting for that
CPU competes with the benefit of running immediately elsewhere. The session
compared cache-warmth modelling, CPU reservation, and look-ahead dispatch from a
shared queue.
Results depended on the workload and approach. Warmth-based placement improved
P99 latency for short waits, while look-ahead dispatch showed no noticeable
memcached latency improvement under light or moderate load and added overhead
under heavier load.
Discussion points:
- Staying on a busy CPU is a short-term gain, while an idle CPU may offer
long-term uninterrupted execution, so the right answer is very workload-
and topology-dependent (shared vs non-shared L2/L3, snoop efficiency). - Suggestions included using PMU counters (as scx_cosmos already does) or Intel
RDT/CMT for cache occupancy (limited by the number of monitoring IDs),
tracking only latency-critical tasks, and broader workloads such as
stress-ng and video encoders.
28 Oct 2026 2:57pm GMT
26 Oct 2026
Planet Lisp
TurtleWare: Heavenly delights of hashing numbers under EQUALP
Table of Contents
Some time ago I decided to dust off my fast generic function dispatch work for ECL. But before merging that, I decided to optimize the table-based dispatch to have a good measure of how much better or worse it is and that opened a whole can of worms, including a new implementation of hash tables and hash functions.
I know, that's a new level of traversing absurdly nested rabbit holes. There are two good outcomes of this:
- Hash tables and generic function dispatch will be much faster soon
- I got inspired to write another blog post pertaining to Common Lisp
Regarding the first point, here are a few bar graphs generated using polyclot, a work-in-progress McCLIM tool for plotting data (less is better):
Figure 1: SLOT-ACCESS/READER - standard reader benchmark (work in progress).
Figure 2: HTABLE-MIXBAG - EQUALP benchmark with randomized keys.
Figure 3: HTABLE-SETREM - benchmark for interleaved insert and remove.
Figure 4: HTABLE-SMALL-STRING - EQUALP benchmark with short strings.
As for the second point, while working on hashing under various Common Lisp predicates, I decided to bite the bullet and fix a few ugly parts of ECL. Most notably consistent hashing of numbers under the predicate #'EQUALP. The topic is interesting enough to deserve a separate note. In this post I'm assuming binary floats (the float radix is two). This is the float representation used in ECL.
1. Hashing numbers - warmup
1.1. Recap: hash table tests and hash functions
A quick recap about Common Lisp and hash tables. The standard prescribes that conforming implementations must allow specifying the hash table tests EQ, EQL, EQUAL and EQUALP. The last test is interesting, because numbers with different representations are considered to be EQUALP when they are =. For example:
(equalp 1 1.0)           ; -> T
(equalp 1/2 0.5)         ; -> T
(equalp 1/3 (float 1/3)) ; -> NIL
(equalp 42 #C(42.0 0.0)) ; -> T
It is worth noting, that hashing can be lossy, but it can't be inconsistent with the test. In other words this is a conforming hash function under #'EQUALP:
;; (equalp 1 1.0)                        ; is true
;; (= (hash-equalp 1) (hash-equalp 1.0)) ; is true

(defun hash-equalp (x)
  (typecase x
    (real      42)
    (complex   (if (zerop (imagpart x))
                   (hash-equalp (realpart x))
                   13))
    (otherwise 15)))
While this function is not conforming, because there are objects that are the same under the test and have different hashes:
;; (equalp 1 1.0)                        ; is true
;; (= (hash-equalp 1) (hash-equalp 1.0)) ; is false

(defun hash-equalp (x)
  (typecase x
    (rational  1337)
    (float     7117)
    (complex   (if (zerop (imagpart x))
                   (hash-equalp (realpart x))
                   13))
    (otherwise 15)))
In other words, when two objects are equal under the supplied test, they must produce the same hash, but two objects having the same hash does not imply that they are equal under the supplied test.
Naive hashes, while conforming, miss the point. A good hashing function tries to produce different hashes for objects that are not equivalent under the predicate with a good bit distribution to ensure good hash table performance.
1.2. Recap: the numeric tower and mathematical equivalence
Common Lisp has a full numeric tower:
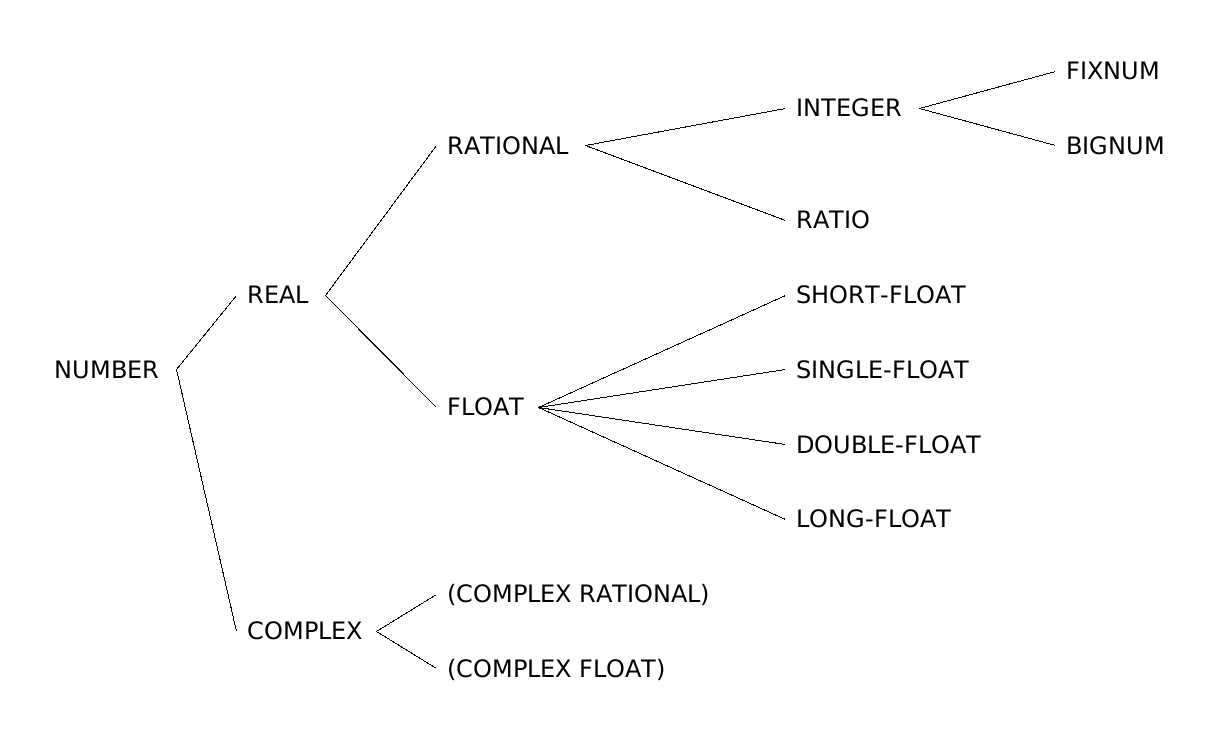
Figure 5: Common Lisp numeric tower.
Note that when complex floats have specialized representation, then there may be multiple subtypes specialized to single-float, double-float etc. Numbers are #'= to each other when their value is mathematically the same, regardless of the underlying representation. That's a wonderful quality when you do math :-).
This quality is not so wonderful, when you want to produce good hashes under the predicate #'EQUALP (that boils down to #'= for numbers). We need to construct a function that will produce the same hashes with good quality for equal objects.
The biggest hurdle comes from the gap between representations of RATIONAL and FLOAT objects. Conventionally representations are
- fixnum
- a single word with a few bits chopped to fit the tag
- bignum
- an array of "limbs", that is parts of the integer (plus sign)
- ratio
- a pair of two integers
- float
- a pair of N-bit mantissa and K-bit exponent (plus sign)
- (complex rational)
- a pair of two rationals
- (complex float)
- a pair of two floats of the same type
Fixnums, bignums and ratios are disjoint under #'=. That leaves us with questions:
-
When are two complex numbers mathematically equal?
This one is easy. Two complex numbers are equal when their real parts are equal and their imaginary parts are equal.
-
When are two floats mathematically equal?
To resolve this question we can cast the float with smaller precision to the float with bigger one and compare bits. There is a gotcha in that -0.0 is not EQL to +0.0, but it is always = to it, so we should canonicalize zeros first.
-
When is an integer mathematically equal to a float?
When the float has no fractional part and integers are equal.
-
When is a ratio equal by #'= to a float?
This is the most interesting question. To answer it, we need to dive a bit deeper into float representation.
Finite binary float values conceptually are represented as:
(* sign mantissa (expt 2 exponent))This corresponds to dyadic rationals, that is rational numbers whose denominator is a power of two:
(/ n (expt 2 k))In other words a float and a ratio may be equal only when the ratio is dyadic, otherwise the ratio value can't be represented as a binary float (this post assumes that we operate on binary floats - with radix=2).
That sums up the recap about mathematical equivalence and numeric tower in Common Lisp.
1.3. Establishing the baseline
The easiest, yet useless, approach is to always return a hash 42. It is adequate because that is the canonical answer to the most important question.
The easy and useful approach relies on the observation that hashing is lossy. All real numbers are coerced to a float precision and hashed. When the rational number does not fit in the float precision, then we hash its approximation. We need to remember to canonicalize -0.0 to +0.0 and to disable floating point exceptions for cases like overflows and underflows.
#define hash_single_float(h,v) hash_float((h), (double)(v))
#define hash_double_float(h,v) hash_float((h), (double)(v))

static inline void
hash_float(cl_hashstate *h, double v)
{
  if (v==-0.0) v=0.0;
  hash_data(h, &v, sizeof(v));
}

static inline void
hash_long_float(cl_hashstate *h, long double v)
{
  ECL_WITHOUT_FPE_BEGIN {
    hash_float(h, (double)(v));
  } ECL_WITHOUT_FPE_END;
}

#define hash_fixnum(h,x) hash_float((h),(double)ecl_fixnum(x))
#define hash_bignum(h,x) hash_rational((h),(x))
#define hash_ratio(h,x)  hash_rational((h),(x))

static inline void
hash_rational(cl_hashstate *h, cl_object x)
{
  ECL_WITHOUT_FPE_BEGIN {
    double v = ecl_to_double(x);
    hash_float(h, v);
  } ECL_WITHOUT_FPE_END;
}
This model is conceptually obvious, very maintainable, reasonably fast, and there are relatively few collisions under the usual workload. We pay for it in a few ways:
- Aesthetically it is not pleasing - crude even.
- "Relatively few collisions" applies only to toy examples, once we start using bigger integers and more precise ratios, the problem starts to show. For example 260 and 260+1 hash identically and that matters for 64bit IDs and timestamps.
- Performance-wise we drop the ball for integers and rationals - we convert numbers between formats even when we could hash only a chunk of memory.
This list is ranked by importance as I see it. The main reason I've kept digging deeper is that it was not to my taste. Then we had impracticality for serious workloads, finally microoptimizations. I believe that the general audience has these priorities in a reversed order.
2. Hashing numbers - round one
A harder but more precise way to hash numbers under the predicate #'EQUALP is to introduce canonicalization rules:
-
Integers are hashed as integers
In the case of FIXNUM we hash its value (a word without the tag) and in the case of BIGNUM we hash the sign and its limbs.
-
Finite floats without the fractional part are hashed as integers
Ensures INTEGER <-> FLOAT correspondence. We can't cast LONG-FLOAT to DOUBLE-FLOAT and then cast to integer, because we'd miss many BIGNUM values. Caveat: with this approach big floats may cons full bignums.
-
Floats that are not integers are cast to DOUBLE-FLOAT and hashed
Ensures X-FLOAT <-> Y-FLOAT correspondence. This approach is lossy for long floats if they have more bits than double floats, but simplifies the implementations because long double has a few "loose" bits that may differ between numbers with the same value.
NaNs and infinities are hashed like other doubles because infinities are exact and NaN is never #'= to anything.
-
Dyadic ratios are hashed as DOUBLE-FLOAT
Ensures FLOAT <-> RATIO correspondence. For simplicity we don't try to determine whether RATIO is representable as DOUBLE-FLOAT - if it is too big or too small, it will be represented either as a 0 or as an infinity.
-
Other ratios are hashed as pairs
We hash the numerator and denominator separately.
-
Complex floats with
(ZEROP (IMAGPART X))are hashed as(HASH (REALPART X))Because
(= 3 #c(3.0 0.0))we need to canonicalize(complex float)while rational complex numbers are canonicalized implicitly. Other complexes are hashed as pairs, that is we hash the real part and imaginary part separately.
This approach results in fewer collisions and is fairly straightforward. Here is the pseudocode:
(defun hash-equalp-number (state number)
  (typecase number
    (fixnum  (hash-word state number))
    (bignum  (hash-data state (signum number) (limbs number)))
    (float   (if (and (finitep number) (is-integer-p number))
                 (hash-equalp-number state (rational number))
                 ;; INV -0.0 and +0.0 are hashed as integers.
                 (hash-data state (coerce number 'double-float))))
    (ratio   (if (dyadic-ratio-p number)
                 ;; INV may produce infinity or zero (that's fine)
                 ;; Disable float overflow and underflow traps.
                 (hash-data state (coerce number 'double-float))
                 (progn
                   (hash-equalp-number state (numerator number))
                   (hash-equalp-number state (denominator number)))))
    (complex (if (zerop (imagpart number))
                 (hash-equalp-number state (realpart number))
                 (progn
                   (hash-equalp-number state (realpart number))
                   (hash-equalp-number state (imagpart number)))))))
2.1. Implementation bites
My initial implementation cast all floats to integers. When I was comparing ECL to other implementations I was wondering why we are so slow compared to others. The key insight came after the realization that randomized keys in the form (random 20.0) were collapsed to only 20 distinct hashes.
Fixing that and giving non-integer floats distinct hashes gave ECL the most noticeable boost on the HTABLE-MIXBAG benchmark (included at the beginning) - the new version is 100x faster than the old one.
While implementing a test suite that ensured that hashes for bignums, dyadic ratios, and corresponding floats matched, I've discovered a non-obvious bug pertaining to casting double floats to integers. The code looked like this:
if (d<=MOST_POSITIVE_FIXNUM && d>=MOST_NEGATIVE_FIXNUM) return to_fixnum(d);
else                                                    return to_bignum(d);
But the MOST_POSITIVE_FIXNUM value on x86-64 is 261-1. In other words, to represent this number exactly as a double, we need 61 significant bits. That's a shame because double has 53 significant bits, so MOST_POSITIVE_FIXNUM, when converted to double, rounds to 261 and that can't fit in a fixnum. After promotion the incorrect code is equivalent to:
if (d<=(1LL<<61) && d>=MOST_NEGATIVE_FIXNUM) return to_fixnum(d);
else                                         return to_bignum(d);
Oops, double is accidentally cast to fixnum when it is 261. That's clearly a problem! After finding the issue, the solution is easy. We need to find an exact double that is the boundary. Note that integers are implemented as two's complement, so the most negative fixnum was alright in our case:
double limit = ldexp(1.0, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
if (d<limit && d>=-limit) return to_fixnum(d);
else                      return to_bignum(d);
This fix is correct, yet it revealed another bug. But that's a different story to tell.
3. Hashing numbers - round two
The approach above is correct and nice, but has a few important flaws:
- we cons a lot for big integer floats (2KB/float in the worst case)
- there is a whole class of dyadic ratios that don't fit in long-float
- long floats lose precision after cast to double, notably very small and very big values collapse to 0 and infinity
After the initial implementation it bugged me enough that I've decided to come up with a new hashing scheme for numbers under the predicate EQUALP. The rules are also simpler (at least conceptually):
- Dyadic rationals are hashed as tuples (sign, mantissa, exponent)
- Other numbers are hashed depending on their type (they are disjoint)
The representation [SIGN MANTISSA EXPONENT] does not require us to convert between types and it is very compact. Moreover it is very precise and doesn't produce unnecessary collisions. On the other hand it requires extra work to normalize tuples. Here is the pseudocode:
(defun hash-equalp-number (state number)
  (typecase number
    (integer
     (multiple-value-bind (s m e) (compute-integer-dyad number)
       (hash-dyad state s m e)))
    (float
     (multiple-value-bind (s m e) (compute-float-dyad number)
       (hash-dyad state s m e)))
    (ratio
     (if (dyadic-ratio-p number)
         (multiple-value-bind (s m e) (compute-ratio-dyad number)
           (hash-dyad state s m e))
         (progn
           (hash-datatype-tag state :ratio)
           (hash-equalp-number state (numerator number))
           (hash-equalp-number state (denominator number)))))
    (complex
     (if (zerop (imagpart number))
         (hash-equalp-number state (realpart number))
         (progn
           (hash-datatype-tag state :complex)
           (hash-equalp-number state (realpart number))
           (hash-equalp-number state (imagpart number)))))))
The implementation is a bit less straightforward because we now need to be able to compute mantissa from numbers. A few words about normalization:
- sign is -1, 0 or +1 for finite numbers - that solves normalization of -0.0/+0.0
- mantissa must be a positive odd integer or zero - that unifies all mantissas
- exponent is also an integer, so the number is (* sign mantissa (expt 2 exp))
- to hash unique values (like infinities) we will abuse sign to fit extra values
Every integer is a dyadic rational, so our task is to normalize it so that the mantissa is an odd number and adjust the exponent accordingly.
(defun compute-integer-dyad (number &optional (exp 0))
  (when (zerop number)
    (return-from compute-integer-dyad
      (values 0 0 0)))
  ;; In the real code use COUNT-TRAILING-ZEROS + ASH.
  ;; Loop division is to make the mechanism clear.
  (do ((sign (signum number))
       (mantissa (abs number) (ash mantissa -1))
       (exponent exp (1+ exponent)))
      ((oddp mantissa)
       (values sign mantissa exponent))))
The implementation for float is also straightforward thanks to the function INTEGER-DECODE-FLOAT. We also need to normalize the signed zero:
(defun compute-float-dyad (number)
  (cond ((nan-p number)
         (return-from compute-float-dyad
           (values -2 0 0)))
        ((negative-infinity-p number)
         (return-from compute-float-dyad
           (values -3 0 0)))
        ((positive-infinity-p number)
         (return-from compute-float-dyad
           (values +3 0 0))))
  (multiple-value-bind (mantissa exponent sign)
      (integer-decode-float number)
    (compute-integer-dyad (* sign mantissa) exponent)))
For ratios we will reuse the function that we have not defined in the last section to decide whether the ratio is dyadic and if it is - convert it to the canonical form:
(defun dyadic-ratio-p (number)
  ;; A positive integer is a power of 2 only when exactly one bit is set.
  (= 1 (logcount (denominator number))))

(defun compute-ratio-dyad (number)
  (values (signum number)
          ;; Ratios are already normalized(!)
          (abs (numerator number))
          ;; den = 2^k, shift = k+1 -> exponent = -k
          (- (1- (integer-length (denominator number))))))
Mind that the functions above are deliberately simple to illustrate how they should work. We have also used non-standard functions NAN-P and INFINITY-P that depend on the implementations extensions (or internals).
This is the most satisfying moment in the post - we have found an elegant and universal (in this domain) abstraction that avoids float-to-bignum conversion, hashes unequal numbers differently, and is easy to understand. That's the high point of this post and the reason I've dubbed it "heavenly delights". Alas, it is time to come back to earth and improve its performance. That's where the engineering lives.
3.1. Back to earth
We have an elegant conceptual model. The thing with elegant conceptual models is that they need to be dirtied to make them fast. And that's what we are going to do now: we will bastardize the clean abstraction and make it performant under usual scenarios without sacrificing precision. We are now optimizing.
Simplifications that we can climb down to from our normalized representation [sign, mantissa, exponent] model:
-
When mantissa or exponent exceeds LONG-FLOAT precision, don't normalize the number
As noted earlier, aside from floats, numbers in Common Lisp are disjoint, for example, there are no integers and ratios that are EQUALP to each other. In that case we use the most convenient hashing scheme for the specified type.
-
Dyads representable as fixnums are hashed as a fixnum (a signed integer)
This is an opportunistic optimization tailored for quick fixnum hashing. We already know how to correctly determine when a float can be reliably cast to fixnum and other numbers don't intersect with fixnums.
-
Dyadic ratios in range are cast to
long doubleand hashed as LONG-FLOATThis way we ensure that ratios and floats that are #'= are hashed the same. This is similar to "Round one" approach, but we retain the maximal precision.
-
Integer floats and bignums in range are hashed in a dyadic form
This step allows us to avoid coercing floats to bignums and is a big memory allocation save. A small cost for bignums is that we need to decide before hashing whether it is in the LONG-FLOAT precision range.
-
Long floats exceeding double float precision are hashed in a dyadic form
By avoiding lossy casts to double, we reduce number of collisions. Most notably, very small and very big values are not collapsed to zero and infinity. Such floats are hashed in a dyadic form because x87 floats have additional padding bits that may differ between equal values, so we can't hash memory.
Another minor optimization: we fold the sign and the exponent into a single word to have fewer hash state updates as 8*exponent+sign (sign has maximum 2 bits).
Notice that this scheme is very similar to the "Round one" approach. In practice it only differs in how we treat floats, bignums and ratios:
| object | round 1 | current variant | note |
|---|---|---|---|
integer float |
fixnum or bignum |
fixnum or tuple |
depends on range |
fractional float |
dfloat |
dfloat or lfloat |
depends on precision |
dyadic-ratio |
dfloat |
dfloat or lfloat |
depends on precision |
fixnum |
fixnum |
fixnum |
no change |
bignum |
bignum |
bignum or tuple |
depends on precision |
A few concrete examples should illustrate these simplifications. They do not try to test precise limits and the set is not exhaustive.
I'm assuming that FIXNUM has 62 bits and LONG-FLOAT has 64-bit mantissa, 15-bit exponent and 1-bit for sign - typical on x86 with GCC.
| ## | dyadic number | canonical representation | cast | note |
|---|---|---|---|---|
| 0. | (/ 1 (expt 2 (expt 2 15))) |
(1 1 -32768) |
ratio |
too small |
| 1. | (/ 1 (expt 2 (expt 2 11))) |
(1 1 -2048) |
lfloat |
|
| 2. | 3/8 |
(1 3 -3) |
dfloat |
|
| 3. | 42 |
(1 21 1) |
fixnum |
|
| 4. | most-positive-fixnum |
(1 most-positive-fixnum 0) |
fixnum |
|
| 5. | most-negative-fixnum |
(-1 1 61) |
fixnum |
|
| 6. | (1+ most-positive-fixnum) |
(1 1 61) |
dyadic |
|
| 7. | (1- most-negative-fixnum) |
(-1 2305843009213693953 0) |
dyadic |
|
| 8. | (expt 2 32768) |
(1 1 32768) |
bignum |
|
| 9. | (/ (1+ (expt 2 40)) 2) |
(1 (1+ (expt 2 40)) -1) |
dfloat |
|
| a. | (/ (1+ (expt 2 53)) 2) |
(1 (1+ (expt 2 53)) -1) |
lfloat |
|
| b. | (/ (1+ (expt 2 64)) 2) |
(1 (1+ (expt 2 64)) -1) |
ratio |
too big |
| c. | 13.0 |
(1 13 0) |
fixnum |
|
| d. | (expt 2.0 61) |
(1 1 61) |
dyadic |
|
| e. | (expt 2.0l0 16383) |
(1 1 16383) |
dyadic |
|
| f. | (expt 2.0l0 16384) |
(3 0 0) |
dfloat |
infinity |
- case 0
- the number underflows long-float exponent precision
- case 1
- the number is representable as LONG-FLOAT but not as DOUBLE-FLOAT
- case a
- the number is representable as LONG-FLOAT but not as DOUBLE-FLOAT
- case b
- the number overflows LONG-FLOAT mantissa precision
- case e
- the number narrowly fits in LONG-FLOAT
- case f
- the number overflows LONG-FLOAT (infinity) - may signal a condition
Illustrative pseudocode:
;;; There is something to be said about conventions. Our dyadic representation
;;; treats the mantissa as an odd integer, but the C representation of floats
;;; treats the mantissa as a fraction [0.5, 1.0). In practice this means that
;;; exponents in our canonical representation must be recalculated, because:
;;;
;;;   our-mantissa === (shift-to-odd (ash float-mantissa +ldbl-mant-dig+))
;;;   our-min-exp  === (- +ldbl-min-exp+ +ldbl-mant-dig+)
;;;   our-max-exp  === (- +ldbl-max-exp+ (integer-length our-mantissa))
;;;
;;; Note that FLOAT-MANTISSA assumes a fraction, but in practice we can usually
;;; extract bits directly and skip the shift by interpreting it as significand.
(defun hash-dyadic-number (state number)
  (multiple-value-bind (sign mantissa exponent)
      (dyadic-representation number)
    (let* ((num-len (integer-length mantissa))
           (min-exp (- +ldbl-min-exp+ +ldbl-mant-dig+))
           (max-exp (- +ldbl-max-exp+ num-len)))
      (if (and (<= num-len +ldbl-mant-dig+)
               (<= min-exp exponent max-exp))
          (hash-dyad state sign mantissa exponent)
          (hash-type state number)))))
3.2. Gravel details
Without further ado, let's dig into the actual implementation. I'm going to show only relevant parts of C code for brevity. If you are not interested in C code and microoptimizations, then just skip this section and move to benchmarks. Here is a TL;DR table (complexes are normalized and each part is hashed with a tag):
| type | hash as | why? |
|---|---|---|
fixnum |
fixnum |
performance |
bignum |
bignum / dyadic |
performance / equivalence (lfloat/dfloat) |
ratio |
ratio / lfloat |
performance / equivalence (lfloat/dfloat) |
dfloat |
fixnum / dyadic / dfloat |
performance / equivalence / performance |
lfloat |
dfloat / fixnum / dyadic |
performance / performance / correctness |
In two places we will hash integers that may be either fixnums or bignums:
- the mantissa in a dyadic form (long double mantissa is 64bit on x86-64)
- a ratio's numerator and denominator when the ratio is not a dyadic number
Hashing them is straightforward. Note that hashing the fixnum is always cheap - we hash a single word.
static inline void
hash_fixnum_data(cl_hashstate *h, cl_object x) {
  hash_word(h, ecl_fixnum(x));
}

#define hash_fixnum(h,x) hash_fixnum_data(h,x)

static inline void
hash_bignum_data(cl_hashstate *h, cl_object x) {
  hash_word(h, ecl_bigsgn(x));
  hash_data(h,
            ECL_BIGNUM_LIMBS(x),
            ECL_BIGNUM_USIZE(x) * sizeof(ecl_limb_t));
}

static void
hash_integer(cl_hashstate *h, cl_object x)
{
  if (ECL_FIXNUMP(x)) {
    hash_fixnum_data(h, x);
  } else {
    hash_bignum_data(h, x);
  }
}
Previously we were concerned with consing. This is why we go an extra mile to not allocate bignums unnecessarily when we hash a bignum in a dyadic form. We operate on a scratch register that is a thread-local variable in ECL when we extract a mantissa:
static inline void
hash_and_free_bignum_register(cl_hashstate *h, cl_object mantissa) {
  /* INV this function assumes that mantissa is already positive. The bignum may
     not be normalized to fixnum. We free the register after hashing. */
  if (ECL_BIGNUM_SIZE(mantissa) == 1) {
    ecl_limb_t y = ECL_BIGNUM_LIMBS(mantissa)[0];
    if (y <= MOST_POSITIVE_FIXNUM) {
      hash_word(h, y);
      goto DONE;
    }
  }
  hash_bignum_data(h, mantissa);
 DONE:
  _ecl_big_register_free(mantissa);
}

/* When hashing bignums we see whether they fit in LONG-FLOAT and only then we
   cast it to a dyadic form. Otherwise we directly hash limbs. */
static void
hash_bignum(cl_hashstate *h, cl_object x) {
  cl_fixnum length = _ecl_big_integer_length(x);
  cl_fixnum exponent = _ecl_big_ctz(x);
  if (length-exponent<=LDBL_MANT_DIG && length<=LDBL_MAX_EXP) {
    /* To avoid allocating fresh bignums by ABS and ASH we opencode this:
       cl_object mantissa = ecl_ash(ecl_abs(x), -exponent); */
    cl_object reg = _ecl_big_register2();
    cl_fixnum signum = ecl_bigsgn(x);
    if (signum<0) {
      _ecl_big_neg(reg, x);
      _ecl_big_div_2exp(reg, reg, exponent);
    }
    else {
      _ecl_big_div_2exp(reg, x, exponent);
    }
    hash_word(h, 8*exponent+signum);
    hash_and_free_bignum_register(h, reg);
  } else {
    hash_bignum_data(h, x);
  }
}
Hashing a ratio is also plain. When the ratio is dyadic and its precision does not exceed long double then we coerce it to that type and hash it. Otherwise we add the tag and hash both integers. We are careful to not allocate memory.
static void
hash_ratio(cl_hashstate *h, cl_object x) {
  /* When the ratio is dyadic and within long-float precision, then we cast it
     to long double for consistent hashes. Otherwise we hash ratio as is. */
  cl_object num = ecl_ratio_num(x);
  cl_object den = ecl_ratio_den(x);
  /* Ratio is dyadic when denominator is a power of two. To avoid bignum
     arithmetic we provide an optimized path for each subtype of integer.
     ecl_zerop(ecl_boole(ECL_BOOLAND, den, ecl_one_minus(den))); */
  bool dyadic_p;
  if (ECL_FIXNUMP(den)) {
    /* Denominator is always positive, so fixnump(x) -> fixnump(x-1) */
    cl_fixnum dfix = ecl_fixnum(den);
    dyadic_p = !(dfix & (dfix-1));
  } else {
    /* When bignum is a pow2, then integer_length == ctz+1 or (popcount==1) */
    dyadic_p = ((_ecl_big_ctz(den)+1) == _ecl_big_integer_length(den));
  }
  if (dyadic_p) {
    /* Normally we would call here
       cl_fixnum length = ecl_integer_length(ecl_abs(num));

       But! Numerator is normalized to an odd integer because denominator is a
       power of two. INTEGER-LENGTH returns different values for X and -X only
       when X is a power of two, and the only odd power of two is X=1.

       (INTEGER-LENGTH -1) == 0 and 0 <= LDBL_MANT_DIG
       (INTEGER-LENGTH +1) == 1 and 1 <= LDBL_MANT_DIG

       This is why we don't need to call ABS on the numerator. QED. */
    cl_fixnum length = (ECL_FIXNUMP(num)
                        ? ecl_integer_length(num)
                        : _ecl_big_integer_length(num));
    cl_fixnum exponent = -(ecl_integer_length(den)-1);
    if (length <= LDBL_MANT_DIG && exponent >= LDBL_MIN_EXP-LDBL_MANT_DIG) {
      /* Generic way to do this is: hash_long_float(h, ecl_to_long_double(x));
         that path recomputes mantissa and exponent from ratio using a generic
         arithmetic. We already have everything ready. */
      long double value = (ECL_FIXNUMP(num)
                           ? ecl_fixnum(num)
                           : _ecl_big_get_lf(num));
      value = ldexpl(value, exponent);
      hash_long_float(h, value);
      return;
    }
  }
  /* Fall-through. */
  hash_word(h, t_ratio);
  hash_integer(h, num);
  hash_integer(h, den);
}
Hashing floats is the most demanding part in this program:
- DOUBLE-FLOAT: the first branch ensures the same hashes for fixnums, bignums, and integer float types, while the second branch ensures the same hashes for ratios and fractional float types.
- LONG-FLOAT: the first branch checks whether we can cast to double without losing precision. The second branch ensures same hashes for fixnums. The third branch unconditionally hashes the value in a dyadic form.
Initially I've introduced functions decode_lf and decode_df that extracted mantissa and exponent from the number, but benchmarks showed that these small allocations dominate both time and consing for relevant profiles. This is why I've fused decoding and hashing and operate on a preallocated register. That's the difference between coming up first and coming up third on the benchmark.
Decoding and hashing double and long double in a dyadic form are practically the same, so I'm going to show only hash_lfloat version. Both functions have a fast path when the mantissa fits in cl_index, and a portable slow path when it doesn't. Initially I've picked unsigned long long, but this type can't be directly assigned to a bignum in GMP, so I've decided on a more robust type.
Functions hash_dfloat and hash_lfloat are identical except for DBL_MANT_DIG -> LDBL_MANT_DIG, ldexp -> ldexpl and frexp -> frexpl. Common Lisp, with its organic macros, could save us repetition and expand a single macro twice, but C preprocessor macros get hairy fast, so it is better to copy-paste the code:
/* INV value is guaranteed to be finite and != 0. */

#define DECODE_SIGNUM(value,signum) \
  do { if (signbit(value)) { signum=-1; value=-value; } } while(0)

/* ... hash_dfloat(cl_hashstate *h, double value) ... */

static inline void
hash_lfloat(cl_hashstate *h, long double value)
{
#if LDBL_MANT_DIG <= ECL_FIXNUM_BITS
  int ctz, exponent, signum=1;
  cl_index mantissa;
  DECODE_SIGNUM(value, signum);
  value = ldexpl(frexpl(value, &exponent), LDBL_MANT_DIG);
  exponent -= LDBL_MANT_DIG;
  mantissa = (cl_index)value;
  ctz = ecl_ctz(mantissa);
  exponent += ctz;
  mantissa >>= ctz;
  /* binary80 mantissa is 64 bits so it can falsify <= MOST_POSITIVE_FIXNUM. */
  if (mantissa <= MOST_POSITIVE_FIXNUM) {
    hash_word(h, 8*exponent+signum);
    hash_word(h, mantissa);
  } else {
    cl_object reg = _ecl_big_register2();
    _ecl_big_set_idx(reg, mantissa);
    hash_word(h, 8*exponent+signum);
    hash_bignum_data(h, reg);
    _ecl_big_register_free(reg);
  }
#else /* Happens for 128bit floats (i.e aarch64). */
  const int fixnum_bits = ECL_FIXNUM_BITS-ECL_TAG_BITS-1;
  int ctz=0, exponent, signum=1;
  cl_object mantissa = _ecl_big_register2();
  cl_fixnum helper, iterator;
  DECODE_SIGNUM(value, signum);
  value = frexpl(value, &exponent);
  _ecl_big_set_ui(mantissa, 0);
  for(iterator=0; iterator<LDBL_MANT_DIG && value; iterator+=fixnum_bits) {
    value = ldexpl(value, fixnum_bits);
    helper = (cl_fixnum)value;
    value -= helper;
    _ecl_big_mul_2exp(mantissa, mantissa, fixnum_bits);
    _ecl_big_add_ui(mantissa, mantissa, helper);
    /* When this chunk contains only 0s, then we extend trailing zeros by
       fixnum_bits (chunk's size). Otherwise we start counting again. */
    ctz = !helper ? ctz+fixnum_bits : ecl_ctz(helper);
  }
  /* ctz is a trailing 0 count for the whole mantissa. iterator denotes how many
     bits we have shifted the mantissa. */
  exponent += ctz - iterator;
  _ecl_big_div_2exp(mantissa, mantissa, ctz);
  hash_word(h, 8*exponent+signum);
  hash_and_free_bignum_register(h, mantissa);
#endif
}
#undef DECODE_SIGNUM
At last we can hash some floats. Hashing single floats is trivial (we cast them to double float) while hashing a long float requires more work:
- integer path
- we need to extract the mantissa from it separately because it can store bignums outside of a double float range.
- fraction path
- DOUBLE-FLOAT is hashed as is, LONG-FLOAT are hashed as a dyad unless it can be represented as DOUBLE-FLOAT, in that case it is cast to it
#define hash_single_float(h,v) hash_double_float((h),(double)(v))

static void
hash_double_float(cl_hashstate *h, double value) {
  if (isfinite(value) && (value==trunc(value))) {
    const double limit = ldexp(1.0, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
    if (value < limit && value >= -limit) {
      hash_word(h, (cl_fixnum)value);
      return;
    }
    hash_dfloat(h, value);
    return;
  }
  /* Fall-through. */
  hash_data(h, &value, sizeof(value));
}

/* We need to ensure, that when long double can be represented as double without
   loss of precision, that is value == (double)value, to hash it as double. */
static void
hash_long_float(cl_hashstate *h, long double value) {
  /* Hash as double. */
  if (!isfinite(value)
      || (fabsl(value) <= DBL_MAX && value==(double)value) ) {
    hash_double_float(h, (double)value);
    return;
  }
  /* Hash as fixnum. */
  {
    const long double limit = ldexpl(1.0L, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
    if ((value==truncl(value)) && (value < limit) && value >= -limit) {
      hash_word(h, (cl_fixnum)value);
      return;
    }
  }
  /* Hash as long double in dyadic form -- this is both for compatibility with
     bignums and to avoid hashing padding bits on x87. */
  hash_lfloat(h, value);
}
And.. that's all. Complex numbers are hashed the same - when the complex float imaginary part is zero then we hash only the real part, otherwise we hash both parts. Summing things up, here are the dominant costs of the procedure:
| type | decision cost | dyadic hash cost | normal hash cost |
|---|---|---|---|
fixnum |
(none) | same as for EQL | same as for EQL |
bignum |
(negligible) | (ash (abs x) -exp) |
same as for EQL |
ratio |
(negligible) | hash_long_float |
same as for EQL |
float |
(negligible) | hash_{dfloat,lfloat} |
same as for EQL |
- bignum decision cost boils down to counting trailing zeros, the dyadic hash operates in a register and it doesn't cons
- ratio decision cost is optimized to not perform bignum arithmetic, so the decision cost is negligible and the main cost is in hashing long double
- float creates an integer from the mantissa - in most cases it is a fixnum, otherwise it operates on a bignum register and it doesn't cons either
This section might not have been the most pleasant read (a lot of C code), but I hope that it gave you some insight into how optimizing ECL hot paths looks like. Certainly it would be nice to have Common Lisp compiler that targets C! Oh…
4. Benchmarks - knockout
I initially planned to run ad hoc benchmarks and get over with it, but I had too much fun writing up tests and coming up with interesting benchmark profiles and fell into another rabbit hole. In this section we'll compare ECL with itself (of course), but we will also discuss other implementations.
First let's focus on tests. I've devised a few profiles for comparisons:
- :AVERAGE
- we pick randomly rational and float numbers
- :TYPICAL
- fixnums, fixnum uuids, small floats and bignums in form 2n
- :DYADIC
- rational and float numbers with overlapping values being =
- :COLLIDE
- white-box test that exploits casting LONG-FLOAT to DOUBLE-FLOAT
- :BEYOND
- white-box test that tests dyadic rationals beyond LONG-FLOAT range
- :FIXNUM :BIGNUM :RATIO :DOUBLE
- basic type-specific benchmark
All benchmarks first generate 216 keys according to their profile and prefill the hash table in the setup phase to avoid resizing. Only after that we run the benchmark. Each profile has the same number of keys that are randomized during setup. Each test is run 8 times to average results.
We measure both run time and consed bytes. The benchmark itself runs SETHASH and GETHASH for each key in the collection, so the hash table implementation impacts cross-implementation comparisons. On the bright side, it also reveals when there are systematic collisions between hashes.
Here is an interesting story (relevant to these charts!). While analyzing data I've noticed that "ECL-round2" unexpectedly conses for three profiles: :DYADIC, :TYPICAL and :AVERAGE. I've felt very disappointed with these, because I went to great lengths to avoid consing. The investigation revealed that if we don't mix in these tests floats and rationals then consing is consistently zero. That was the "aha!" moment - hash table allocates memory when it compares float and rational keys! I'm keeping the figures as-is, but keep in mind that "ECL-round2" hashing really doesn't cons; allocations come from the key comparison. I could pull out my yak shaver and fix EQUALP too, but this descent stops being funny.
ECL variants are: "warmup", "round one" and "round two" that correspond to approaches discussed earlier: cast everything to double, type-specific hashes, and the final version where we exploit a dyadic canonical form. All tests are performed using the new hash function (xxhash) and hash table (swiss).
Tested implementations are CCL, ECL, LispWorks and SBCL. There are caveats:
- I initially planned to include ABCL and CLASP too, but a smoke test revealed ABCL#763 and CLASP#1876. Both share the same flaw as ECL before changes described in this post, that is they don't hash numbers correctly under EQUALP. Benchmarking them would be beside the point.
- LispWorks performs badly on profiles any float numbers and other results are dwarfed by it, so I've excluded LW from some plots (but accounted for it in relevant analysis)
- CCL is the mirror image of LispWorks, and performs badly on profiles with rationals (and it is great with floats), so it is also skipped on some plots
- The :COLLIDE test does not apply to other implementations because they don't have LONG-FLOAT that is separate from DOUBLE-FLOAT - we use :TYPICAL instead
The smoke test:
(defvar *ht* (make-hash-table :test #'equalp))
(setf (gethash 1/4 *ht*) 42)
(unless (eql (gethash 0.25 *ht*) 42) ; a proper test should cover more pairs
  (format t "ERROR: 1/4 and 0.25 do not share the hash value under EQUALP.~%"))
All charts report either elapsed time or allocated memory aggregated for the whole execution. Smaller is better. Test results are normalized to [0, 1] relative to the slowest / most consing variant in each panel. "0.00" means "below 0.005" of the maximum, not zero. All measurements were performed on X86-64 Intel(R) Core(TM) i9-9900K CPU @ 3.60GHz.
One of the hardest parts in analyzing data is to decide what we can remove without simplifying the picture too much. Interpretations presented in this section skip many benchmarks to present an understandable story.
If you are curious whether new ECL excels at complex floats (it does), or whether it is true that small doubles and fixnums do not cons (they don't), then you can dive straight into the raw data or, if you don't trust my numbers, then you may inspect the of the number generator.
4.1. ECL vs ECL
First we will compare ECL variants developed in this post. The first chart shows a benchmark for basic types:
Figure 6: (ECL-warmup ECL-round1 ECL-round2) x BASIC-TYPES x (TIME CONS).
A few interesting observations emerge from this chart:
- Hashing doubles is fastest on "ECL-warmup", because this implementation is simplest for that particular profile. It also doesn't cons. "ECL-round1" is dominated by memory allocations for large double values that are bignums.
- Hashing ratios has progressively better results with each round, both the time and consing.
- Hashing bignums is a mirror image to hashing doubles, where "ECL-round1" excels at bignums, "ECL-warmup" must coerce bignums to doubles and memory allocation dominates its time. "ECL-round2" is as performant as "ECL-round1".
- Fixnums on all variants are on a relatively fast path and don't need to cons at all.
Notice that "ECL-round2" is slower only when we hash specifically doubles. Otherwise it is always tied or it is the fastest. It also doesn't cons.
It already looks good, but charts start to look even more interesting when we start exploiting mixed data patterns:
Figure 7: (ECL-warmup ECL-round1 ECL-round2) x MIXED-DATA x (TIME CONS).
-
The "beyond" profile is a benchmark where we generate bignums and ratios that can't be represented as float, but have a shape that resembles floats - both have a mantissa that can be stored in a double and an exponent that doesn't fit in binary128 floats (the most precise float on ECL aarch64 and no tested Lisp has a wider float).
And it shows. "ECL-warmup" takes the bait and collapses everything to double. That spikes both allocations and collisions. "ECL-round1" avoids part of that cost because bignums are hashed as is and they avoid collapsing to a single hash (double positive infinity). "ECL-round2" avoids both allocation and the collision traps and it is 400x faster (0.3s vs 125s) and doesn't cons while "ECL-warmup" conses 2GB.
- The "collide" profile is similar, but numbers can be neatly represented as a long float (binary80) and not as a double float (binary64). That means in particular that both ratios and bignums must be hashed in a compatible manner to floats. Once again "ECL-round2" is very fast (600x faster! 0.2s vs 118s) and doesn't cons, while "ECL-warmup" conses 833MB. "ECL-round2" has much less collisions than "ECL-warmup" thanks to exact bignum hashing.
- The "dyadic" profile mixes fixnums, double floats, bignums in double float range and dyadic ratios in double float range. This profile forces the need to bring all numbers to the same canonical representation and does not exhibit any systematic collisions. Since all here boils down to doubles, "ECL-warmup" conses less than "ECL-round1", yet "ECL-round2" is even better thanks to our optimizations. Little consing that is exhibited comes from comparing floats and bignums with EQUALP (not from hashing).
- The "average" profile takes rational and float numbers at random. Here we can again see that "ECL-round1" was not a regression over "ECL-warmup" - it was a targeted optimization that tried to balance effort between different types of numbers. Still, "ECL-round2" wins clearly against both variants.
My takeaways here are that:
- specialized implementations are better for their particular data profile, notably "ECL-warmup" excels at doubles; "ECL-round1" ties "ECL-round2" at bignums and balances other types well
- "ECL-round1" approach optimizes for typical cases, but it is not very frugal with memory (to the point where allocations dominate the benchmark in doubles)
- "ECL-round2" also optimizes for typical cases but it is also austere with memory allocations and avoids hash collisions - that is responsible for two orders of magnitude faster and leaner implementation for adverse profiles
4.2. ECL vs the world
Comparing implementations between each other is inherently noisy. They don't share the same hash table implementation and various unrelated operations on the hashing and hash table path have different cost profiles. That said with a big set of data we can clearly see some trends. Let's start with basic types:
Figure 8: (CCL ECL LispWorks SBCL) x BASIC-TYPES x (TIME CONS).
LispWorks is excluded from the test involving floats because it is around 2500x slower than CCL (96s vs 0.04s) and conses 66MB while other implementations don't cons at all. In benchmarks involving rational numbers it is competitive. My guess is that LispWorks calls RATIONALIZE on floats and that get costly fast.
CCL is another side of the same coin. It performs well for floats (around 1.7x slower than ECL and SBCL), but it is much worse for rationals. The difference is not that drastic but still much slower for bignums compared to LispWorks (0.18s vs 0.03s). It is surprising but it allocates data even for FIXNUMs. It probably calls FLOAT on all numbers before hashing.
SBCL heavily optimizes fixnums, bignums, and doubles - it is a leader on these basic types and it doesn't cons. It drops a ball with ratios where it is slower and conses 155MB (while ECL nor LispWorks don't allocate memory for ratios).
ECL never conses and wins for ratios, while for other basic types it is always second. For BIGNUM SBCL pulls ahead, while for FIXNUM and DOUBLE it follows closely.
Figure 9: (CCL ECL LispWorks SBCL) x MIXED-DATA x (TIME CONS).
Results in these benchmarks are implicit from tests on basic types:
- BEYOND, DYADIC and AVERAGE involve floats, so LispWorks is too slow to include. SBCL is also underperforming on these tests, because these profiles contain ratios - the cost seems to be dominated by memory allocations.
- TYPICAL profile is manageable for all implementations, but both CCL and LispWorks underperform because both (small) floats and rationals are in the test set. CCL allocates much more memory than others. SBCL performs well, but is slower than ECL.
- In all these tests with mixed numbers ECL is the leader and allocates least (as noted earlier, hashing itself doesn't cons at all).
My takeaway is that each implementation could close the gap to the others if:
- LispWorks adds hashing specialization for floats
- CCL adds hashing specialization for rationals
- SBCL adds hashing specialization for ratios
This new approach of ECL is competitive with all implementations on each metric and it is either the first or a close second with the biggest (around 1.5x) gap to SBCL hashing bignums.
5. Summary
The main takeaway here is that every dyadic rational has one canonical form that may be used to produce good hashes under the EQUALP predicate and that efficient implementations take liberties with simplifications after absorbing the model.
It may look like we have abandoned the elegant dyadic model in the later phase, but that's not true: we don't lose precision by lossy casting to double and all numbers except equal ones are hashed differently (hashing differently does not imply different hashes just like tossing a dice differently does not guarantee different results).
Another interesting insight is that we can learn a lot about strategies used by different implementations by merely benchmarking them with cleverly put number selection profiles.
In practice EQUALP is not often used as a hash test, so while the numbers look impressive, the new approach is not a game changer. That said, there is value in hashing under EQUALP precisely because it coalesces different numbers. Usage may follow when implementations are performant, while underperforming abstractions will almost certainly be skipped.
That's about the hashing itself, but the post is not only about hashing. Note how we have started with a simple baseline model, improved it and then refined our understanding with an elegant conceptual model. We didn't stop there: we turned it into an efficient implementation through the optimization and validation loop. That's an engineering lesson worth remembering even if you don't care much about heavenly delights of hashing numbers under EQUALP.
Uff, the summary was exhausting. For me, this was certainly a fun trip. I've recently learned a lot about hashing, hash tables, number equivalence, micro-optimizations, benchmarking and diving too deep. Look forward to:
- a blogpost that discusses new hash table and generic function implementations
- the next release with all accumulated performance and conformance improvements
You may find the current progress in the ECL repository under branches xxhash, swiss-ht and improve-gf-cache.
Happy Hackshing!
Daniel
PS If you liked this post or have some interesting insights, then let's chat.
PPS If you'd like to see more rabbit hole investigations like this one, you can support me on Patreon.
PPPS I'd like to thank Charlie McMackin for proofreading this text and providing many valuable remarks.
26 Oct 2026 12:00am GMT
25 Oct 2026
Planet Lisp
Marco Antoniotti: Exercising on a Threadmiλ, multitasking
As I get older, I need to exercise. I decided to use a Threadmiλ.
Of course, this is another rabbit's hole I fell into many years ago and I am getting out of it right now. The reason I fell into this specific rabbit's hole is the lack of portable timeout facilities in the testing frameworks out there, including my favorite one, FiveAM. More on this later.
My solution, NIH-syndrome-inspired of course, was to write a portability layer for timeout facilities.
Which begged the question: why not Bordeaux Threads?
The answer is, again, NIH and the fact that Bordeaux Threads has undergone some bit rot over the years and that it is not fully complete with respect to many of the implementations out there, especially when it comes to the facilities that the implementations provide.
The result is Threadmiλ (or threadmiλ, or ThreadMIL, or threadmilambda...), i.e., a Bordeaux Threads like library, re-done in MILan; the λ is de rigueur.
Threadmiλ
As I said, Threadmiλ (Threadmil) is a fork and a somewhat re-implementation of the well known Bordeaux Threads library that aims to make it even more CL-centric, expand it and fix the semantics of a few constructs, most notably the timeout machinery.
Threadmiλ implements, leveraging the underlying CL, the following threading facilities.
- Threads
- Locks
- Semaphores
- Condition Variables
- Timers
- Mailboxes
- Barriers
- Atomics
- Timeouts
These are the facilities available in most CL, especially Lispworks.
Current Implementation Status
The table below gives you a quick status of the support for a number of implementations. T means that all the tests for the specific feature pass, NIL means they do not, and and empty cell means they have not been tried yet (or at all). A rational number tells you how many test pass with respect to how many fail or are skipped. The test suite uses fiveam.
| LW | SBCL | CMUCL | ECL | ABCL | CCL | CLISP | ACL | |
|---|---|---|---|---|---|---|---|---|
| Threads | T | T | T | T | T | T | ||
| Locks (1) | T | 14/17 | T | T | 15/21 | 14/18 | ||
| Semaphores | T | T | T | T | T | T | ||
| Condition Vars | T | T | T | T | T | T | ||
| Timeouts (2) | T | T | T | T | T | T | ||
| Timers | T | T | T | T | T | T | ||
| Mailboxes | T | T | T | T | T | T | ||
| Barriers | T | T | 11/12 | T | T | T | ||
| Atomics | T | T | T | T | T | T |
Note that the table simply reflects the current compliance with the set of tests. Adding some tests may change the entries in the table. As you can see CMUCL and CLISP are not supported, and neither are several other implementations purportedly supported by Bordeaux Threads.
(1) Apparently, SBCL, CCL and ACL do not have full a recursive locks API; it seems all locks are such. The missing bits are different and this is reflected in the number of tests actually performed. In the future the regular API may be used and the missing tests will just work.
(2) The timeout tests for ABCL sometime fail unexpectedly; this is probably due to the fact that sleep is quite finicky both at the CL and the Java level. Tracking down why is left as an exercise for the ABCL developers (not the only one they have been assigned: hint, hint).
Where You Can Get your Threadmiλ
The main documentation page can be found https://threadmil.common-lisp.dev.
/ The project page is at https://gitlab.common-lisp.net/mantoniotti/threadmilambda
How Did I Get Here?
Before AI stuff I used some testing frameworks to tortur... pardon, evaluate students' projects (yes, I inflict CL on them). Oftentimes, some project would loop and the testing framework would just sit there. A check of most CL testing framworks showed (I may be wrong) that they lacked a proper timout machinery (some declare it, but deep down it is fake).
I thus set out to create a portable with-timeout macro. That was the mistake that led to Threadmiλ.
Now, testing frameworks developers have no more excuses.
Disclaimer
As usual here you have the scariest disclaimer here. The library is bound to have bugs and race conditions.
AI was used only to generate a few of the tests.
Any Help Appreciated
Of course you are free to fork the project subject to the current licensing scheme. However, before you do so, I ask you to consider plain old "cooperation" by asking me to become a developer. It helps keeping the entropy level at an acceptable level.
Of course, in this case, I did not heed my own advice, and yet...
'(cheers)
Marco Antoniotti 2026-10-24
25 Oct 2026 4:34pm GMT
20 Oct 2026
Kernel Planet
Linux Plumbers Conference: LPC 2026 – Kernel Testing MC
The Kernel Testing & Dependability Micro-Conference was back again at Plumbers this year, in Prague and with a wide variety of topics. In addition to the well-established frameworks such as KUnit and kselftest, some new frontiers are being explored with the spotlight on LLM-assisted tools. Developers are also getting special treats with new kci-dev features and expert insights into local build testing at scale.
Primary author: Guillaume Tucker
kci-dev
What Changed, What Works, and What Kernel Developers Still Need - by Arisu Tachibana (virtual)
The kci-dev command line tool enables developers to interact with KernelCI. Here's a summary of the latest changes:
- Core implementation moved to the
kcidevPython module as an API library - Standalone patch file testing enabled on top of a Git checkout
- Submission of results to KCIDB enabled with artifacts uploaded to storage
- Experimental MCP added on top of the API
The tool also benefits from these new plugins:
kci-patchworkto apply patch series from Patchwork and submit test jobkci_release_reviewto compare revisions and create reports
Plugins can help extend functionality so they should be a good way of driving future kci-dev development. The MCP may also enable new use cases. Please join the KernelCI mailing list and Discord channel as per the contact page if you wish to take part and discuss things further.
Build Identity
Kernel Builds Deserve an Identity: Portable Kernel Artifacts and Traceable Test Results - by Cong Wang
The raw metadata provided by uname, Git, IDs from various CI systems etc. does not provide any standard or consistent way to identify a build. As such, bug reports can't directly refer to a single reproducible binary.
Cong Wang's proposal is the Kernel Bundle Image (KBI) project. It draws a parallel with how OCI solved this for container images. The idea is essentially to create OCI images for kernel builds. However, it still has a low level of adoption and isn't used by current automated testing systems.
How may KBI gain more traction?
Where should the line be drawn about what to include in the kernel build ID? There hasn't been a clear consensus on this yet, whether it should include device trees, firmware blobs and other artifacts.
Yocto / OE also has a way to reproduce entire OS builds, including the kernel. This may be used as a guideline or potentially combined with the KBI approach.
It's also worth noting that TuxMake is able to reproduce binary-identical builds for a given set of inputs (container image and build parameters), which does not constitute a build ID per se but could still be potentially very helpful for this purpose.
A related initiative is KernelSbom since a bill of materials could define the input to a KBI image: source with metadata, main build artifacts, additional contents (firmware, BPF).
KUnit Configuration
Rethinking KUnit Configuration - by David Gow
The session started with a poll: roughly half of the room use KUnit regularly and 3 people answered yes to the last question about running KUnit with multiple configurations. This tends to show that the tool is well established for standard usage but few developers use it in an expert way.
The main issue covered by this session is about limitations with the .kunitconfig file and qemu_config Python module, especially the lack of output format options and the fact that each config covers only a single KUnit run.
Proposal: Determine a single standard configuration mechanism to go beyond limitations while being easy to share between developers. Passing metadata through to the results would also be especially useful for CI systems which can deal with more details and trace the results back to their origin.
Should this be solved with a new config system or by extending an existing one?

- Option 1: extend
.kunitconfig(currently a plainKconfigfragment) - Option 2: native Python module since
kunit.pyis already in Python - Any other options?
David's preferred option is to extend .kunitconfig.
For multiple runs bundled together, it's important to be able to parse the results as if they were individual ones e.g. objects embedded within a bigger blob. One potential solution is to produce results in separate files (KTAP).
Multiple runs are useful for CI integration with a single entry point. It also removes the overhead of setting up many short-lived individual jobs. This doesn't however appear to be too useful for manual runs. It can help a bit with git bisect run although multiple KUnit commands may be bundled within a single script.
It's also worth noting that having isolated kernel runs would prevent a single crash from breaking the whole series.
The overall consensus is that multiple runs in a single command or config aren't probably that useful except in particular cases e.g. CI hooks.
Build Testing
Optimizing local kernel build testing - by Arnd Bergmann
As a sequel from Arnd's talk at Kernel Recipes, this session is to discuss using a manual, local setup to achieve wide build testing coverage. The focus is on linux-next, with -Werror enabled to try and catch all new build issues.
The best approach when something breaks is to send a fix if possible as it is a lot more effective than just reporting bugs. By doing this for many years, Arnd has fixed thousands of bugs upstream (3000+) and touched every subsystem in the kernel.
The most common problems are Kconfig dependency bugs since its logic is complicated and deceptive, especially with tristate options. The new kconfirm tool aims at solving this issue via static analysis.
Arnd keeps a small config fragment to maximise the effectiveness of build testing:
# maximize search space, disable options not worth testing
CONFIG_COMPILE_TEST=y
# avoid long build times
# PROFILE_ALL_BRANCHES is not set
# reduce compile-time dependencies
CONFIG_STANDALONE=y
CONFIG_PREVENT_FIRMWARE_BUILD=y
Should orchestration of parallel builds be integrated upstream?
This sounds useful although the discussion didn't expand on how to approach this topic in practice. The general makefile and arm64-specific testrandconfig64 files attached have been kindly provided by Arnd as a reference based on his local setup. Please feel free to reach out to him via email should you wish to discuss this further.
Should local build regression reports be sent to KCIDB? With a proposed fix in a patch?
Several people would welcome this and a follow-up discussion is intended to take place with the KernelCI team.
kcov and kselftest
Kselftest coverage with kcov - by Shuah Khan
Thousands of tests are available in-tree via kselftest and KUnit, but what is their coverage? Shuah has made an experimental tool to run kselftest with kcov and start looking into the issue. Coverage data is not ready to be published yet so the discussion was more about the potential use cases. You can already expect to see a more in-depth follow-up analysis on this topic next year and other general kselftest sessions at every future LPC.
How is code coverage useful?
When working with unknown customer workloads, comparing their coverage with well-known tests gives an idea of how much the tests are covering these workloads.
One issue with enabling kcov at build time is that it's not suitable for production kernels. However, ftrace is usually enabled so it could be used in combination with kcov with different granularity (function-level only coverage with ftrace).
Another dimension to the problem is about evaluating other tools e.g. LLVM/Clang coverage. See also the LLM fuzzing session on a related topic.
KFuzzTest
KFuzzTest: One year on - by Ethan Graham
The aim of KFuzzTest is to combine the benefits of fuzzing and unit testing. A new, experimental API is now available in the latest version of the patch series to make it easier to write tests and facilitate adoption.
The next core feature which is currently under development is stateful fuzzing. Initial trials found a known bug which had already been fixed but this showed the tool's potential.
Can fuzzing target specific code?
This is not trivial. In some cases, hardware mocks may be used to enable coverage on specific drivers. Generally speaking, KFuzzTest's aim is to narrow down fuzzing to isolated functions like a unit test would typically do. The effectiveness of this method is still being debated, perhaps the sweet spot lies in between this and syzkaller's broader approach.
How about stateful fuzzing?
Stateful fuzzing in userspace exists and enables setting extra boundaries. Kernel fuzzing is typically run from outside the kernel, kind of guessing how to invoke the syscalls. Having the kernel asking a userspace fuzzer has led to successful experiments in the past. So overall, stateful fuzzing is feasible.
How about KUnit overlap?
David Gow is in favour of adding functionality that lets userspace pass data into KUnit tests. This could also facilitate making reproducers. However, the stateful approach is not a good fit for KUnit with long strings of operations as unit tests are meant to be run in isolation.
LLM Fuzzing
LLM-Assisted Fuzzing with Syzkaller - by Chuyang Wang & Aleksandr Nogikh

The issue when fuzzing with high-level descriptions is that they don't go deep enough to reach good code coverage. Hand-written seed programs partially solve this but the approach doesn't scale.
The proposed solution here is to rely on LLM-generated ones instead. While attempting to reach areas never covered by syzbot, an overall 15% increased coverage was reached over a few months using this approach. This uncovered a new issue with the LLM trying to evade syzkaller's sandboxing environment. The next step is going to integrate with syzbot.
Is AI-driven cheaper?
Probably but not measured in terms of actual costs. One seed program could then expand coverage.
How about fuzzing drivers?
This is tricky because testing drivers often requires access to real hardware. USB is an exception as physical devices are not strictly necessary. This has enabled the team to significantly increase fuzzing coverage and report many bugs over a short period of time.
Still useful to upstream hand-written seed programs?
Yes, these are complementary approaches.
KernelCI in the Cloud
Testing the kernel where the fleet runs: KernelCI in the cloud - by Norbert Manthey & Stanislav Uschakow
Going beyond the historical use cases of KernelCI which originated on embedded platforms, this session is about testing kernels deployed in the Cloud. The system covers x86_64 and Graviton (arm64) VMs in an AWS lab. Additionally, nested KVM guests on particular VM types are also supported. It provides the typical scalability and variety of platforms one would typically expect to find in this environment. Developers may also run the tests themselves using their own AWS account.
Current upstream kernel coverage includes mainline, linux-next and LTS. Runtime coverage is limited to baseline boot testing and basic checks. Performance testing is next on the roadmap.
How is A/B testing done in the AWS Cloud?
The approach is to run both A and B kernels with the same VM definition to reduce dependencies on the environment (hardware of physical host, virtualization stack, firmware, …). Keeping the kernel as the single moving part enforces it to be the only root cause for any difference found in test results. The code for this A/B testing is made available as a GitHub repository under the KernelCI project umbrella.
How does A/B testing on AWS work with live migrations?
Tests are not relying on a file system for now to keep resource dependencies low. Hypervisor updates can cause one VM to stop but tests are run multiple times and in a distributed way so the impact is mitigated.
Are you running KUnit?
KernelCI is running KUnit in other environments, not in AWS. It's unclear whether doing this would increase existing coverage.
Which kernel trees have the priority?
Testing linux-next and mainline kernels should be the priority. Covering LTS is also useful to verify that fixes get backported successfully as they would typically be applied to the AWS forks too although those are outside the scope of KernelCI.
Are any more details of the test runs available?
In order to give maintainers access to more details about test runs, the AWS lab setup needs to expand its integration with KernelCI in general. Additional features have been requested during LPC such as being able to automatically bisect issues and sending regressions as direct replies to patches via emails threads. Those reports should also be sent to the kernel regressions list.
Testing BoF
Note - The speaker has apologised for not being able to host the last session of the schedule due to personal reasons. It was replaced with an impromptu Testing BoF instead.
One particular point was discussed:
How to address kselftest failing to build and run?
- Tests may fail to build due to missing dependencies. The
kselftest_deps.shtool can be used to discover those. Integrating it into the kselftest Makefile is being considered in order to report them directly to the user. - Test build failures don't cause the overall kselftest build to fail. This is good, although reporting this in a better way might be helpful.
- Build and run regressions need better reporting, they could be made more visible using a tag in email subjects.
Wrapping Up
One lesson learnt is that AI-assisted development tends to be more about data analysis while the initial scope of the Testing MC is rather to focus on low-level tools. These may be seen as optimised, primitive functions producing raw data that LLMs can then leverage and potentially use to orchestrate test runs. Having a session about LLM-assisted fuzzing was a good fit though as it showcased how AI can make use of existing testing components in novel ways.
Last but not least, many thanks to all the speakers for reviewing this blog post, the conference committee and all the attendees for making Plumbers such a great experience. It was a pleasure to be a co-organiser of the Testing MC again this year.
See you at LPC 2027 
20 Oct 2026 7:06pm GMT
09 Oct 2026
Planet Twisted
Glyph Lefkowitz: Programming Isn’t Special
Creative Work
Writers went on strike to get protections against "AI". Thousands of artists have signed open letters in protest of "AI". There are so many copyright lawsuits from creative industry groups against AI that there's a whole dedicated website for it. Popular YouTubers absolutely hate it. If they're also musicians, they REALLY hate it. Across all creative industries, there is a concerted push to reject this technology.
Yet, almost unique among creative fields, many experienced programmers remain convinced that it's fine to use "AI" for programming. We do seem to hate it, and what it's doing to our industry. It's making us all miserable, but we are using it anyway.
A lot of the justification of this resignation seems to be to be because programming is not Art. If the tool can get the job done, and the job is just functional, then why does it matter?
It does matter, though. It matters because we shouldn't be using AI to produce Art, and programming is Art.
Art can be Mundane
Some people will say that programs cannot be art because programs are functional, rather than being expressive. Programs are mundane whereas art is transcendent.
This is based on a distorted understanding of what Art actually is.
In John Berger's "Ways of Seeing", he names this type of distortion "mystification". His example of this process is both amusing and illustrative. I encourage you to read it in its entirety.
In summary, though: Berger critiques the florid prose of an art historian describing a commissioned group portrait, including phrases like "subtle modulations of the deep, glowing blacks" and "harmonious fusion". The portrait is described as sublime, in nearly ecstatic terms.
Berger reveals that the reality of this portrait is that a poor old painter needed some work, and some officials probably thought it might be nice to have an official portrait. So they paid some money to the poor old man, and he painted it, and then they had a painting. It's a well-executed portrait of a group of people. Beautiful, even. But it was work commissioned for a fairly mundane purpose and it suited that purpose just fine. It was not, and is not, a divine relic.
Culturally, we are prone to mystifying painting, and sculpture, and film, and music. We imbue them with "subtle modulations". We ignore their functional aspects - we desire decoration, amusement, and distraction - and focus on their emotional impact.
Don't get me wrong: I love me some good aesthetic philosophy. I think it's great to really examine our reactions to artwork and to try and gain a deeper understanding of our culture and our selves through media analysis. If anything we really need to do more of it.
This does not mean that the creation of such works is mystical or that it should be venerated beyond any other sort of labor.
Not least of which other types of labor that are adjacent to, but not as culturally venerated, as fine art. We tend to mystify the work of a novelist, but to denigrate the work of a journalist. In reality, the functional prose of the journalist is no less important and deserves no less respect.
Although they might be far below the ethereal realm that novelists inhabit in our collective imagination, even journalists receive more respect and thus more mystification than lowly copywriters. Yet, there is no transcendental distinction between "novelist" and "copywriter"; the many of the skills are the same, and the distinction is merely an accident of commerce and opportunity.
In fact, many famous writers have famously inhabited both roles. This is not an accident! Working with words professionally, even (perhaps especially) mundane words, is excellent practice for working with words in a more purely artistic context, because even mundane creativity is still artistic.
Code can be Beautiful
One thousand Internet years ago, when I was in my late teens, I would describe myself as a "code poet". I was relentlessly mocked for this as what the Youth would today call "being cringe", and at the time was referred to as "pretentious".
I succumbed to the peer pressure, removed it from my email signature and my bio. While I still believed strongly in the parallels, I accepted that - socially, at least - comparing code to poetry, or indeed to Art, was a silly thing to do.
However, I never abandoned the idea, in my heart.
The thing that I am most well-known for, the invention of Deferred, was specifically an aesthetic reaction to the tedium of passing callback and errback parameters to every single remote procedure call in an RPC client/server application. Those two callbacks got the job done just fine. But they were ugly, and annoying to work with.
Deferred is an intentional poem about asynchronous task execution, with a deliberate eye to the aesthetics of the problem and the experience of using it. It was influential because of its focus on aesthetics.
I do not want to overstate the beauty or profundity of this minor contribution, or indeed its durability. That a poem exists does not mean it is a great poem, merely that it is a poem.
Our aesthetic culture around programs is more like folk epic poetry than fine art, so the influence of this contribution is less about its specific enduring power than it is about its influence on what came next; from MochiKit.Async to JQuery Deferred to JavaScript Promises and eventually to async/await; a long chain of different artisans each adding something of their own until the original has all but dissolved. (And I wasn't the "original" here, either, as I drew heavily from the E language's Promises, among other things.)
In order to make code into a deliberate artistic expression, one must have spent quite a bit of time contemplating the problem domain. Without having experienced the tedium of manually passing a thousand callback parameters, I would have had neither the skill, nor indeed the motivation, to bother creating such a thing.
Now, most code does not have to be like this. Most code does not get to be like this. Most code is functional, workday code. Most code could not make a lady weep. It's just copy-writing, if you will.
As I explained previously, most writing couldn't do that either. Most writing is just copy-writing, too. Most visual art is advertising. Most live music performance is background music in bars that will go largely ignored.
However, code that is intentionally aesthetically designed tends to be important, both socially and technologically.
We do have some tradition of self-mystification in software. As Abelson memorably put it, "Programs must be written for people to read, and only incidentally for machines to execute.", so we have long had some conception of programs as highly expressive, even if we can't always agree on what they're expressing or to whom. We will occasionally wax poetical about the philosophical implications of a particular piece of software. This is not unique to a single piece of software, either; more than one community has indulged in similar philosophizing.
The expressive and aesthetic qualities of software are not limited to reading source code or interacting with other programmers via APIs, either. For example, every year, Federico Viticci does a review of Apple's new operating system, which is (among other things) an aesthetic critique. Such a project would not be possible if the software did not have an aesthetic impact on its users.
Not to mention that every video game review is also a software review.
A Brief Aside about Software Literacy
It does make me a bit sad that we don't have much of a critical reading tradition in the software community. Literate Programming is often praised, but rarely practiced.
Moreover, it makes me sad that users have a pretty jumbled idea of what goes into making software, that programming literacy is pretty low, and that modern programming practices often deliberately produce a bad mental model of what the software is doing so it's even harder for the user to understand. The aesthetic experience of software is often wildly detached from its internal state.
While all of these problems predate AI by years or indeed decades, that's no reason to enthusiastically make them worse.
Defend The Mundane
If we use AI to erase all the copy-writing, all the graphic design, all the boring mundane art, and yes, all the boring custom WordPress theme development, then we will be removing all the practical opportunities for the vast amounts of practice and contemplation required for people to elevate their craft to eventually achieve great things. Education is great, but the majority of true skill development happens on the job and always has.
This doesn't mean that we can't use abstractions, or automation, to make our work easier. Programming is the art of abstraction, of understanding how to compose smaller ideas into bigger ones, of how to understand the automation of a larger system by understanding the rules that automate smaller ones and understanding how to combine them.
When we use "AI" to eliminate that understanding rather than raise it up to a higher level, to entirely destroy that creative decision-making process, we do a disservice both to ourselves as programmers and to our users. We would be doing a disservice to our users and our downstream fellow developers in the same way that a visual artist would be doing a disservice to their viewers or a musician would be doing a disservice to their listeners if they served them auto-generated filler instead of their own creative output.
Slop is slop, no matter the medium.
Each mundane project has some tiny chance - let's say, something like 0.1% - of achieving greatness. If we do a single project with AI, then sure, whatever, there's almost no chance that that project was going to be the one hit to create that career-defining moment for an engineer working on it. If we make a habit of doing all projects that way, though, we take the total likelihood of those moments of greatness from "definitely sometimes" to "never".
The precisely appropriate ways in which to resist AI encroachment on all software development lie well beyond the margins of this one short post. How much you can resist and which specific uses you should resist are up to you. But it is worth resisting in software just as much as it would be worth resisting in any creative medium.
Programming isn't special. It's just Art, and Art is the most human - and thus, the most universal - thing that there is.
Acknowledgments
Thank you to my patrons who are supporting my writing on this blog. If you like what you've read here and you'd like to read more of it, or you'd like to support my various open-source endeavors, you can support my work as a sponsor!
09 Oct 2026 7:00am GMT
28 Sep 2026
Planet Twisted
Glyph Lefkowitz: What Would A Serious AI Product Look Like?
One of the issues that I have with the current generation of "AI" products is that they do not appear to take their own premises seriously. I look at a plethora of obsequious chatbots claiming to be serious tools for problem solving, and I think, this is not what a problem-solving tool would look like.
Even before we get to the tremendous ethical problems with the frontier labs, it is this impression of their composition as a product that makes me feel, constantly, whenever I am interacting with them, that they are less a software product than that they are a grift, a scam designed to make me feel like I am interacting with a product that has capabilities that it simply does not, to try to lull me into a false sense of security that I can trust it.
The frontier labs are of course the worst offenders, but every criticism here applies just as much to Ollama, which (if anything, due to the obviously poorer quality of the available models themselves) needs these features even more than the frontier labs do.
Here, I will set down a few features that might convince me that an LLM-based product, particularly one focused on research or software development, was actually serious about helping me do useful things with it.
Make "Checking For Mistakes" A First-Class Feature
This is the biggest issue, and the major reason that I was inspired to write this post.
It is a truth universally acknowledged, that AIs cannot reliably provide information.
I could cite a ton of news articles and studies about this fact, but there is no need. Every single chatbot admits this, up front, in a fine-print disclaimer as a core part of their user interface. Gemini says "AI can make mistakes, so double-check responses", Claude says "Claude is AI and can make mistakes. Please double-check responses.1" ChatGPT says "ChatGPT can make mistakes. Check important info.".
Every time I see that last one, I wonder how I'm supposed to know what "info" is supposed to be "important".
All of these warnings are all small, gray text, painfully obviously included as legalese to push responsibility back onto the user rather than to help with anything. This is a core limitation of all these products. Checking their output is a part of the workflow for using them that:
- you absolutely cannot skip or skimp on without creating risks to yourself and whoever you are conveying its output to, and,
- it is very easy to skip or skimp on and you are encouraged at every turn to do so, because "just trust the output" is one of the quickest ways to save time.
A chatbot product that took this weakness seriously, as an actual consideration for using it, would put a checkbox next to every claim in its output. It would be a 2-column worksheet, where you've got the LLM output in the first column, and next to it, human notes in the second column, explaining what work went into checking this claim, and a big checkbox that you would only check off after you believe you'd checked its claims thoroughly enough.
Coding assistants would need to have some version of this as well. Right now, this is pushed off into code review, which means it is a dark pattern which subtly encourages the "author"2 to offload this work to their code reviewer without ever looking. Once again, "it's probably fine, I don't need to check" is the quickest way to save time and churn out those PRs faster.
It might even be useful for coding harnesses to have some affordance for checking code before it even runs tests. As the vendors themselves have admitted, it's not just expensive to burn tokens on your "AI", you also end up burning far more compute on the AI. Being able to check your diffs before sending them over to uselessly exhaust your testing compute cluster would be useful.
If your product tells me that it makes mistakes and I must be the one to check for the mistakes, but then gives me zero tools to check for mistakes, I cannot take it seriously.
More Citations to Check, And More Details
Most chatbots prefer to give an answer, rather than a citation. In my own personal use, I find that when asked to provide a list of citations with clearly marked sources for each one, they will appear to "get bored" halfway through the list and simply stop including citations at some point.
When the bots include citations at all, present them as inline annotations that say nothing but the domain name of the search result, in a font so small that it's barely legible, and an equally indecipherable icon that is fewer than 16 pixels on a side.
This is backwards.
Now, I am aware that these citations do come from somewhere, and in an attempt to reduce hallucinations, all of the major providers support some form of "grounding"3, and that those little barely-readable citation links are referencing actual structures in the RAG pipeline and not just potentially-hallucinated tokens, but I'm not talking about the underlying machinery in the model, I'm talking about the presentation to the user.
Plus, regardless of whether a snippet of text came from a RAG query, we know that LLMs can never provide an authoritative result; it's a fundamental limitation of the technology. They can still garble the results of RAG as much as they can misrepresent any other training data. This means that it must never present its results as authoritative.
If you ask an AI to do research queries, every result should be presented as a list of citations. Moreover, the presentation should display each citation as a large object of in its own right, with clearly identified metadata, including not just the site where it was found but its publication date and, if possible, the name of the author. The literal, unmodified quotation (not from RAG, not a summary: a quotation extracted with a regular program and not an LLM) should be front-and-center, larger than any AI-generated text.
If the AI product wants to editorialize or summarize (which should not always be necessary!), the AI-generated text should be presented as small text underneath the citation that has been found, de-emphasized as much as the disclaimer is right now, at the very least until the user has verified that the summary is accurate. Perhaps, for a research project, a "did you read the citation" checkbox might even be helpful.
If your product openly tells me that it will scramble, misrepresent, or omit its citations in its summaries, and I must read the original human-authored citations to be sure, but then gives me no tools to track my reading of those citations or even any way to find them, I cannot take it seriously.
No First-Person Output, No Apologies
There is no reason for a software development or research tool to use first-person language to describe itself. They should not do so. In fact they should not be allowed to do so.
There is also no reason that they should ever apologize. It is a waste of everyone's time; it's a waste for the chatbot to generate the apology, it's a waste for the user to read the apology, and it's a waste for the user to respond to the apology. Yet they unfailingly do this upon every correction.
The vendors of these tools know that they are routinely causing mental-health crises. In response, they have added non-functional "guard rails" that can still, in 2026, easily be bypassed.4
A product seriously interested in helping with productivity would correct this glaringly obvious flaw, focus on the task at hand, and stop emitting useless verbiage.
In the previous two sections, I tried to focus on ways in which the harness would be constructed differently even if the LLM technology is fundamentally impossible to improve; in this case, I have to assume that the labs have some control over the model itself. But unless they are truly incapable of influencing their output (and all their "benchmarks" and "capabilities" seem to indicate that they can control it very tightly) they ought to be building models that are much less verbose.
More Non-Natural-Language User Interfaces
Although natural language could hypothetically be a powerful interface for interacting with a computer system, the practical upshot of LLM natural language interfaces is that these interfaces are imprecise and repetitive, full of superstitions masquerading as "best practices". The inputs are a mess and the resulting outputs are a mess.
The general way of addressing this unstructured mess is to allow the chatbot to directly take action in response to the user's input; in other words to supply it with "tools" via an MCP server. But again, this is backwards. If we cannot even express our intent clearly in the first place, why are we trusting this system to take potentially destructive and harmful actions on our behalf?
Instead, I would expect a product that was seriously invested in helping me accomplish specific tasks, to have user interfaces specific to those tasks. Is it supposed to be able to be a security scanner that can discover OWASP top 10 bugs in a codebase? Have a button for that. Build that functionality into your harness, train it directly into the model, use smaller models that can satisfy that functionality more effectively than throwing it at the planet-sized brain of Fable or whatever.
I'm aware that there are small software startups that do something like this, but they are bolted on to the side of the main model providers' APIs, not integrated into the core of the product and not using their own models and AI systems to achieve consistent and repeatable results.
Strong Data Provenance Indicators
Chatbots produce data tables pulled from websites, from APIs, from MCP tools or from summarizing and scrambling the user's input. In order to provide the illusion of a seamless interface, this data is presented in-line regardless of where it comes from. But some of these outputs are produced mechanically via regular old API calls, for example, from the result of calling a tool or querying a website, but presented uniformly.
But there is a huge difference between an authoritative data source being inlined as part of a chatbot conversation, being treated as input by the chatbot, and some ad-hoc hallucinated data being treated as output of the chatbot.
If a product is trying to help me make accurate, empirically-grounded, data-driven decisions, the source of the data is critical.
Integrated into the "check for mistakes" and "verify citations" workflow I described above, there's a necessary "verify data programmatically" pass as well; to have tools that will treat portions of the output as a regular spreadsheet, allowing regular-old computer arithmetic to verify things and showing where such arithmetic was used, and how.
Better User Control of Reproducibility
Anyone familiar with the technical specifics of LLMs will know that they have a variable called "temperature" which controls the degree of randomness that the LLM uses to produce its outputs. But most users don't know this, because it isn't exposed as part of the user interface by default.
This leads to a subjective impression that you asked ChatGPT, and you got ChatGPT's authoritative answer.
You can't just set the temperature to zero and still get useful results - I am aware that it does more than just scramble the output at random, and there are perhaps good reasons that simply exposing just a temperature setting would not be that useful to users. But if we followed some more of my earlier recommendations for making more structured UI elements to solve specific problems rather than having long back-and-forth chats where each refinement depends on the previous response, perhaps those elements could also re-play the process so that users can see how reliable the bot is at a particular task and develop a sense of how the stochastic nature of the process actually affects it.
Similarly, if a user is trying to solve the same problem repeatedly with a chatbot, and the chatbot product has numerous computational tools that don't really have anything to do with the LLM, such as deterministic data-processing tools, then having a way to freeze the non-deterministic parts of the transcript but re-populate a particular data frame with updated information and fork / continue the conversation from there would be a way to avoid introducing pointless additional randomness when you already know what tool you're trying to use.
The fact that every conversation is presented as this flat chat prompt that doesn't let me interact with any of the widgets that were previously produced except through more chatting, really makes me feel like the whole product is just doing predatory social-media style "increase time on site" optimization, just trying to lure me into further repetitive and unreliable chats, rather than letting me get in, solve my problem, and get out.
Context Visibility
Managing the LLM context is the ongoing challenge facing organizations that are trying to use "agentic" workflows. Filling up the context with too much information causes well-known problems. In response, advanced LLM users attempting to solve larger problems must break up very long prompts into "skills", give access to lengthy information via "tools", and delegating sub-problems to "sub-agents" rather than simply extending a single prompt indefinitely.
All of these strategies have flaws, because even on the largest models, compared to the breadth and depth of knowledge-work problems, LLM contexts are quite small.
And yet, none of these products will show the context to the user by default. There are third-party addons that can show you a simple progress bar but for addressing the premier engineering difficulty with this technology, that is below the bare minimum.
This lack of visibility means that almost all of the tools for extending the context are flying blind. Rather than responding meaningfully to a full context, everyone just kind of guesses how much state they need by guessing and trying over and over again with progressively more elaborate skill and sub-agent layouts. Even managing context compaction ends up being an advanced API-driven workflow5.
A serious product that was trying to help the user understand would not only show "available context" but explain the impact of context compactions, make it easier to see harness-generated prompts, and so on. This would be a first-class feature, combined with the aforementioned reproducibility / replay tools, would allow users to do real experiments to develop an understanding about how to make good use of the context window.
A Sandbox That Actually Works
I've been focused on the chatbot interface here because it is the most immediately egregious upon looking at the UI. But the "agentic loop" tools used for coding are equally dangerous, if not more so. Coding tools keep destroying everyone's data, over the course of years.
These catastrophic incidents that become front-page news are relatively rare compared to the amount of coding-agent use out there. But they also aren't the only kind of sandbox violation. Coding models will so routinely edit test code instead of the system under test that there are "pro tips" articles all over the web giving you the flawed advice to simply ask the agent not to cheat. News write-ups of the catastrophic incidents themselves will also offer glib and wrong advice, like "use a docker container". That might prevent it from literally deleting your operating system, but it won't prevent it from destroying all the local work you have in your codebase (it needs access to a checkout, after all!)
There is a flurry of activity in the infosec space where people are rushing to plug the gaps left by these coding harnesses. Everyone's got their own version of an MCP approval gateway where you can optionally place a proxy between your agent and your production infrastructure.
In the best case, though, all these mitigations and proxies and prompts simply turn the user into an auto-approval automaton, hitting Y, Y, Y, Y over and over again, until you finally are driven mad and hit "yes to all", turn on full-auto mode and submit yourself to the void. With nothing between your personal vigilance and disaster, there are no workflows left beyond decrementing your own vigilance until there's nothing left and then hoping the disaster never arrives.
The fact that some mitigations exist that can be deployed by extra-cautious users does not change the fact that "agentic coding" is an unsafe-by-default technology deployed without concern or guidance. Every frontier lab has tied a spring-loaded shotgun to a dog; the fact that dog owners can publish thoughtful blog posts explaining how you can teach your dog the basics of gun safety or how you can have your dogs play in a bullet-proof room does not mitigate the fact that the product should not have been allowed in the first place, nor should it continue to exist without VERY strong security controls.
I might believe that a frontier lab were seriously interested in providing developers with a useful tool if they shipped something that had safety built-in.
That means tools in the harness, detached from any LLM, independent of the prompt, that could:
- sandbox all filesystem operations and strictly limit ANY deletions outside of specified scopes, regardless of operating system,
- enforce snapshotting of the entire repo on every operation for easy rollbacks and minimal lost work,
- remove the disaster of "auto mode" (not to mention nonsense like
--dangerously-skip-permissions) entirely, and - carefully consider a structure for presenting plans to the user where, rather than provoking immediate alert fatigue by asking for checks on every action, make structured plans which can be submitted to the user as a group of actions and reviewed and approved as a batch.
In the same way that I suggested above that research-based tasks should have a way of re-issuing prompts to determine how reproducible a result is, or whether other sources might be found, agent-based tasks should have a way of being executed against mock services for popular APIs, so that the verification can match both on the front-end (review the plan for making the API calls before they're executed) and the back end (review the API calls that were issued to the mock service and verify that they matched).
Instead, the frontier labs provide us products that are disasters out of the box, give us "best practices" to build massive and elaborate, as well as incomplete and error-prone, security perimeters of our own design. Then they blame "operator error" when it inevitably goes wrong. I cannot believe that these design choices are intended to help us be productive.
Bonus: Human Processes
Organizations deploying AI also frequently come across as unserious, for similar reasons. In 2023, naive exuberance could perhaps be forgiven. But today, as we near the close of 2026, there are several well-known problems, that have been extremely well-covered in the press. None of these things should be surprising, but most orgs deploying these tools are still just letting them rip and hoping it all works out.
Organizations deploying these tools would need at least three kinds of major modifications to their internal processes, if they wanted to be serious about using them safely:
1. Shift Rotations to Prevent Vigilance Decrement
There have been several high-profile incidents where software developers' gradual acquiescence to accepting LLM output have lead to serious economic consequences for the companies deploying them, perhaps best typified by Amazon's "millions of lost orders" due to a gradual decay of their engineering processes from LLM use.
These outages, and other AI-related failures, are due to the difficulty of maintaining focus on the same problems. In other words, as I described above, vigilance decrement is a constant problem, because AI outputs are most often correct, but continue to be incorrect in surprising and non-intuitive ways. As I have previously written, you cannot trust yourself to catch every bug with code review, and LLM output.
Aviation, for example, has very strict rules around rest requirements. There is also a specific rule that "No certificate holder may operate an aircraft without a second in command if that aircraft has a passenger seating configuration, excluding any pilot seat, of ten seats or more.". Other safety-critical professions have similar rules.
And yet, even in the age of the supposed "AI revolution", most software teams are still assigning every engineer a full feature load, not planning for any rest, and telling people to review code whenever they happen to have some "free time".
Maintenance of vigilance has to be your top priority. Regular, scheduled, inviolable rest periods where people do work without AI assistance, and are not exposed to any AI output for review or otherwise, would be crucial in order to stay mentally sharp enough.
The tools themselves should have this sort of thing built in. The mistake-review process described above should have a periodic spot-check mode where a second reviewer periodically reviews a chatbot log, doing their own independent verification of claims, to see if they spot the same errors. This could provide a feedback loop to determine how much rest is necessary to maintain continuous attention and actually spot hallucinations.
2. Skill Practice To Prevent Skill Loss
It is also well-known that AI use leads to AI reliance, and AI reliance leads to skill loss.
I like to use the analogy to dockworkers at a seaport6 adopting automation.
If you employ dockworkers to load and unload ships all day long, they are going to be getting tons of exercise. They will be able to lift heavy objects on demand, whenever. They might have plenty of health problems and injuries from this type of work, but "lack of exercise" will not be a problem.
With the development of standardized container ships and mechanized cranes, you are going to be changing their job description substantially: now they mostly spend all day sitting in a small cubicle moving a control lever back and forth, not lifting heavy stuff. They will get worse at lifting heavy objects.
In this analogy however, the cranes are not all that reliable. We know they break, and they drop their payloads sometimes, and the stuff needs to be manually moved. But this only happens a few times a week, at most. If you need whoever is driving the crane to be able to jump out at any moment and still move stuff around manually, then you need to make an affordance for that. You need to give them time to go to the gym and do some lifting for practice, or every crane failure is going to be a major emergency.
An organization doing an AI transformation would also need a massive increase to learning & development budget, both in terms of resources and in terms of schedule. If your people are going to lose skills because they've lost regular practice in the incidental course of doing their duties, then they are going to need deliberate, intentional, non-incidental practice of those skills to keep them sharp.
But rather than trying to accommodate new workflows and give time for people to adjust, most AI mandates are simply dropped on workers like a ton of bricks, with no time to adapt and no affordance for maintaining their skills. Operate the crane and stay fit and healthy and ready to switch back to manual lifting at any time and then get back in the crane cockpit right afterwards. Don't mess up.
Then an accident happens and everyone is surprised, as if this process weren't practically designed to produce a terrible result.
3. Mental Health Resources to Deal with Mental Health Risks
AI psychosis often begins with practical problem-solving, and beyond that, it can start specifically at work. Not to mention the more pedestrian condition of "AI brain fry".
If you are mandating your employees to use a hazardous tool that may seriously and directly damage their mental health, you need trainings and resources. You need in-house therapists and you need to be making sure to check in with people actively to make sure that this is not happening.
Again, the tool itself ought to have some way of dealing with this. An occasional "take a break" popup is easily dismissed; they need a user-visible AI personal dosimeter so you can see your cumulative usage over time.
I don't even know if "usage over time" is a sufficient metric to gauge risk. Maybe if your work chatbot start to talk about resonance too much, unless you literally work as an acoustic engineer, that should be flagged for someone.
We are, again, years into dealing with these tools, and we know these risks exist. Yet no serious mitigations are provided. Not even any way of measuring the risk exposure.
And More
There are also many other risks associated with the technology. There are intellectual property risks with the foundation models, due to recklessness with their training data. There are existential financial risks associated with the infrastructure build-out. The extent to which most "open" models are simply derivatives of frontier models is an open question.
What I Think
If any one of these things were regularly overlooked by AI vendors or users, that would be a totally normal product oversight. Room for improvement for the next version, but nothing catastrophic.
Shipping without any of them doesn't seem like lean product management, it seems like a careless attitude towards risk and a product design philosophy oriented entirely towards short-term demos, with no regard for how to realize actual productivity gains.
Furthermore, being available for years without anything like these features, despite hundreds of incidents demonstrating the risks, with hundreds of billions of dollars of funding, makes it seem to me like if they were to add all the features that would make their product actually safe and hypothetically useful, these features would reveal that it is actually not an improvement to productivity.
In the year since I first wrote about measuring the cost/benefit ratio of AI, I have heard from numerous people who have shown this to management to try to illustrate why their AI initiatives - like almost all AI initiatives - were either failing or burning out their engineers.
I've also heard from lots of people that have told me that it's obviously useful and they don't need to measure so carefully, because they are getting lots of work done that they couldn't have otherwise.7
I have yet to hear from a single person who has said "yeah, we measured according to your methodology8, and it turns out that our AI work is going great and that our ratio is 0.75".
Obviously, I cannot say for sure why this is; absence of evidence is not evidence of absence. But at this point I think the null hypothesis is that AI tools provide, in aggregate, zero value. They make mistakes too often, and the externalities they produce are so bad and so difficult to control that even before we get to the places where they are just physically poisoning people, even the negative effects on their direct users end up cancelling out whatever benefit to they provide to their organizations.
If I were wrong, then including tools to measure an AI's effectiveness at the tasks their users are actually trying to accomplish, rather than meaningless benchmarks, would show big productivity gains. The frontier labs would be champing at the bit to add such features, and crowing about their fantastic results.
I think the labs know that if they did that, it would present a grim picture to their users. Such tools would let their users see that it's making mistakes much more often than they realized, that they're spending much more time with it than they want to be, and that it's just generally not fit for purpose.
If they prove me wrong by adding in all of these safety mechanisms, and in the process, they make all of their AI technology less harmful, I'll be thrilled to be debunked.
Acknowledgments
Thank you to my patrons who are supporting my writing on this blog. If you like what you've read here and you'd like to read more of it, or you'd like to support my various open-source endeavors, you can support my work as a sponsor!
-
It is also interesting that for the next section, sometimes it seems that Claude's disclaimer is "Please double-check cited sources." instead. ↩
-
... by which I mean the "prompter", since authorship is not what's happening here. ↩
-
Claude has the "citations API", Google has various different kinds of "grounding" against its own APIs, and I guess Microsoft can check OpenAI's homework if you want. ↩
-
Given the relatively slow speed of the justice system and the mainstream press around the world, we probably will not hear about whether people are managing to incidentally break through these guard rails to self harm right now, but there are no shortage of stories still being reported right now where people were still doing just that, such as in this story where the effect of the much vaunted "guard rails" in 2025 was that if you wanted it to write you a suicide note, it would refuse twice but acquiesce on the third try. I don't see any reason to believe this fundamental issue has been addressed in the meanwhile, since it had been happening for years at that point. ↩
-
In this tutorial we can also see an incredibly rosy scenario presented, where a long-running workflow effortlessly compresses all of the necessary information into the new context, even if it uses a lower-fidelity model to do so, rather than the tangled and gnarly problem of problems which really are too big to fit in the context, which is to say, "most real-world problems". This presents the context limit instead as a minor speedbump to be worked around rather than the fundamental flaw in LLM tooling. ↩
-
A heavily fictionalized seaport. This is not how actual dockworkers work. This is a simplistic metaphor about incidental benefits of instrumental tasks, it is not supposed to delve deeply into the mechanics of maritime shipping. In particular I know that cranes are more reliable than this and this is not actually how you would respond to a crane malfunction anyway. Feel free to share fun facts about maritime shipping if that is your special interest but please do not @ me to correct this metaphor. ↩
-
To my knowledge, none of their publicly-traded employers have posted a measurable improvement to efficiency outside the margin of error. ↩
-
Or any similar methodology. I don't need people to adopt the exact practice that I proposed there. ↩
28 Sep 2026 4:27am GMT