22 Nov 2026
 Planet Grep
Mattias Geniar: nginx HTTP/2 RCE (CVE-2026-123633, CVE-2026-123007): patch status per distro

Two bugs in nginx's HTTP/2 code allow remote code execution without logging in: CVE-2026-123633 and CVE-2026-123007 . Every nginx from 1.9.5 to 1.31.8 is affected when HTTP/2 is on. The fix is in nginx 1.30.7 (stable) and 1.31.9 (mainline), released on 18 November 2026. The best fix is to upgrade from nginx's upstream repo . It already has the fix. Otherwise check your distribution in the table below. Switch HTTP/2 off until it has a fix.
22 Nov 2026 12:32pm GMT
Mattias Geniar: PHP security release of 19 November 2026: patch status
PHP released 8.2.36, 8.3.37, 8.4.28 and 8.5.13 on 19 November 2026. The security advisories went public at 14:05 UTC. They fix 17 security bugs, 7 of them CRITICAL (ChangeLog ). The worst one affects PHP-FPM when the web server in front of it reuses FastCGI connections. See Am I affected? , then patch .
22 Nov 2026 12:32pm GMT
Lionel Dricot: The Simulation We Are Living In
The Simulation We Are Living In
Or How We Are Roleplaying a Successful Capitalist Life
Nat wrote a piece about Copilot being the peak-oil of high technology.
I agree with Nat's anger and the feeling of disorientation.
I've lived through multiple tech bubbles and, in all of them, the "believers" were a minority. In fact, you always had a minority of vocal believers opposing "serious seasoned people". The vast majority of the world didn't care much about the bubble or were exposed to it only through mainstream media. I've witnessed crazy stuff, including very influential and powerful people trying to "join the bubble". But if I disconnected, walked out of parties or meeting or went outside, I would see little trace of the bubble.
With the AI bubble, it seems like nearly everyone has been turned into a believer. Around me, every single conversation seems to be about AI, especially in non-tech circles. While my experience told me that most industries have always been very reluctant to adopt new technologies, we are witnessing a world where every big company, every CEO, every manager and every teacher/academic is suddenly voluntarily sabotaging a lifetime of experience to make sure we use an unreliable-by-design tool everywhere even though it barely existed a couple of years ago.
From a technological perspective, this is absolute nonsense.
Remember that everything is propaganda
Reading Chomsky helped me a lot here: I was reminded that everything we read, everything we
hear is propaganda. Those are not facts. Those are intentionally designed messages to turn us into believers.
The current propaganda is geared toward making chatbots the new norm because this is our current consumption bubble and the system always needs something into which we will inject as much money as we can.
According to Chomsky, propaganda means you should always invert cause and consequence:
- People don't write good things about vibecoding because it works for them, they believe it works for them because they read and need to write good things about it.
- Chatbots are not inevitable: people try to convince themselves they are inevitable to justify using them.
We now know that, at least for Open Source programming, AI doesn't make you more productive. But it makes you believe that you are. Just like drugs make you believe you are smart and alcohol makes you believe that you are a good driver. The productivity of LLMs is not a fact. But the intoxication is real.
The propaganda is not even subtle! It is transparent and sometimes borderline parodic, like the time when an Anthropic employee recognized that it was stupid to have an AI managing your business but you had to prepare for that world because you had no choice.
Bad managers are leading the world
In the end, this is mainly propaganda to make us believe that we live in the world as seen through the eyes of Juliuses (my word for what Ed Zitron calls "the business idiots").
Juliuses are people who don't even understand that there are things to understand. They don't even have access to that part of consciousness where you truly understand a concept. They live in a blurry state of consciousness where they only care about the "next action". They
don't have any notion of "rationality" or "logic". They believe intuition is as good as scientific knowledge ("Oh, you are Sagittarius? That explains why you speak like that!")
Feynman famously said that, to solve a problem, you need to:
1. Write the problem down
2. Think hard
3. Write the solution
As Feynman said, most people do everything they can to skip steps 1 and 2.
They really want to go straight to 3. That's why AI is wonderful: it even does what looks like step 3 for you if you are not qualified enough to check.
But it cannot work for one simple reason: if your problem is not clear, you will never have a good solution. Writing code is 90% about defining the problem and all its edge cases. Writing code is taking decisions, by essence. The same can be said for legal contracts. Lawyers are people who write a form of code where they want to account for every conceivable situation and decide what to do before it happens.
We are delegating our free will to remove accountability
In his book "Éloge du bug", Marcello Vitali-Rosati draws an analogy with the genie of Aladdin. In the story, Aladdin asks for "beautiful clothes" and the genie obeys. Or does he?
In fact, the genie makes a lot of decisions about what "beautiful clothes" are. Would they be clothes that "look expensive"? That "follow the norms" or, on the contrary, that are completely new and creative? Without realizing it, Aladdin completely gave up on his free will and his own identity. From that moment, Aladdin is just a puppet in the genie's hands.
The whole point of vibecoding is "let an opaque proprietary algorithm controlled by a huge economic entity take all the decisions about what it thinks I want now and how I should live my future". It cannot work if there's some accountability in play. Nobody would sign a randomly generated contract. So the trick is to remove accountability.
We have all encountered examples of "I'm not wrong, this is what AI told me". By communicating a lot about ChatGPT mistakes and saying they take them seriously, OpenAI is reinforcing the sense that you are not accountable for blindly obeying ChatGPT. You can delegate your responsibilities to them. The whole discourse about "inevitability" is only that: it is about removing liability and responsibility. "Of course I signed that random contract. Everyone does it. It is inevitable. And they will make the next contract better."
Juliuses live in a world where they do everything to get immediate benefits and avoid accountability. That's what modern businesses are built for: you get the money as an individual but the company pays fines and nobody goes to jail, even if you kill millions with a defective product (except if you mess with shareholders money,then you are liable). At worst, you are fired (with a golden parachute if you are high enough on the ladder).
In that regard, LLMs are a terrible engineering tool. After all, they have random output, are unreliable by design and act randomly. But they are perfect business tools because they remove agency, free will and liability.
The successful capitalist roleplay
On his blog, Ron Gilbert quotes "AI feels amazing when it's talking about a subject you know nothing about, but is laughably wrong when you do". The solution is thus simple: make sure nobody knows anything about anything anymore.
The social media bubble was led by marketers and their view of the world. They wanted us to believe that everybody was a marketer, that our life should be marketed ("personal branding"), that every happy moment was there to "advertize" how cool we are. People do not meet to have fun, they meet to take pictures to convince the world they had fun.
The cryptocurrency bubble was led by financiers. They told us that everything is an asset and everyone is a trader. We should all become rich while selling assets to each other. The AI bubble is led by management. Everyone should be the manager of a team of "agents" that blindly obey and agree to everything we say.
The capitalist system is successfully selling us the fact that, after our long hours at a shitty job, if we are lucky enough to have one, we can roleplay a very successful capitalist life on a small bright screen. Indeed, they were wrong about the VR bubble! No need for immersive virtual reality. We are intoxicated enough by the capitalist roleplay to break our necks while spending our nights looking at a screen smaller than those Terry Gilliam envisioned in Brazil. At least, in Brazil, they still had real keyboards!
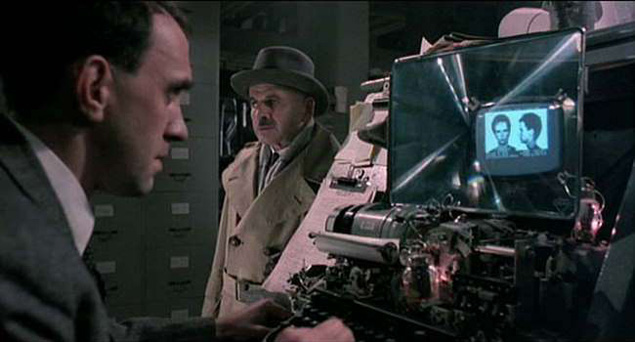 Still from the movie "Brazil" (by Terry Gilliam)
Remember the pods in The Matrix? Turns out small addictive screens do the job. We even pay for them! Neo is not fighting Agent Smith with a cool leather jacket and guns. He wears a lousy t-shirt and is ignored, frowned upon or, at best, offered social skills therapy.
When you understand that this is all propaganda, a fiction, a shared dream (or a nightmare), that business people are all lying through their teeth because, for them, it's part of the game, it gradually starts to make sense.
But it is no less frightening…
About the author
I'm Ploum, a writer and an engineer. I like to explore how technology impacts society. You can subscribe by email or by rss. I value privacy and never share your adress.
I write science-fiction novels in French. For Bikepunk, my new post-apocalyptic-cyclist book, my publisher is looking for contacts in other countries to distribute it in languages other than French. If you can help, contact me!
22 Nov 2026 12:32pm GMT
LXer Linux News
KDE Releases Kwi 0.1, Its New GPU-Accelerated Terminal Emulator
KDE's new Kwi terminal emulator reaches version 0.1 with improved tabs, global menu support, interface refinements, and a Flatpak release.
22 Nov 2026 11:48am GMT
Linuxiac
Libreboot Reverses AI Code Ban, Adopts Reduction Policy
Libreboot reverses its total AI code ban, introducing a policy to reduce AI-generated contributions while allowing exceptions when necessary.
22 Nov 2026 10:25am GMT
LXer Linux News
Linux 7.4 To Remove NVMe Namespaces In Parallel For Faster Results
As part of this week's block subsystem fixes for the Linux 7.4-rc4 kernel release due out on Sunday are many bug fixes plus also a nice NVMe namespaces optimization…
22 Nov 2026 10:05am GMT
Sashiko AI Introducing Linux Performance Specialist Review Stage
The Google-developed Sashiko for agentic AI code review initially focused on the Linux kernel continues helping to uncover new bugs and issues as new patches hit the kernel mailing list as well as those manually running this open-source AI software. In addition to recently introducing an experimental patch series design assessment, they are introducing another new skill for helping with…
22 Nov 2026 8:09am GMT
Planet Debian
Daniel Baumann: Debian: Modernizing iperf/iperf3 and introducing fireperf
Recently I spend some time on modernizing the packaging of the Internet Protocol bandwidth measuring tools iperf and iperf3 in Debian, as well as uploading fireperf to Debian.
Modernizing iperf
sudo apt install -yU iperf-server and you're donePreviously, src:iperf only built iperf. If you wanted to run an iperf server, you had to do it on your own, i.e. there was no systemd service for that.
Apart from tidying the Debian package, src:iperf now builds the new iperf-client and iperf-server packages, the latter contains the systemd and ufw integration. iperf-server runs with a dynamic systemd user and systemd service hardening.
The iperf package is now a transitional package, that also cleans up any leftovers from before the package split into iperf-client and iperf-server (e.g. when upgrading from trixie to forky).
For historical reasons, iperf2 is packaged in debian as iperf, not iperf2. Now the iperf packages have provides for iperf2, iperf2-client, and iperf2-server respectively (so they can be installed by these names too).
Updated iperf packages are available in sid, and backports for trixie are available at Debian Fast Forward.
It might make sense in the future…
given that iperf2 and iperf3 are completely different tools with different advantages and disadvantages depending on the use-case
therefore the one is not replacing the other (iperf2 in general is the better tool than iperf3, eventhough the common misconception is that iperf3 is supposedly better than iperf2 because the number 3 is greater than the number 2)
…to maybe rename iperf to iperf2 to match both upstream naming and also to harmonize the packaging of iperf2 with other distributions.
Modernizing iperf3
sudo apt install -yU iperf3-server and you're donePreviously, src:iperf3 only built iperf3. If you wanted to run an iperf3 server, iperf3 had a debconf yes/no question which would then start one iperf3 server on the default port 5201.
Apart from tidying the Debian package, src:iperf3 now builds the new iperf3-client and iperf3-server packages, the latter contains the systemd and ufw integration. iperf3-server runs with a dynamic systemd user instead of the previous local system account, and has systemd service hardening.
Since iperf3 (contrary to iperf, also see here and here for iperv vs. iperf3) does not allow using multiple connections on the same port, you have to run multiple iperf3 servers, each on their own port, in order to serve more than one client at the time.
The old debconf question for enabling a single iperf3 server has been removed as well as the obsolete sysvinit integration.
In order to allow running multiple iperf3 servers at the same time (but on different ports), iperf3-server now contains a systemd service template so you can enable multiple iperf3 servers (e.g. 3 servers on subsequent port numbers, but you can run as many as you want on any ports you like) either manually with:
sudo systemctl enable --now iperf3-server@5201sudo systemctl enable --now iperf3-server@5202sudo systemctl enable --now iperf3-server@5203or by using debconf interactively to do it automatically for you (which defaults to one instance on port 5201):
sudo dpkg-reconfigure -p low iperf3-serveror by using debconf non-interactively to do it automatically for you:
TMPFILE="$(mktemp)"echo "iperf3 iperf3-server ports string 5201 5202 5203" > ${TMPFILE}cat "${TMPFILE}" | sudo debconf-set-selectionsdpkg-reconfigure -fnoninteractive -pcritical iperf3-serverrm -f "${TMPFILE}"The iperf3 package is now a transitional package, that also cleans up any leftovers from before the package split into iperf3-client and iperf3-server.
Updated iperf3 packages are available in sid, and backports for trixie are available at Debian Fast Forward.
Introducing fireperf
sudo apt install -yU fireperf-clientsudo apt install -yU fireperf-server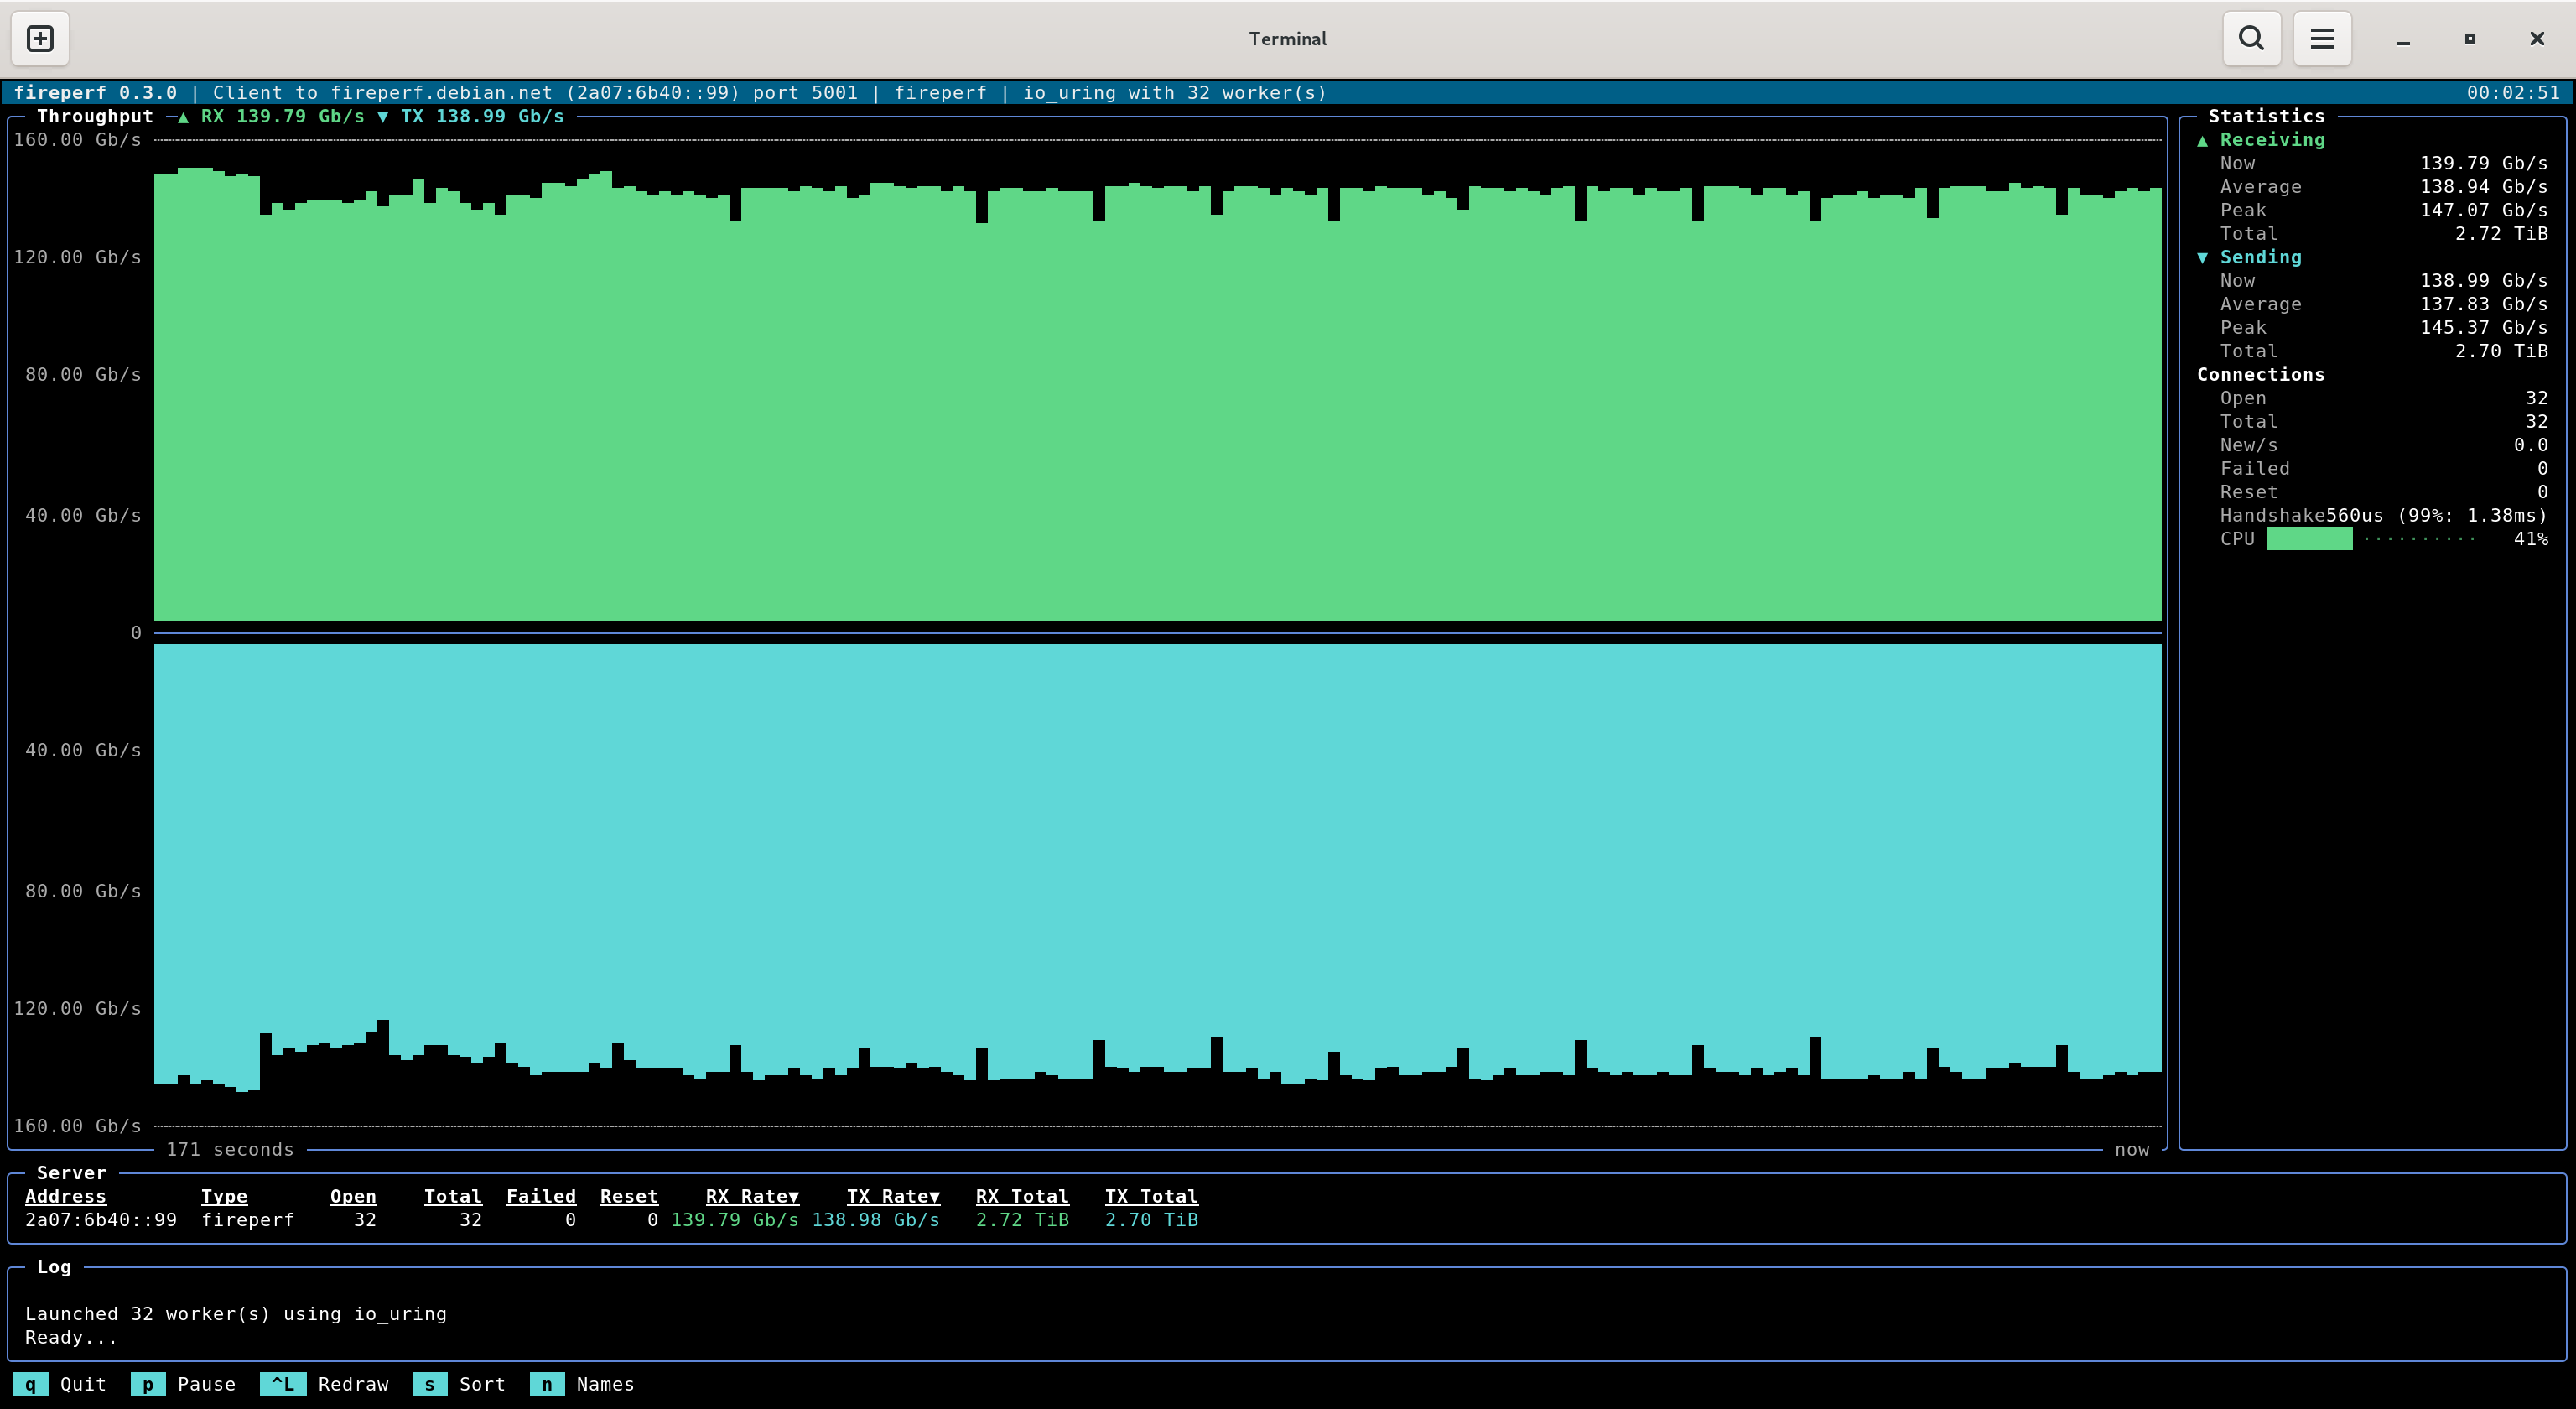
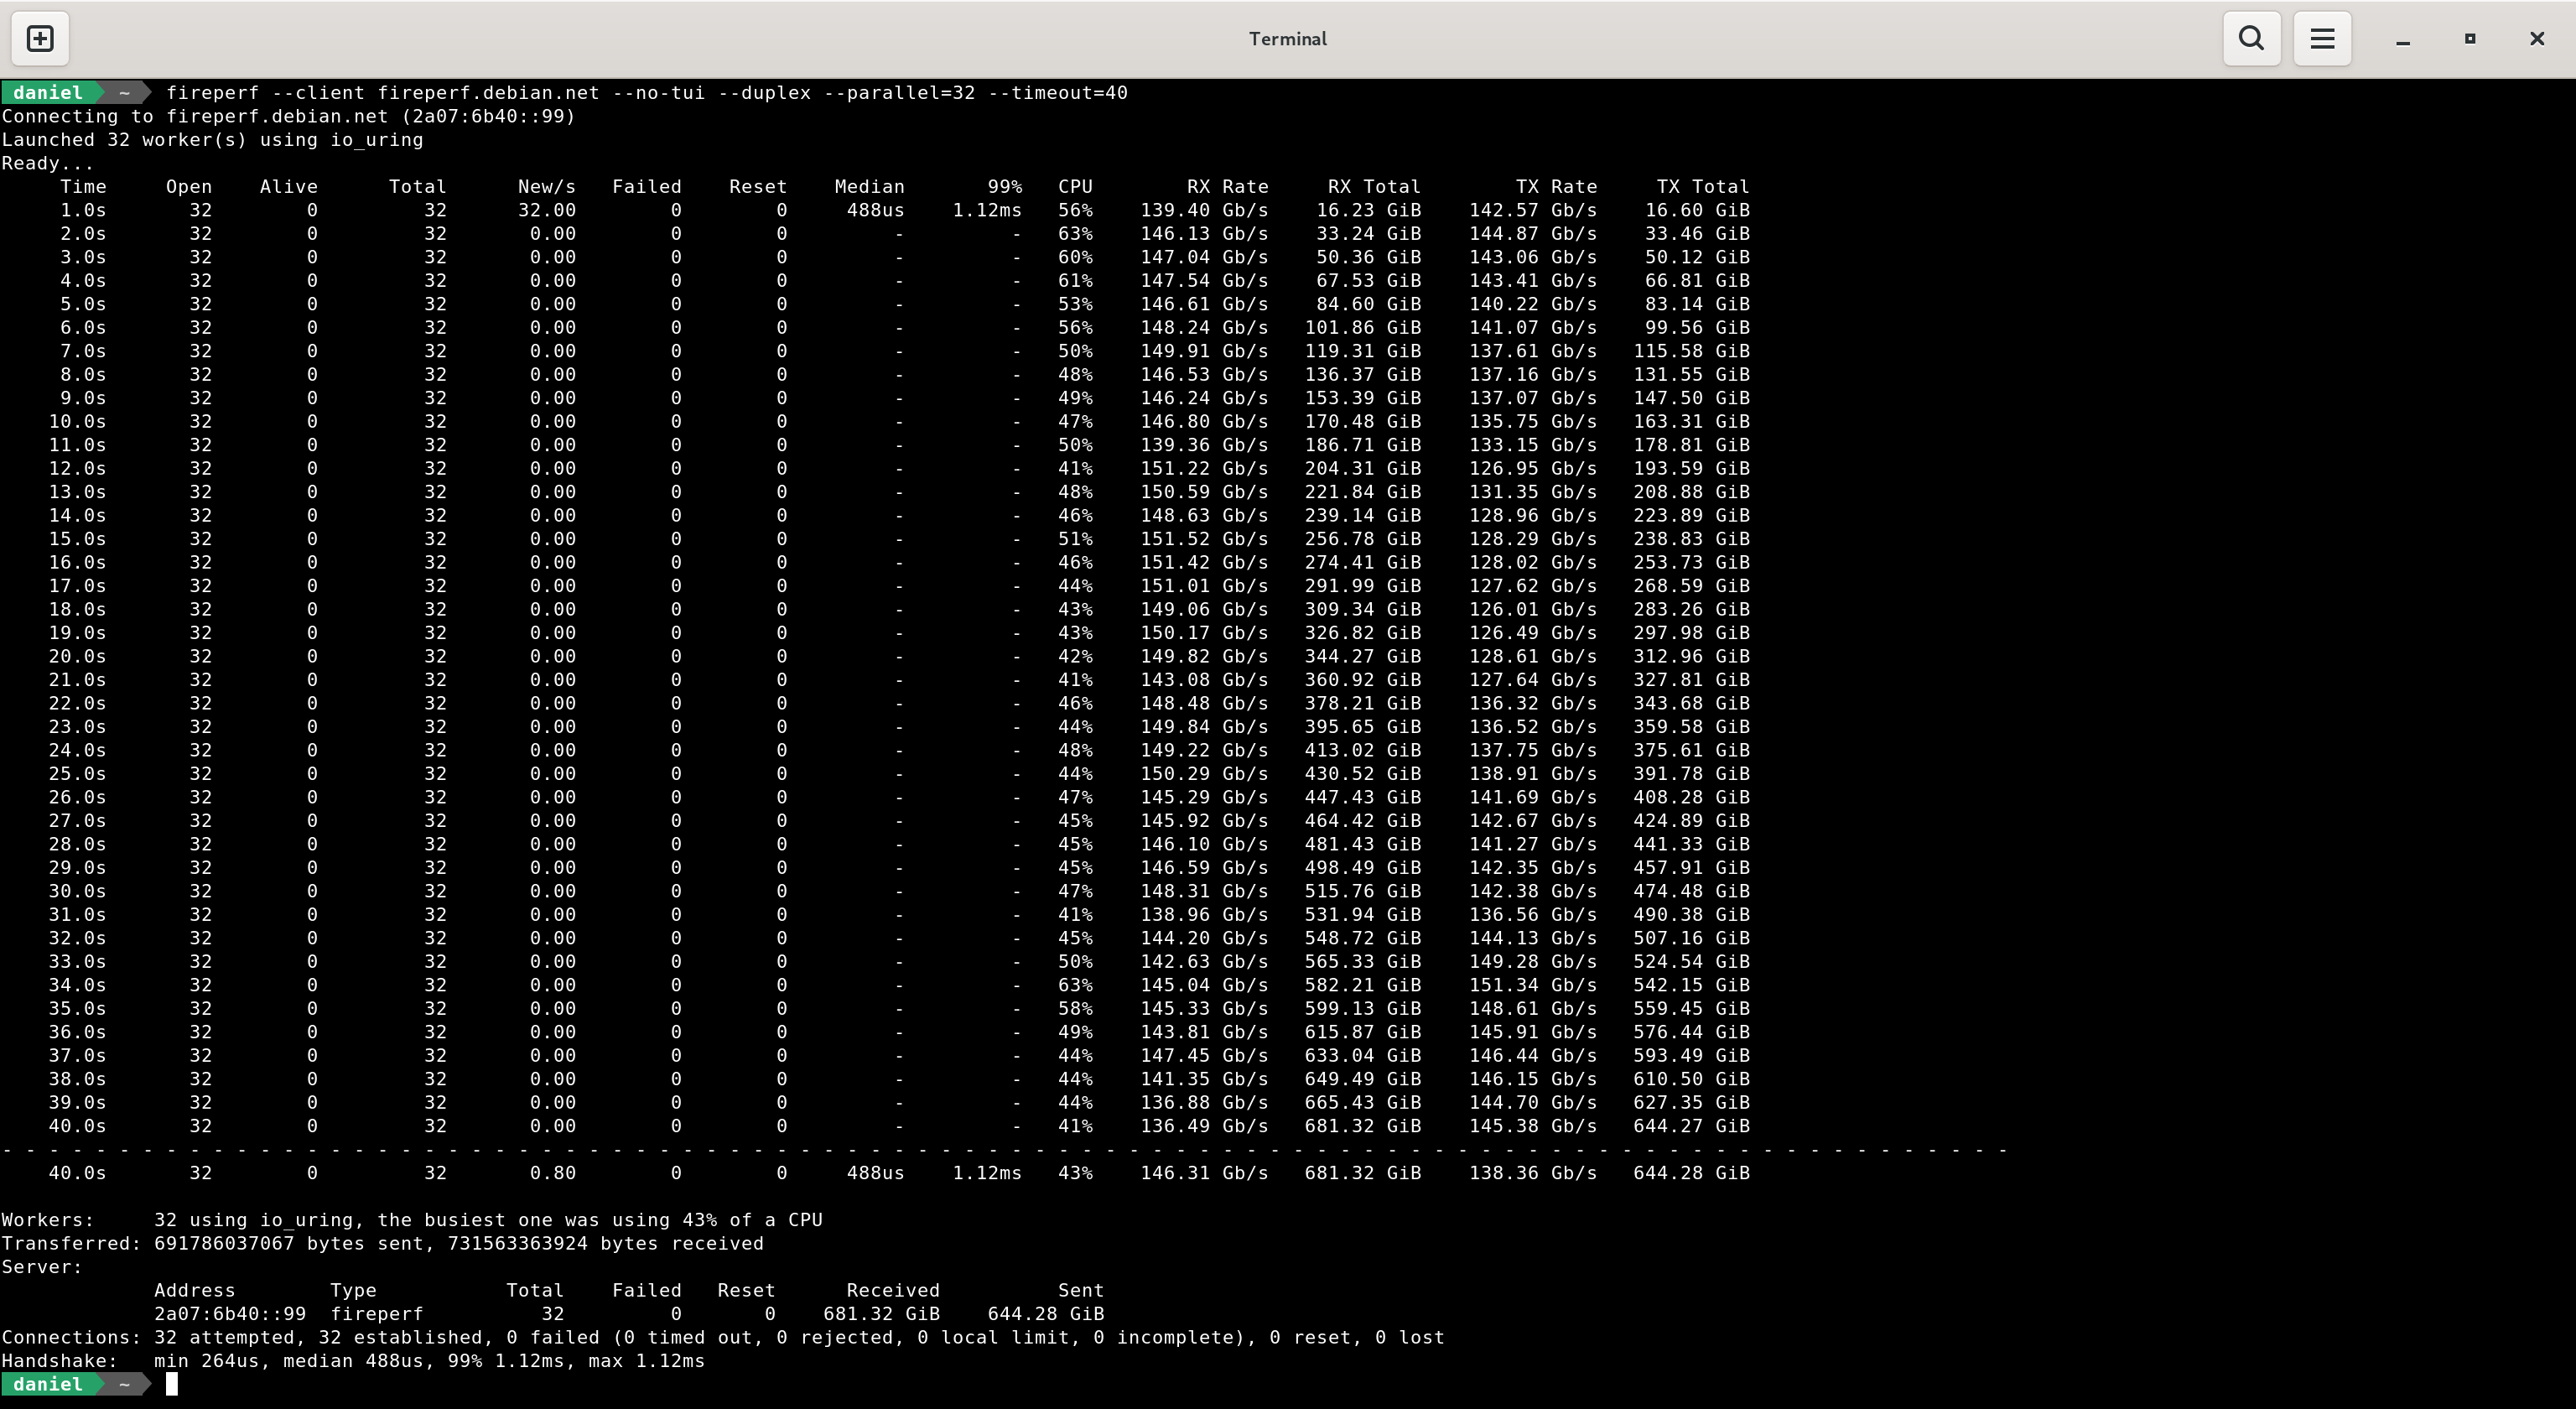
fireperf is a modern take on the iperf3 network performance and stress-testing tool under the IPFire project umbrella:
measures upload or download individually, or concurrent upload and download
allows to serve many clients in parallel (on the same port)
allows to use many workers in parallel (for maxing out bandwith of servers with LACP instead of ECMP)
allows to use and track many connection sessions in parallel (for maxing out firewalls)
can also be used as a client for both iperf and iperf3 (autodetecting the target)
can also be used as a iperf3 server
can output results in JSON
has a live graph (ncurses)
uses less CPU ressources on both the client and the server (io_uring, zerocopy, …)
fireperf packages are in sid, and backports for trixie are available at Debian Fast Forward.
Happy bandwidth measuring!
22 Nov 2026 6:19am GMT
Russ Allbery: Review: Whalesong
Review: Whalesong, by Miles Cameron
| Series: | Arcana Imperii #3 |
| Publisher: | Saga Press |
| Copyright: | 2025 |
| Printing: | August 2026 |
| ISBN: | 1-6682-1021-5 |
| Format: | Kindle |
| Pages: | 362 |
Whalesong is a far-future semi-military science fiction novel and the third in the Arana Imperii series, not counting the story collection Beyond the Fringe. It did an adequate job of jogging my memory of previous events, but I kind of wish I had re-read the series before reading this entry.
Artifact Space and Deep Black were closely linked, almost one novel in two volumes. Whalesong is not. There is a frame story featuring Nbaro and Dorcas and an introductory story featuring Nbaro's friend Qaqqaq, but the protagonist for most of the novel is a minor character from the earlier books: Thor Storkel.
After Deep Black, Storkel mustered out of the DHC and purchased the captured New Texas ship Silver Star. An arrangement with Morosini involving secret reserve status let him keep a hidden weapon system. His plan was to become an independent trader, working for himself and going wherever he wanted.
This did not go as smoothly has he planned. Keeping a ship running was expensive in numerous ways that had never previously been his problem, and the end of the Non-War meant a glut of ships and crews trying to do the same thing he was doing. His PTSD and associated paranoia from his time on the Athens didn't help. As Whalesong opens, Storkel is running the Silver Star by himself (a horrible idea), trying to find both cargo he can make money on and crew he can afford to hire.
Also the antigravity is weirdly glitchy, and he's fairly sure the ship's sub-AI doesn't like him.
Whalesong feels like an interlude in the larger series. Although there are important connections to the larger series plot, the advancement of that plot is limited and mostly happens in the background. Instead, this is more of a merchant adventure with some found family vibes, returning to military SF and larger political concerns only late in the book. It felt like Cameron needed to move pieces into place for the next major plot development and decided to use that interlude to tell a smaller character story.
The appeal of this book is therefore going to depend on how much you like the characters. Storkel is an improviser and a tinkerer, the kind of person who sets up an elaborate set of tools and macros and alarms to partly automate his job without letting go of any piece of it. The primary tension in the story is Storkel's paranoia and the increasing evidence that it is justified, that there is something fundamentally wrong with his ship. By himself, Storkel is a little too intense. Thankfully, he gradually accumulates crew over the course of the story, and that settles him down and adds some enjoyable character interactions. Dorcas, when he shows up, is exactly like Dorcas in the previous books; if you liked him before, you'll still like him here.
This is the kind of book that I enjoyed while reading and then promptly forgot most of as soon as I finished it. The details of Storkel's attempt to become an independent trader and how it is slowly hijacked by the series plot is competent, but not more than that (at least for me). The one real complaint that I have is that Nbaro, even when mostly off-camera, continues to be hypercompetent and central to DHC politics in a way that I found a bit unbelievable. Otherwise, the worst that I can say is that this book never grabbed me like Artifact Space did. I happily turned the pages, but I probably won't read it again.
After reading this book, I re-read both Artifact Space and Deep Black and greatly enjoyed both of them. I haven't felt any similar desire to re-read this one.
If you're following the series, there's no reason to skip Whalesong, but I doubt it will be your favorite.
Followed by The Alien's War, which will hopefully have the sort of major plot advancements hinted at by the title. At the time I am writing this review, it is scheduled for publication in September of 2027 in the UK and does not yet have a publishing schedule in the US.
Rating: 7 out of 10
22 Nov 2026 4:10am GMT
21 Nov 2026
Linuxiac
DietPi 10.9 Released with Support for Five New Single-Board Computers
DietPi 10.9 adds support for new Odroid and Orange Pi boards, expands its software catalog, and improves Raspberry Pi management.
21 Nov 2026 11:42pm GMT
KDE Releases Kwi 0.1, Its New GPU-Accelerated Terminal Emulator
KDE's new Kwi terminal emulator reaches version 0.1 with improved tabs, global menu support, interface refinements, and a Flatpak release.
21 Nov 2026 11:26pm GMT
Fedora People
Kevin Fenzi: misc fedora bits: third week of november 2026

The last week was a very busy one, while next week will be hopefully very quiet.
Mass updates/reboots
We managed to get everything updated and rebooted last week, but the outage on thursday didn't go at all nicely. Here's a few of the big things we hit:
I fumbled a ad-hock ansible command horribly. I was meaning to upgrade a few builders from fedora 44 to fedora 45. ansible lets you run ad-hock commands by passing the command and a host pattern to run that command on. You can use wildcards in those patterns as well as groups or hostnames or anything ansible can understand. You need to seperate patterns with a sperator, : and escape wildcards from the shell. I meant to use:
buildvm-a64-0*:!buildvm-a64-01*:!staging
That is, all the buildvm-a64-0* hosts, except not bvmhost-a64-01 or any hosts in the staging group. Instead what I typed:
buildvm-a64-0*:!buildvm-a64-01:*:!staging
That is, all buildvm-a64-0* hosts, not a host called "buildvm-a64-01" which does not exist (we use fqdn everywhere), all hosts, and not staging. Oops. I saw it right after I ran it, and hit control-c, but it already started the dnf command on some hosts. ;( Luckily our rhel hosts all failed because we have some repo files expanding versions and 'epel45' and the like doesn't exist there. Unfortunately it did affect some fedora hosts I didn't plan on. ;(
Due to the above, the wiki, openqa and some copr hosts all got upgraded. The wiki broke, but we were able to back out the upgrade there and get things working again, openqa just needed a playbook run and the copr hosts are planned to upgrade next week anyhow, so things were not too bad.
For some reason some of the builders got into a bad state. I think it may be because it started the upgrade and then something caused it to stop in the middle. This resulted in needing to reinstall a bunch of the buildvm's. Basically all the aarch64, ppc64le, and s390x builders were reinstalled. Luckily thats just a playbook away.
The f45 change moving repo files bit us. In the past we just copy over via ansible new repo files that point to our internal mirror. However, until those are moved over newly install buildvm's try and use the default metalink and were getting mirrors that are completely not reachable by them. Additionally, we disable the openh264 repo by copying over a repo file with just a note in it. Until ansible copies that over however, builders see the enabled openh264 and try and hit the external cisco cdn and of course cannot reach it. Finally our local repo file copies all point to gpg keys that are no longer in the same place. All this is fixable, and I'm kicking myself for not doing fresh installs in staging sooner to catch this sort of thing.
Next, our aarch64 reinstalls were not working right. About 50-75% of the time they would boot, but then not be able to download the initramfs from the network. I still need to try and figure out whats going on here. In the mean time I just brute forced installing them all until they booted correctly and installed/came up.
Finally, the new fedora 45 builders were unable to build epel packages. This was emitting a signature error in buildSRPM tasks. This issue was caused by the Fedora 45 rpm enforcing signatures change. We had tested Fedora and dnf5 handles this just fine, unfortunately, epel builds use dnf-3 and it doesn't handle this. For now at least I switched rpm on all the builders back to the old digests verify only. I'm not sure there's going to be much else to do, although I suppose we could try and move epel to use dnf5 for bootstrapping / srpm builds. It could well change some behavior, but would be a lot more future proof.
Anubis challenges
The anubis valkey backend seems to be working fine from all I can tell. I haven't heard anyone say that they are getting less challenges, but it sure seems like that here.
Thanksgiving next week
Next week is the thanksgiving holidays in the us and I am taking all week off. Of course I will still be around in the Fedora community, but don't expect me to be at meetings or do things that aren't either urgent or not things I enjoy.
I've got a lot of personal projects piled up and I hope to work on some of those, but also just decompress and relax some.
As always, comment on the fediverse: https://fosstodon.org/@nirik/117656544865011334
21 Nov 2026 8:43pm GMT
Planet GNOME
Jussi Pakkanen: Welcome to Soviet Union 2.0, comrade
I have a former coworker who was born in the Soviet Union at a very specific time in history. He was just old enough to see the system from the inside and grasp how it works (or, more specifically, did not work) but young enough that it did not consume him. He got out fairly quickly after the collapse and is nowadays doing computer related work in "the west", as it were. Having seen both sides of the world order he had quite an interesting view on why the Soviet Union eventually crashed and how it ties to modern companies.
Let's assume that you are working in the Soviet Union in a car factory. Your job is to be responsible for all things needed to attach the wheels to the body of the car. In practice this means taking parts from subcontractors (typically other divisions of the same factory) such as break pads and lines, the actual wheels, and all other things and put them together so that the car can roll forward. Seems reasonable enough, right?
In practice it turns out that all parts you get are actually garbage. The wheels are not properly balanced. The inner tube might have a hole in it or be completely missing. The metal in brake pads has been silently changed to a cheaper one removing 50-70% of braking power. The brake lines are too short for installation. To make them work you'd need to cut holes in the car's superstructure. Your screws are too soft to properly function, but fortunately so are your wrenches. The downside is that after tightening one wheel all your tools are shaped like a banana. And so on and so on.
Should you find yourself in such a situation, what should you do about it? In theory the parts you are given are not up to spec. So you could file a complaint about it. But you really can't, because then the problem would be you. You would need to do the extra work of getting the people providing you parts to fix their process (which you can't do). You would need to file the paper work. Your name would be on every one of them. When higher ups get reprimanded for cars not getting finished fast enough to reach the requirements of the current five year plan, they are going to come looking for a scapegoat. You made a ruckus. You stopped the pipeline. You are the problem. You get punished.
But it gets worse. Not only are the people below you not caring and producing garbage work, so are the people above you. At every part of the chain nobody gives a shit, they just take things from below, fiddle with them a bit and then shove them upwards and hope that when things eventually fail, you can deflect the blame on to someone else. If you wish to survive, that is what you must do also. This, according to my coworker, was what eventually brought down the Soviet Union. When all organizational layers of an entire nation gets filled with garbage in - garbage out shovelers, the system loses its capability to function, becomes a zombie, wanders on aimlessly and eventually dies.
He claims to have witnessed aspects of this appearing in the organizational chains of several software companies and that he has tried to warn them about the bad direction things are heading. Usually to deaf ears.
But what about today?
All of that happened years ago. The question is whether any of it still matters in this, our Shining New Era of AI. It most definitely does, more than ever.
Any organization can tolerate a small fraction of employees that don't particularly care about "the job" and are just hanging around putting in the minimal amount of effort they need to to still remain employed. That is just how large organizations work. The problem is ratio, and this is where AI comes in.
One of the main non-technical changes AI has brought about seems to be the wholesale conversion of formerly competent and caring people into garbage in - garbage out shovelers. We see them all around us every day. Like the people who handle all emails sent to them by copypasting the entire email thread to a chatbot, asking "what should I reply to this" and then copypasting the entire thing (including the prompt) back as their reply. Or software developers who used to be smart, knowledgeable and competent but suddenly resemble Alzheimer's patients who reply to merge review questions such as "why did you do this thing here" with "I don't know, Claude told me to" and then merge their code without fixing any of the issues raised.
All of this is exacerbated by all the recent layoffs in the tech sector. No doubt this has been used to rid the company of those pesky troublemakers who dare point out flaws in The Perfect New System. Those who know their history might remember that this was the preferred tactic of Stalin (though, granted, his methods were more extreme). As firing people saves money immediately and only causes problems with a delay, this is seen as a good thing and managers doing it get rewarded.
And this is where we are today. Many formerly good organizations have become or are on their way to becoming lumbering hulks that can no longer properly function and will eventually collapse under the weight of their own incompetence. You can already feel this with the recent outages of Microsoft cloud and other services. Things that should have worked just breaking down randomly without anyone really knowing why was an every day occurrence in the Soviet Union. People just shrugged it off as an unavoidable fact of life. That is the direction we are heading.
The last laugh of Lenin
The latter half of the 20th century was a battle between communism and capitalism. The latter won and having its world view validated went on to an even more extreme end of ultra-capitalism. The ultimate irony is that eventually it reached the exact same end state as communism: an absolute unwavering ideological religion. Which is made all the more amusing by the fact that both of these movements were meant to be fully atheistic.
In communism the country was filled with party leaders who were vocal that communism would lead to "the workers' paradise" which was "within our grasp just over the horizon", we just have to give it some time. The average person, on the other hand, did not believe a word of this nonsense, just pretended to care to get along with their life.
I communism 2.0 we instead have CEOs claiming that AI leads to "freeing humanity from the shackles of work" and that "the cure for cancer is just over the horizon", we just have to give them infinite amounts of money first. The average person does not believe a word of this nonsense, just pretend to care to get along with their life.
At least the Soviet Union had the banging Red Army Choir. All noises the techbro CEOs seem to be capable of producing seem to consist of whingy stuttering and vocal fry.
21 Nov 2026 6:21pm GMT
Planet Debian
Andrew Cater: Back in Cambridge - this time for media testing / media release 20261121
I never did quite finish the blog posts for mini-DebConf Cambridge at ARM - sorry, but life got in the way. Videos are now available in the Debian video archives.
Back in Cambridge for release of Debian 13.8 - testing is going well. A couple of new bugs - speech install doesn't *depend* on a working screen but it surely does help as a sighted user :)
Six of us here, including Richard who is new to the process and pham who has helped with ARM v7 remotely.
All good - and glad to be here.
21 Nov 2026 3:59pm GMT
Fedora People
Guillaume Kulakowski: Migration de Gmail vers plMail : reprendre le contrôle sur mes e-mails
21 Nov 2026 1:47pm GMT
Planet GNOME
Ignacio Casal Quinteiro: Mundi
Apart from Teclas, few months ago I started another small application called Mundi, Mundi is a geography learning application for GNOME. It all started from an assignment from the teacher of my kid where they had to use the following web page: https://mapasenriquealonso.com/
The web page is actually quite nice but it pissed me off that it had publicity. So I said to myself, what if I make a clone but better for GNOME? Since then I started adding maps and different exercises and I think the application reached to a pretty good state.
 When you start the application you get to select the country or a region of the world you want to learn.
 The country may have different exercises.
 Once you select the exercise you want you can either select the different regions to learn what they are or you can click on "Start Quiz".
 The quiz will start asking you the different regions and you have to click on the right one. It will account for the timing.
 Once you are done it will give you the result and you can save your name.
I've been playing it with my family and colleagues and it is really funny. It is also interesting to discover how bad you are at geography when you start playing with it!
Go fetch it in Flathub or Snapcraft and enjoy!
21 Nov 2026 12:54pm GMT
Planet KDE | English
KMcpClientInspector 0.3 released: a KDE tool to inspect and debug MCP servers
I'm happy to announce the release of KMcpClientInspector 0.3, a KDE application to inspect and debug servers implementing the Model Context Protocol (MCP).
MCP is an open protocol that lets applications expose tools, prompts and resources to clients such as AI assistants, using JSON-RPC messages. When you write an MCP server, you quickly need a way to see what your server actually announces, to call its tools by hand and to look at every message exchanged. That is what KMcpClientInspector does: it acts as an MCP client, connects to your server, lets you send requests to it and shows you everything that goes over the wire.
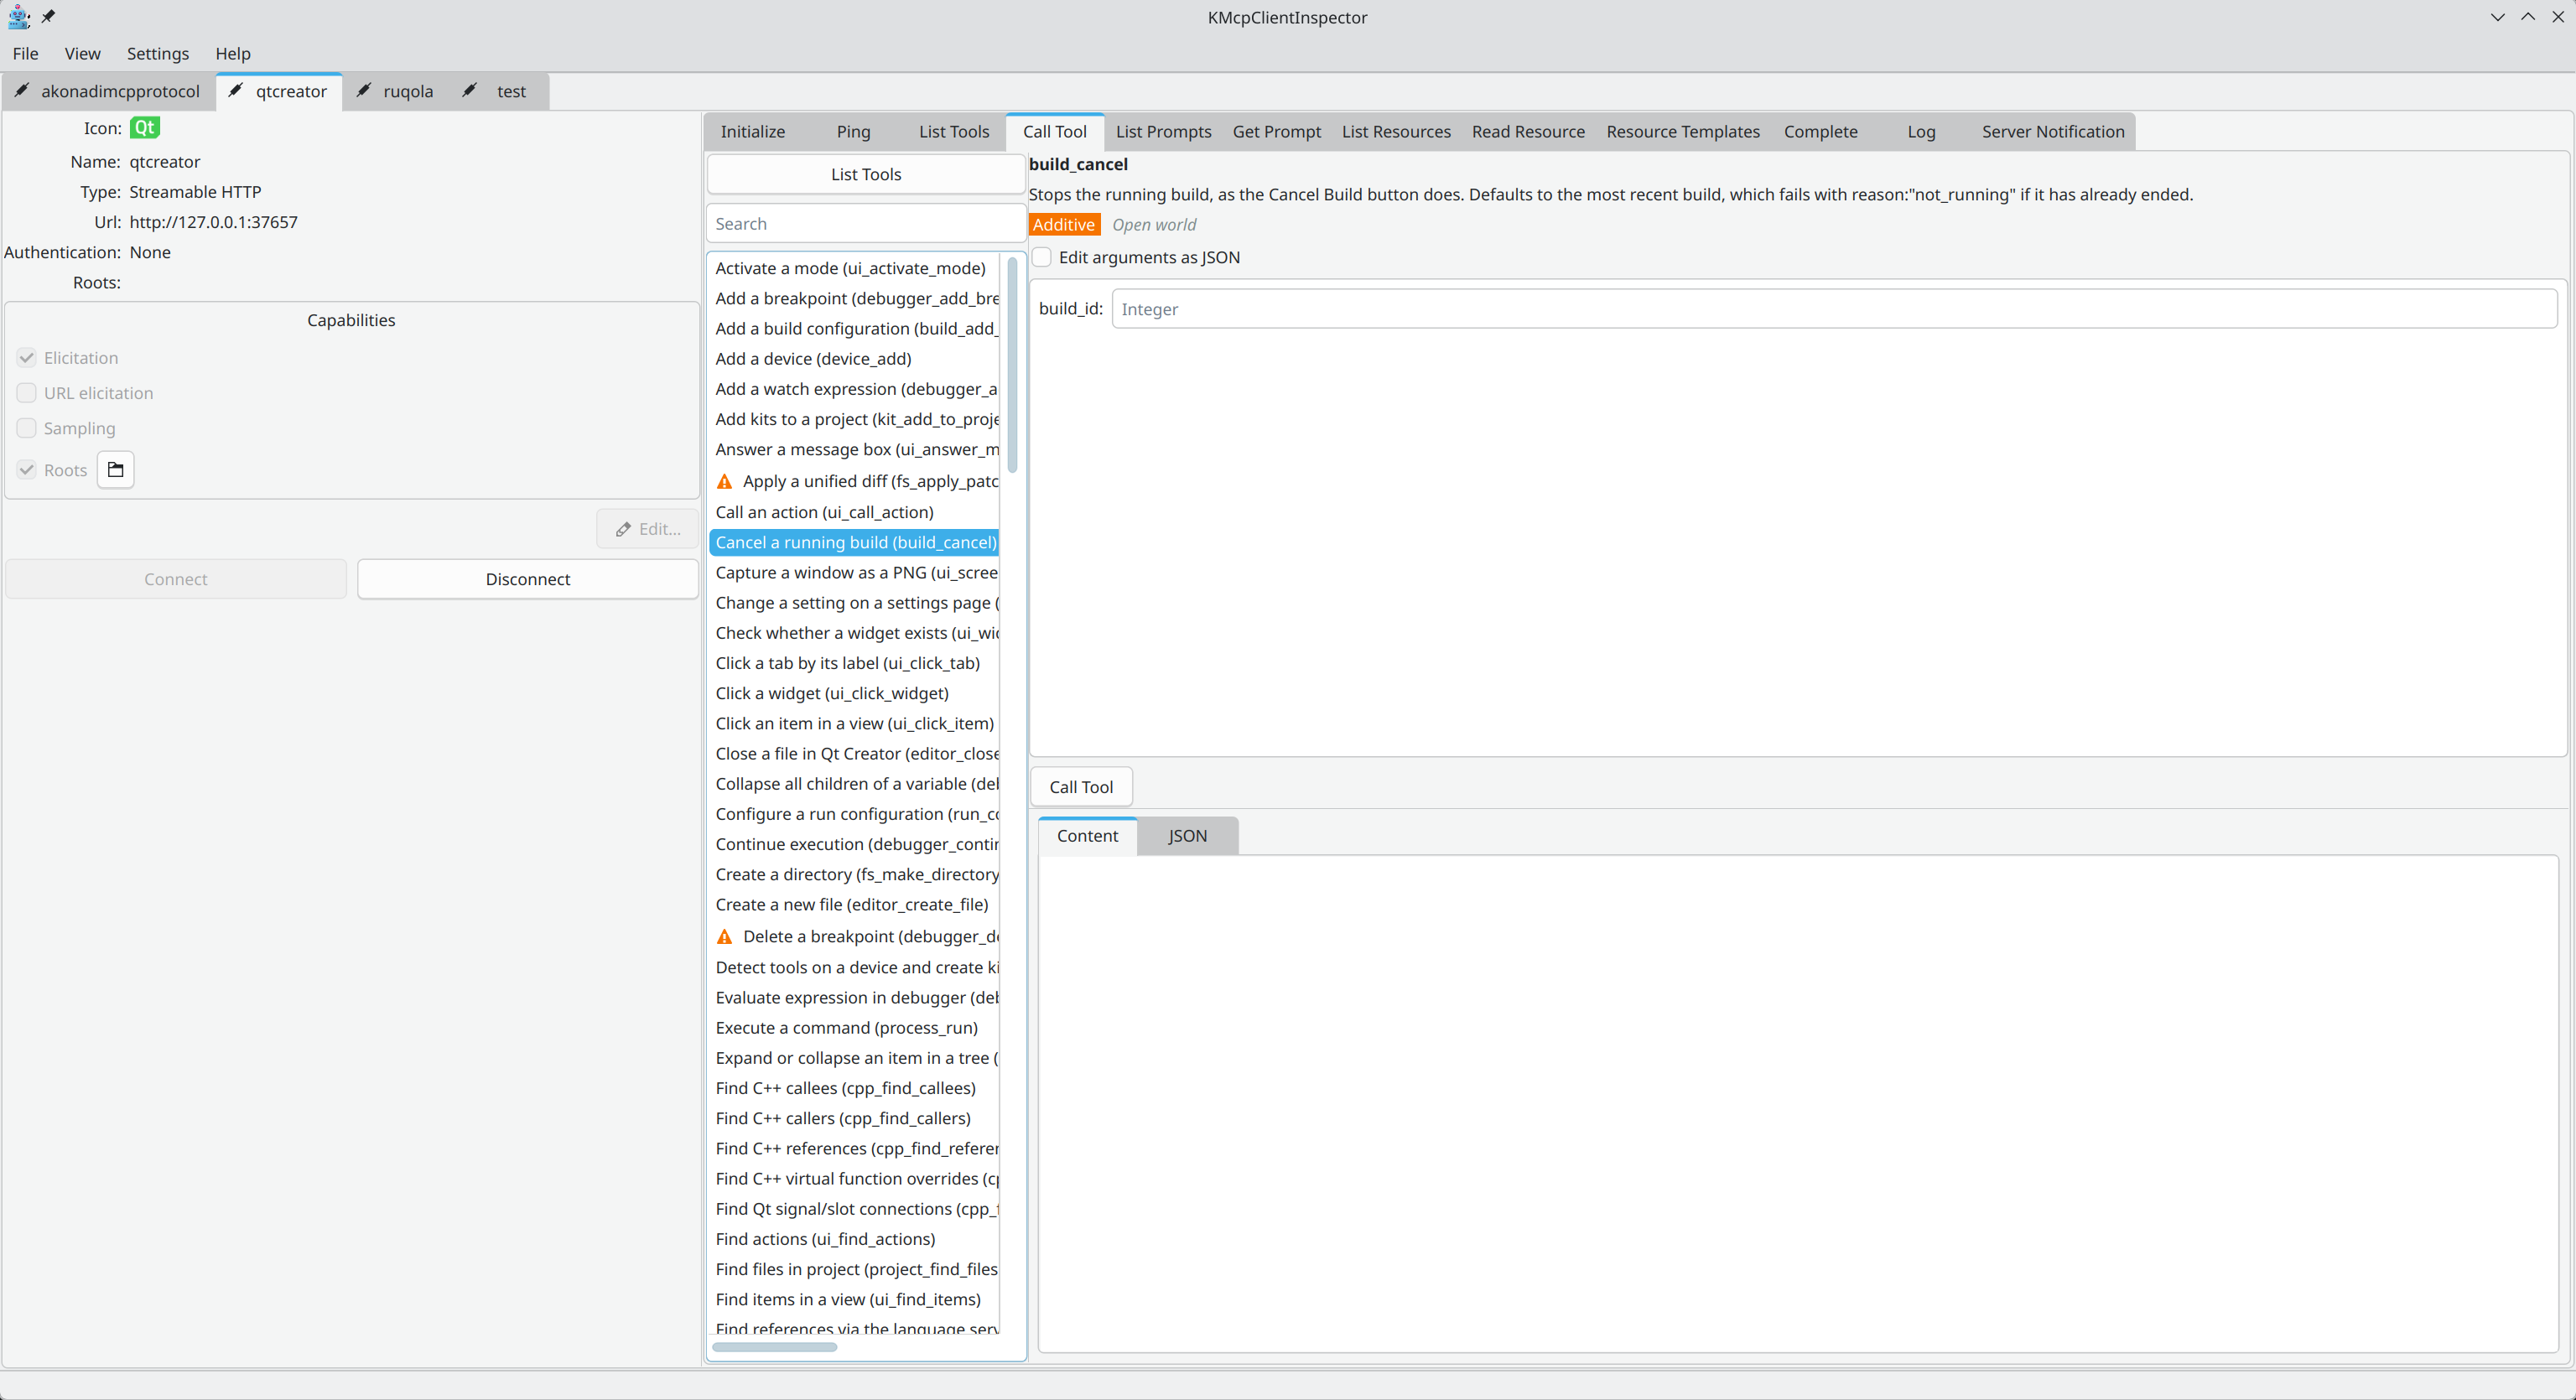
Managing your servers
- Keep a list of MCP servers, and add, edit, remove, enable or disable them. Each enabled server gets its own tab.
- Two kinds of servers are supported: local servers, started as a process with a command, arguments and environment variables, and remote servers, reached through a URL, with custom HTTP headers and optional bearer-token authentication.
- Choose which client capabilities are announced during initialization: elicitation, URL elicitation, sampling and roots. Global defaults are set in the configuration dialog and can be overridden per server.
- Define the roots (directories or files) exposed to a server, globally or per server. If roots change while the server is connected, the server is notified.
- Configure a request timeout.
Talking to a server
Once connected, the server tab shows one tab per kind of request. Tabs for tools, prompts and resources only appear when the server announces the matching capability.
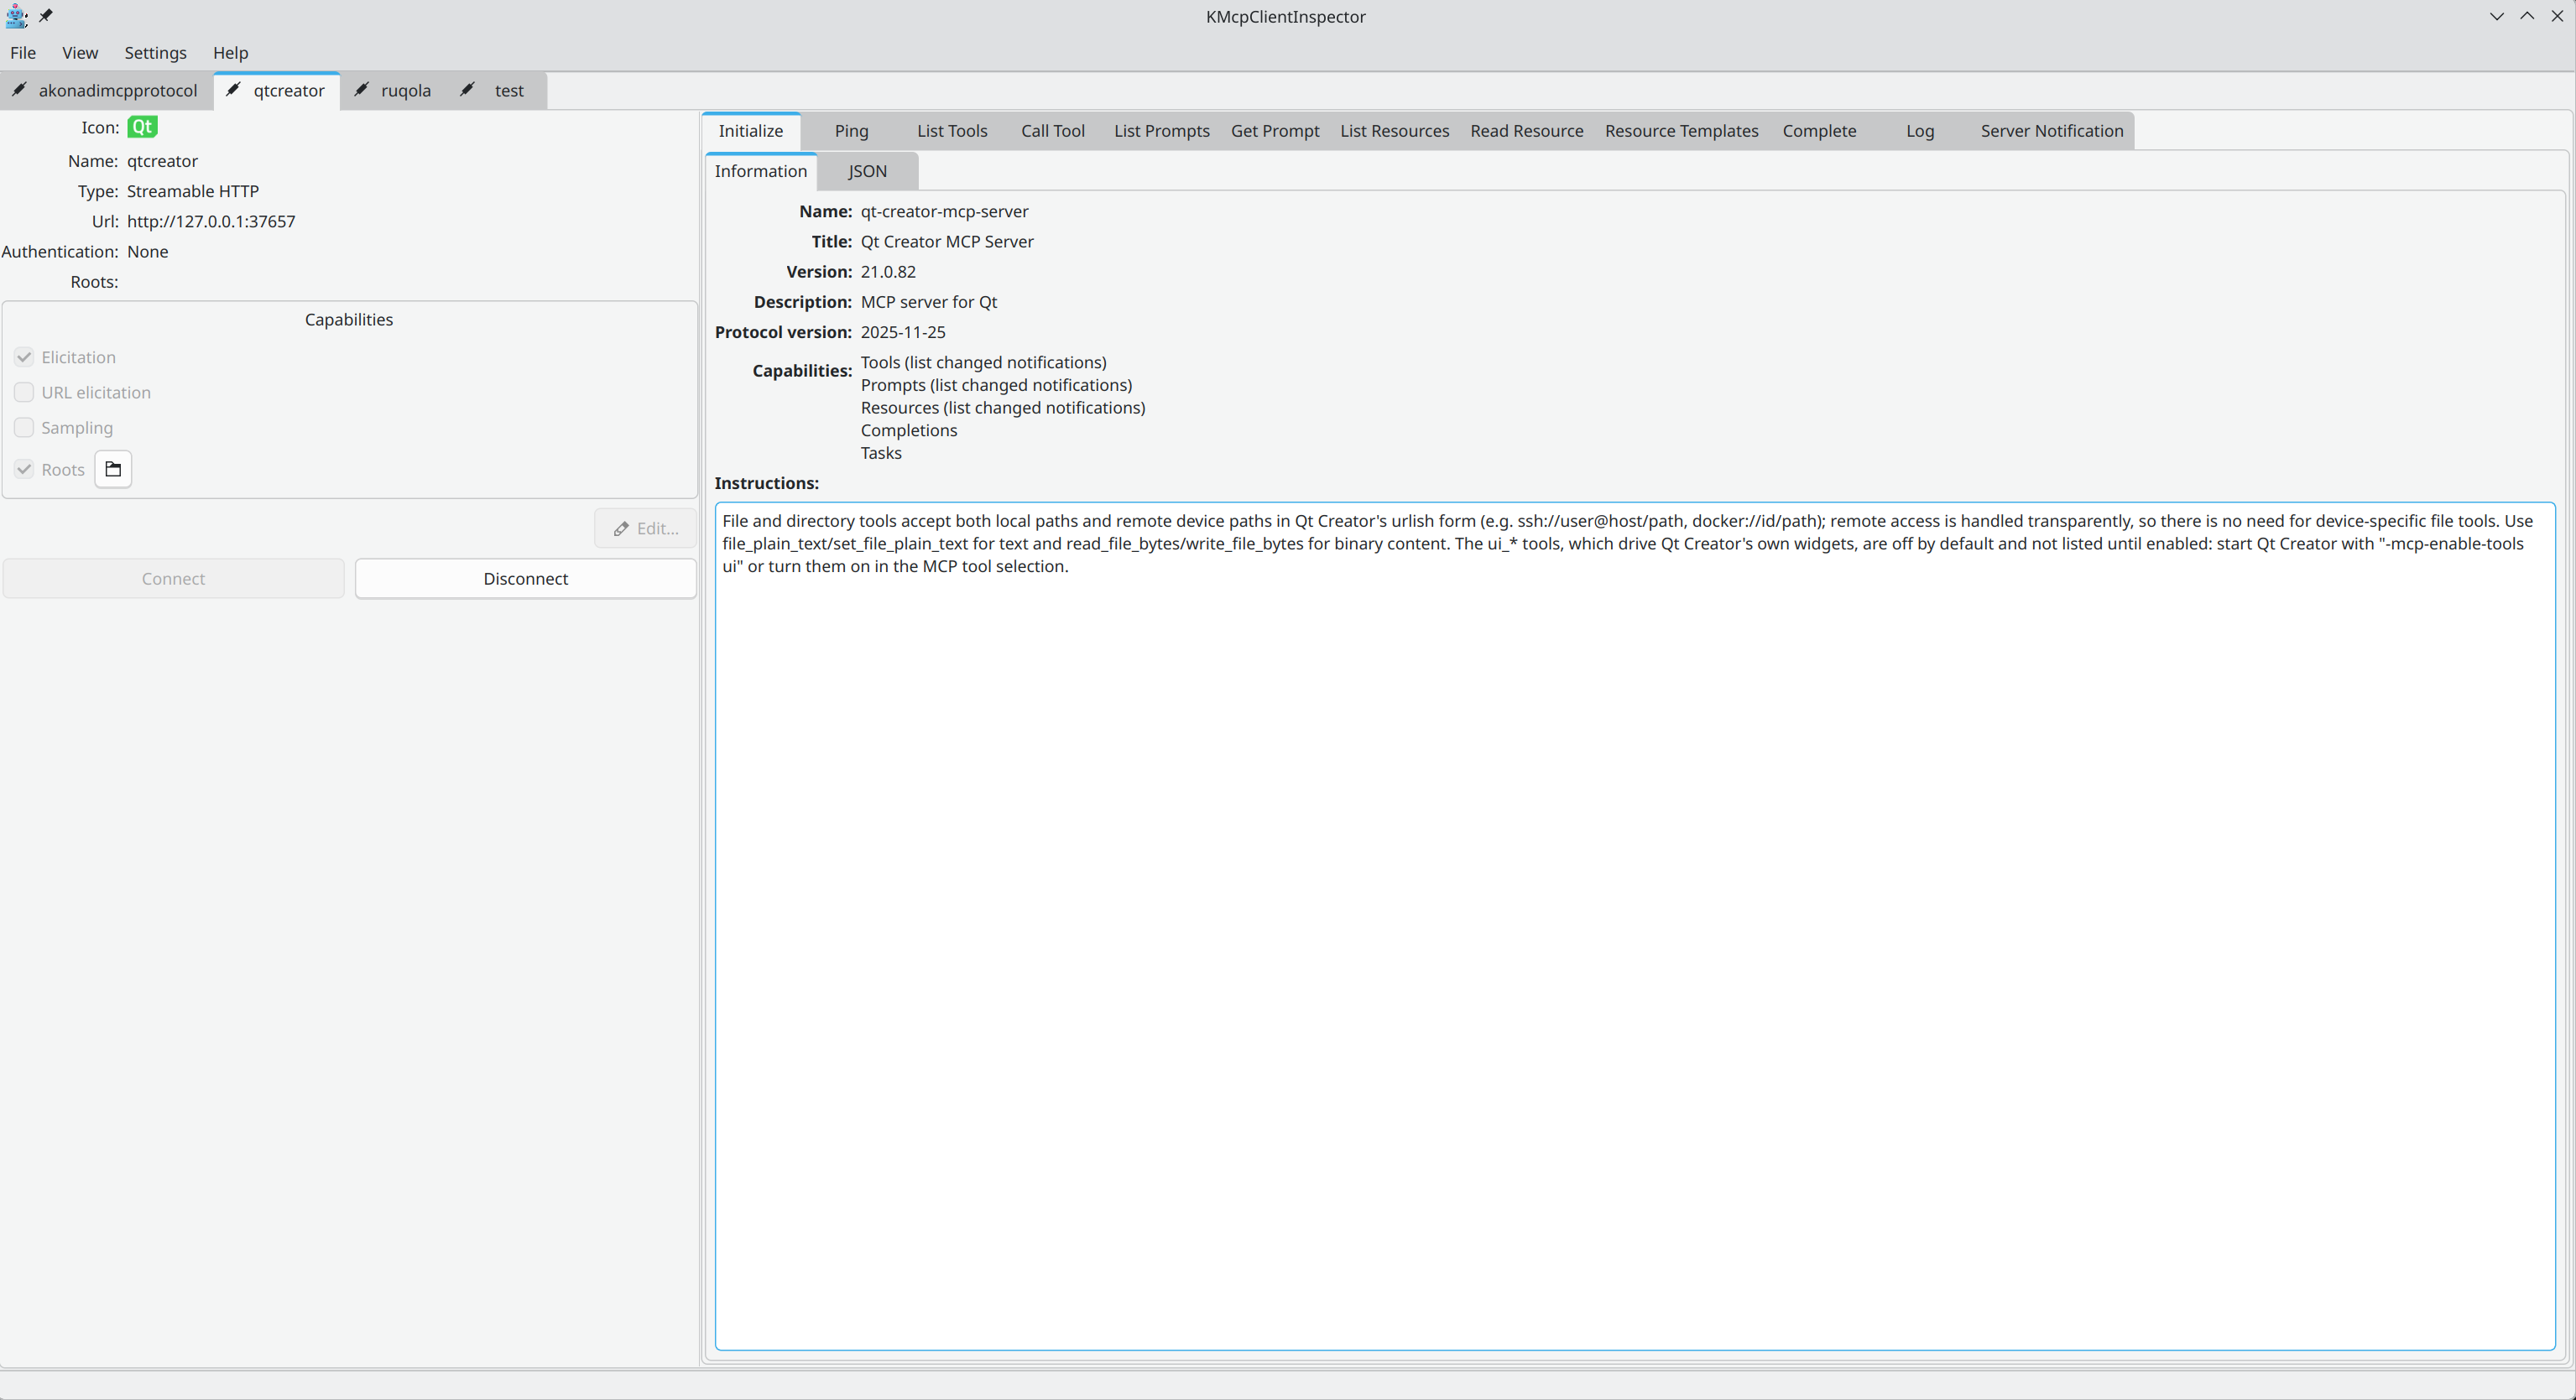
- Initialize: the server's answer to the initialization handshake (name, version, protocol version, capabilities and instructions), as a readable summary and as raw JSON.
- Ping: check that the server is still answering.
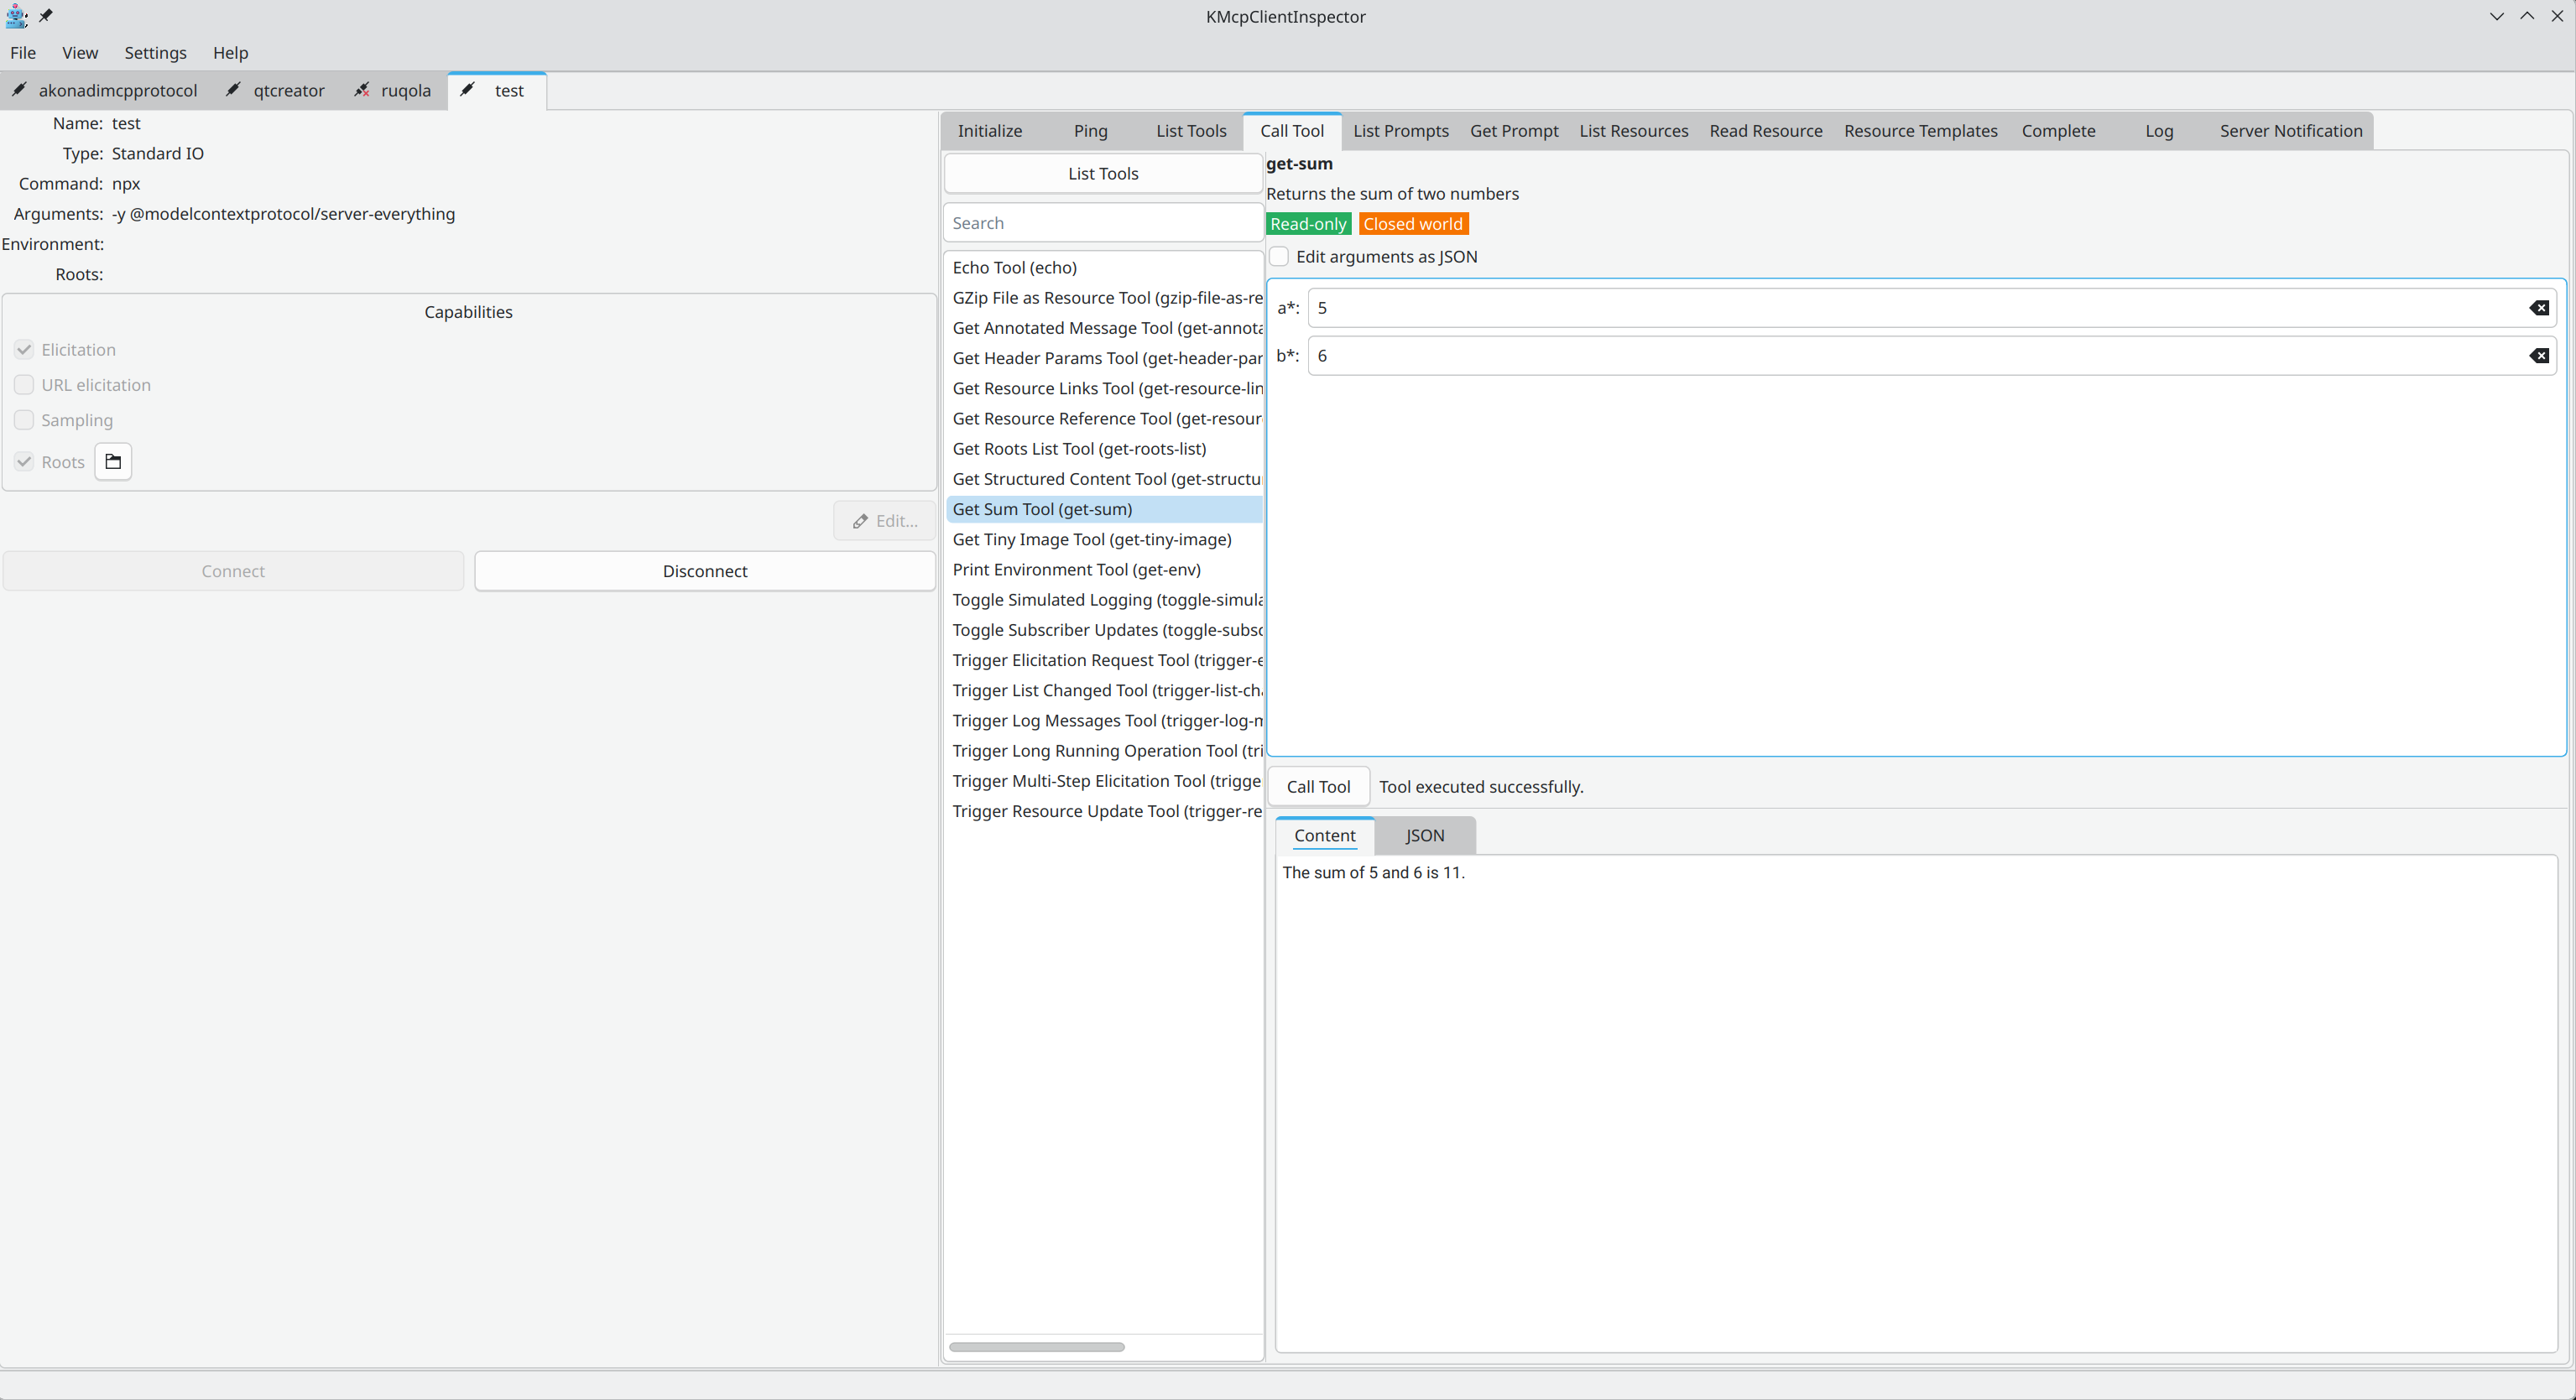
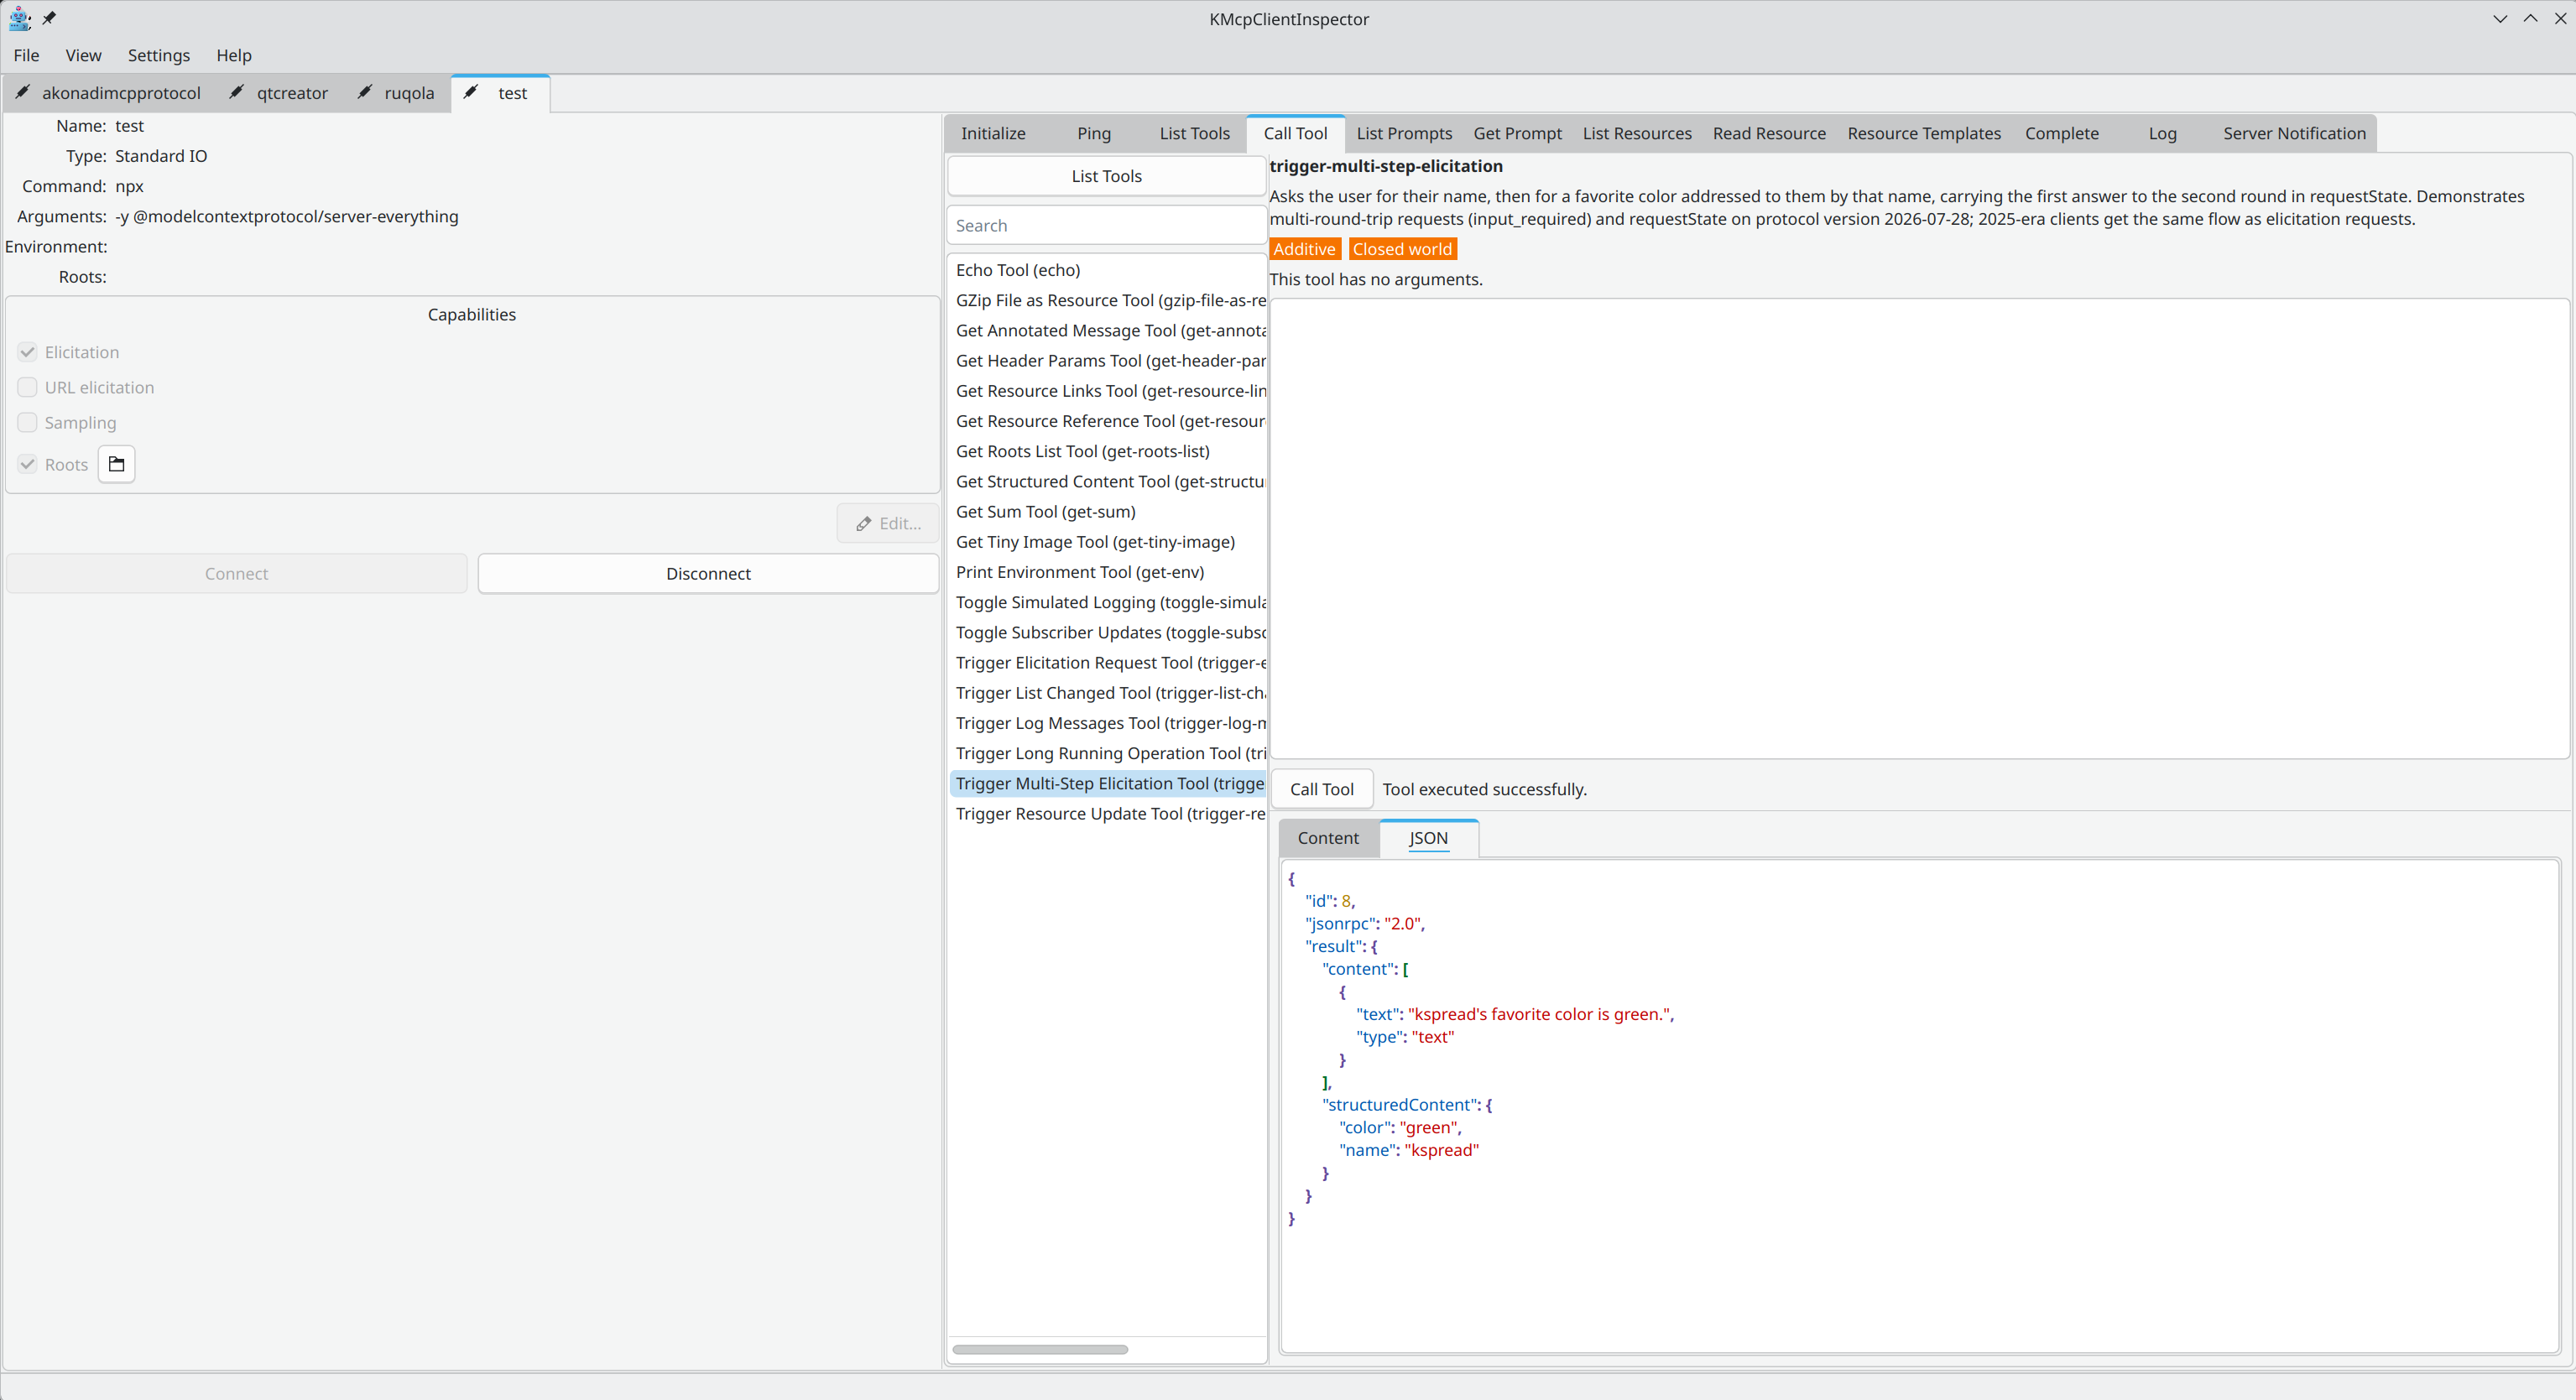
- Tools: list the tools and call them. Each argument gets a field matching its type (text, integer, number, boolean or JSON), or you can write all arguments as one JSON object. Required arguments and types are checked before the request is sent. Tool annotations are shown as badges (read-only, destructive, idempotent, open world…), and destructive tools get a warning icon. During a call, progress notifications are shown in a progress bar, and a long call can be cancelled. The result is shown both as readable content (text, images, audio, resource links, embedded resources, structured content) and as raw JSON.
- Prompts: list the prompts, fill in their arguments and get them. The resulting messages are shown with their role (user or assistant).
- Resources: list resources and resource templates, read a resource by selecting it or typing its URI, and subscribe to it so it is read again automatically when it changes.
- Completion: ask the server to complete an argument value for a prompt or a resource template.
Seeing what goes over the wire
- The Log tab lists every JSON-RPC message exchanged with the server, with its identifier, method, time, duration and direction (sent or received). You can search it, filter by direction, and select a message to see its JSON.
- The Server Notification tab shows the log messages sent by the server, with time, level, logger and message. You can ask the server to change its logging level (
logging/setLevel) and hide messages below a chosen level. - Desktop notifications tell you when a server's tools, prompts or resources change, and when an error happens.
Answering requests from the server
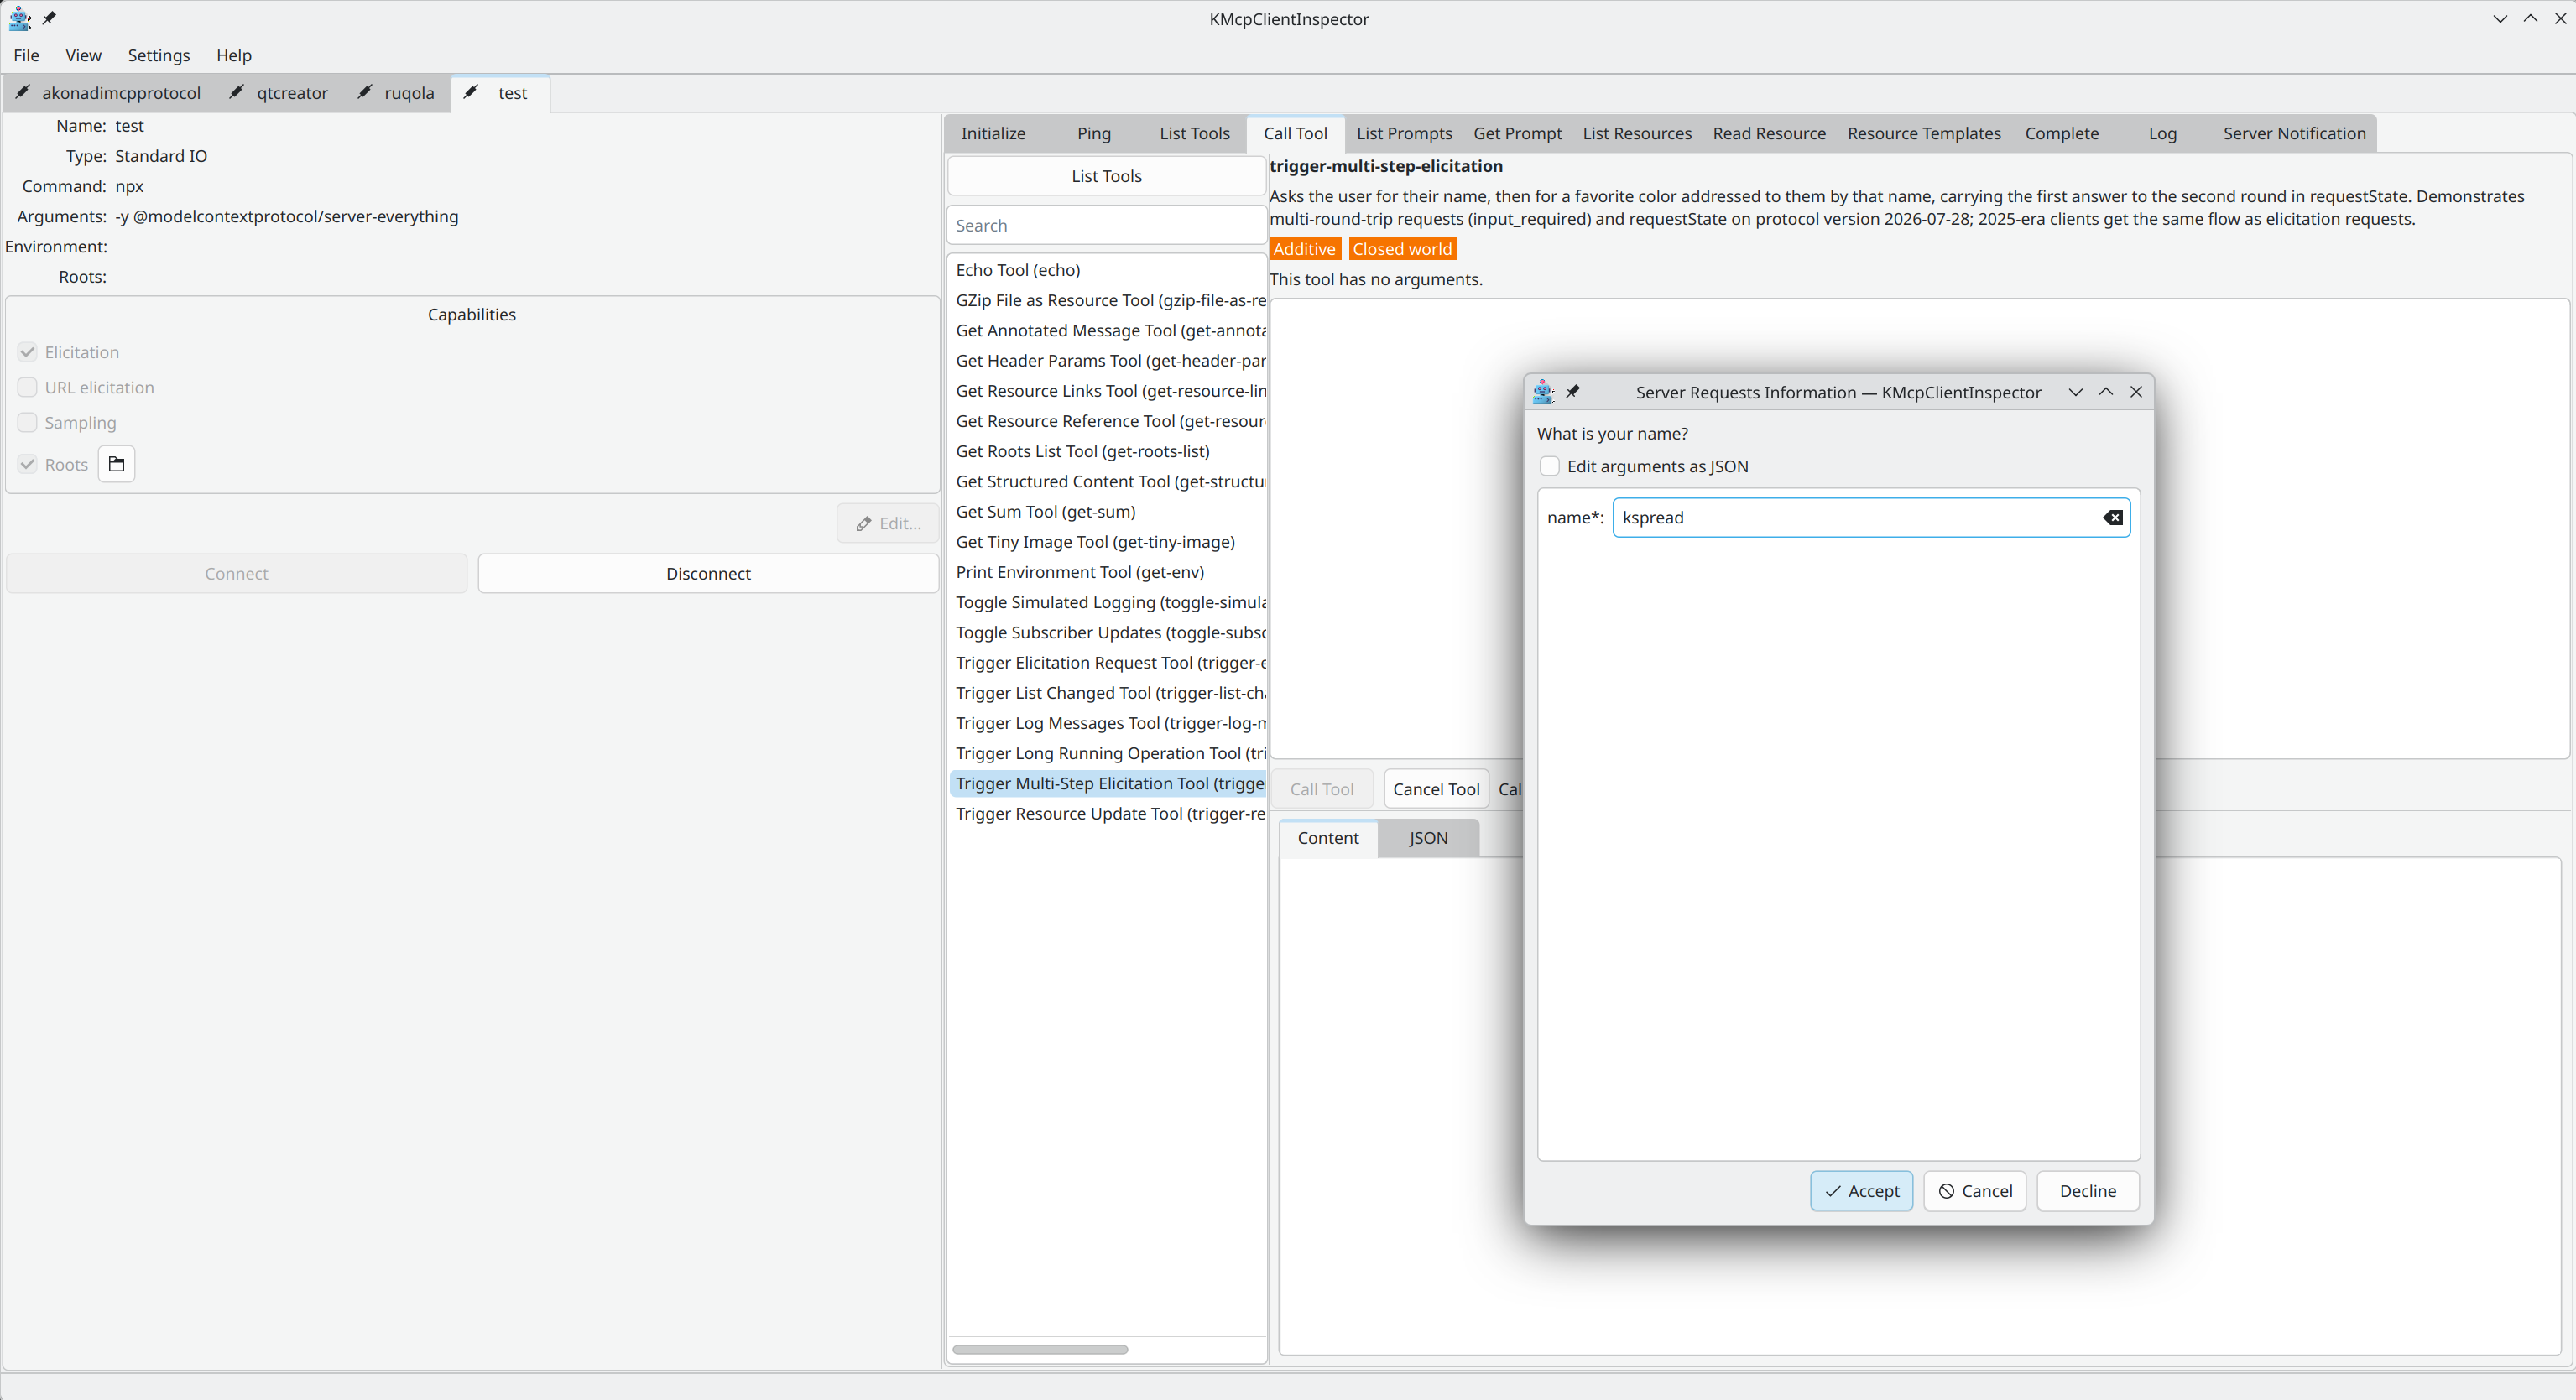
MCP is not one-way: a server can also send requests to the client. KMcpClientInspector shows a dialog for each of them, so you can test these flows by hand:
- Elicitation: the server asks the user for information. A field is shown for each requested value, and you can accept, decline or cancel.
- URL elicitation: the server asks the user to complete an interaction in a web browser. The domain and full URL are shown, and the page is only opened if you click Open.
- Sampling: the server asks the client to generate a message with a language model. You see the request and write the answer yourself, so you can test your server without plugging in a real model.
- Roots: answered automatically with the roots configured for the server.
Getting it
KMcpClientInspector 0.3 depends on KTextAddons 2.3.0, which provides the MCP protocol implementation it is built on. It also needs Qt 6.10 and KDE Frameworks 6.
- Tarball: kmcpclientinspector-0.3.0
- Source code: invent.kde.org/sdk/kmcpclientinspector
- Bug reports: bugs.kde.org
Feedback, bug reports and contributions are welcome. If you are writing an MCP server, give it a try and tell me what is missing!
21 Nov 2026 8:32am GMT
OMG! Ubuntu
Kessler is an open-source, zine-style music player (with iPod support)
 kessler is a new, open-source music player with a zine-style design, dithered album artwork and iPod support. It was also made with AI coding tools. Kessler's developer, Felix, an artist and designer from Germany, told me this upfront in an email, saying "like everyone on the internet right now i started making an application with the help of a coding assistant". He inherited an old iPod and found modern music player support for it was lacking I get a lot of software pitches now (more than at any point in my 16 years of blogging). AI agents don't sleep and […]
You're reading Kessler is an open-source, zine-style music player (with iPod support), a blog post from OMG! Ubuntu. Do not reproduce elsewhere without permission.
21 Nov 2026 5:30am GMT
Planet KDE | English
This Week in Plasma: CJK Text Input and Performance
Welcome to a new issue of This Week in Plasma!
Notable new features
Plasma 6.9
Plasma's on-screen keyboard now includes various text composers for Chinese, Japanese, and Korean. (Devin Lin, plasma-keyboard MR #113)

You can now control the rate at which the text insertion point blinks throughout most apps, or make it stop blinking entirely. (Alexander Berg, KDE Bugzilla #343635)
The Kicker Application Menu widget now supports showing a text label alongside the icon, just like Kickoff does. (小太, KDE Bugzilla #456252)
Notable UI improvements
Plasma 6.8.4
KRunner's window is no longer so flickery and jumpy as it grows and shrinks. (Victor Prudniy, KDE Bugzilla #513950)
The Networks widget no longer offers you the opportunity to connect to a Wi-Fi network via a QR code on systems with no Wi-Fi adapters. (Niccolò Venerandi, KDE Bugzilla #517252)
It's now possible to play or pause media on the lock screen using a device that sends explicit "play" or "pause" signals, not just the combined "play/pause" toggle. (Niccolò Venerandi, KDE Bugzilla #500388)
The Kickoff Application Launcher widget now displays more standard behavior for the highlighting applied to its grid items after you right-click them. (Niccolò Venerandi, KDE Bugzilla #505920)
Plasma 6.9
On a multi-screen setup, right-clicking the desktop and choosing "Display Configuration" now opens the relevant System Settings page showing the screen with the desktop you right-clicked. (Kai Uwe Broulik and Joshua Goins, kscreen MR #522)
System Settings' Accessibility page now includes convenient links to pages where you can change the display scale or font sizes. (Alexander Berg, KDE Bugzilla #462501)
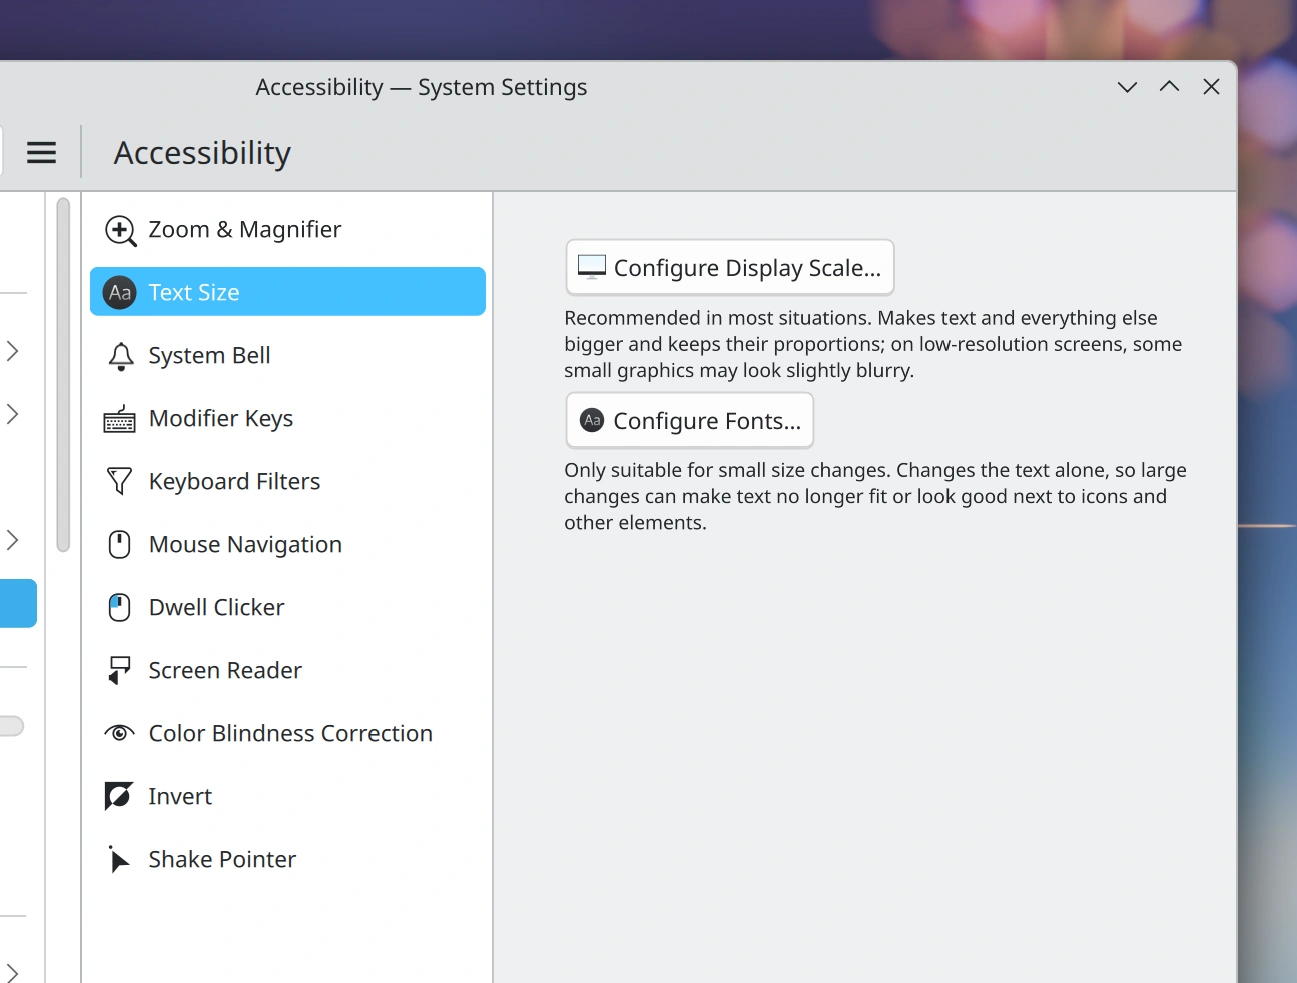
System Settings' Font Management page has been transformed into a standalone app. It seemed to fit better that way, and this reduces the clutter in System Settings. (Tobias Fella, plasma-workspace MR #7395)
The indicator highlight for panel widgets with a popup open is now sized in the same way that it is for System Tray widgets, improving consistency. (Niccolò Venerandi, KDE Bugzilla #522844)
Synchronizing your Plasma desktop settings to Plasma Login Manager now includes your Night Light settings, too. (Anton Birkel, KDE Bugzilla #521408)
Notable bug fixes
Plasma 6.6.8
Deleting a panel now deletes any global shortcuts that had been assigned to its widgets, preventing them from forever cluttering up System Settings' Shortcuts page and your Plasma config file. (Niccolò Venerandi, KDE Bugzilla #410903)
The Web Browser widget's custom home page setting now works. (Christoph Wolk, kdeplasma-addons MR #1286)
Fixed a bug that prevented connecting to an OpenConnect VPN with authentication group names in Chinese. (Zheng Ender, plasma-nm MR #698)
Plasma 6.8.4
Fixed a recent regression that made KWin crash at login on certain systems. (Xaver Hugl, KDE Bugzilla #528824)
Fixed a case where KWin could crash after a GPU reset. (Xaver Hugl, kwin MR #10349)
Fixed a case where Plasma could crash when you unplugged a removable USB disk very quickly after telling Plasma to safely eject it. (Niccolò Venerandi, KDE Bugzilla #526537)
Fixed a case where Plasma could crash when you removed a Weather Report widget. (Bohdan Onofriichuk, KDE Bugzilla #528997)
Fixed a case where notifications about your battery being critically low could pile up after waking the computer. (Niccolò Venerandi, KDE Bugzilla #520491)
When Plasma is woken up due to certain kinds of background network and Bluetooth activity, now it goes to sleep again afterwards. (Michael Auer, powerdevil MR #706)
Fixed a case where Discover would fail to install local package files (e.g. .rpm or .deb files) when the PackageKit daemon wasn't already running. (Taras Oleksyn, KDE Bugzilla #528037)
The "Horizontal Bars" display style for System Monitor sensors now looks correct when using a left-to-right language like Arabic or Hebrew. (Niccolò Venerandi, KDE Bugzilla #523137)
Pressing keys on your keyboard's numberpad no longer activates KRunner when they aren't supposed to. (Alan Witkowski, KDE Bugzilla #528338)
Deleting a super duper thick panel no longer visually breaks Plasma's edit mode. (Niccolò Venerandi, KDE Bugzilla #525374)
Plasma 6.9
Plasma no longer freezes if you try to add more widgets to the desktop when it's already completely full. (Marco Martin, KDE Bugzilla #528989)
Support for auto-mounting only specific disks now works reliably, by storing the ID of each disk in a way that's persistent over time. (Tobias Fella, KDE Bugzilla #458349)
The Task Manager now shows the icons of web apps more reliably. (Nicolas Fella, KDE Bugzilla #447845)
Fixed an issue that made the labels of items on the desktop blurry at certain screen scale factors. (Ramil Nurmanov and Anton Birkel, libplasma MR #1606)
Spectacle's "Use last-used capture mode" setting now works again. (Mohanraj Velayutham, KDE Bugzilla #508488)
The keyboard shortcut used to show and hide Yakuake now works on Wayland when using the app's "Use Open/Retract action to focus window" setting. (Albert Vaca Cintora, KDE Bugzilla #402634)
Notable in performance & technical
Plasma 6.6.8
Fixed a memory leak in System Settings' Display Configuration page. (Stefan Zabka, kscreen MR #533)
Plasma 6.9
Spectacle is now even faster to take screenshots. And not just Spectacle, but all software using KWin's screenshot plugin. You can read more about it on Kai's blog. (Vlad Zahorodnii and Kai Uwe Broulik, kwin MR #10307, spectacle MR #632)
KWin now uses overlay planes for NVIDIA GPUs using driver version 615.78.08 or later, which should reduce energy usage. (Jakub Okoński, kwin MR #10398)
When a third-party plugin is making KWin crash repeatedly, now it stops after two crashes and unloads those plugins. (Alexander Berg, kwin MR #10283)
KWin now works around a kernel issue that can cause visual stutters when opening and closing windows on some systems. (Vlad Zahorodnii, KDE Bugzilla #523813)
Plasma no longer invokes its animated image support for images capable of animation but containing only a single frame, which saves some resources. (Viesturs Zarins, plasma-workspace MR #7418)
Plasma Login Manager no longer shows sessions that are supposed to be hidden. (Alexander Berg, KDE Bugzilla #525584)
KWin's screenshot and color picker plugins have been ported away from direct OpenGL usage, paving the way for a Vulkan future. (Xaver Hugl, kwin MR #10355 and kwin MR #10393)
Plasma Desktop's session files now live in the plasma-desktop repository/package, so they won't be inappropriately shown to people using Plasma Mobile. (Peder Bergan, plasma-workspace work item #173)
Frameworks 6.33
KDE's icon loader now makes use of the GTK icon cache if it's present, which slightly speeds up icon loading in all KDE software, and all Qt-based software run in Plasma. (Chinmoy Pradhan, kiconthemes MR #222)
How you can help
KDE has become important in the world, and your time and contributions have helped us get there. As we grow, we need your support to keep KDE sustainable.
One of the best ways right now is to donate to KDE's fundraiser. We're halfway to our 2026 goal, and I think we can get all the way there! Your donations will help support the two open positions, as well as hopefully more in the future. So consider making a donation today!
Beyond that, you can help KDE by directly getting involved in any other projects. Donating time can actually be more impactful than donating money. Each contributor makes a huge difference in KDE - you are not a number or a cog in a machine! You don't have to be a programmer, either; many other opportunities exist.
You can also help out by making a donation! This helps cover operational costs, salaries, travel expenses for contributors, and in general just keeps KDE bringing Free Software to the world.
To get a new Plasma feature or a bug fix mentioned here
Push a commit to the relevant merge request on invent.kde.org.
21 Nov 2026 12:00am GMT
20 Nov 2026
Fedora People
Filipe Rosset: dkms vs r8168-8.057.00 issues

r8168 Makefile does not honor the KVER variable, there some issues there:
BASEDIR := /lib/modules/$(shell uname -r)
KERNELDIR ?= $(BASEDIR)/build
KVER = $(shell uname -r)
as KERNELDIR is using BASEDIR, and BASEDIR does use "uname -r" hardcoded, our workaround here is to pass a dynamic value for KERNELDIR, the precedence for our value do the trick.
rosset@xeon:# diff -ruN /usr/src/r8168-8.057.00-1/dkms.conf.bak /usr/src/r8168-8.057.00-1/dkms.conf

--- /usr/src/r8168-8.057.00-1/dkms.conf.bak 2026-09-10 21:00:00.000000000 -0300

+++ /usr/src/r8168-8.057.00-1/dkms.conf 2026-11-20 20:36:00.398148359 -0300

@@ -1,6 +1,6 @@

PACKAGE_NAME=r8168

PACKAGE_VERSION=8.057.00-1

-MAKE[0]="'make' -j$(nproc) KVER=${kernelver}"

+MAKE[0]="'make' -j$(nproc) KVER=${kernelver} KERNELDIR=/lib/modules/${kernelver}/build"

BUILT_MODULE_NAME[0]=r8168

DEST_MODULE_LOCATION[0]=/kernel/drivers/net

AUTOINSTALL="YES"

rosset@xeon:#
rosset@xeon:~# sudo dkms status
for K in /lib/modules/; do
K=${K##/}
echo "===== $K ====="
modinfo -k "$K" r8168 2>/dev/null |
grep -E '^(filename|rhelversion|vermagic):'
done
gpu-unlock/2.0.0, 6.12.0-208.112.5.3.el10uek.x86_64, x86_64: installed
gpu-unlock/2.0.0, 6.12.0-211.74.1.el10_2.x86_64, x86_64: installed
gpu-unlock/2.0.0, 6.12.0-264.14.1.el10_3.x86_64, x86_64: installed
nvidia/620.70.06, 6.12.0-208.112.5.3.el10uek.x86_64, x86_64: installed
nvidia/620.70.06, 6.12.0-211.74.1.el10_2.x86_64, x86_64: installed
nvidia/620.70.06, 6.12.0-264.14.1.el10_3.x86_64, x86_64: installed
r8168/8.057.00-1, 6.12.0-208.112.5.3.el10uek.x86_64, x86_64: installed
r8168/8.057.00-1, 6.12.0-211.74.1.el10_2.x86_64, x86_64: installed
r8168/8.057.00-1, 6.12.0-264.14.1.el10_3.x86_64, x86_64: installed
===== 6.12.0-207.111.5.3.el10uek.x86_64 =====
===== 6.12.0-207.111.5.4.el10uek.x86_64 =====
===== 6.12.0-207.111.5.5.el10uek.x86_64 =====
===== 6.12.0-207.111.5.6.el10uek.x86_64 =====
===== 6.12.0-208.112.5.1.el10uek.x86_64 =====
===== 6.12.0-208.112.5.2.el10uek.x86_64 =====
===== 6.12.0-208.112.5.3.el10uek.x86_64 =====
filename: /lib/modules/6.12.0-208.112.5.3.el10uek.x86_64/extra/r8168.ko.xz
vermagic: 6.12.0-208.112.5.3.el10uek.x86_64 SMP preempt mod_unload modversions
===== 6.12.0-211.62.1.el10_2.x86_64 =====
===== 6.12.0-211.65.1.el10_2.x86_64 =====
===== 6.12.0-211.66.1.el10_2.x86_64 =====
===== 6.12.0-211.68.1.el10_2.x86_64 =====
===== 6.12.0-211.69.1.el10_2.x86_64 =====
===== 6.12.0-211.72.1.el10_2.x86_64 =====
===== 6.12.0-211.73.1.el10_2.x86_64 =====
===== 6.12.0-211.74.1.el10_2.x86_64 =====
filename: /lib/modules/6.12.0-211.74.1.el10_2.x86_64/extra/r8168.ko.xz
rhelversion: 10.2
vermagic: 6.12.0-211.73.1.el10_2.x86_64 SMP preempt mod_unload modversions
===== 6.12.0-264.14.1.el10_3.x86_64 =====
filename: /lib/modules/6.12.0-264.14.1.el10_3.x86_64/extra/r8168.ko.xz
rhelversion: 10.3
vermagic: 6.12.0-264.14.1.el10_3.x86_64 SMP preempt mod_unload modversions
20 Nov 2026 11:58pm GMT
Planet GNOME
Miguel de Icaza: What Maintaining SwiftTerm Taught Me About AI Contributions
If you maintain an open-source project right now, your pull request queue probably looks very different than it did two years ago.
I maintain SwiftTerm, an open-source terminal emulator library that is now seven years old. Today, I estimate that about 80% of the pull requests I receive involve AI in some capacity. Looking back, though, this didn't happen all at once-it came in distinct waves.
Disclosure: as a Mexican national that routinely writes tedious and typo-ridden English blog posts, I had Antigravity fix my writing and repeated tedious and repetitive points (as my wife often points out).
Wave One: Vibe-Coded Band-Aids and Fork Experiments
Before people even started opening AI-assisted pull requests on my repository, I would browse the GitHub network graph just to see what forks were popping up and what problems users were struggling with. Early on, what I found was a lot of "vibe coding"-folks patching around issues in ways that were fundamentally wrong, slapping surface-level band-aids over deeper terminal state bugs. I would fix or implement the feature, despite the fact that the user had not submitted the fix - for the sake of helping all my users.
In one fork I stumbled across, someone had clearly unleashed an autonomous agent to try to fix all of my open issues in rapid fire. Luckily, they never actually submitted those PRs-they were likely just experimenting-and it was only my nosy self browsing the network graph that spotted it. Still, looking through those commits confirmed the early reality: the fixes weren't worth merging. They solved surface symptoms without understanding the system.
The Rise of the Promptsplainer
Alongside those early waves came a new open-source archetype-one that many communities had to deal with: the Promptsplainer.
Some folks are really eager to particiapte in improving a project and LLMs have opened new doors, but they lack some basic etiquette.
A Promptsplainer is someone who asks an LLM a question, gets back a confident-sounding explanation or a sprawling patch, and suddenly believes they can override decades of hard-won domain expertise. They don't actually understand the underlying quirks, race conditions, or protocol edge cases of the codebase they are touching. When a veteran maintainer points out a flaw, the Promptsplainer doesn't go investigate the code; they just copy-paste the maintainer's review comments straight back into their chat session and paste whatever the bot spits out next.
You don't need a massive daily flood of Promptsplainers to feel the damage. Even the occasional encounter can fill a maintainer with rage - and with good reason.
Wave Two: "Send a Patch" Finally Became Real
Here is what has changed dramatically over the last year. We went from AI fixes being flat-out wrong or lazy band-aids to pretty much landing in the right ballpark.
To appreciate why this matters so much to me, you have to remember what maintaining an open-source library looked like just a few years ago. Back then, I would get a steady stream of bug reports-and if I had the spare time, the patience, the kids went to sleep early, and my Netflix queue was empty, I might actually sit down and fix the bug.
For decades, open-source communities had a semi-joking, semi-exasperated stock response whenever a user asked, "Why doesn't it...?". We told them, "Patches welcome," or "Send a PR." Most of the time, we knew they wouldn't, because diving into a complex codebase from scratch was too steep a climb. The perfect storm between unpaid volunteer work, uneducated takes and exasperation.
Like many others, I have witnessed the change from getting bug reports to getting detailed pull requests. And I am personally grateful for this.
My philosophy on incoming contributions comes down to a simple reality: every PR represents a real pain point caught in the wild. It means a real user ran into a problem in their day-to-day work, reported or tracked down the issue, found a working solution, and felt the pain acutely enough that they took the time to package it up and upstream it.
As a maintainer, that is an infinitely better signal than my own laundry list of wish-list items sitting in the issue tracker. Even if the implementation needs additional work, someone just handed me proof of a real-world problem along with a concrete starting point to fix it.
Multi-Agent Code Review on My Side of the Table
The catch is that many coding models and agents still have a bad habit of just doing the fix-taking the shortest path to make a test pass without stepping back to look at the whole library. And not every contributor has learned how to tune their agents for deep engineering review, or has access to the best models for it.
The first pass of AI-generated code often needs work, and that is okay. Just as we spent years developing the discipline to master our programming languages, debuggers, and in some cases, write m4 macros, we now need to develop the muscle for using AI tools effectively-learning how to steer them, verify their assumptions, and audit their output.
For me, building that muscle meant putting AI on my side of the table to bridge the gap. Before I even bother reading a contributor's patch line-by-line, I religiously run /code-review in Claude and /review in ChatGPT [1].
These review passes routinely catch far more than narrow syntax nits-they surface genuine architectural flaws, subtle API breakage, rare side effects, and terminal conformance problems that would take me hours to trace manually [2].
Armed with that feedback, I can point contributors toward concrete architectural fixes-or, if someone disappears after opening a PR for a critical bug, I can clean up their branch and land it myself.
Some maintainers lament that reviewing these PRs feels like talking to someone who just copies and pastes feedback into a remote LLM. But we are still communicating with a human being on the other end. That gives us a real opportunity not just to coach contributors on how to use these tools responsibly, but to model and adopt better engineering practices across our industry. Given that the economics of top-tier reasoning models aren't ideal for everyone doing casual open-source work, I'm happy to foot that bill on my end for the sake of keeping my library healthy.
The Friction of One-Size-Fits-All Rules
This brings me to why I've been watching the broader debate around AI policies in large projects like Gnome and Godot with a lot of sympathy-and a bit of concern.
At Godot's massive scale, protecting volunteer reviewers from unvetted submissions and the occasional Promptsplainer is a completely understandable instinct. Nobody wants their Netflix time eaten up by drive-by code the author didn't bother to understand.
The challenge is that drawing hard lines around how code was written inevitably creates friction for experienced contributors who are already doing the architectural heavy lifting. Recently, I tried to upstream a small, production-tested bug fix to Godot as a trial balloon-one of roughly 60 to 80 improvements my team has built and tested in our own tree. Because I disclosed my AI workflow honestly, it ran afoul of their strict guidelines and was rejected.
When a policy polices provenance rather than quality, two unintended things happen:
- It penalizes transparency: Honest contributors who disclose their tools get blocked, while others are quietly nudged to keep quiet and pretend they typed every character by hand.
- Good fixes stay locked in private forks: Rather than wrestling with policy friction, teams like mine simply keep useful patches in our own internal trees. Because AI has made maintaining forks trivial, it doesn't slow us down-it just means the broader community misses out on fixes that could have helped everyone.
Accountability Over Provenance
The Promptsplainer is a real headache, and open-source projects are right to push back against uncomprehending, drive-by contributions.
But the antidote isn't banning the tools-it's requiring human accountability paired with better review tooling on the maintainer's side. At the end of the day, as the maintainer of a library, it is my role to make the editorial decisions about what goes in-and the people who depend on my library trust me to make those calls. Whether a patch started in an LLM prompt or was typed out by hand doesn't change that responsibility. If a contributor understands the problem, has tested the fix, and can engage thoughtfully in review as a human being, the models they used in their editor shouldn't disqualify their work.
Of course, scaling that kind of review culture when a handful of core maintainers are already stretched thin is a structural challenge all its own.
[1] With Claude I use Opus 5.5 alongside /review in GPT 6.2 with Sol-xhigh. In Claude, /code-review actually launches multiple distinct agents in parallel, each focused on different goals and common engineering mistakes. Looking forward to Antigravity to get this.
[2] In fact these reviews are so thorough, that I use /code-review on my own changes before shipping. In a seven-year-old codebase, it is impossible to keep every historical invariant in your head at once, and those agents regularly catch edge-case scenarios I had completely forgotten about.
20 Nov 2026 11:32pm GMT
Planet KDE | English
Changes on freedesktop.org!
Today we launched a change that has been a long time in the making: The updated website for freedesktop.org, as well as the refreshed wiki.freedesktop.org are live now!
You can read the announcement here, this blog post elaborates a bit on it and on the background of the changes, as well as future plans.
Why change anything?
The freedesktop.org website has been a wiki for a long time, which definitely was the right call in its inception. A wiki is very much in spirit of Freedesktop's mission statement to foster collaboration between desktop environments and to be a place to create de-facto standards.
However, over the years, working with the wiki became a bit of an issue: Not only did we face multiple spam-apocalypses (which in part motivated the switch to IkiWiki in 2013 and resulted in us heavily restricting write access to the wiki), but it also meant that official project information, finished specifications, half-finished proposals and pages nobody had touched in fifteen years were all sitting next to each other.
Since 2000 when Freedesktop.org was started, the project has grown so much and has had so many associated projects and specifications over the decades that it is now very difficult for new people to get an overview what is current and what state the software projects and specifications hosted by Freedesktop.org are in.
Having only a wiki as a large and somewhat disorganized pile of information did not help with that issue, so I worked to split things up: We now have a website as well as a wiki, using different designs to distinguish the two, and serving different purposes.
Website & website plans
The website at www.freedesktop.org will be the place for "official", or rather, more curated information. Now that the new website is live, its content is still largely that of the old wiki. Over the next weeks, I will be working on cleaning up its contents and listings. For example, I will clearly split active projects from archived ones, add missing ones, and also work towards synchronizing the specifications hosted on the former wiki / website with the ones listed on specifications.fd.o.
So, basically I will do an inventory check of Freedesktop. That work has already started, but until now, I could not make any public changes to not disrupt workflows or make my own future work harder by having diverging information in two places (website & wiki).
I also wanted to make it easier for people to find information on how to get involved with Freedesktop and associated projects, so the new website now has a more discoverable section for that.
The new website is a static site hosted via GitLab Pages and using Pelican. You can view its sources if you like.
Wiki changes
Of course, we also still want to keep the Wiki and all of its rich history around! It remains the easy-to-edit place for collaboration on upcoming projects and specifications.
Wiki edits must now happen through GitLab instead of the old IkiWiki web interface. While this sounds like an additional barrier to edit the wiki, it is significantly easier than requesting an account on annarchy to edit the old Wiki through the web interface. It also still allows us to keep the existing history as well as spam protection measures. In order to use the wiki with GitLab Pages and to keep the history easily accessible and readable, I rewrote the Git history of the wiki to make it pretend that all changes always happened in a content subdirectory. So, if commit signatures are missing and hashes are different: That is the only reason why. There have been no content changes or other metadata changes (and we still have a copy of the pristine wiki Git repository).
For the fd.o wiki, we are now also using Hari's IkiWiki template that is already in use on the X.org website and which is much easier on the eyes.
Next steps
At the moment, I am mostly concerned with ensuring that the change has not broken any existing links and all systems keep working. After that, the wiki 🡘 website deduplication work will start and we can modernize both the content of the website and wiki.
If you find a broken link, an outdated page or anything else that looks wrong, please file an issue or, even better, open a merge request.
For the wiki, you are very welcome to just fix or otherwise update the page directly.
I did reach out to all wiki editors and projects impacted by this change in advance, but since there are so many people and projects involved, it is always possible to miss someone or something. If you found a bug, need edit permissions, or need help with anything, don't hesitate to ping me: You can find me as ximion in OFTC's #freedesktop IRC channel, in the very recently created #xdg-specs channel on the Freedesktop Matrix space, or you can email me.
Thank you!
I do want to echo the announcement news post here: None of Freedesktop.org would exist without the people who filled it with life over the years and who worked on cross-desktop collaborative projects. I have read through a lot of wiki history and old project pages over the recent months, and it feels amazing to know how much work and passion people have poured into the projects and collaborative efforts over the years - no matter if they were successes in the end, or remained experiments. I am very thankful for all current, past and future editors of the website and wiki, as well as all project maintainers and contributors.
I also want to thank the Sovereign Tech Agency once more for supporting me in their fellowship program as a maintainer, which enabled me to work on this task among other things.
Thanks to all contributors, in whichever way you contribute to our free desktop ecosystem!
20 Nov 2026 10:22pm GMT
OMG! Ubuntu
Linux 7.3 is likely to be the next LTS kernel
 Linux 7.3 is looking like it'll be the new long-term support (LTS) kernel. Greg Kroah-Hartman, one of the kernels' key maintainers, intimated this in early November in a reply on the Linux Kernel Mailing List, discussing the status of Linux 7.4 and when it's likely to be released. In a reply to Linus Torvalds, who'd noted people were expecting Linux 7.4 to be designated an LTS (since it's shaping up to a big release and longterm kernels are picked, partly, based on being a feature-filled one) he said he planned for 7.3 to be LTS. "If people are trying to […]
You're reading Linux 7.3 is likely to be the next LTS kernel, a blog post from OMG! Ubuntu. Do not reproduce elsewhere without permission.
20 Nov 2026 5:37pm GMT
19 Nov 2026
OMG! Ubuntu
Check if that bargain SD card or USB drive is fake on Ubuntu
 Check if a bargain SD card or USB drive has fake capacity on Ubuntu using F3 (Fight Flash Fraud), an open-source Linux alternative to h2testw.
You're reading Check if that bargain SD card or USB drive is fake on Ubuntu, a blog post from OMG! Ubuntu. Do not reproduce elsewhere without permission.
19 Nov 2026 11:54pm GMT
16 Nov 2026
Planet Arch Linux
Mutex poisoning is not for everyone
After some recent discussion on the topic of mutex poisoning and notably a blog post that I thought was interesting, thoughtful, exhaustive, yet completely disagreed with, I wanted to comment on the debate myself. To me, poisoning-by-default is one of biggest mistakes that were made in the language, next to some others that are a story for a different time.
16 Nov 2026 12:00am GMT
30 Oct 2026
Kernel Planet
Matthew Garrett: Getting Google Cast on my Soundbar
I have a Samsung Q800A soundbar. It ships with built-in support for the Apple Airplay protocol, but I'm not really an Apple kind of guy so that's never been particularly helpful for me. So, instead, I have a Chromecast Audio plugged into it via TOSLINK, and that works fine - except for the fact that there's no way to explicitly pick TOSLINK as the audio input. Instead, there's a "Digital In" option that refers to both the optical in and eARC input from a TV. Not inherently a problem, given I'm unlikely to be watching TV while listening to music, but my TV is a Samsung Frame, a device that's intended to display art whenever someone is standing nearby, and which infuriatingly generates an eARC signal even if it's only in art mode and isn't going to make any noise. This switches the soundbar away from optical and I get sad. I could plug a video cast device into the HDMI port on the soundbar and cast audio to that, but then the art would get replaced with album covers whenever I'm playing music, and again that's not quite the ambience I want. Still, none of this is that important.
Until I learned that the Australian version of the soundbar does have Google Cast support. The firmware image was downloadable from Samsung support, so I grabbed that, but unfortunately found that it was encrypted. However, if I downloaded the firmware image for the US model, the encrypted blob was identical - there's no difference in the underlying firmware between the two of them. So, how come one has support, and the other doesn't?
I'd need an unencrypted copy of the firmware to have a real chance of figuring this out, and the easiest way to get one was to just run an ebay watch for a broken model of the same series. Once I had one in my hands I used hot air to remove the eMMC storage from the device, cleaned up the chip, and then stuck it in one of these adapters to read it on a local system. Samsung uses a weird in-house filesystem called VDFS4 on some of their devices and this was one of them, so I needed to cobble together a kernel that was compatible with their source dump for this device (not all VDFS drivers seem to be able to read all VDFS filesystems), but eventually I had it all extracted, and then I got distracted by other stuff, so let's fast forward to this week.
Samsung makes use of a modified version of the Android Debug Bridge called sdb, which is included in the Tizen SDK. The firmware showed that this device had sdbd on it, and it would be executed if a network device called "huart0" was plugged in. Samsung does, thankfully, provide the source code for their GPLed components, so I could dig through that to discover that drivers/net/usb/usbnet.c had a bunch of references to huart (which apparently stands for "HyperUART"). If CONFIG_SAMSUNG_USBNET_HYPERUART_IFNAME is set, and if the ethernet device is using either the asix or ax88179_178a drivers, and if "/opt/etc/HyperUART_IP_Addr"1 isn't just "0", it sets the interface name to "huart0" and in turn triggers sdbd startup. So now I just needed to figure out how to set /opt/etc/HyperUART_IP_Addr to something else.
Some digging revealed a binary called wap-factory that referenced the file, which then led to /usr/share/mobile-mgr/jsons/com.samsung.audio.waapp-verification-test.json which mentioned a "SetUartOnOff" call, which brought me here2, which led me into a bit of a rabbit hole about the Samsung WAM protocol. Long story short, you connect to either port 55001 or 56001 and make two requests over the same connection:
|
|
and then plug in an asix chipset ethernet adapter into the USB port (which on mine is micro-B, so I needed an OTG adapter), and suddenly it's sitting there on 192.168.250.250 and will speak sdb to you. sdb root on switches it into root mode, and sdb shell now gives you a root shell. I was in, and now I could investigate what was happening.
First up, there was a process called "com.samsung.audio.google-cast-control-app" running, which seemed like a good start. Unfortunately it wasn't doing anything. After some tracing I found that it was making a call to Samsung at startup time, and getting back a response telling it that Cast support wasn't available. The request (which was helpfully dumped to stdout when I ran this by hand) included the country code, in my case "US". Repeating the request by hand with curl and changing the code to "AU" told me it was supported, so now I needed to figure out how to get the soundbar to believe it was Australian. Some digging showed it was reading this from a config variable called db/comss/countrycode, and running
|
|
got me past that gate. Now, however, it was complaining that it couldn't provision a key. /usr/apps/com.samsung.audio.google-cast-control-app/shared/res included a bunch of encrypted blobs and an app called teeStoreKey.elf, and tracing com.samsung.audio.google-cast-control-app showed it was trying to call that, but it seemed like it was failing with a permissions issue. Running com.samsung.audio.google-cast-control-ap directly as root triggered key provisioning successfully, and a few seconds later the rest of the Cast API came up and I could talk to port 8443 with standard Cast API calls. Unfortunately it still wasn't working as a Cast device, though - it wasn't advertising itself via mDNS and so nothing could see it. Querying the /setup/eureka_info endpoint gave me a clue - the 'tos_accepted' field was false. Normally this would be set as part of initial device setup, but the Samsung app wasn't doing that because it didn't think the device had Cast support. It turns out that POSTing some json with {"tos_accepted": true} to setup/set_eureka_info made it work, and suddenly there was an additional Cast device available to me.
(Update: I realised I didn't mention anything about why it was doing key provisioning in the first place! The Cast protocol doesn't enforce cryptographic identity as such, but Google's reference client implementation which is what almost everything uses verifies that the device is presenting an identity that chains back to Google. Unsurprisingly they don't want the private key material to be easily extractable and used to produce clone devices, so it's all supposed to be encrypted and only accessible to some sort of trusted execution environment, which is why keys here need to be loaded into Trustzone and never be visible in the clear to the main OS)
Mission accomplished. Unfortunately the device vanished from my Smartthings home aferwards, presumably because there's a mismatch between its reported country code and my account country. To get around that I'd somehow need to get com.samsung.audio.google-cast-control-app to either change the query without changing the global device country, or to ignore the response from Samsung (it does this every 24 hours, ugh), and that's made more annoying by the fact that this thing will only execute signed binaries. Although, weirdly, one of the signed binaries shipped is a full Python interpreter, so if I cared enough I could probably cobble together enough Python to execute arbitrary binaries. I currently don't.
More modern soundbars don't implement the listener on port 55001 or 56001. I don't know how you get sdb working on them.
30 Oct 2026 6:03pm GMT
28 Oct 2026
Kernel Planet
Linux Plumbers Conference: The sched_ext Microconference
The sched_ext Microconference was very active this year at Linux Plumbers in Prague. It featured
six talks, preceded by an opening discussion on the future direction of sched_ext.
(Written by Andrea Righi)
Three main topics dominated the discussions
- Priority inversion and how to handle it in sched_ext: lock holder and
lock waiter preemption, time slice extension, and making proxy execution
work together with BPF schedulers. - Paravirtualized scheduling: letting the host and guest schedulers
cooperate across the VM boundary, with sched_ext as the policy engine on
the host. - Device and topology-aware scheduling: using hardware feedback (Intel
HFI), device/accelerator locality and cache topology to drive task
placement.
Intro: where sched_ext is going
The opening discussion outlined three directions for sched_ext development:
- Move more into BPF. With BPF arenas, queuing and idle CPU management can
be implemented entirely in BPF, and several schedulers are already
converging on this model. Once they all move, a significant amount of
in-kernel sched_ext code can be removed. - Composability. Long discussed, now a good time to tackle it: reusable
BPF/user-space building blocks (load balancer from one scheduler, idle CPU
selection from another, etc.) that can be combined into new schedulers. - Generate BPF code from Rust. Most schedulers today are Rust in
user space plus C for the BPF part. The trend, aligned with the wider
BPF community, is to generate the BPF code from Rust as well, so a
single language and shared abstractions can be used to access
scheduling data structures from both sides. Prototypes exist but this
is not there yet.
Priority inversion
Making proxy execution compatible with sched_ext
(Andrea Righi and John Stultz)
Proxy execution lets a mutex-blocked task lend its scheduling context to the
lock owner. The work presented makes this compatible with sched_ext, with
support enabled explicitly by each BPF scheduler. Dispatching a blocked task
triggers the core proxy machinery, keeping the BPF scheduler in control.
The compatibility changes and follow-up improvements are queued for Linux v7.4.
Distributions will be able to enable both `CONFIG_SCHED_PROXY_EXEC` and
`CONFIG_SCHED_CLASS_EXT` in the same kernel, removing their previous mutual
exclusion. The follow-up changes will also make proxy migrations transparent to
BPF, without exposing intermediate bookkeeping through extra enqueue callbacks.
Discussion points:
- User-space locks: futexes are not covered since `FUTEX_WAIT` does not
identify the owner. A new futex op that carries ownership is being explored;
passing user-space owner hints (e.g., via BPF maps or futex flags) is
inherently racy. A "directed yield" (timed proxy to a specific task) was
mentioned as future work. - rwsems / semaphores: writer boosting is supported via a patch; boosting
multiple readers is harder and has overhead. Plain semaphores have no owner
and cannot be proxied. - Observability: there are no upstream tracepoints for proxy execution
yet, which makes traces confusing (the owner runs under the donor's
context). Something similar to the existing PI tracepoints was requested.
Taming latency spikes caused by lock holder and lock waiter preemption
(Changwoo Min)
On the Steam Frame VR headset, camera processing must finish within 33ms but
needs only about 7-8ms of CPU time. Under heavy gaming load, preempting a lock
holder or delaying a woken lock waiter can stretch the pipeline enough to miss
that deadline.
LAVD addresses both cases with time slice extension and boosting of lock
waiters. The mitigations reduced scheduling delays above 2ms across four games,
with no missed camera frames observed during an hour of gameplay in the tested
titles.
A common interface for lock ownership and waiting information, covering kernel
and user-space locks, would help replace scheduler-specific heuristics.
Discussion points:
- Abuse of the extension is bounded by fairness: a task that constantly
extends its slice is deprioritized. - Why not just rely on proxy execution? Proxy is reactive (owner scheduled
out, donor scheduled in, owner scheduled in again), with extra overhead.
The consensus was that the two approaches are complementary: slice
extension is like a spinlock (cheap, good for short critical sections),
proxy execution is like a mutex (heavier, but handles long ones).
Paravirtualized scheduling
Bridging the VM Boundary: Scheduling Passthrough via pvsched and sched_ext
(Josh Don and Vineeth Remanan Pillai)
A host scheduler normally sees opaque vCPU threads, without knowing whether
they are running urgent guest work or background jobs. pvsched provides a
bidirectional channel: guests communicate priorities and preemption hints,
while hosts report which vCPUs they can run concurrently.
The proposed v3 design moves negotiation into the VMM through a virtual PCI
device, keeping policy outside KVM. On the host, sched_ext can implement bounded
vCPU boosting and gang scheduling. Guests can concentrate work on the vCPUs the
host can actually run, reducing the cost of double scheduling.
The next revision is still to be posted upstream.
Discussion points:
- BPF arenas as an alternative to a dedicated device: a host scheduler
could allocate an arena, hand out per-guest chunks and get zero-copy
communication with no kernel changes, needing only a way to pin arena
memory. Someone from the audience pointed out that allocating memory on
the host and mapping it into the guest on the fly is slow (memslot
creation, guest notification), which is why guest-initiated allocation was
chosen. However, this cost can be avoided: the host BPF scheduler can
create the arena once when it is started and hand out per-guest chunks
from the preallocated arena, mapping each chunk when the guest is set up
rather than on the fly, which keeps the fast path cheap. It was also
noted that the device model keeps the handshake arch-agnostic and
evolvable without kernel changes. - There is related work from others in this area; the agreement was that
the various efforts should converge on a single kernel module, possibly
alongside a BPF-arena-based path. - Standardization: post the kernel module first, then the QEMU device, then
other VMMs. - The preferred-CPU framework (steal governor) is related, but reactive,
while pvsched allows an explicit policy.
Device and topology-aware scheduling
Automatic placement of accelerator workloads
(Balbir Singh and Lee Trager)
CPU and memory placement can have a large effect on accelerator performance,
but manual pinning requires applications or administrators to know the topology
and device usage in advance. The proposed alternative combines hints about
which device a task is using, sched_ext task placement, and memory-access
telemetry to guide page placement. PMU counters were also suggested as a source
of remote-access and bandwidth telemetry to inform those decisions.
Two interfaces are needed: a generic process-to-device association and BPF
control over NUMA placement preferences. A series enabling NUMA balancing under
sched_ext had recently been posted, together with a kfunc for requesting a
preferred memory node.
Discussion points:
- Exposing PMU telemetry to non-root applications raises side-channel
concerns; IPC is fairly safe, cache/TLB misses are a gray area. An
allowlist of audited events was suggested. - Is a BPF map the right interface, or is a common user-space library needed
so all frameworks can provide hints? - Migrating network-heavy tasks across nodes may interact badly with per-CPU
queues and TCP flows. - NUMA balancing needs improvements, including asynchronous migration and
charging migration work to the right task. Enabling it under sched_ext
reuses the existing mechanism, so that work can proceed in parallel with
those fixes. Telemetry-driven `move_pages()` can serve as an interim solution.
HFI plug-in for sched_ext
(Srinivas Pandruvada)
Intel's Hardware Feedback Interface supplies per-CPU performance and efficiency
hints that reflect the platform's changing power budget. Integrating these
hints into LAVD improved Shadow of the Tomb Raider performance by about three
frames per second on a hybrid Intel handheld at a 10W power limit.
The prototype took less than a month. A Rust user-space thread receives HFI
updates over netlink and passes them to BPF through a map; LAVD then adjusts CPU
selection and effective capacity.
Discussion points:
- Why is HFI not used by the in-kernel scheduler? Older generations were too
noisy, and the firmware was tuned mostly on Windows workloads; the last two
generations treat Linux on equal footing, so it is worth revisiting. - Qualcomm's WALT has a similar CPU isolation feature (thermal and
low-utilization cases), implemented downstream via Android vendor hooks. - The preferred-CPU framework (steal governor) could be a natural in-kernel
hook for HFI exclusion. The thermal pressure signal filter currently only allows
slowing down the reaction time, and patches to make it configurable in both
directions may be revisited given how fast firmware can now report changes. - The HFI code is structured as a library and was proposed for inclusion in
the scx library so other schedulers can reuse it.
Stickiness: keeping tasks cache-warm in the work-conserving LAVD scheduler
(Gavin Guo)
Keeping a task on a cache-warm CPU can improve performance, but waiting for that
CPU competes with the benefit of running immediately elsewhere. The session
compared cache-warmth modelling, CPU reservation, and look-ahead dispatch from a
shared queue.
Results depended on the workload and approach. Warmth-based placement improved
P99 latency for short waits, while look-ahead dispatch showed no noticeable
memcached latency improvement under light or moderate load and added overhead
under heavier load.
Discussion points:
- Staying on a busy CPU is a short-term gain, while an idle CPU may offer
long-term uninterrupted execution, so the right answer is very workload-
and topology-dependent (shared vs non-shared L2/L3, snoop efficiency). - Suggestions included using PMU counters (as scx_cosmos already does) or Intel
RDT/CMT for cache occupancy (limited by the number of monitoring IDs),
tracking only latency-critical tasks, and broader workloads such as
stress-ng and video encoders.
28 Oct 2026 2:57pm GMT
27 Oct 2026
Planet Gentoo
The next circle of security hell
A few years back I wrote "The modern packager's security nightmare". Have things improved since? On the contrary, I feel like we're slipping down a well-oiled slope with no end in sight. Vulnerabilities are reported at unprecedented rates. A lot of people are doing everything they can to patch them up, which doesn't necessarily mean they're not making things even worse. Complex software involves complex trees of dependencies, and every branch on that tree needs tending to. When they stop being reliable, people further down the tree start taking more weight. And there's a limit of how much a single person can do, so what started as an effort to resolve an issue upstream may quickly become a weakness.
Is software less secure these days? It's tempting to say yes. I'd love to blame the corporate sector for egotistically dumping low quality software on us. I'd love to blame marketing-oriented people developing stuff with the sole goal of making a profit. I'd love to blame Rust for getting people obsessed about memory safety, and ignoring the kinds of vulnerabilities that aren't caught by the compiler. Finally, I'd really love to blame slop. But the truth is, I don't know. That's really beside the point.
The point is that nowadays everyone and their chatbot became security researchers. Projects are being flooded with vulnerability reports. Even though pretty much every bug bounty was discontinued because of slop, people aren't stopping. And even if we disregard truly invalid junk reports, there's a lot left, and you have to deal with them somehow. You have to figure out how important they are, and how to fix them (or more likely, whether the fixes submitted are truly valid and don't introduce regressions), or if you should reject them and why.
In the end, security is tricky. We're seeing lots of bugs like REDoS, or other kinds of "performance bugs". Are they really vulnerabilities? Well, it depends on the attack vector. And that in turn depends on how the software is used. Some scenarios are really contrived, and feel like "shell can execute dangerous commands if you type them in". But then, you also have really serious issues such as "timing attack can be used to guess user's secret". You need to know a lot to make that kind of judgment, and sometimes your judgment doesn't really match users' expectations.
In the end, what can project maintainers do? Even if they have the expertise and the energy to judge, if they can "know better", there's likely a CVE assigned already. It may have absurdly high score. All security scanners will complain unless you fix it, and users will come asking or complaining, or attacking, or forking. I mean, technology can't handle nuances. More than once I've been doing unnecessary security stabilizations over vulnerabilities that didn't affect Gentoo (for example, because we already unbundled the vulnerable dependencies), to avoid false positives from security scanners. I've been also doing meaningless version bumps (with no real changes or no changes that applied to Gentoo) so that our packages don't get reported as being "outdated". It's a hassle and it sucks, but it saves people from worrying.
I've said this before and I'll say it again: most projects aren't really prepared to handle security issues. And it's not just about triage. It's about having LTS or security branches, it's about making proper security releases with minimal changes. Unfortunately, it's quite common for security fixes to be combined with new features, deprecations, API changes. In extreme cases, people are caught with their metaphorical pants down, and suddenly need to make a security release in the middle of a major rewrite, or along with barely tested new code. And then, people downstream discover that they need to quickly deal with major API changes to upgrade past a vulnerable version. These things keep piling up.
What happens next? The community reaches a breaking point. People can't keep up. You discover you can't rely on others, so you work around them. You start bundling more stuff. Soon enough your workload goes beyond your ability. Software development becomes "every chatbot for itself". The nightmare becomes worse, and the wheel keeps turning.
27 Oct 2026 5:46pm GMT
26 Oct 2026
Planet Gentoo
php-8.1 on gentoo after CVE-2026-109618 and CVE-2026-109619
As we all know, PHP 8.1 reached EOL on December 31, 2025, and the Gentoo PHP package maintainers, as usual, followed the upstream project's line.
PHP releases often include fixes for CVEs, and once a release series reaches EOL, no further releases are published to address those vulnerabilities.
Until recently, even though some published CVEs were reproducible on PHP 8.1, upgrading was not strictly essential. However, with CVE-2026-109618 and CVE-2026-109619, I believe upgrading has become mandatory.
Unfortunately, I still have a few installations running PHP 8.1 because the software that requires it cannot be upgraded.
I imagine many other people are in the same situation, so I decided to publish this article to provide a practical solution.
All it took was resurrecting the latest php-8.1.x ebuild from the Gentoo Git repository and making a few minor changes to turn it into a live ebuild (9999) that uses Remi Collet's repository.
Remi Collet is a PHP contributor who maintains repositories for EOL PHP branches, backporting security patches so that users can continue running older PHP versions without leaving them vulnerable to known security issues. He also packages PHP for RHEL-based distributions.
I'd like to take this opportunity to thank Remi for his great work.
For convenience, I've added the ebuild to my overlay, so anyone who wants to install a PHP 8.1 version containing backported security patches can do so with:
layman -a ago
emerge =php-8.1.9999
A few things worth mentioning
1. Build environment
As of the time of writing, the ebuild builds successfully with a stable toolchain: gcc-16.2.1 and glibc-2.43-r4. I've also verified that the build succeeds with gcc-14.2.1 and glibc-2.42-r7.
2. Tests
src_test() pass successfully, however there are few unexpected failing tests that I'm investigating. In my view, a failing test can be an indication that software running in production may not be working as expected, so I strongly recommend enabling the tests.
3. Init system
The ebuild has been tested with OpenRC.
4. USE flags
Not all USE flag combinations have been tested, so enabling options different from the ones I used may cause the build to fail.
If you encounter a compilation failure, please report it to Remi Collet, as it is likely related to the PHP source code or its security patches.
If, on the other hand, you encounter an issue with the ebuild itself, please report it to me so I can investigate and make the necessary changes.
5. PHP_VERSION and the upstream commit
After installing php-8.1.9999, running:
php -r 'echo PHP_VERSION;'
will still output 8.1.34, because the version string is hardcoded here and here.
It would be nice if it printed something like 8.1.SHA or 8.1-SHA instead. Making this change in the ebuild would be trivial, but I don't want to do it without a proper audit of where this string is used and whether it is involved in version comparisons or other operations.
If having the commit SHA in the version string is important to you, feel free to bring it up with Remi, who can decide whether to make the necessary changes to the repository.
Therefore, if you want to determine which commit your build was compiled from, you'll have to use qlop -m to find the build date and then check the state of the php-src-security/PHP-8.1-security-backports repository at that time.
6. Older PHP versions
I don't have any software that requires a PHP version older than 8.1, but if you do, you can apply the same approach in your own local repository by changing EGIT_BRANCH to point to whichever branch you need.
Keep in mind that different branches may require different build instructions, which you'll need to adapt accordingly.
7. Backporting Gentoo ebuild changes
Although the ebuild worked out of the box and required no major modifications, since I decided to publish it and make it available to others, I also took the opportunity to backport some of the changes that the Gentoo PHP maintainers had made to ebuilds for versions newer than 8.1.
8. Keeping up with security updates
I recommend setting up a watch on the repository. Whenever a new commit introducing a security patch is published, you'll need to rebuild and reinstall the package by running:
emerge =php-8.1.9999
This ensures that your installation picks up the latest available security patches.
That's all.
26 Oct 2026 1:23pm GMT
24 Oct 2026
Planet Gentoo
eMudhra Intermediate CA Compromise
On 2026-10-20, it has been disclosed that the private keys of eight eMudhra intermediate CA certificates have been compromised. These keys can be used to issue forged CA certificates that would be considered fully trusted by the affected software, and therefore could be used to perform man-in-the-middle attacks.
Importantly, the vulnerability can also affect software self-update processes that use TLS verification as the only security measure, with an attempt to upgrade the system leading to it being compromised. The standard Gentoo configuration mitigates this risk, as both the ebuild repository updates and binary package downloads are secured using OpenPGP keys. A malicious third party may be able to intercept update requests, but Portage will reject any tampered packages or metadata.
The baseline remediation is to upgrade to >=app-misc/ca-certificates-20260816.3.125. However, some packages are using bundled certificate stores and require separate remediation. In some cases the bundled certificates are updated automatically, in others, the relevant packages will need to be upgraded. We are actively tracking the affected packages in bug 984601, and releasing fixed versions to Gentoo stable ASAP. We are also looking into forcing the use of the system certificate store in more packages, per our unbundling policy.
Please note that packages installed outside Gentoo package manager are also affected. For example, Python virtual environments featuring the prior versions of certifi, pip or uv packages are vulnerable. Please refer to the Python upstream announcement for more details and the recommended remediation.
24 Oct 2026 5:00am GMT
20 Oct 2026
Kernel Planet
Linux Plumbers Conference: LPC 2026 – Kernel Testing MC
The Kernel Testing & Dependability Micro-Conference was back again at Plumbers this year, in Prague and with a wide variety of topics. In addition to the well-established frameworks such as KUnit and kselftest, some new frontiers are being explored with the spotlight on LLM-assisted tools. Developers are also getting special treats with new kci-dev features and expert insights into local build testing at scale.
Primary author: Guillaume Tucker
kci-dev
What Changed, What Works, and What Kernel Developers Still Need - by Arisu Tachibana (virtual)
The kci-dev command line tool enables developers to interact with KernelCI. Here's a summary of the latest changes:
- Core implementation moved to the
kcidevPython module as an API library - Standalone patch file testing enabled on top of a Git checkout
- Submission of results to KCIDB enabled with artifacts uploaded to storage
- Experimental MCP added on top of the API
The tool also benefits from these new plugins:
kci-patchworkto apply patch series from Patchwork and submit test jobkci_release_reviewto compare revisions and create reports
Plugins can help extend functionality so they should be a good way of driving future kci-dev development. The MCP may also enable new use cases. Please join the KernelCI mailing list and Discord channel as per the contact page if you wish to take part and discuss things further.
Build Identity
Kernel Builds Deserve an Identity: Portable Kernel Artifacts and Traceable Test Results - by Cong Wang
The raw metadata provided by uname, Git, IDs from various CI systems etc. does not provide any standard or consistent way to identify a build. As such, bug reports can't directly refer to a single reproducible binary.
Cong Wang's proposal is the Kernel Bundle Image (KBI) project. It draws a parallel with how OCI solved this for container images. The idea is essentially to create OCI images for kernel builds. However, it still has a low level of adoption and isn't used by current automated testing systems.
How may KBI gain more traction?
Where should the line be drawn about what to include in the kernel build ID? There hasn't been a clear consensus on this yet, whether it should include device trees, firmware blobs and other artifacts.
Yocto / OE also has a way to reproduce entire OS builds, including the kernel. This may be used as a guideline or potentially combined with the KBI approach.
It's also worth noting that TuxMake is able to reproduce binary-identical builds for a given set of inputs (container image and build parameters), which does not constitute a build ID per se but could still be potentially very helpful for this purpose.
A related initiative is KernelSbom since a bill of materials could define the input to a KBI image: source with metadata, main build artifacts, additional contents (firmware, BPF).
KUnit Configuration
Rethinking KUnit Configuration - by David Gow
The session started with a poll: roughly half of the room use KUnit regularly and 3 people answered yes to the last question about running KUnit with multiple configurations. This tends to show that the tool is well established for standard usage but few developers use it in an expert way.
The main issue covered by this session is about limitations with the .kunitconfig file and qemu_config Python module, especially the lack of output format options and the fact that each config covers only a single KUnit run.
Proposal: Determine a single standard configuration mechanism to go beyond limitations while being easy to share between developers. Passing metadata through to the results would also be especially useful for CI systems which can deal with more details and trace the results back to their origin.
Should this be solved with a new config system or by extending an existing one?

- Option 1: extend
.kunitconfig(currently a plainKconfigfragment) - Option 2: native Python module since
kunit.pyis already in Python - Any other options?
David's preferred option is to extend .kunitconfig.
For multiple runs bundled together, it's important to be able to parse the results as if they were individual ones e.g. objects embedded within a bigger blob. One potential solution is to produce results in separate files (KTAP).
Multiple runs are useful for CI integration with a single entry point. It also removes the overhead of setting up many short-lived individual jobs. This doesn't however appear to be too useful for manual runs. It can help a bit with git bisect run although multiple KUnit commands may be bundled within a single script.
It's also worth noting that having isolated kernel runs would prevent a single crash from breaking the whole series.
The overall consensus is that multiple runs in a single command or config aren't probably that useful except in particular cases e.g. CI hooks.
Build Testing
Optimizing local kernel build testing - by Arnd Bergmann
As a sequel from Arnd's talk at Kernel Recipes, this session is to discuss using a manual, local setup to achieve wide build testing coverage. The focus is on linux-next, with -Werror enabled to try and catch all new build issues.
The best approach when something breaks is to send a fix if possible as it is a lot more effective than just reporting bugs. By doing this for many years, Arnd has fixed thousands of bugs upstream (3000+) and touched every subsystem in the kernel.
The most common problems are Kconfig dependency bugs since its logic is complicated and deceptive, especially with tristate options. The new kconfirm tool aims at solving this issue via static analysis.
Arnd keeps a small config fragment to maximise the effectiveness of build testing:
# maximize search space, disable options not worth testing
CONFIG_COMPILE_TEST=y
# avoid long build times
# PROFILE_ALL_BRANCHES is not set
# reduce compile-time dependencies
CONFIG_STANDALONE=y
CONFIG_PREVENT_FIRMWARE_BUILD=y
Should orchestration of parallel builds be integrated upstream?
This sounds useful although the discussion didn't expand on how to approach this topic in practice. The general makefile and arm64-specific testrandconfig64 files attached have been kindly provided by Arnd as a reference based on his local setup. Please feel free to reach out to him via email should you wish to discuss this further.
Should local build regression reports be sent to KCIDB? With a proposed fix in a patch?
Several people would welcome this and a follow-up discussion is intended to take place with the KernelCI team.
kcov and kselftest
Kselftest coverage with kcov - by Shuah Khan
Thousands of tests are available in-tree via kselftest and KUnit, but what is their coverage? Shuah has made an experimental tool to run kselftest with kcov and start looking into the issue. Coverage data is not ready to be published yet so the discussion was more about the potential use cases. You can already expect to see a more in-depth follow-up analysis on this topic next year and other general kselftest sessions at every future LPC.
How is code coverage useful?
When working with unknown customer workloads, comparing their coverage with well-known tests gives an idea of how much the tests are covering these workloads.
One issue with enabling kcov at build time is that it's not suitable for production kernels. However, ftrace is usually enabled so it could be used in combination with kcov with different granularity (function-level only coverage with ftrace).
Another dimension to the problem is about evaluating other tools e.g. LLVM/Clang coverage. See also the LLM fuzzing session on a related topic.
KFuzzTest
KFuzzTest: One year on - by Ethan Graham
The aim of KFuzzTest is to combine the benefits of fuzzing and unit testing. A new, experimental API is now available in the latest version of the patch series to make it easier to write tests and facilitate adoption.
The next core feature which is currently under development is stateful fuzzing. Initial trials found a known bug which had already been fixed but this showed the tool's potential.
Can fuzzing target specific code?
This is not trivial. In some cases, hardware mocks may be used to enable coverage on specific drivers. Generally speaking, KFuzzTest's aim is to narrow down fuzzing to isolated functions like a unit test would typically do. The effectiveness of this method is still being debated, perhaps the sweet spot lies in between this and syzkaller's broader approach.
How about stateful fuzzing?
Stateful fuzzing in userspace exists and enables setting extra boundaries. Kernel fuzzing is typically run from outside the kernel, kind of guessing how to invoke the syscalls. Having the kernel asking a userspace fuzzer has led to successful experiments in the past. So overall, stateful fuzzing is feasible.
How about KUnit overlap?
David Gow is in favour of adding functionality that lets userspace pass data into KUnit tests. This could also facilitate making reproducers. However, the stateful approach is not a good fit for KUnit with long strings of operations as unit tests are meant to be run in isolation.
LLM Fuzzing
LLM-Assisted Fuzzing with Syzkaller - by Chuyang Wang & Aleksandr Nogikh

The issue when fuzzing with high-level descriptions is that they don't go deep enough to reach good code coverage. Hand-written seed programs partially solve this but the approach doesn't scale.
The proposed solution here is to rely on LLM-generated ones instead. While attempting to reach areas never covered by syzbot, an overall 15% increased coverage was reached over a few months using this approach. This uncovered a new issue with the LLM trying to evade syzkaller's sandboxing environment. The next step is going to integrate with syzbot.
Is AI-driven cheaper?
Probably but not measured in terms of actual costs. One seed program could then expand coverage.
How about fuzzing drivers?
This is tricky because testing drivers often requires access to real hardware. USB is an exception as physical devices are not strictly necessary. This has enabled the team to significantly increase fuzzing coverage and report many bugs over a short period of time.
Still useful to upstream hand-written seed programs?
Yes, these are complementary approaches.
KernelCI in the Cloud
Testing the kernel where the fleet runs: KernelCI in the cloud - by Norbert Manthey & Stanislav Uschakow
Going beyond the historical use cases of KernelCI which originated on embedded platforms, this session is about testing kernels deployed in the Cloud. The system covers x86_64 and Graviton (arm64) VMs in an AWS lab. Additionally, nested KVM guests on particular VM types are also supported. It provides the typical scalability and variety of platforms one would typically expect to find in this environment. Developers may also run the tests themselves using their own AWS account.
Current upstream kernel coverage includes mainline, linux-next and LTS. Runtime coverage is limited to baseline boot testing and basic checks. Performance testing is next on the roadmap.
How is A/B testing done in the AWS Cloud?
The approach is to run both A and B kernels with the same VM definition to reduce dependencies on the environment (hardware of physical host, virtualization stack, firmware, …). Keeping the kernel as the single moving part enforces it to be the only root cause for any difference found in test results. The code for this A/B testing is made available as a GitHub repository under the KernelCI project umbrella.
How does A/B testing on AWS work with live migrations?
Tests are not relying on a file system for now to keep resource dependencies low. Hypervisor updates can cause one VM to stop but tests are run multiple times and in a distributed way so the impact is mitigated.
Are you running KUnit?
KernelCI is running KUnit in other environments, not in AWS. It's unclear whether doing this would increase existing coverage.
Which kernel trees have the priority?
Testing linux-next and mainline kernels should be the priority. Covering LTS is also useful to verify that fixes get backported successfully as they would typically be applied to the AWS forks too although those are outside the scope of KernelCI.
Are any more details of the test runs available?
In order to give maintainers access to more details about test runs, the AWS lab setup needs to expand its integration with KernelCI in general. Additional features have been requested during LPC such as being able to automatically bisect issues and sending regressions as direct replies to patches via emails threads. Those reports should also be sent to the kernel regressions list.
Testing BoF
Note - The speaker has apologised for not being able to host the last session of the schedule due to personal reasons. It was replaced with an impromptu Testing BoF instead.
One particular point was discussed:
How to address kselftest failing to build and run?
- Tests may fail to build due to missing dependencies. The
kselftest_deps.shtool can be used to discover those. Integrating it into the kselftest Makefile is being considered in order to report them directly to the user. - Test build failures don't cause the overall kselftest build to fail. This is good, although reporting this in a better way might be helpful.
- Build and run regressions need better reporting, they could be made more visible using a tag in email subjects.
Wrapping Up
One lesson learnt is that AI-assisted development tends to be more about data analysis while the initial scope of the Testing MC is rather to focus on low-level tools. These may be seen as optimised, primitive functions producing raw data that LLMs can then leverage and potentially use to orchestrate test runs. Having a session about LLM-assisted fuzzing was a good fit though as it showcased how AI can make use of existing testing components in novel ways.
Last but not least, many thanks to all the speakers for reviewing this blog post, the conference committee and all the attendees for making Plumbers such a great experience. It was a pleasure to be a co-organiser of the Testing MC again this year.
See you at LPC 2027 
20 Oct 2026 7:06pm GMT
08 Oct 2026
Planet Arch Linux
Writing parsers is hard
This is a story of how we got from something like this: Failed to deserialize BUILDINFO file: Parser failed with the following error: unknown ^ invalid makepkg build environment option expected `buildflags`, `ccache`, `check`, `color`, `distcc`, `sign`, `makeflags` To this: When the ALPM project started, the goal was fairly simple: Better tooling to interact with the low-level plumbing of Arch Linux Package Management (ALPM). This meant binaries to read/write individual file types, better error messages, extensive specifications and of course exports to common dataformats like JSON. The thing is, although some of us already had experience with low-level dataframe parsing, …
08 Oct 2026 12:00am GMT
29 Aug 2026
Planet Maemo
An In-Depth Look at the LiberNovo Omni SE
Two months, one chair, and a cushion that had to be replaced - twice. This isn't a review in the strict sense. The only other chair I've used long-term is an IKEA Nominell, so I can't offer broad comparisons. What I can offer is an honest account of living with the Omni SE - plus a few observations most reviews skip.
Where I'm coming from
My background shapes what I look for in a chair, so it's worth stating up front.
I never had back problems with my old IKEA chair, but I credit that to regular exercise rather than to the chair. In my experience, exercise is by far the most effective way to prevent back pain - closely followed by changing posture throughout the day: standing up now and then and putting your leg muscles to work.
The upshot: for me, the specific chair matters less than people assume. What I value instead are quality-of-life features - freedom to move and the ability to recline deeply for a quick moment of relaxation. That's the lens I judged the Omni SE through.
The Omni chairs hardly need an introduction; they're among the most aggressively marketed chairs on social media. So rather than rehash the spec sheet (Dan Ahn's YouTube channel covers that well), I'll stick to my own experience.
Ordering
I paid the 10€ deposit, ordered on 16 June for 589€, and received the chair on 23 June - so about two months of use at the time of writing.
The 10€ "deposit" turned out to be a one-year warranty extension rather than a deposit. Fine by me.
The seat cushion problem
The downside of ordering early and cheap: at least the first batch shipped with foam that was too soft in the seat cushion.
The Omni cushion combines three foam densities, with the firmest section only near the backrest. Even that section wasn't firm enough - once the foam warmed up, you'd sink through to the plastic pan. Steve, the Anthros CEO, summarises the issue neatly - keep in mind though, that this is coming from a rival.
If you're reading this in a seemingly fine Omni and wonder what this feels like, sit on the front edge for a few minutes: the softer foam lets you bottom out. Sit with your lumbar against the backrest and you're on the firm section, where it should feel comfortable.
Customer support assured me that batches produced after early May went through improved firmness testing - which means my chair was made before that. At the time of writing, it's still unclear whether all new deliveries ship with the updated cushion. So if you'd rather not go through the hassle of getting a replacement, wait until that's confirmed.
How support handled it
Sitting with my lumbar against the backrest was exactly where the problem showed up for me, so after a few uncomfortable weeks I contacted support via email. They replied within 24 hours, and their first suggestion was that I should sit closer to the backrest. Once I confirmed I already was, they promised a revised cushion - and noted that my return window would restart on the day the replacement arrived.
A week later a new cushion arrived - the Pro version, sent by mistake. Since the correct replacement was another month out, I used the Pro cushion in the meantime; its firmer foam didn't bottom out. I also received a small compensation package for the inconvenience, including the StepSync Mat, which turned out to be surprisingly handy - more on that below.
The correct SE cushion arrived at the end of August, so at the time of writing I've used the Pro cushion for about a month and the revised SE cushion for three days.
On the two replacement cushions
The revised SE cushion is noticeably stiffer than the one my chair originally shipped with, across all three foam zones.

The Pro uses Gabriel Atlantic fabric, which the active ventilation requires because it allows more airflow. It's also more durable. The trade-off is the coarser weave: less soft and slightly scratchy compared to the standard fabric.
In terms of firmness, the two replacement cushions feel about the same to me - the fabric is the main difference. Upgrading to the Pro just for the fabric isn't worth it in my view.
Backrest and recline
The backrest is what LiberNovo builds its marketing around, and deservedly so. Sitting down for the first time, it was the most noticeable difference to my IKEA chair: it hugs you around the lumbar region and you immediately feel supported, without limiting your range of motion.
The second standout is the recline. If you've ever wanted to lie back for a moment of relaxation and quick back relief, that's what the 160° position gives you. Even at maximum recline the chair feels stable - but to be genuinely comfortable, you'll want to raise your legs. Whether that calls for the official footrest is up to you; I put the StepSync Mat on the subwoofer under my desk and called it a day.
Day to day, though, I keep the chair locked at 135° with the tension tightened up - that lets me move freely back and forth while still getting the back support.
Armrests
These get called out as a weak point, so I'll say plainly that I like them. Yes, they slide forward and backward very easily - but for me that's an advantage: I can pull up to the desk and the armrests simply move out of the way. If you prefer them to stay put, I can see it being annoying.
The one real drawback: at the two narrowest width settings they collide with the backrest unless fully extended forward.
Material-wise, the firmness and smooth surface are pleasant. Keep in mind, though, that my old chair had no armrests at all.
The standout: parts availability
The cushion swap points to what I consider LiberNovo's real strength - not the chair itself, but what you can do with it after you buy it.
Competing brands may advertise a 12-year warranty instead of six, but their spare-parts selection is very limited. With LiberNovo you can order every individual component - and, unusually, at fair prices: building an Omni SE from parts comes to €681, against €679 for the finished chair (current price). Most brands price their spares steeply enough to make that comparison absurd.
What that enables is customization: want a headrest in a different colour? Order that spare part. Worried about the motorized lumbar? Swap in the manual one from the SE.
Verdict
After two months, I'm happy with the upgrade. The Omni SE is far more comfortable than my IKEA chair, and I use the recline often - reading a book, or just taking the load off my back.
The biggest drawback is probably the fixed seat depth. You can change it later by buying the 45 cm / 48 cm cushion replacement, but that still doesn't let different people share the same chair.
LiberNovo recently extended the warranty to six years for everyone, which makes seven with my deposit. Since the SE has no electronic components, that covers the whole chair in my case.
My cushion wasn't right out of the box, and it still took two months and two shipments to sort out. But the parts availability and the support response mean you're not stuck with a problem you can't fix - and that, more than any spec, is what won me over.
I'll update this post if anything changes.
0  0

29 Aug 2026 11:27am GMT
09 Aug 2026
Planet Arch Linux
On scripts and hooks
Over the last few weeks, we have been doing research on the integration of our official distribution packages when installed on a target system. In this context we have been looking at the current uses of alpm-install-scriptlet(5) files and alpm-hooks(5) in around 120 package source repositories (alpm-source-repo(7)) to better understand the underlying functionality and use-cases these two integrations offer and target. In this article we are going to look at how these two systems work, how Arch Linux is currently using them and attempt to provide suggestions for when to use which. Learning about alpm-hooks(5) and alpm-install-scriptlet(5) files …
09 Aug 2026 12:00am GMT
04 Jul 2026
Planet Maemo
Reticulum is interesting
It all started innocently enough: sometime last summer, I ran into the blog post Start your own Internet Resiliency Club on Hacker News.
…communicate with each other across a few kilometers without any centralized infrastructure using cheap, low-power, unlicensed LoRa radios and open source Meshtastic text messaging software.
The idea of a local, infrastructure-free communications mesh sounded useful, especially as we were about to sail into the Pacific.
Meshtastic
While conflicts and natural disasters are hopefully far away, on the smaller atolls there is no cellular network. With Meshtastic we could communicate over LoRa.

Over the hurricane season, the Meshtastic setup became quite extensive. Our boat has a Meshtastic node, plus a mast-mounted solar repeater. We both have Meshtastic cards that we carry with us. With these we can communicate with text messages over quite a long distance. And we get telemetry and alerts from the boat.
In Cartagena, Colombia we could hear the boat pretty much across the city. And since some of our buddy boats also run Meshtastic, we've even had conversations while offshore.
While the existing Meshtastic setup is serving us well, there is always room for improvement and new ideas.
Reticulum
Reticulum is a project that seeks to take this to a whole new level. It is a whole decentralized networking stack that allows anything from instant messaging and voice calls to full-on SSH sessions to be carried over a multitude of different interfaces. You can transport Reticulum over LoRa, Bluetooth, and also over regular TCP/IP networks. And if authorities didn't take a dim view on encryption in ham radio, it would also work over our HF radio. With store-and-forward mechanisms it can deal with intermittent connectivity.
Because your identity is portable, your connectivity can be fluid. You can be sitting at a desk connected to a fiber backbone one moment, and walking through a field connected only to a long-range LoRa mesh the next. To the rest of the network, nothing has changed. Your friends do not need to update your contact info. The messages they send do not bounce back. The network senses the shift in the medium and reroutes the flow of data automatically.
You are no longer a stationary node in a fixed grid. You are a wanderer in a fluid medium.
- The Zen of Reticulum
As it stands now, Reticulum is still quite an early system with rudimentary and tech-heavy user interfaces. But that seems to be about to change: the Columba app for Android seems about as user-friendly as Meshtastic or something like Signal. There's a lot of potential in that once it reaches a stable version.
Distributed development over Reticulum
In the meanwhile, there is one aspect of Reticulum we developers can benefit from immediately: Distributed development. With it, any rngit node running on Reticulum can be your "GitHub". Git history, issue tracking, release distribution is already there.
I recently switched my various programming projects over. We have rngit running on the boat NAS, and VPS running a mirror behind more consistent connectivity. And for now I also mirror the work periodically to GitHub for backwards compatibility.
Reticulum for software
What I think is worthwhile to explore is having machines interface with Reticulum. Just like we can tell our boat to switch lights on via a Meshtastic message, we should be able to do the same with Reticulum. And maybe there should be a NomadNet "site" for the boat showing status of the various systems.
Going further, maybe boats could share chart data, depth soundings, weather information with each other over this. The promise of VDES, but built from the grassroots perspective.
And maybe things like NoFlo should be able to communicate over Reticulum? Reticulum implementations exist for multiple programming languages, but for this we'd need a JavaScript port.
There's still a lot to study and to think about. Watch this space. Last time I noted that something is interesting, it took me to a ten year rabbit hole.
0 0
04 Jul 2026 12:00am GMT
26 Jan 2026
Planet Maemo
Igalia Multimedia contributions in 2025
Now that 2025 is over, it's time to look back and feel proud of the path we've walked. Last year has been really exciting in terms of contributions to GStreamer and WebKit for the Igalia Multimedia team.
With more than 459 contributions along the year, we've been one of the top contributors to the GStreamer project, in areas like Vulkan Video, GstValidate, VA, GStreamer Editing Services, WebRTC or H.266 support.
In Vulkan Video we've worked on the VP9 video decoder, and cooperated with other contributors to push the AV1 decoder as well. There's now an H.264 base class for video encoding that is designed to support general hardware-accelerated processing.
GStreaming Editing Services, the framework to build video editing applications, has gained time remapping support, which now allows to include fast/slow motion effects in the videos. Video transformations (scaling, cropping, rounded corners, etc) are now hardware-accelerated thanks to the addition of new Skia-based GStreamer elements and integration with OpenGL. Buffer pool tuning and pipeline improvements have helped to optimize memory usage and performance, enabling the edition of 4K video at 60 frames per second. Much of this work to improve and ensure quality in GStreamer Editing Services has also brought improvements in the GstValidate testing framework, which will be useful for other parts of GStreamer.
Regarding H.266 (VVC), full playback support (with decoders such as vvdec and avdec_h266, demuxers and muxers for Matroska, MP4 and TS, and parsers for the vvc1 and vvi1 formats) is now available in GStreamer 1.26 thanks to Igalia's work. This allows user applications such as the WebKitGTK web browser to leverage the hardware accelerated decoding provided by VAAPI to play H.266 video using GStreamer.
Igalia has also been one of the top contributors to GStreamer Rust, with 43 contributions. Most of the commits there have been related to Vulkan Video.
In addition to GStreamer, the team also has a strong presence in WebKit, where we leverage our GStreamer knowledge to implement many features of the web engine related to multimedia. From the 1739 contributions to the WebKit project done last year by Igalia, the Multimedia team has made 323 of them. Nearly one third of those have been related to generic multimedia playback, and the rest have been on areas such as WebRTC, MediaStream, MSE, WebAudio, a new Quirks system to provide adaptations for specific hardware multimedia platforms at runtime, WebCodecs or MediaRecorder.
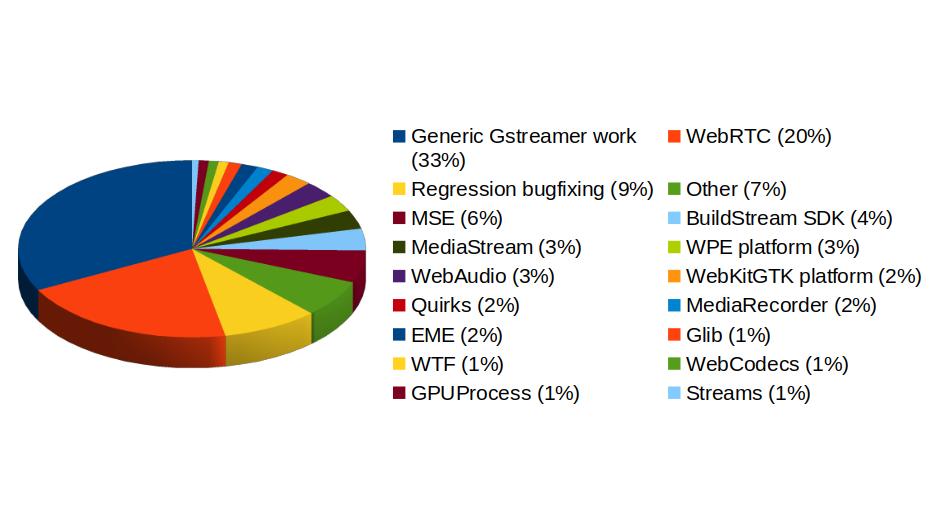
We're happy about what we've achieved along the year and look forward to maintaining this success and bringing even more exciting features and contributions in 2026.
0 0
26 Jan 2026 9:34am GMT
18 Sep 2022
Planet Openmoko
Harald "LaF0rge" Welte: Deployment of future community TDMoIP hub
I've mentioned some of my various retronetworking projects in some past blog posts. One of those projects is Osmocom Community TDM over IP (OCTOI). During the past 5 or so months, we have been using a number of GPS-synchronized open source icE1usb interconnected by a new, efficient but strill transparent TDMoIP protocol in order to run a distributed TDM/PDH network. This network is currently only used to provide ISDN services to retronetworking enthusiasts, but other uses like frame relay have also been validated.
So far, the central hub of this OCTOI network has been operating in the basement of my home, behind a consumer-grade DOCSIS cable modem connection. Given that TDMoIP is relatively sensitive to packet loss, this has been sub-optimal.
Luckily some of my old friends at noris.net have agreed to host a new OCTOI hub free of charge in one of their ultra-reliable co-location data centres. I'm already hosting some other machines there for 20+ years, and noris.net is a good fit given that they were - in their early days as an ISP - the driving force in the early 90s behind one of the Linux kernel ISDN stracks called u-isdn. So after many decades, ISDN returns to them in a very different way.
Side note: In case you're curious, a reconstructed partial release history of the u-isdn code can be found on gitea.osmocom.org
But I digress. So today, there was the installation of this new OCTOI hub setup. It has been prepared for several weeks in advance, and the hub contains two circuit boards designed entirely only for this use case. The most difficult challenge was the fact that this data centre has no existing GPS RF distribution, and the roof is ~ 100m of CAT5 cable (no fiber!) away from the roof. So we faced the challenge of passing the 1PPS (1 pulse per second) signal reliably through several steps of lightning/over-voltage protection into the icE1usb whose internal GPS-DO serves as a grandmaster clock for the TDM network.
The equipment deployed in this installation currently contains:
-
a rather beefy Supermicro 2U server with EPYC 7113P CPU and 4x PCIe, two of which are populated with Digium TE820 cards resulting in a total of 16 E1 ports
-
an icE1usb with RS422 interface board connected via 100m RS422 to an Ericsson GPS03 receiver. There's two layers of of over-voltage protection on the RS422 (each with gas discharge tubes and TVS) and two stages of over-voltage protection in the coaxial cable between antenna and GPS receiver.
-
a Livingston Portmaster3 RAS server
-
a Cisco AS5400 RAS server
For more details, see this wiki page and this ticket
Now that the physical deployment has been made, the next steps will be to migrate all the TDMoIP links from the existing user base over to the new hub. We hope the reliability and performance will be much better than behind DOCSIS.
In any case, this new setup for sure has a lot of capacity to connect many more more users to this network. At this point we can still only offer E1 PRI interfaces. I expect that at some point during the coming winter the project for remote TDMoIP BRI (S/T, S0-Bus) connectivity will become available.
Acknowledgements
I'd like to thank anyone helping this effort, specifically * Sylvain "tnt" Munaut for his work on the RS422 interface board (+ gateware/firmware) * noris.net for sponsoring the co-location * sysmocom for sponsoring the EPYC server hardware
18 Sep 2022 10:00pm GMT
08 Sep 2022
Planet Openmoko
Harald "LaF0rge" Welte: Progress on the ITU-T V5 access network front
Almost one year after my post regarding first steps towards a V5 implementation, some friends and I were finally able to visit Wobcom, a small German city carrier and pick up a lot of decommissioned POTS/ISDN/PDH/SDH equipment, primarily V5 access networks.
This means that a number of retronetworking enthusiasts now have a chance to play with Siemens Fastlink, Nokia EKSOS and DeTeWe ALIAN access networks/multiplexers.
My primary interest is in Nokia EKSOS, which looks like an rather easy, low-complexity target. As one of the first steps, I took PCB photographs of the various modules/cards in the shelf, take note of the main chip designations and started to search for the related data sheets.
The results can be found in the Osmocom retronetworking wiki, with https://osmocom.org/projects/retronetworking/wiki/Nokia_EKSOS being the main entry page, and sub-pages about
In short: Unsurprisingly, a lot of Infineon analog and digital ICs for the POTS and ISDN ports, as well as a number of Motorola M68k based QUICC32 microprocessors and several unknown ASICs.
So with V5 hardware at my disposal, I've slowly re-started my efforts to implement the LE (local exchange) side of the V5 protocol stack, with the goal of eventually being able to interface those V5 AN with the Osmocom Community TDM over IP network. Once that is in place, we should also be able to offer real ISDN Uk0 (BRI) and POTS lines at retrocomputing events or hacker camps in the coming years.
08 Sep 2022 10:00pm GMT
Harald "LaF0rge" Welte: Clock sync trouble with Digium cards and timing cables
If you have ever worked with Digium (now part of Sangoma) digital telephony interface cards such as the TE110/410/420/820 (single to octal E1/T1/J1 PRI cards), you will probably have seen that they always have a timing connector, where the timing information can be passed from one card to another.
In PDH/ISDN (or even SDH) networks, it is very important to have a synchronized clock across the network. If the clocks are drifting, there will be underruns or overruns, with associated phase jumps that are particularly dangerous when analog modem calls are transported.
In traditional ISDN use cases, the clock is always provided by the network operator, and any customer/user side equipment is expected to synchronize to that clock.
So this Digium timing cable is needed in applications where you have more PRI lines than possible with one card, but only a subset of your lines (spans) are connected to the public operator. The timing cable should make sure that the clock received on one port from the public operator should be used as transmit bit-clock on all of the other ports, no matter on which card.
Unfortunately this decades-old Digium timing cable approach seems to suffer from some problems.
bursty bit clock changes until link is up
The first problem is that downstream port transmit bit clock was jumping around in bursts every two or so seconds. You can see an oscillogram of the E1 master signal (yellow) received by one TE820 card and the transmit of the slave ports on the other card at https://people.osmocom.org/laforge/photos/te820_timingcable_problem.mp4
As you can see, for some seconds the two clocks seem to be in perfect lock/sync, but in between there are periods of immense clock drift.
What I'd have expected is the behavior that can be seen at https://people.osmocom.org/laforge/photos/te820_notimingcable_loopback.mp4 - which shows a similar setup but without the use of a timing cable: Both the master clock input and the clock output were connected on the same TE820 card.
As I found out much later, this problem only occurs until any of the downstream/slave ports is fully OK/GREEN.
This is surprising, as any other E1 equipment I've seen always transmits at a constant bit clock irrespective whether there's any signal in the opposite direction, and irrespective of whether any other ports are up/aligned or not.
But ok, once you adjust your expectations to this Digium peculiarity, you can actually proceed.
clock drift between master and slave cards
Once any of the spans of a slave card on the timing bus are fully aligned, the transmit bit clocks of all of its ports appear to be in sync/lock - yay - but unfortunately only at the very first glance.
When looking at it for more than a few seconds, one can see a slow, continuous drift of the slave bit clocks compared to the master :(
Some initial measurements show that the clock of the slave card of the timing cable is drifting at about 12.5 ppb (parts per billion) when compared against the master clock reference.
This is rather disappointing, given that the whole point of a timing cable is to ensure you have one reference clock with all signals locked to it.
The work-around
If you are willing to sacrifice one port (span) of each card, you can work around that slow-clock-drift issue by connecting an external loopback cable. So the master card is configured to use the clock provided by the upstream provider. Its other ports (spans) will transmit at the exact recovered clock rate with no drift. You can use any of those ports to provide the clock reference to a port on the slave card using an external loopback cable.
In this setup, your slave card[s] will have perfect bit clock sync/lock.
Its just rather sad that you need to sacrifice ports just for achieving proper clock sync - something that the timing connectors and cables claim to do, but in reality don't achieve, at least not in my setup with the most modern and high-end octal-port PCIe cards (TE820).
08 Sep 2022 10:00pm GMT