22 Nov 2026
 Planet Grep
Mattias Geniar: nginx HTTP/2 RCE (CVE-2026-123633, CVE-2026-123007): patch status per distro

Two bugs in nginx's HTTP/2 code allow remote code execution without logging in: CVE-2026-123633 and CVE-2026-123007 . Every nginx from 1.9.5 to 1.31.8 is affected when HTTP/2 is on. The fix is in nginx 1.30.7 (stable) and 1.31.9 (mainline), released on 18 November 2026. The best fix is to upgrade from nginx's upstream repo . It already has the fix. Otherwise check your distribution in the table below. Switch HTTP/2 off until it has a fix.
22 Nov 2026 12:32pm GMT
Mattias Geniar: PHP security release of 19 November 2026: patch status
PHP released 8.2.36, 8.3.37, 8.4.28 and 8.5.13 on 19 November 2026. The security advisories went public at 14:05 UTC. They fix 17 security bugs, 7 of them CRITICAL (ChangeLog ). The worst one affects PHP-FPM when the web server in front of it reuses FastCGI connections. See Am I affected? , then patch .
22 Nov 2026 12:32pm GMT
Lionel Dricot: The Simulation We Are Living In
The Simulation We Are Living In
Or How We Are Roleplaying a Successful Capitalist Life
Nat wrote a piece about Copilot being the peak-oil of high technology.
I agree with Nat's anger and the feeling of disorientation.
I've lived through multiple tech bubbles and, in all of them, the "believers" were a minority. In fact, you always had a minority of vocal believers opposing "serious seasoned people". The vast majority of the world didn't care much about the bubble or were exposed to it only through mainstream media. I've witnessed crazy stuff, including very influential and powerful people trying to "join the bubble". But if I disconnected, walked out of parties or meeting or went outside, I would see little trace of the bubble.
With the AI bubble, it seems like nearly everyone has been turned into a believer. Around me, every single conversation seems to be about AI, especially in non-tech circles. While my experience told me that most industries have always been very reluctant to adopt new technologies, we are witnessing a world where every big company, every CEO, every manager and every teacher/academic is suddenly voluntarily sabotaging a lifetime of experience to make sure we use an unreliable-by-design tool everywhere even though it barely existed a couple of years ago.
From a technological perspective, this is absolute nonsense.
Remember that everything is propaganda
Reading Chomsky helped me a lot here: I was reminded that everything we read, everything we
hear is propaganda. Those are not facts. Those are intentionally designed messages to turn us into believers.
The current propaganda is geared toward making chatbots the new norm because this is our current consumption bubble and the system always needs something into which we will inject as much money as we can.
According to Chomsky, propaganda means you should always invert cause and consequence:
- People don't write good things about vibecoding because it works for them, they believe it works for them because they read and need to write good things about it.
- Chatbots are not inevitable: people try to convince themselves they are inevitable to justify using them.
We now know that, at least for Open Source programming, AI doesn't make you more productive. But it makes you believe that you are. Just like drugs make you believe you are smart and alcohol makes you believe that you are a good driver. The productivity of LLMs is not a fact. But the intoxication is real.
The propaganda is not even subtle! It is transparent and sometimes borderline parodic, like the time when an Anthropic employee recognized that it was stupid to have an AI managing your business but you had to prepare for that world because you had no choice.
Bad managers are leading the world
In the end, this is mainly propaganda to make us believe that we live in the world as seen through the eyes of Juliuses (my word for what Ed Zitron calls "the business idiots").
Juliuses are people who don't even understand that there are things to understand. They don't even have access to that part of consciousness where you truly understand a concept. They live in a blurry state of consciousness where they only care about the "next action". They
don't have any notion of "rationality" or "logic". They believe intuition is as good as scientific knowledge ("Oh, you are Sagittarius? That explains why you speak like that!")
Feynman famously said that, to solve a problem, you need to:
1. Write the problem down
2. Think hard
3. Write the solution
As Feynman said, most people do everything they can to skip steps 1 and 2.
They really want to go straight to 3. That's why AI is wonderful: it even does what looks like step 3 for you if you are not qualified enough to check.
But it cannot work for one simple reason: if your problem is not clear, you will never have a good solution. Writing code is 90% about defining the problem and all its edge cases. Writing code is taking decisions, by essence. The same can be said for legal contracts. Lawyers are people who write a form of code where they want to account for every conceivable situation and decide what to do before it happens.
We are delegating our free will to remove accountability
In his book "Éloge du bug", Marcello Vitali-Rosati draws an analogy with the genie of Aladdin. In the story, Aladdin asks for "beautiful clothes" and the genie obeys. Or does he?
In fact, the genie makes a lot of decisions about what "beautiful clothes" are. Would they be clothes that "look expensive"? That "follow the norms" or, on the contrary, that are completely new and creative? Without realizing it, Aladdin completely gave up on his free will and his own identity. From that moment, Aladdin is just a puppet in the genie's hands.
The whole point of vibecoding is "let an opaque proprietary algorithm controlled by a huge economic entity take all the decisions about what it thinks I want now and how I should live my future". It cannot work if there's some accountability in play. Nobody would sign a randomly generated contract. So the trick is to remove accountability.
We have all encountered examples of "I'm not wrong, this is what AI told me". By communicating a lot about ChatGPT mistakes and saying they take them seriously, OpenAI is reinforcing the sense that you are not accountable for blindly obeying ChatGPT. You can delegate your responsibilities to them. The whole discourse about "inevitability" is only that: it is about removing liability and responsibility. "Of course I signed that random contract. Everyone does it. It is inevitable. And they will make the next contract better."
Juliuses live in a world where they do everything to get immediate benefits and avoid accountability. That's what modern businesses are built for: you get the money as an individual but the company pays fines and nobody goes to jail, even if you kill millions with a defective product (except if you mess with shareholders money,then you are liable). At worst, you are fired (with a golden parachute if you are high enough on the ladder).
In that regard, LLMs are a terrible engineering tool. After all, they have random output, are unreliable by design and act randomly. But they are perfect business tools because they remove agency, free will and liability.
The successful capitalist roleplay
On his blog, Ron Gilbert quotes "AI feels amazing when it's talking about a subject you know nothing about, but is laughably wrong when you do". The solution is thus simple: make sure nobody knows anything about anything anymore.
The social media bubble was led by marketers and their view of the world. They wanted us to believe that everybody was a marketer, that our life should be marketed ("personal branding"), that every happy moment was there to "advertize" how cool we are. People do not meet to have fun, they meet to take pictures to convince the world they had fun.
The cryptocurrency bubble was led by financiers. They told us that everything is an asset and everyone is a trader. We should all become rich while selling assets to each other. The AI bubble is led by management. Everyone should be the manager of a team of "agents" that blindly obey and agree to everything we say.
The capitalist system is successfully selling us the fact that, after our long hours at a shitty job, if we are lucky enough to have one, we can roleplay a very successful capitalist life on a small bright screen. Indeed, they were wrong about the VR bubble! No need for immersive virtual reality. We are intoxicated enough by the capitalist roleplay to break our necks while spending our nights looking at a screen smaller than those Terry Gilliam envisioned in Brazil. At least, in Brazil, they still had real keyboards!
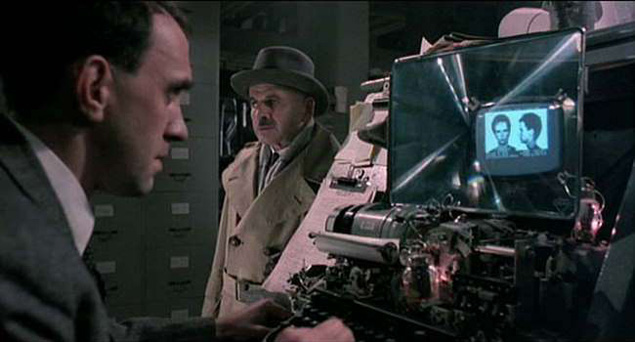 Still from the movie "Brazil" (by Terry Gilliam)
Remember the pods in The Matrix? Turns out small addictive screens do the job. We even pay for them! Neo is not fighting Agent Smith with a cool leather jacket and guns. He wears a lousy t-shirt and is ignored, frowned upon or, at best, offered social skills therapy.
When you understand that this is all propaganda, a fiction, a shared dream (or a nightmare), that business people are all lying through their teeth because, for them, it's part of the game, it gradually starts to make sense.
But it is no less frightening…
About the author
I'm Ploum, a writer and an engineer. I like to explore how technology impacts society. You can subscribe by email or by rss. I value privacy and never share your adress.
I write science-fiction novels in French. For Bikepunk, my new post-apocalyptic-cyclist book, my publisher is looking for contacts in other countries to distribute it in languages other than French. If you can help, contact me!
22 Nov 2026 12:32pm GMT
Planet Debian
Daniel Baumann: Debian: Modernizing iperf/iperf3 and introducing fireperf
Recently I spend some time on modernizing the packaging of the Internet Protocol bandwidth measuring tools iperf and iperf3 in Debian, as well as uploading fireperf to Debian.
Modernizing iperf
sudo apt install -yU iperf-server and you're donePreviously, src:iperf only built iperf. If you wanted to run an iperf server, you had to do it on your own, i.e. there was no systemd service for that.
Apart from tidying the Debian package, src:iperf now builds the new iperf-client and iperf-server packages, the latter contains the systemd and ufw integration. iperf-server runs with a dynamic systemd user and systemd service hardening.
The iperf package is now a transitional package, that also cleans up any leftovers from before the package split into iperf-client and iperf-server (e.g. when upgrading from trixie to forky).
For historical reasons, iperf2 is packaged in debian as iperf, not iperf2. Now the iperf packages have provides for iperf2, iperf2-client, and iperf2-server respectively (so they can be installed by these names too).
Updated iperf packages are available in sid, and backports for trixie are available at Debian Fast Forward.
It might make sense in the future…
given that iperf2 and iperf3 are completely different tools with different advantages and disadvantages depending on the use-case
therefore the one is not replacing the other (iperf2 in general is the better tool than iperf3, eventhough the common misconception is that iperf3 is supposedly better than iperf2 because the number 3 is greater than the number 2)
…to maybe rename iperf to iperf2 to match both upstream naming and also to harmonize the packaging of iperf2 with other distributions.
Modernizing iperf3
sudo apt install -yU iperf3-server and you're donePreviously, src:iperf3 only built iperf3. If you wanted to run an iperf3 server, iperf3 had a debconf yes/no question which would then start one iperf3 server on the default port 5201.
Apart from tidying the Debian package, src:iperf3 now builds the new iperf3-client and iperf3-server packages, the latter contains the systemd and ufw integration. iperf3-server runs with a dynamic systemd user instead of the previous local system account, and has systemd service hardening.
Since iperf3 (contrary to iperf, also see here and here for iperv vs. iperf3) does not allow using multiple connections on the same port, you have to run multiple iperf3 servers, each on their own port, in order to serve more than one client at the time.
The old debconf question for enabling a single iperf3 server has been removed as well as the obsolete sysvinit integration.
In order to allow running multiple iperf3 servers at the same time (but on different ports), iperf3-server now contains a systemd service template so you can enable multiple iperf3 servers (e.g. 3 servers on subsequent port numbers, but you can run as many as you want on any ports you like) either manually with:
sudo systemctl enable --now iperf3-server@5201sudo systemctl enable --now iperf3-server@5202sudo systemctl enable --now iperf3-server@5203or by using debconf interactively to do it automatically for you (which defaults to one instance on port 5201):
sudo dpkg-reconfigure -p low iperf3-serveror by using debconf non-interactively to do it automatically for you:
TMPFILE="$(mktemp)"echo "iperf3 iperf3-server ports string 5201 5202 5203" > ${TMPFILE}cat "${TMPFILE}" | sudo debconf-set-selectionsdpkg-reconfigure -fnoninteractive -pcritical iperf3-serverrm -f "${TMPFILE}"The iperf3 package is now a transitional package, that also cleans up any leftovers from before the package split into iperf3-client and iperf3-server.
Updated iperf3 packages are available in sid, and backports for trixie are available at Debian Fast Forward.
Introducing fireperf
sudo apt install -yU fireperf-clientsudo apt install -yU fireperf-server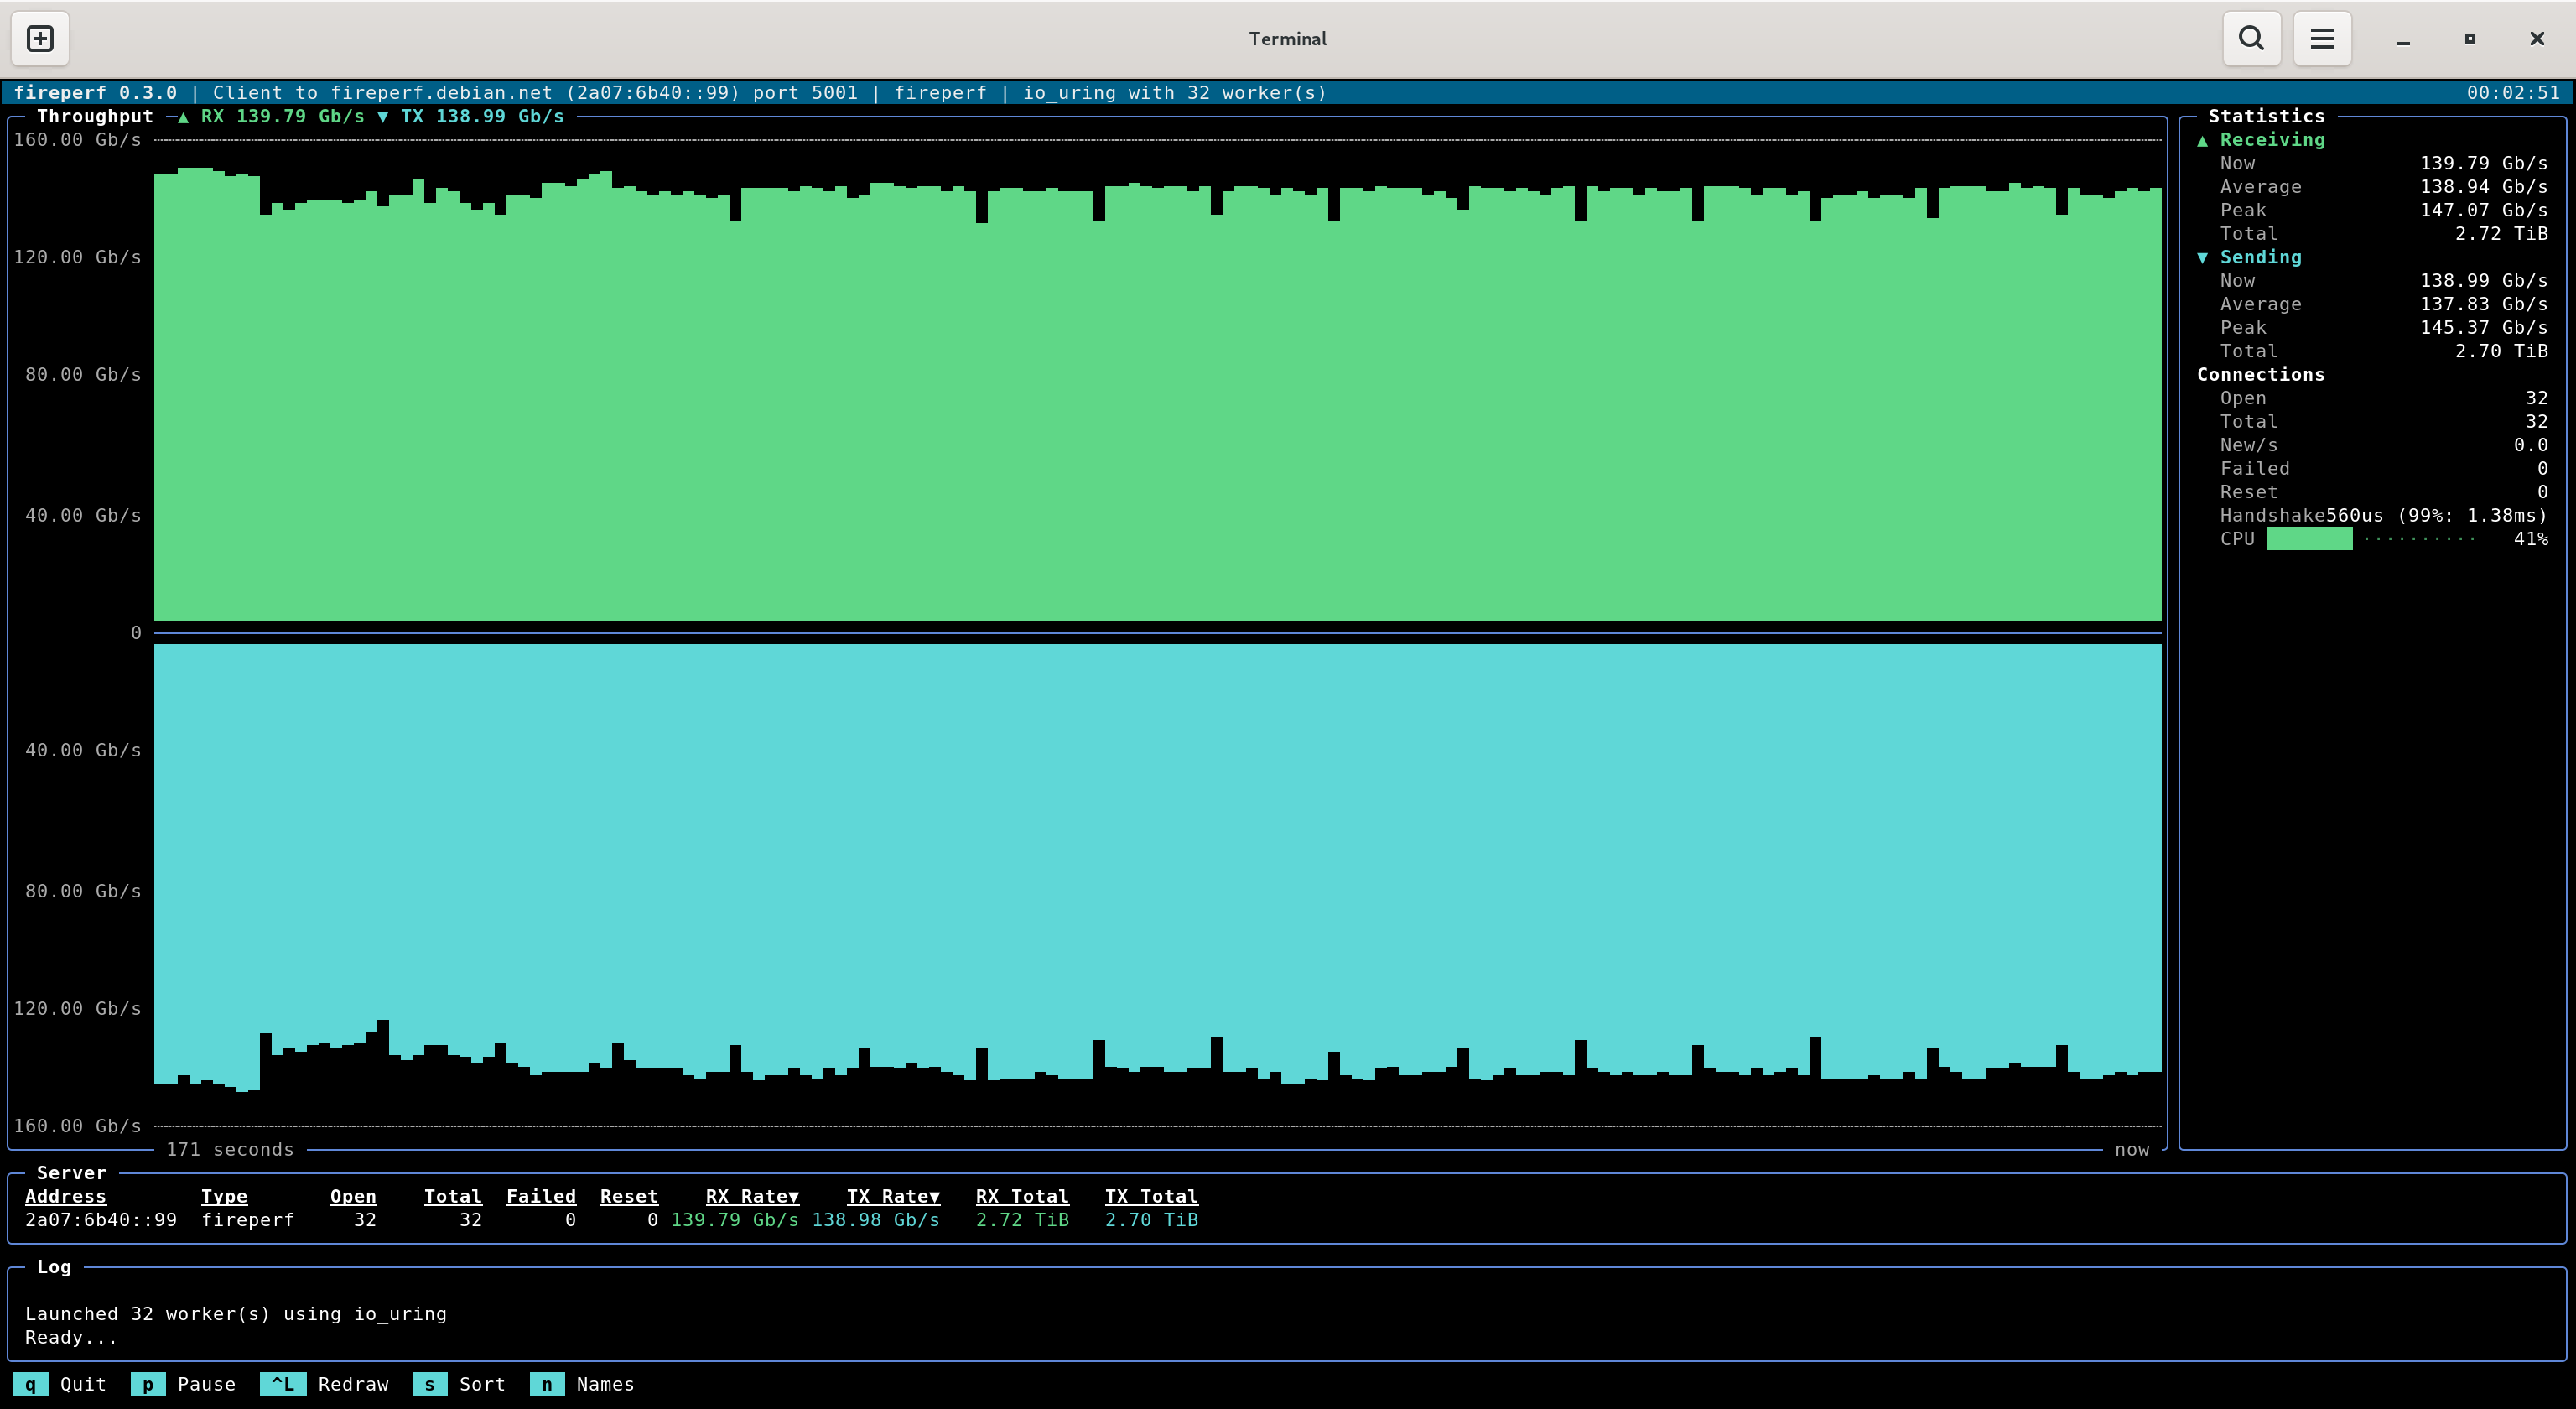
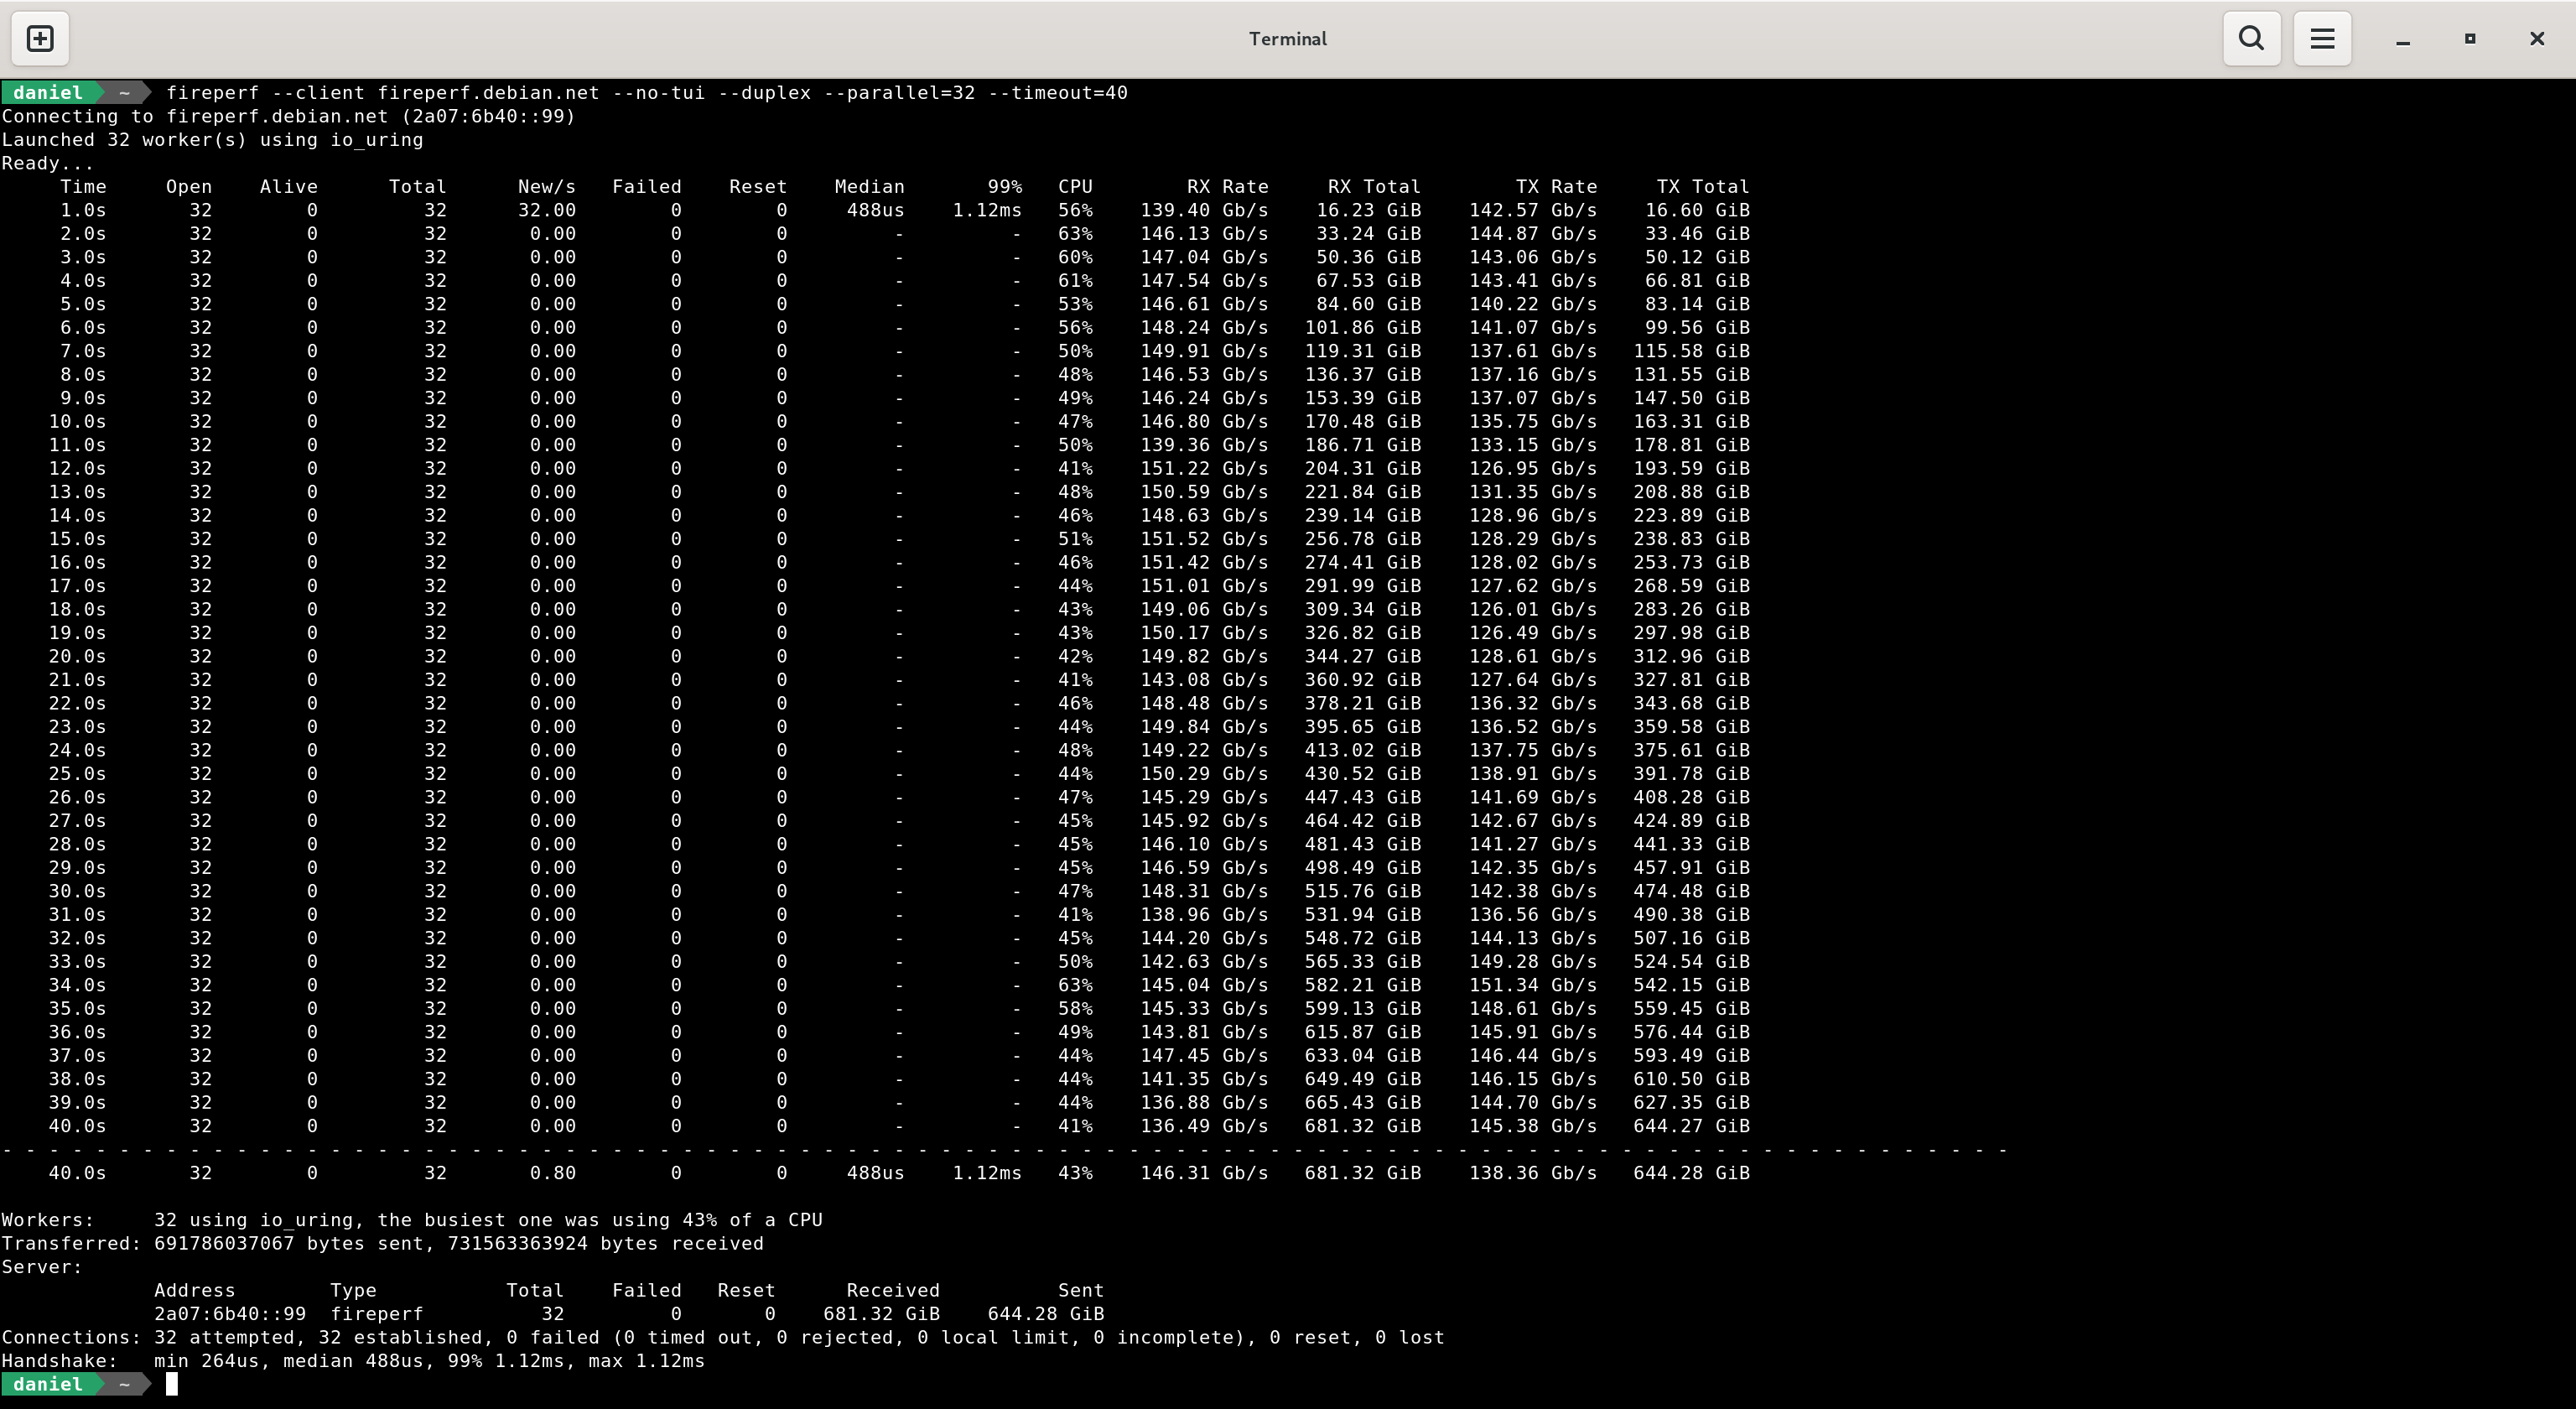
fireperf is a modern take on the iperf3 network performance and stress-testing tool under the IPFire project umbrella:
measures upload or download individually, or concurrent upload and download
allows to serve many clients in parallel (on the same port)
allows to use many workers in parallel (for maxing out bandwith of servers with LACP instead of ECMP)
allows to use and track many connection sessions in parallel (for maxing out firewalls)
can also be used as a client for both iperf and iperf3 (autodetecting the target)
can also be used as a iperf3 server
can output results in JSON
has a live graph (ncurses)
uses less CPU ressources on both the client and the server (io_uring, zerocopy, …)
fireperf packages are in sid, and backports for trixie are available at Debian Fast Forward.
Happy bandwidth measuring!
22 Nov 2026 6:19am GMT
Russ Allbery: Review: Whalesong
Review: Whalesong, by Miles Cameron
| Series: | Arcana Imperii #3 |
| Publisher: | Saga Press |
| Copyright: | 2025 |
| Printing: | August 2026 |
| ISBN: | 1-6682-1021-5 |
| Format: | Kindle |
| Pages: | 362 |
Whalesong is a far-future semi-military science fiction novel and the third in the Arana Imperii series, not counting the story collection Beyond the Fringe. It did an adequate job of jogging my memory of previous events, but I kind of wish I had re-read the series before reading this entry.
Artifact Space and Deep Black were closely linked, almost one novel in two volumes. Whalesong is not. There is a frame story featuring Nbaro and Dorcas and an introductory story featuring Nbaro's friend Qaqqaq, but the protagonist for most of the novel is a minor character from the earlier books: Thor Storkel.
After Deep Black, Storkel mustered out of the DHC and purchased the captured New Texas ship Silver Star. An arrangement with Morosini involving secret reserve status let him keep a hidden weapon system. His plan was to become an independent trader, working for himself and going wherever he wanted.
This did not go as smoothly has he planned. Keeping a ship running was expensive in numerous ways that had never previously been his problem, and the end of the Non-War meant a glut of ships and crews trying to do the same thing he was doing. His PTSD and associated paranoia from his time on the Athens didn't help. As Whalesong opens, Storkel is running the Silver Star by himself (a horrible idea), trying to find both cargo he can make money on and crew he can afford to hire.
Also the antigravity is weirdly glitchy, and he's fairly sure the ship's sub-AI doesn't like him.
Whalesong feels like an interlude in the larger series. Although there are important connections to the larger series plot, the advancement of that plot is limited and mostly happens in the background. Instead, this is more of a merchant adventure with some found family vibes, returning to military SF and larger political concerns only late in the book. It felt like Cameron needed to move pieces into place for the next major plot development and decided to use that interlude to tell a smaller character story.
The appeal of this book is therefore going to depend on how much you like the characters. Storkel is an improviser and a tinkerer, the kind of person who sets up an elaborate set of tools and macros and alarms to partly automate his job without letting go of any piece of it. The primary tension in the story is Storkel's paranoia and the increasing evidence that it is justified, that there is something fundamentally wrong with his ship. By himself, Storkel is a little too intense. Thankfully, he gradually accumulates crew over the course of the story, and that settles him down and adds some enjoyable character interactions. Dorcas, when he shows up, is exactly like Dorcas in the previous books; if you liked him before, you'll still like him here.
This is the kind of book that I enjoyed while reading and then promptly forgot most of as soon as I finished it. The details of Storkel's attempt to become an independent trader and how it is slowly hijacked by the series plot is competent, but not more than that (at least for me). The one real complaint that I have is that Nbaro, even when mostly off-camera, continues to be hypercompetent and central to DHC politics in a way that I found a bit unbelievable. Otherwise, the worst that I can say is that this book never grabbed me like Artifact Space did. I happily turned the pages, but I probably won't read it again.
After reading this book, I re-read both Artifact Space and Deep Black and greatly enjoyed both of them. I haven't felt any similar desire to re-read this one.
If you're following the series, there's no reason to skip Whalesong, but I doubt it will be your favorite.
Followed by The Alien's War, which will hopefully have the sort of major plot advancements hinted at by the title. At the time I am writing this review, it is scheduled for publication in September of 2027 in the UK and does not yet have a publishing schedule in the US.
Rating: 7 out of 10
22 Nov 2026 4:10am GMT
21 Nov 2026
Planet Debian
Andrew Cater: Back in Cambridge - this time for media testing / media release 20261121
I never did quite finish the blog posts for mini-DebConf Cambridge at ARM - sorry, but life got in the way. Videos are now available in the Debian video archives.
Back in Cambridge for release of Debian 13.8 - testing is going well. A couple of new bugs - speech install doesn't *depend* on a working screen but it surely does help as a sighted user :)
Six of us here, including Richard who is new to the process and pham who has helped with ARM v7 remotely.
All good - and glad to be here.
21 Nov 2026 3:59pm GMT
14 Nov 2026
FOSDEM 2027
FOSDEM 2027 Accepted Stands: complete list
This year, we've received 256 submissions, taking a decision was not easy and harder then expected.
After we released a week ago the first batch of stands, we are now releasing the complete list of stands. We have some additions and also some merges.
- 0 A.D.
- ALCASAR & Mageia.Org
- AlmaLinux OS Foundation
- Apache Software Foundation
- Ariel OS
- Automotive Grade Linux, OpenEmbedded, & The Yocto Project
- Bareos
- BeWelcome: The Open-Source, Non-Profit Hospitality Network
- Bor & Kiwi TCMS (Sunday)
- CEPH
- Checkmk - "You own it - Checkmk monitors it!"
- CISO Assistant & BunkerWeb
- ClickHouse
- Cloud Native Computing Foundation (CNCF)
- Codeberg and Forgejo
- Collabora Office
- conda-forge, conda, Pixi and friends
- DBeaver
- Delta Chat - Decentralized & Secure Messaging
- Digital Public Goods
- Drupal CMS: the open-source CMS, built by a global community
- Eclipse Foundation
- Ente Technologies Inc
- F-Droid
- Fedora Project
- FLOSSK - Free Libre Open Source Software Kosova (Sunday)
- Foreman
- FOSS for All
- FOSS United Foundation & fundingjson (and FLOSS/fund)
- FOSSASIA
- Framasoft & PeerTube
- Free Android World: From Hardware to Apps: An Open, Sustainable Ecosystem
- Free Software Foundation Europe
- FreeBSD
- Gentoo Linux
- GitLab
- GNOME
- GNU Radio
- Grafana
- Grist (Saturday)
- grommunio: The enterprise open source project for E-Mail, Groupware and Collaboration
- Hex sticker booth by NLnet Foundation
- Homebrew
- Infostand on amateur radio and open source radio technology
- Internet Archive Europe (Sunday)
- Jenkins (Saturday)
- Joplin
- KDE
- KiCAD + FreeCAD
- Kotlin Community Stand
- Let's Encrypt
- Libre Space Foundation (LSF)
- Libreoffice
- Linaro - Open Source Embedded Testing
- LineageOS, CalyxOS, /e/OS
- Linphone
- Linux on Mobile
- Luanti
- MariaDB Server
- Mastodon
- metal-stack
- Minodu Local Community Network
- MIT App Inventor
- Mozilla
- Nerdearla
- Nextcloud: A self-hosted, open file sync & communication platform
- Nitrokey
- Nix and NixOS Stand & Mobile Nixos
- ntop & NetXMS: Two ways to see a network
- Nura (formely known as postmarketOS)
- Open Culture Foundation + Taiwan Open Source Community
- Open-Source Firmware Foundation
- OpenBao & OpenTofu
- OpenFlexure Microscope
- openHAB
- OpenInfra Foundation
- OpenNebula
- OpenRemote
- OpenScan - 3D Scanner
- OpenSearch Project
- OpenSSL Foundation
- openSUSE Project
- OurSQL Foundation
- Passbolt
- Percona
- PINE64 Community (Sunday)
- PostgreSQL
- Proxmox VE - PBS - PDM
- Python & Django
- Qubes OS + Genode OS
- QuestDB + OpenC3 COSMOS: Open Mission Control for Satellites (Saturday)
- ReactOS
- revela & Borg
- RIAT & decentral.community stand
- RiceWM - Complete Linux Desktop in the Browser
- RISC-V International
- Rust
- Samba and Himmelblau
- Software Freedom Conservancy
- SOGo Webmail
- Sovereign Identity Everywhere: Keycloak, FreeIPA, privacyIDEA, & SSSD
- Stalwart Mail and Collaboration Server (Saturday)
- Star Labs
- T2 Linux
- The Debian Project
- The Matrix.org Foundation
- Thunderbird
- TidesDB
- TinyGo, Yzma & GoEducation
- Tor / Tails / NoScript
- Trifecta Tech Foundation
- Ubuntu & Ubports
- Unicode Consortium
- Valkey
- VictoriaMetrics
- VideoLAN
- Weblate
- Wikidata
- Wireshark
- wolfSSL
- Women of Open Source
- XCP-ng
- Xen Project
- XMPP & Realtime Lounge
- XWiki & CryptPad
- Zabbix
14 Nov 2026 11:00pm GMT
07 Nov 2026
FOSDEM 2027
FOSDEM Junior Call for Participation
Proposals for FOSDEM Junior can now be submitted!
FOSDEM Junior is a specific track to organise workshops and activities for children from age 7 to 17 during the FOSDEM weekend. These activities are for children to learn and get inspired about technology and open source.
Last year's activities included microcontrollers, game development, embroidery, python programming, mobile application development, music, and data visualization. If you are still unsure if your activity fits FOSDEM Junior, feel free to reach out so we can assist you.
It is important for the children to remain inspired when they return home. So make sure that you give the children something after your activity. This can either be that they can continue working on their project that they worked on during the activity, or in the form of goodies or certifications. Also, if necessary, include information about where the children and their guardians can find resources and tutorials about your project. This is another step towards making sure they continue their technical journey when they return home.
Each room has a maximum capacity of 48 seats, but will be capped at 30 children per activity by the organisers. This is to ensure there is enough seating for both children and their guardians.
Submission process
Please submit your proposals at https://fosdem.org/submit by the 7th of December 2026. If you already have an account from a previous year, you should reuse it so all recorded FOSDEM contributions are associated with your profile.
When submitting your proposal, select 'Junior' from the track drop-down menu. Write the desired duration and maximum capacity into the proposal so we can take that into account when planning. Also, please include whether you need additional volunteers available during your activity.
Requirements
The conference language is English. All content must relate to Free and Open Source Software. By participating in the event you agree to the publication of your slides and other content made available under the same licence as all FOSDEM content (CC-BY). By participating in FOSDEM you are required to adhere to the Code of Conduct.
The FOSDEM Junior track is not recorded.
07 Nov 2026 11:00pm GMT
FOSDEM Accepted Stands
This year, we've received 256 submissions, and the number of high-quality projects is steadily increasing. Attached is the first batch of booths that have been accepted.
A few more booths will be added in the coming days; another post will follow regarding this.
- 0 A.D.
- AlmaLinux OS Foundation
- Apache Software Foundation
- Ariel OS
- Automotive Grade Linux, OpenEmbedded, & The Yocto Project
- Bareos
- BeWelcome: The Open-Source, Non-Profit Hospitality Network
- Bor & Kiwi TCMS (Sunday)
- CEPH
- Checkmk
- ClickHouse
- Cloud Native Computing Foundation (CNCF)
- Codeberg and Forgejo
- conda-forge, conda, Pixi and friends
- Delta Chat - Decentralized & Secure Messaging
- Digital Public Goods
- Drupal CMS: the open-source CMS, built by a global community
- Eclipse Foundation
- Ente Technologies Inc
- F-Droid
- Fedora Project
- FLOSSK - Free Libre Open Source Software Kosova (Sunday)
- Foreman
- FOSS for All
- FOSSASIA
- Framasoft & PeerTube
- Free Android World: From Hardware to Apps: An Open, Sustainable Ecosystem
- Free Software Foundation Europe
- FreeBSD
- Gentoo Linux
- GitLab
- GNOME
- GNU Radio
- Grafana
- Grist (Saturday)
- grommunio: The enterprise open source project for E-Mail, Groupware and Collaboration
- Hex sticker booth by NLnet Foundation
- Homebrew
- Infostand on amateur radio and open source radio technology
- Internet Archive Europe (Sunday)
- Jenkins (Saturday)
- Joplin
- KDE
- KiCAD + FreeCAD
- Kotlin Community Stand
- Let's Encrypt
- Libre Space Foundation (LSF)
- Linaro - Open Source Embedded Testing
- LineageOS, CalyxOS, /e/OS
- Linphone
- Linux on Mobile
- Luanti
- MariaDB Server
- Mastodon
- metal-stack
- Minodu Local Community Network
- MIT App Inventor
- Nerdearla
- Nextcloud: A self-hosted, open file sync & communication platform
- Nitrokey
- Nura (formely known as postmarketOS)
- Open Culture Foundation + Taiwan Open Source Community
- Open-Source Firmware Foundation
- OpenBao & OpenTofu
- OpenFlexure Microscope
- openHAB
- OpenInfra Foundation
- OpenNebula
- OpenRemote
- OpenScan - 3D Scanner
- OpenSearch + Valkey
- OpenSearch Project
- OpenSSL Foundation
- openSUSE Project
- OurSQL Foundation
- Passbolt
- Percona
- PINE64 Community (Sunday)
- PostgreSQL
- Proxmox VE - PBS - PDM
- Python & Django
- Qubes OS + Genode OS
- QuestDB + OpenC3 COSMOS: Open Mission Control for Satellites (Saturday)
- ReactOS
- RIAT & decentral.community stand
- RiceWM - Complete Linux Desktop in the Browser
- RISC-V International
- Rust
- Samba and Himmelblau
- Software Freedom Conservancy
- SOGo Webmail
- Stalwart Mail and Collaboration Server (Saturday)
- Star Labs
- T2 Linux
- The Debian Project
- The Matrix.org Foundation
- Thunderbird
- TidesDB
- TinyGo, Yzma & GoEducation
- Tor / Tails / NoScript
- Trifecta Tech Foundation
- Two ways to see a network
- Ubuntu & Ubports
- Unicode Consortium
- VictoriaMetrics
- VideoLAN
- Weblate
- Wikidata
- Wireshark
- wolfSSL
- Women of Open Source
- XCP-ng
- Xen Project
- XMPP & Realtime Lounge
- XWiki & CryptPad
- Zabbix
07 Nov 2026 11:00pm GMT
Planet Lisp
vindarel: CSV parsing in Common Lisp, data manipulation by columns with data frames
Parsing CSV files is a common task. What are our options? We'll start with cl-csv, add the data-table library, and present lisp-stat's data frames.
This is another contribution to the Common Lisp Cookbook so you should read it there as this is where it will get updates.
With a very simple dataset we could split CSV lines manually (subseq, split-sequence, str:split, cl-ppcre...) but when a column contains the separator, a library starts to be useful.
And a library will be even more so to help us manipulate columns by name, to use tabular data structures, to automatically infer the columns' types, and more.
I recommend:
- for simple use, try
cl-csv - if you'll do statistics or want a good dataframes library, go for
lisp-stats - to work with large datasets, see
cl-csv's:row-fnargument. - for the fastest parsing, maybe
fare-csv, or DuckDB with cl-duckdb, which can also ingest much more file formats than CSV, including Excel.
Table of Contents
- Introduction: our test files
- Parsing with cl-csv
- cl-csv and data-table: column names, column types, columns manipulation
- lisp-stat's Data Frame
- Utilities
- See also
Introduction: our test files
Let's work together with this simple CSV file, persons.csv:
Alice,7,1
Bob,77,0
The separator is , (often the default in libraries).
For simplicity, the file doesn't contain a headers row.
This second file, persons2.csv, contains headers:
name,age,lisper
Alice,7,1
Bob,77,0
Parsing with cl-csv
The cl-csv library is on Quicklisp.
(ql:quicklisp "cl-csv")
It allows to parse data from a string, from a file, or from any stream.
It may not be the fastest, but it has a decent set of quality-of-life features.
Please go read its README, as we don't illustrate some of its features here. For example, it supports multiline quoted data, we can set the quote character, it has good error messages (line and column number, char index), etc.
For reference, this is the function signature of cl-csv:read-csv (C-c-s on Slime):
(cl-csv:read-csv stream-or-string :csv-reader csv-reader
                                             :row-fn row-fn
                                             :map-fn map-fn
                                             :data-map-fn data-map-fn
                                             :sample sample
                                             :skip-first-p skip-first-p
                                             :separator *separator*
                                             :quote *quote*
                                             :escape *quote-escape*
                                             :unquoted-empty-string-is-nil *unquoted-empty-string-is-nil*
                                             :quoted-empty-string-is-nil *quoted-empty-string-is-nil*
                                             :trim-outer-whitespace *trim-outer-whitespace*
                                             :newline *read-newline*
                                             :escape-mode *escape-mode*)
Parsing from a string
To parse from a string, just use cl-csv:read-csv:
(cl-csv:read-csv "Alice,7,1
Bob,77,0")
;; =>
(("Alice" "7" "1") ("Bob" "77" "0"))
It returns a list of lists, values are all strings.
Parsing from a file
Also use cl-csv:read-csv but give a pathname as argument, not only the filename as a string.
(cl-csv:read-csv #P"persons.csv")
;; =>
(("Alice,7,1") ("Bob,77,0"))
What happens if you omit the #P?
(cl-csv:read-csv "persons.csv")
;; =>
(("persons.csv"))
this looks strange and no, there is no bug ;)
To parse from a stream, see the library's documentation.
Using another separator
Is ; the columns separator? Use cl-csv:read-csv's :separator argument, or the global cl-csv:*separator* parameter.
For a Tab, use #\Tab.
(defparameter *csv-string* "Alice;7;1
Bob;77;0")

(cl-csv:read-csv *csv-string* :separator #\;)

;; OR

(let ((cl-csv:*separator* #\;))
  (cl-csv:read-csv *csv-string*))
Skipping the first row of headers
With cl-csv, use :skip-first-p.
However, we'll use this row of headers as soon as we work with dataframes.
(cl-csv:read-csv "name,age,lisper
Alice,7,1
Bob,77,0"
 :skip-first-p t)
Returning a list of objects
So far, we got a list of lists with raw values as strings. We can do whatever we want with them. cl-csv has a :map-fn argument that we can use to create an object while parsing each row.
Let's re-use our class definition from the CLOS chapter:
(defclass person ()
  ((name :initarg :name :initform "")
   (age :initarg :age :initform nil)
   (lisper :initarg :lisper :initform nil)))
We can parse our CSV and return a list of objects at once:
(cl-csv:read-csv #p"persons.csv"
  :map-fn (lambda (values)
             (make-instance 'person :name (nth 0 values)
                                    :age (parse-integer (nth 1 values))
                                    :lisper (if (equal "1" (nth 2 values)) t nil))))
Observe that:
- we had to parse the age from a string to an integer ourselves
- our file doesn't have a headers row.
Streaming reads (for large files)
cl-csv provides the :row-fn parameter, that does something with each row and doesn't return them. This allows us to work with large datasets.
In this example, the :row-fn function has side-effects after each row was read and passed to it. Our function returns a result, the mean of ages.
(let ((sum-ages 0)
      (nb-ages 0))
  (cl-csv:read-csv #p"persons.csv"
                   :row-fn (lambda (values)
                             (incf sum-ages (parse-integer (nth 1 values)))
                             (incf nb-ages)))
  ;; Age mean:
  (/ sum-ages nb-ages))
Using cl-csv's reader information for debugging
cl-csv makes efforts to tell us where it is at its parsing. Here's where to find the bits of information that will help us during debugging.
In this dummy example, we'll observe cl-csv's hints:
;; this is uncomplete CSV, parsing will raise an error:
(cl-csv:read-csv "Alice,7,1
Bob,77,0
Oh?")

;; =>

The value
  NIL
is not of type
  STRING
when binding STRING
   [Condition of type TYPE-ERROR]

Restarts:
 0: [RETRY] Retry SLIME REPL evaluation request.
 1: [*ABORT] Return to SLIME's top level.
 2: [ABORT] Exit debugger, returning to top level.

Backtrace:
  0: (SB-IMPL::PARSE-INTEGER10 NIL 0 NIL NIL) [external]
  1: ((LAMBDA (VALUES)) ("oh?"))
  2: (CL-CSV::READ-CSV-WITH-READER #P"persons.csv" :CSV-READER NIL :ROW-FN #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}> :MAP-FN NIL :DATA-MAP-FN NIL :SKIP-FIRST-P NIL)
      Locals:
        #:.DEFAULTING-TEMP. = NIL
        CSV-READER = #<CL-CSV::CSV-READER LINE-IDX:2 CHARACTER-LINE-IDX:4 CHARACTER-IDX:23 "" {1203B99343}>

        ^^^^^ let's see more about this READER object.

        DATA-MAP-FN-P = NIL
        IN-STREAM = #<SB-SYS:FD-STREAM for "file /home/vindarel/cl-cookbook/persons.csv" {1203B96553}>
        MAP-FN-P = NIL
        #:NEW3 = #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}>
        #:NEW5 = NIL
        #:NEW7 = NIL
        #:NEW9 = NIL
        ROW-FN-P = T
        STREAM-OR-STRING = #P"persons.csv"
  3: (CL-CSV:READ-CSV #P"persons.csv" :ROW-FN #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}>)
We don't see everything. Click or press Enter on the CSV-READER that is on the 2nd backtrace:
#<CL-CSV::CSV-READER {1203B99343}>
--------------------
Class: #<STANDARD-CLASS CL-CSV::CSV-READER>
--------------------
 Group slots by inheritance [ ]
 Sort slots alphabetically  [X]

All Slots:
[ ]  AFTER-QUOTED?      = NIL
[ ]  BUFFER             = ""
[ ]  CHARACTER-IDX      = 23         <------------ useful: character index in the file
[ ]  CHARACTER-LINE-IDX = 4
[ ]  DATA-MAP-FN        = CL-CSV::MAP-EMPTY-STRING-TO-NIL
[ ]  ENTRIES            = #(#<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B98F93}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B99033}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B990D3}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B99173}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B99213}> #<CL-CSV::READ-DISPATCH-TABLE-ENTRY {1203B992B3}>)
[ ]  LINE-DATA          = #()
[ ]  LINE-IDX           = 2           <------------- useful: line index
[ ]  MAP-FN             = NIL
[ ]  PARSE-STREAM       = #<SB-SYS:FD-STREAM for "file /home/vindarel/cl-cookbook/persons.csv" {1203B96553}>
[ ]  READING-QUOTED?    = NIL
[ ]  ROW-FN             = #<FUNCTION (LAMBDA (VALUES)) {1203B956DB}>
[ ]  ROWS               = #()
[ ]  SKIP-ROW?          = NIL

[set value]  [make unbound]
Knowing the line causing an error and the file position is useful.
cl-csv and data-table: column names, column types, columns manipulation
data-table is a library by the same authors that brings a data structure that represents our CSV data.
A data table has rows of data, associates names to the columns, and guesses columns types.
Then, we can access values by row and column names, and manipulate columns (add data, take a substract etc).
We link cl-csv and data-tables together with the system cl-csv-data-table (defined in cl-csv).
(ql:quickload '("cl-csv" "data-table" "cl-csv-data-table"))
You don't need to go read its README, as it is poorly documented (only in tests).
We'll use the second CSV file, persons2.csv.
Let's parse it:
(cl-csv:get-data-table-from-csv #p"persons2.csv")
;; =>
#<DATA-TABLE:DATA-TABLE {1205D151C3}>
This returns a DATA-TABLE object. What is it? We can inspect it:
(inspect *)

The object is a STANDARD-OBJECT of type DATA-TABLE:DATA-TABLE.
0. COLUMN-NAMES: ("name" "age" "lisper")
1. COLUMN-TYPES: (STRING INTEGER INTEGER)
2. ROWS: (("Alice" 7 1) ("Bob" 77 0))
We observe:
- the data-table used our headers row
- the columns' types were inferred: "name" is a string, "age" and "lisper" are integers.
- in each row, the "age" and "lisper" fields were parsed to an integer.
Let's save our result to a parameter:
(defparameter *dt* **)
Get all rows with:
(data-table:rows *dt*)
Instead of accessing a column by its index, you can access it by its name.
Use data-table:data-table-value dt &key row row-idx col-name col-idx.
For example, what is the "name" of the first row?
(csv:data-table-value *dt* :row-idx 0 :col-name "age")
;; => 7
The library has more functions to manipulate columns and data-tables. We give them as a reference, and then we'll see how lisp-stat does it.
data-table:number-of-rows and data-table:number-of-columns
data-table-to-plists, plists-to-data-table
Add columns together with (csv:add-column dt column-name [default] [column-type] [index]).
Select columns with (csv:select-columns table column-names) to create a new data-table.
In this example, we create a new data-table object with only 2 columns. We also inverted their order.
(csv:select-columns *dt* '("age" "name"))
;; =>
#<DATA-TABLE:DATA-TABLE {1203F88213}>
CL-USER> (inspect *)

The object is a STANDARD-OBJECT of type DATA-TABLE:DATA-TABLE.
0. COLUMN-NAMES: ("age" "name")
1. COLUMN-TYPES: (INTEGER STRING)
2. ROWS: ((7 "Alice") (77 "Bob"))
> q
overlay-region new dt :col-idx col-idx :row-idx row-idx): "puts all values from new-dt into dt starting at row-idx col-idx".
make-sub-table parent :uri uri :lri lri :uci uci :lci lci:
Make a new data table from a subset of another data-table
   lci - low column index
   uci - upper column index (as per subseq 1 beyond the col you want)
   lri - low row index
   uri - upper row index (as per subseq 1 beyond the row you want)
Write a data-table to a file (or any stream) with (data-table-to-csv dt &optional stream)
All this is good, but today lisp-stat does this, and more.
lisp-stat's Data Frame
lisp-stat is a powerful library.
Lisp-Stat provides a statistical computing engine comparable to R, Python, Julia and Matlab. Its major differentiators are a true REPL based development environment, high performance and a single binary image that can be moved through the devops pipeline in a secure, safe and manageable way.
It integrates with Jupyter notebooks, to Quarto, it can load R datasets...
It's pretty good and actively used and developed.
It interests us for its Data Frame. You should go read its documentation ;)
Let's load the library:
(ql:quickload :lisp-stat)
We'll give a brief showcase. For this, we'll go to the ls-user package. It is "the package for you to do statistics work".
(in-package :ls-user)
We can read a CSV file with read-csv. This function is actually not the one we used so far with cl-csv, it is a wrapper around fare-csv.
So, using another separator is different, use fare-csv:*separator*.
(defparameter *persons-df* (read-csv #p"persons2.csv"))
;; => *PERSONS-DF*
It is important we used our file persons2.csv which contains the first row with column names.
We can start working with our data.
How do we get all names of our dataset? Simply like this:
LS-USER> (column *persons-df* 'name)
#("Alice" "Bob")
That's already interesting, isn't it?
Observe that: - the result is not a list, it is an array.
lisp-stat has a notation trick to access data in an even shorter way. For this, we need to define an "environment" with defdf:
LS-USER> (defdf persons (read-csv #p"persons2.csv"))
;; => #<DATA-FRAME (2 observations of 3 variables)>
Observe that: - we deliberately didn't use "*earmuffs*" around "persons" - the environment already gives us information: it saw 2 rows and 3 columns.
Now, we can get all names simply with:
LS-USER> persons:name   <----- you can use auto-completion, of course.
;; => #("Alice" "Bob")
all ages:
LS-USER> persons:age
;; => #(7 77)
We can inspect the shape of our data:
LS-USER> (head persons)

;;   NAME  AGE LISPER
;; 0 Alice   7      1
;; 1 Bob    77      0
Using another function, select, we can get all ages with:
LS-USER> (select persons t 'age)
;;                      ^^^ take the age of all rows
But with select we can get a subset of values:
LS-USER> (select persons '(0 1) 'age)
;;                         ^^^ our subset (it's all our data lol)
;; => #(7 77)
We can get values of some columns:
LS-USER> (columns persons '(age name))
;; => #(#(7 77) #("Alice" "Bob"))
We can get a high-level description of our dataset:
LS-USER> (describe persons)
PERSONS
  A data-frame with 2 observations of 3 variables

Variable | Type | Unit | Label
-------- | ---- | ---- | -----------
NAME     | NIL  | NIL  | NIL
AGE      | NIL  | NIL  | NIL
LISPER   | NIL  | NIL  | NIL
This shows that the columns' types were not inferred. Can we fix this?
LS-USER> (heuristicate-types persons)
NIL

LS-USER> (describe persons)
PERSONS
  A data-frame with 2 observations of 3 variables

Variable | Type    | Unit | Label
-------- | ----    | ---- | -----------
NAME     | STRING  | NIL  | NIL
AGE      | INTEGER | NIL  | NIL
LISPER   | BIT     | NIL  | NIL
Yes, now they are.
We can now manipulate columns: add, remove, rename, replace, transform... as well as rows: add, count, loop over (do-rows), map into, mask, filter...
Everything is in lisp-stat's documentation!
Utilities
Print data in an ascii table
We saw how to do that with lisp-stat's head function.
We have another solution with the cl-ansi-term library.
(ql:quickload '("cl-ansi-term"))
Its global nickname is term (warn: global nicknames are now legacy, prefer package-local nicknames).
We use term:table to print our tabular data.
(let ((csv (cl-csv:read-csv #p"persons2.csv")))
  (term:table csv))

;; =>
+-----+---+------+
|name |age|lisper|
+-----+---+------+
|Alice|7  |1     |
+-----+---+------+
|Bob  |77 |0     |
+-----+---+------+
It has a few more options. With many columns, you could display only a chosen set of columns. You can style cells programmatically, etc.
See also
- acknowldegment: read CSV files in CL on dev.to
- auto-text, automatic detection for text files (encoding, end of line, column width, csv delimiter etc). inquisitor for detection of asian and far eastern languages.
- CLAWK, an AWK implementation embedded into Common Lisp, to parse files line-by-line.
- redditors' feedback about duckdb, SBCL maintainer's fast parsing snippet.
07 Nov 2026 1:12pm GMT
26 Oct 2026
Planet Lisp
TurtleWare: Heavenly delights of hashing numbers under EQUALP
Table of Contents
Some time ago I decided to dust off my fast generic function dispatch work for ECL. But before merging that, I decided to optimize the table-based dispatch to have a good measure of how much better or worse it is and that opened a whole can of worms, including a new implementation of hash tables and hash functions.
I know, that's a new level of traversing absurdly nested rabbit holes. There are two good outcomes of this:
- Hash tables and generic function dispatch will be much faster soon
- I got inspired to write another blog post pertaining to Common Lisp
Regarding the first point, here are a few bar graphs generated using polyclot, a work-in-progress McCLIM tool for plotting data (less is better):
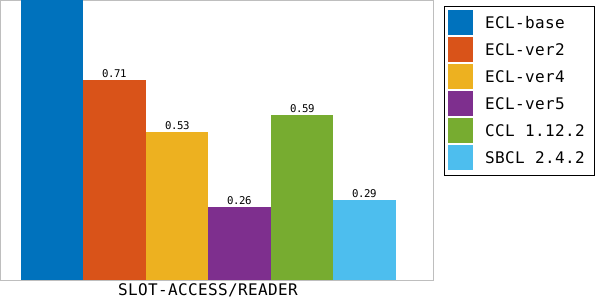
Figure 1: SLOT-ACCESS/READER - standard reader benchmark (work in progress).
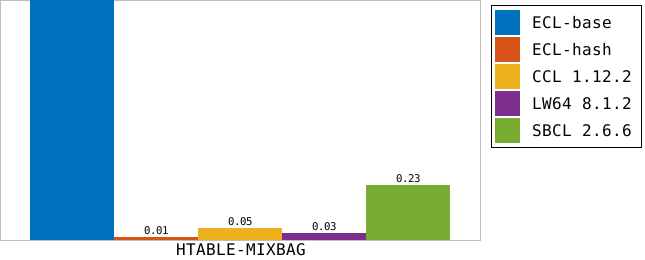
Figure 2: HTABLE-MIXBAG - EQUALP benchmark with randomized keys.
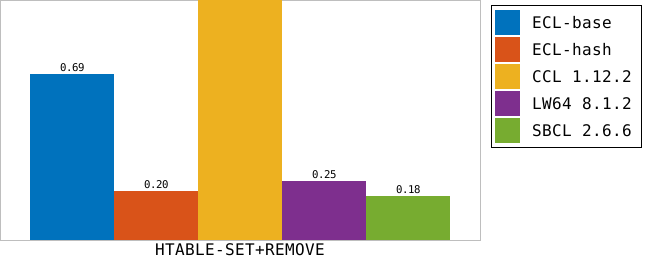
Figure 3: HTABLE-SETREM - benchmark for interleaved insert and remove.
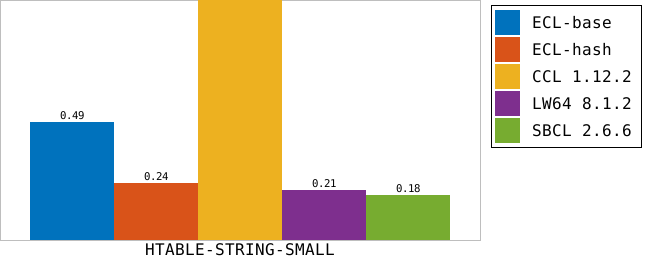
Figure 4: HTABLE-SMALL-STRING - EQUALP benchmark with short strings.
As for the second point, while working on hashing under various Common Lisp predicates, I decided to bite the bullet and fix a few ugly parts of ECL. Most notably consistent hashing of numbers under the predicate #'EQUALP. The topic is interesting enough to deserve a separate note. In this post I'm assuming binary floats (the float radix is two). This is the float representation used in ECL.
1. Hashing numbers - warmup
1.1. Recap: hash table tests and hash functions
A quick recap about Common Lisp and hash tables. The standard prescribes that conforming implementations must allow specifying the hash table tests EQ, EQL, EQUAL and EQUALP. The last test is interesting, because numbers with different representations are considered to be EQUALP when they are =. For example:
(equalp 1 1.0)           ; -> T
(equalp 1/2 0.5)         ; -> T
(equalp 1/3 (float 1/3)) ; -> NIL
(equalp 42 #C(42.0 0.0)) ; -> T
It is worth noting, that hashing can be lossy, but it can't be inconsistent with the test. In other words this is a conforming hash function under #'EQUALP:
;; (equalp 1 1.0)                        ; is true
;; (= (hash-equalp 1) (hash-equalp 1.0)) ; is true

(defun hash-equalp (x)
  (typecase x
    (real      42)
    (complex   (if (zerop (imagpart x))
                   (hash-equalp (realpart x))
                   13))
    (otherwise 15)))
While this function is not conforming, because there are objects that are the same under the test and have different hashes:
;; (equalp 1 1.0)                        ; is true
;; (= (hash-equalp 1) (hash-equalp 1.0)) ; is false

(defun hash-equalp (x)
  (typecase x
    (rational  1337)
    (float     7117)
    (complex   (if (zerop (imagpart x))
                   (hash-equalp (realpart x))
                   13))
    (otherwise 15)))
In other words, when two objects are equal under the supplied test, they must produce the same hash, but two objects having the same hash does not imply that they are equal under the supplied test.
Naive hashes, while conforming, miss the point. A good hashing function tries to produce different hashes for objects that are not equivalent under the predicate with a good bit distribution to ensure good hash table performance.
1.2. Recap: the numeric tower and mathematical equivalence
Common Lisp has a full numeric tower:
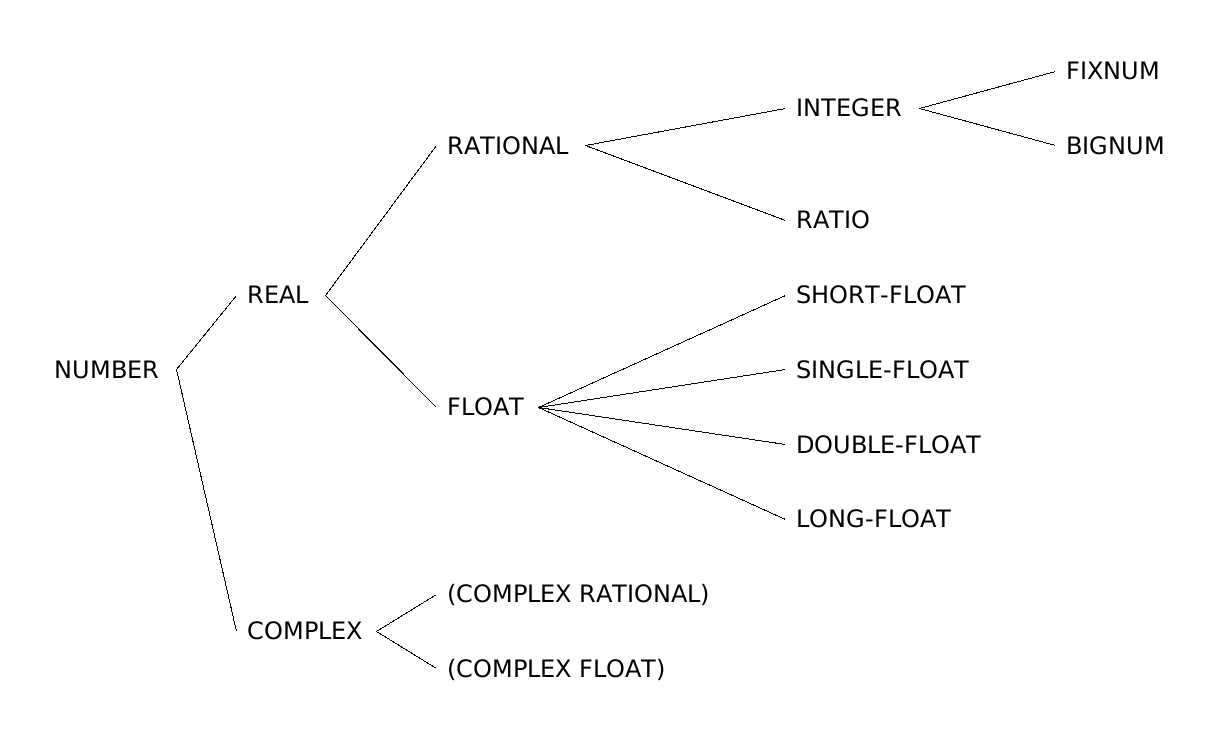
Figure 5: Common Lisp numeric tower.
Note that when complex floats have specialized representation, then there may be multiple subtypes specialized to single-float, double-float etc. Numbers are #'= to each other when their value is mathematically the same, regardless of the underlying representation. That's a wonderful quality when you do math :-).
This quality is not so wonderful, when you want to produce good hashes under the predicate #'EQUALP (that boils down to #'= for numbers). We need to construct a function that will produce the same hashes with good quality for equal objects.
The biggest hurdle comes from the gap between representations of RATIONAL and FLOAT objects. Conventionally representations are
- fixnum
- a single word with a few bits chopped to fit the tag
- bignum
- an array of "limbs", that is parts of the integer (plus sign)
- ratio
- a pair of two integers
- float
- a pair of N-bit mantissa and K-bit exponent (plus sign)
- (complex rational)
- a pair of two rationals
- (complex float)
- a pair of two floats of the same type
Fixnums, bignums and ratios are disjoint under #'=. That leaves us with questions:
-
When are two complex numbers mathematically equal?
This one is easy. Two complex numbers are equal when their real parts are equal and their imaginary parts are equal.
-
When are two floats mathematically equal?
To resolve this question we can cast the float with smaller precision to the float with bigger one and compare bits. There is a gotcha in that -0.0 is not EQL to +0.0, but it is always = to it, so we should canonicalize zeros first.
-
When is an integer mathematically equal to a float?
When the float has no fractional part and integers are equal.
-
When is a ratio equal by #'= to a float?
This is the most interesting question. To answer it, we need to dive a bit deeper into float representation.
Finite binary float values conceptually are represented as:
(* sign mantissa (expt 2 exponent))This corresponds to dyadic rationals, that is rational numbers whose denominator is a power of two:
(/ n (expt 2 k))In other words a float and a ratio may be equal only when the ratio is dyadic, otherwise the ratio value can't be represented as a binary float (this post assumes that we operate on binary floats - with radix=2).
That sums up the recap about mathematical equivalence and numeric tower in Common Lisp.
1.3. Establishing the baseline
The easiest, yet useless, approach is to always return a hash 42. It is adequate because that is the canonical answer to the most important question.
The easy and useful approach relies on the observation that hashing is lossy. All real numbers are coerced to a float precision and hashed. When the rational number does not fit in the float precision, then we hash its approximation. We need to remember to canonicalize -0.0 to +0.0 and to disable floating point exceptions for cases like overflows and underflows.
#define hash_single_float(h,v) hash_float((h), (double)(v))
#define hash_double_float(h,v) hash_float((h), (double)(v))

static inline void
hash_float(cl_hashstate *h, double v)
{
  if (v==-0.0) v=0.0;
  hash_data(h, &v, sizeof(v));
}

static inline void
hash_long_float(cl_hashstate *h, long double v)
{
  ECL_WITHOUT_FPE_BEGIN {
    hash_float(h, (double)(v));
  } ECL_WITHOUT_FPE_END;
}

#define hash_fixnum(h,x) hash_float((h),(double)ecl_fixnum(x))
#define hash_bignum(h,x) hash_rational((h),(x))
#define hash_ratio(h,x)  hash_rational((h),(x))

static inline void
hash_rational(cl_hashstate *h, cl_object x)
{
  ECL_WITHOUT_FPE_BEGIN {
    double v = ecl_to_double(x);
    hash_float(h, v);
  } ECL_WITHOUT_FPE_END;
}
This model is conceptually obvious, very maintainable, reasonably fast, and there are relatively few collisions under the usual workload. We pay for it in a few ways:
- Aesthetically it is not pleasing - crude even.
- "Relatively few collisions" applies only to toy examples, once we start using bigger integers and more precise ratios, the problem starts to show. For example 260 and 260+1 hash identically and that matters for 64bit IDs and timestamps.
- Performance-wise we drop the ball for integers and rationals - we convert numbers between formats even when we could hash only a chunk of memory.
This list is ranked by importance as I see it. The main reason I've kept digging deeper is that it was not to my taste. Then we had impracticality for serious workloads, finally microoptimizations. I believe that the general audience has these priorities in a reversed order.
2. Hashing numbers - round one
A harder but more precise way to hash numbers under the predicate #'EQUALP is to introduce canonicalization rules:
-
Integers are hashed as integers
In the case of FIXNUM we hash its value (a word without the tag) and in the case of BIGNUM we hash the sign and its limbs.
-
Finite floats without the fractional part are hashed as integers
Ensures INTEGER <-> FLOAT correspondence. We can't cast LONG-FLOAT to DOUBLE-FLOAT and then cast to integer, because we'd miss many BIGNUM values. Caveat: with this approach big floats may cons full bignums.
-
Floats that are not integers are cast to DOUBLE-FLOAT and hashed
Ensures X-FLOAT <-> Y-FLOAT correspondence. This approach is lossy for long floats if they have more bits than double floats, but simplifies the implementations because long double has a few "loose" bits that may differ between numbers with the same value.
NaNs and infinities are hashed like other doubles because infinities are exact and NaN is never #'= to anything.
-
Dyadic ratios are hashed as DOUBLE-FLOAT
Ensures FLOAT <-> RATIO correspondence. For simplicity we don't try to determine whether RATIO is representable as DOUBLE-FLOAT - if it is too big or too small, it will be represented either as a 0 or as an infinity.
-
Other ratios are hashed as pairs
We hash the numerator and denominator separately.
-
Complex floats with
(ZEROP (IMAGPART X))are hashed as(HASH (REALPART X))Because
(= 3 #c(3.0 0.0))we need to canonicalize(complex float)while rational complex numbers are canonicalized implicitly. Other complexes are hashed as pairs, that is we hash the real part and imaginary part separately.
This approach results in fewer collisions and is fairly straightforward. Here is the pseudocode:
(defun hash-equalp-number (state number)
  (typecase number
    (fixnum  (hash-word state number))
    (bignum  (hash-data state (signum number) (limbs number)))
    (float   (if (and (finitep number) (is-integer-p number))
                 (hash-equalp-number state (rational number))
                 ;; INV -0.0 and +0.0 are hashed as integers.
                 (hash-data state (coerce number 'double-float))))
    (ratio   (if (dyadic-ratio-p number)
                 ;; INV may produce infinity or zero (that's fine)
                 ;; Disable float overflow and underflow traps.
                 (hash-data state (coerce number 'double-float))
                 (progn
                   (hash-equalp-number state (numerator number))
                   (hash-equalp-number state (denominator number)))))
    (complex (if (zerop (imagpart number))
                 (hash-equalp-number state (realpart number))
                 (progn
                   (hash-equalp-number state (realpart number))
                   (hash-equalp-number state (imagpart number)))))))
2.1. Implementation bites
My initial implementation cast all floats to integers. When I was comparing ECL to other implementations I was wondering why we are so slow compared to others. The key insight came after the realization that randomized keys in the form (random 20.0) were collapsed to only 20 distinct hashes.
Fixing that and giving non-integer floats distinct hashes gave ECL the most noticeable boost on the HTABLE-MIXBAG benchmark (included at the beginning) - the new version is 100x faster than the old one.
While implementing a test suite that ensured that hashes for bignums, dyadic ratios, and corresponding floats matched, I've discovered a non-obvious bug pertaining to casting double floats to integers. The code looked like this:
if (d<=MOST_POSITIVE_FIXNUM && d>=MOST_NEGATIVE_FIXNUM) return to_fixnum(d);
else                                                    return to_bignum(d);
But the MOST_POSITIVE_FIXNUM value on x86-64 is 261-1. In other words, to represent this number exactly as a double, we need 61 significant bits. That's a shame because double has 53 significant bits, so MOST_POSITIVE_FIXNUM, when converted to double, rounds to 261 and that can't fit in a fixnum. After promotion the incorrect code is equivalent to:
if (d<=(1LL<<61) && d>=MOST_NEGATIVE_FIXNUM) return to_fixnum(d);
else                                         return to_bignum(d);
Oops, double is accidentally cast to fixnum when it is 261. That's clearly a problem! After finding the issue, the solution is easy. We need to find an exact double that is the boundary. Note that integers are implemented as two's complement, so the most negative fixnum was alright in our case:
double limit = ldexp(1.0, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
if (d<limit && d>=-limit) return to_fixnum(d);
else                      return to_bignum(d);
This fix is correct, yet it revealed another bug. But that's a different story to tell.
3. Hashing numbers - round two
The approach above is correct and nice, but has a few important flaws:
- we cons a lot for big integer floats (2KB/float in the worst case)
- there is a whole class of dyadic ratios that don't fit in long-float
- long floats lose precision after cast to double, notably very small and very big values collapse to 0 and infinity
After the initial implementation it bugged me enough that I've decided to come up with a new hashing scheme for numbers under the predicate EQUALP. The rules are also simpler (at least conceptually):
- Dyadic rationals are hashed as tuples (sign, mantissa, exponent)
- Other numbers are hashed depending on their type (they are disjoint)
The representation [SIGN MANTISSA EXPONENT] does not require us to convert between types and it is very compact. Moreover it is very precise and doesn't produce unnecessary collisions. On the other hand it requires extra work to normalize tuples. Here is the pseudocode:
(defun hash-equalp-number (state number)
  (typecase number
    (integer
     (multiple-value-bind (s m e) (compute-integer-dyad number)
       (hash-dyad state s m e)))
    (float
     (multiple-value-bind (s m e) (compute-float-dyad number)
       (hash-dyad state s m e)))
    (ratio
     (if (dyadic-ratio-p number)
         (multiple-value-bind (s m e) (compute-ratio-dyad number)
           (hash-dyad state s m e))
         (progn
           (hash-datatype-tag state :ratio)
           (hash-equalp-number state (numerator number))
           (hash-equalp-number state (denominator number)))))
    (complex
     (if (zerop (imagpart number))
         (hash-equalp-number state (realpart number))
         (progn
           (hash-datatype-tag state :complex)
           (hash-equalp-number state (realpart number))
           (hash-equalp-number state (imagpart number)))))))
The implementation is a bit less straightforward because we now need to be able to compute mantissa from numbers. A few words about normalization:
- sign is -1, 0 or +1 for finite numbers - that solves normalization of -0.0/+0.0
- mantissa must be a positive odd integer or zero - that unifies all mantissas
- exponent is also an integer, so the number is (* sign mantissa (expt 2 exp))
- to hash unique values (like infinities) we will abuse sign to fit extra values
Every integer is a dyadic rational, so our task is to normalize it so that the mantissa is an odd number and adjust the exponent accordingly.
(defun compute-integer-dyad (number &optional (exp 0))
  (when (zerop number)
    (return-from compute-integer-dyad
      (values 0 0 0)))
  ;; In the real code use COUNT-TRAILING-ZEROS + ASH.
  ;; Loop division is to make the mechanism clear.
  (do ((sign (signum number))
       (mantissa (abs number) (ash mantissa -1))
       (exponent exp (1+ exponent)))
      ((oddp mantissa)
       (values sign mantissa exponent))))
The implementation for float is also straightforward thanks to the function INTEGER-DECODE-FLOAT. We also need to normalize the signed zero:
(defun compute-float-dyad (number)
  (cond ((nan-p number)
         (return-from compute-float-dyad
           (values -2 0 0)))
        ((negative-infinity-p number)
         (return-from compute-float-dyad
           (values -3 0 0)))
        ((positive-infinity-p number)
         (return-from compute-float-dyad
           (values +3 0 0))))
  (multiple-value-bind (mantissa exponent sign)
      (integer-decode-float number)
    (compute-integer-dyad (* sign mantissa) exponent)))
For ratios we will reuse the function that we have not defined in the last section to decide whether the ratio is dyadic and if it is - convert it to the canonical form:
(defun dyadic-ratio-p (number)
  ;; A positive integer is a power of 2 only when exactly one bit is set.
  (= 1 (logcount (denominator number))))

(defun compute-ratio-dyad (number)
  (values (signum number)
          ;; Ratios are already normalized(!)
          (abs (numerator number))
          ;; den = 2^k, shift = k+1 -> exponent = -k
          (- (1- (integer-length (denominator number))))))
Mind that the functions above are deliberately simple to illustrate how they should work. We have also used non-standard functions NAN-P and INFINITY-P that depend on the implementations extensions (or internals).
This is the most satisfying moment in the post - we have found an elegant and universal (in this domain) abstraction that avoids float-to-bignum conversion, hashes unequal numbers differently, and is easy to understand. That's the high point of this post and the reason I've dubbed it "heavenly delights". Alas, it is time to come back to earth and improve its performance. That's where the engineering lives.
3.1. Back to earth
We have an elegant conceptual model. The thing with elegant conceptual models is that they need to be dirtied to make them fast. And that's what we are going to do now: we will bastardize the clean abstraction and make it performant under usual scenarios without sacrificing precision. We are now optimizing.
Simplifications that we can climb down to from our normalized representation [sign, mantissa, exponent] model:
-
When mantissa or exponent exceeds LONG-FLOAT precision, don't normalize the number
As noted earlier, aside from floats, numbers in Common Lisp are disjoint, for example, there are no integers and ratios that are EQUALP to each other. In that case we use the most convenient hashing scheme for the specified type.
-
Dyads representable as fixnums are hashed as a fixnum (a signed integer)
This is an opportunistic optimization tailored for quick fixnum hashing. We already know how to correctly determine when a float can be reliably cast to fixnum and other numbers don't intersect with fixnums.
-
Dyadic ratios in range are cast to
long doubleand hashed as LONG-FLOATThis way we ensure that ratios and floats that are #'= are hashed the same. This is similar to "Round one" approach, but we retain the maximal precision.
-
Integer floats and bignums in range are hashed in a dyadic form
This step allows us to avoid coercing floats to bignums and is a big memory allocation save. A small cost for bignums is that we need to decide before hashing whether it is in the LONG-FLOAT precision range.
-
Long floats exceeding double float precision are hashed in a dyadic form
By avoiding lossy casts to double, we reduce number of collisions. Most notably, very small and very big values are not collapsed to zero and infinity. Such floats are hashed in a dyadic form because x87 floats have additional padding bits that may differ between equal values, so we can't hash memory.
Another minor optimization: we fold the sign and the exponent into a single word to have fewer hash state updates as 8*exponent+sign (sign has maximum 2 bits).
Notice that this scheme is very similar to the "Round one" approach. In practice it only differs in how we treat floats, bignums and ratios:
| object | round 1 | current variant | note |
|---|---|---|---|
integer float |
fixnum or bignum |
fixnum or tuple |
depends on range |
fractional float |
dfloat |
dfloat or lfloat |
depends on precision |
dyadic-ratio |
dfloat |
dfloat or lfloat |
depends on precision |
fixnum |
fixnum |
fixnum |
no change |
bignum |
bignum |
bignum or tuple |
depends on precision |
A few concrete examples should illustrate these simplifications. They do not try to test precise limits and the set is not exhaustive.
I'm assuming that FIXNUM has 62 bits and LONG-FLOAT has 64-bit mantissa, 15-bit exponent and 1-bit for sign - typical on x86 with GCC.
| ## | dyadic number | canonical representation | cast | note |
|---|---|---|---|---|
| 0. | (/ 1 (expt 2 (expt 2 15))) |
(1 1 -32768) |
ratio |
too small |
| 1. | (/ 1 (expt 2 (expt 2 11))) |
(1 1 -2048) |
lfloat |
|
| 2. | 3/8 |
(1 3 -3) |
dfloat |
|
| 3. | 42 |
(1 21 1) |
fixnum |
|
| 4. | most-positive-fixnum |
(1 most-positive-fixnum 0) |
fixnum |
|
| 5. | most-negative-fixnum |
(-1 1 61) |
fixnum |
|
| 6. | (1+ most-positive-fixnum) |
(1 1 61) |
dyadic |
|
| 7. | (1- most-negative-fixnum) |
(-1 2305843009213693953 0) |
dyadic |
|
| 8. | (expt 2 32768) |
(1 1 32768) |
bignum |
|
| 9. | (/ (1+ (expt 2 40)) 2) |
(1 (1+ (expt 2 40)) -1) |
dfloat |
|
| a. | (/ (1+ (expt 2 53)) 2) |
(1 (1+ (expt 2 53)) -1) |
lfloat |
|
| b. | (/ (1+ (expt 2 64)) 2) |
(1 (1+ (expt 2 64)) -1) |
ratio |
too big |
| c. | 13.0 |
(1 13 0) |
fixnum |
|
| d. | (expt 2.0 61) |
(1 1 61) |
dyadic |
|
| e. | (expt 2.0l0 16383) |
(1 1 16383) |
dyadic |
|
| f. | (expt 2.0l0 16384) |
(3 0 0) |
dfloat |
infinity |
- case 0
- the number underflows long-float exponent precision
- case 1
- the number is representable as LONG-FLOAT but not as DOUBLE-FLOAT
- case a
- the number is representable as LONG-FLOAT but not as DOUBLE-FLOAT
- case b
- the number overflows LONG-FLOAT mantissa precision
- case e
- the number narrowly fits in LONG-FLOAT
- case f
- the number overflows LONG-FLOAT (infinity) - may signal a condition
Illustrative pseudocode:
;;; There is something to be said about conventions. Our dyadic representation
;;; treats the mantissa as an odd integer, but the C representation of floats
;;; treats the mantissa as a fraction [0.5, 1.0). In practice this means that
;;; exponents in our canonical representation must be recalculated, because:
;;;
;;;   our-mantissa === (shift-to-odd (ash float-mantissa +ldbl-mant-dig+))
;;;   our-min-exp  === (- +ldbl-min-exp+ +ldbl-mant-dig+)
;;;   our-max-exp  === (- +ldbl-max-exp+ (integer-length our-mantissa))
;;;
;;; Note that FLOAT-MANTISSA assumes a fraction, but in practice we can usually
;;; extract bits directly and skip the shift by interpreting it as significand.
(defun hash-dyadic-number (state number)
  (multiple-value-bind (sign mantissa exponent)
      (dyadic-representation number)
    (let* ((num-len (integer-length mantissa))
           (min-exp (- +ldbl-min-exp+ +ldbl-mant-dig+))
           (max-exp (- +ldbl-max-exp+ num-len)))
      (if (and (<= num-len +ldbl-mant-dig+)
               (<= min-exp exponent max-exp))
          (hash-dyad state sign mantissa exponent)
          (hash-type state number)))))
3.2. Gravel details
Without further ado, let's dig into the actual implementation. I'm going to show only relevant parts of C code for brevity. If you are not interested in C code and microoptimizations, then just skip this section and move to benchmarks. Here is a TL;DR table (complexes are normalized and each part is hashed with a tag):
| type | hash as | why? |
|---|---|---|
fixnum |
fixnum |
performance |
bignum |
bignum / dyadic |
performance / equivalence (lfloat/dfloat) |
ratio |
ratio / lfloat |
performance / equivalence (lfloat/dfloat) |
dfloat |
fixnum / dyadic / dfloat |
performance / equivalence / performance |
lfloat |
dfloat / fixnum / dyadic |
performance / performance / correctness |
In two places we will hash integers that may be either fixnums or bignums:
- the mantissa in a dyadic form (long double mantissa is 64bit on x86-64)
- a ratio's numerator and denominator when the ratio is not a dyadic number
Hashing them is straightforward. Note that hashing the fixnum is always cheap - we hash a single word.
static inline void
hash_fixnum_data(cl_hashstate *h, cl_object x) {
  hash_word(h, ecl_fixnum(x));
}

#define hash_fixnum(h,x) hash_fixnum_data(h,x)

static inline void
hash_bignum_data(cl_hashstate *h, cl_object x) {
  hash_word(h, ecl_bigsgn(x));
  hash_data(h,
            ECL_BIGNUM_LIMBS(x),
            ECL_BIGNUM_USIZE(x) * sizeof(ecl_limb_t));
}

static void
hash_integer(cl_hashstate *h, cl_object x)
{
  if (ECL_FIXNUMP(x)) {
    hash_fixnum_data(h, x);
  } else {
    hash_bignum_data(h, x);
  }
}
Previously we were concerned with consing. This is why we go an extra mile to not allocate bignums unnecessarily when we hash a bignum in a dyadic form. We operate on a scratch register that is a thread-local variable in ECL when we extract a mantissa:
static inline void
hash_and_free_bignum_register(cl_hashstate *h, cl_object mantissa) {
  /* INV this function assumes that mantissa is already positive. The bignum may
     not be normalized to fixnum. We free the register after hashing. */
  if (ECL_BIGNUM_SIZE(mantissa) == 1) {
    ecl_limb_t y = ECL_BIGNUM_LIMBS(mantissa)[0];
    if (y <= MOST_POSITIVE_FIXNUM) {
      hash_word(h, y);
      goto DONE;
    }
  }
  hash_bignum_data(h, mantissa);
 DONE:
  _ecl_big_register_free(mantissa);
}

/* When hashing bignums we see whether they fit in LONG-FLOAT and only then we
   cast it to a dyadic form. Otherwise we directly hash limbs. */
static void
hash_bignum(cl_hashstate *h, cl_object x) {
  cl_fixnum length = _ecl_big_integer_length(x);
  cl_fixnum exponent = _ecl_big_ctz(x);
  if (length-exponent<=LDBL_MANT_DIG && length<=LDBL_MAX_EXP) {
    /* To avoid allocating fresh bignums by ABS and ASH we opencode this:
       cl_object mantissa = ecl_ash(ecl_abs(x), -exponent); */
    cl_object reg = _ecl_big_register2();
    cl_fixnum signum = ecl_bigsgn(x);
    if (signum<0) {
      _ecl_big_neg(reg, x);
      _ecl_big_div_2exp(reg, reg, exponent);
    }
    else {
      _ecl_big_div_2exp(reg, x, exponent);
    }
    hash_word(h, 8*exponent+signum);
    hash_and_free_bignum_register(h, reg);
  } else {
    hash_bignum_data(h, x);
  }
}
Hashing a ratio is also plain. When the ratio is dyadic and its precision does not exceed long double then we coerce it to that type and hash it. Otherwise we add the tag and hash both integers. We are careful to not allocate memory.
static void
hash_ratio(cl_hashstate *h, cl_object x) {
  /* When the ratio is dyadic and within long-float precision, then we cast it
     to long double for consistent hashes. Otherwise we hash ratio as is. */
  cl_object num = ecl_ratio_num(x);
  cl_object den = ecl_ratio_den(x);
  /* Ratio is dyadic when denominator is a power of two. To avoid bignum
     arithmetic we provide an optimized path for each subtype of integer.
     ecl_zerop(ecl_boole(ECL_BOOLAND, den, ecl_one_minus(den))); */
  bool dyadic_p;
  if (ECL_FIXNUMP(den)) {
    /* Denominator is always positive, so fixnump(x) -> fixnump(x-1) */
    cl_fixnum dfix = ecl_fixnum(den);
    dyadic_p = !(dfix & (dfix-1));
  } else {
    /* When bignum is a pow2, then integer_length == ctz+1 or (popcount==1) */
    dyadic_p = ((_ecl_big_ctz(den)+1) == _ecl_big_integer_length(den));
  }
  if (dyadic_p) {
    /* Normally we would call here
       cl_fixnum length = ecl_integer_length(ecl_abs(num));

       But! Numerator is normalized to an odd integer because denominator is a
       power of two. INTEGER-LENGTH returns different values for X and -X only
       when X is a power of two, and the only odd power of two is X=1.

       (INTEGER-LENGTH -1) == 0 and 0 <= LDBL_MANT_DIG
       (INTEGER-LENGTH +1) == 1 and 1 <= LDBL_MANT_DIG

       This is why we don't need to call ABS on the numerator. QED. */
    cl_fixnum length = (ECL_FIXNUMP(num)
                        ? ecl_integer_length(num)
                        : _ecl_big_integer_length(num));
    cl_fixnum exponent = -(ecl_integer_length(den)-1);
    if (length <= LDBL_MANT_DIG && exponent >= LDBL_MIN_EXP-LDBL_MANT_DIG) {
      /* Generic way to do this is: hash_long_float(h, ecl_to_long_double(x));
         that path recomputes mantissa and exponent from ratio using a generic
         arithmetic. We already have everything ready. */
      long double value = (ECL_FIXNUMP(num)
                           ? ecl_fixnum(num)
                           : _ecl_big_get_lf(num));
      value = ldexpl(value, exponent);
      hash_long_float(h, value);
      return;
    }
  }
  /* Fall-through. */
  hash_word(h, t_ratio);
  hash_integer(h, num);
  hash_integer(h, den);
}
Hashing floats is the most demanding part in this program:
- DOUBLE-FLOAT: the first branch ensures the same hashes for fixnums, bignums, and integer float types, while the second branch ensures the same hashes for ratios and fractional float types.
- LONG-FLOAT: the first branch checks whether we can cast to double without losing precision. The second branch ensures same hashes for fixnums. The third branch unconditionally hashes the value in a dyadic form.
Initially I've introduced functions decode_lf and decode_df that extracted mantissa and exponent from the number, but benchmarks showed that these small allocations dominate both time and consing for relevant profiles. This is why I've fused decoding and hashing and operate on a preallocated register. That's the difference between coming up first and coming up third on the benchmark.
Decoding and hashing double and long double in a dyadic form are practically the same, so I'm going to show only hash_lfloat version. Both functions have a fast path when the mantissa fits in cl_index, and a portable slow path when it doesn't. Initially I've picked unsigned long long, but this type can't be directly assigned to a bignum in GMP, so I've decided on a more robust type.
Functions hash_dfloat and hash_lfloat are identical except for DBL_MANT_DIG -> LDBL_MANT_DIG, ldexp -> ldexpl and frexp -> frexpl. Common Lisp, with its organic macros, could save us repetition and expand a single macro twice, but C preprocessor macros get hairy fast, so it is better to copy-paste the code:
/* INV value is guaranteed to be finite and != 0. */

#define DECODE_SIGNUM(value,signum) \
  do { if (signbit(value)) { signum=-1; value=-value; } } while(0)

/* ... hash_dfloat(cl_hashstate *h, double value) ... */

static inline void
hash_lfloat(cl_hashstate *h, long double value)
{
#if LDBL_MANT_DIG <= ECL_FIXNUM_BITS
  int ctz, exponent, signum=1;
  cl_index mantissa;
  DECODE_SIGNUM(value, signum);
  value = ldexpl(frexpl(value, &exponent), LDBL_MANT_DIG);
  exponent -= LDBL_MANT_DIG;
  mantissa = (cl_index)value;
  ctz = ecl_ctz(mantissa);
  exponent += ctz;
  mantissa >>= ctz;
  /* binary80 mantissa is 64 bits so it can falsify <= MOST_POSITIVE_FIXNUM. */
  if (mantissa <= MOST_POSITIVE_FIXNUM) {
    hash_word(h, 8*exponent+signum);
    hash_word(h, mantissa);
  } else {
    cl_object reg = _ecl_big_register2();
    _ecl_big_set_idx(reg, mantissa);
    hash_word(h, 8*exponent+signum);
    hash_bignum_data(h, reg);
    _ecl_big_register_free(reg);
  }
#else /* Happens for 128bit floats (i.e aarch64). */
  const int fixnum_bits = ECL_FIXNUM_BITS-ECL_TAG_BITS-1;
  int ctz=0, exponent, signum=1;
  cl_object mantissa = _ecl_big_register2();
  cl_fixnum helper, iterator;
  DECODE_SIGNUM(value, signum);
  value = frexpl(value, &exponent);
  _ecl_big_set_ui(mantissa, 0);
  for(iterator=0; iterator<LDBL_MANT_DIG && value; iterator+=fixnum_bits) {
    value = ldexpl(value, fixnum_bits);
    helper = (cl_fixnum)value;
    value -= helper;
    _ecl_big_mul_2exp(mantissa, mantissa, fixnum_bits);
    _ecl_big_add_ui(mantissa, mantissa, helper);
    /* When this chunk contains only 0s, then we extend trailing zeros by
       fixnum_bits (chunk's size). Otherwise we start counting again. */
    ctz = !helper ? ctz+fixnum_bits : ecl_ctz(helper);
  }
  /* ctz is a trailing 0 count for the whole mantissa. iterator denotes how many
     bits we have shifted the mantissa. */
  exponent += ctz - iterator;
  _ecl_big_div_2exp(mantissa, mantissa, ctz);
  hash_word(h, 8*exponent+signum);
  hash_and_free_bignum_register(h, mantissa);
#endif
}
#undef DECODE_SIGNUM
At last we can hash some floats. Hashing single floats is trivial (we cast them to double float) while hashing a long float requires more work:
- integer path
- we need to extract the mantissa from it separately because it can store bignums outside of a double float range.
- fraction path
- DOUBLE-FLOAT is hashed as is, LONG-FLOAT are hashed as a dyad unless it can be represented as DOUBLE-FLOAT, in that case it is cast to it
#define hash_single_float(h,v) hash_double_float((h),(double)(v))

static void
hash_double_float(cl_hashstate *h, double value) {
  if (isfinite(value) && (value==trunc(value))) {
    const double limit = ldexp(1.0, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
    if (value < limit && value >= -limit) {
      hash_word(h, (cl_fixnum)value);
      return;
    }
    hash_dfloat(h, value);
    return;
  }
  /* Fall-through. */
  hash_data(h, &value, sizeof(value));
}

/* We need to ensure, that when long double can be represented as double without
   loss of precision, that is value == (double)value, to hash it as double. */
static void
hash_long_float(cl_hashstate *h, long double value) {
  /* Hash as double. */
  if (!isfinite(value)
      || (fabsl(value) <= DBL_MAX && value==(double)value) ) {
    hash_double_float(h, (double)value);
    return;
  }
  /* Hash as fixnum. */
  {
    const long double limit = ldexpl(1.0L, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
    if ((value==truncl(value)) && (value < limit) && value >= -limit) {
      hash_word(h, (cl_fixnum)value);
      return;
    }
  }
  /* Hash as long double in dyadic form -- this is both for compatibility with
     bignums and to avoid hashing padding bits on x87. */
  hash_lfloat(h, value);
}
And.. that's all. Complex numbers are hashed the same - when the complex float imaginary part is zero then we hash only the real part, otherwise we hash both parts. Summing things up, here are the dominant costs of the procedure:
| type | decision cost | dyadic hash cost | normal hash cost |
|---|---|---|---|
fixnum |
(none) | same as for EQL | same as for EQL |
bignum |
(negligible) | (ash (abs x) -exp) |
same as for EQL |
ratio |
(negligible) | hash_long_float |
same as for EQL |
float |
(negligible) | hash_{dfloat,lfloat} |
same as for EQL |
- bignum decision cost boils down to counting trailing zeros, the dyadic hash operates in a register and it doesn't cons
- ratio decision cost is optimized to not perform bignum arithmetic, so the decision cost is negligible and the main cost is in hashing long double
- float creates an integer from the mantissa - in most cases it is a fixnum, otherwise it operates on a bignum register and it doesn't cons either
This section might not have been the most pleasant read (a lot of C code), but I hope that it gave you some insight into how optimizing ECL hot paths looks like. Certainly it would be nice to have Common Lisp compiler that targets C! Oh…
4. Benchmarks - knockout
I initially planned to run ad hoc benchmarks and get over with it, but I had too much fun writing up tests and coming up with interesting benchmark profiles and fell into another rabbit hole. In this section we'll compare ECL with itself (of course), but we will also discuss other implementations.
First let's focus on tests. I've devised a few profiles for comparisons:
- :AVERAGE
- we pick randomly rational and float numbers
- :TYPICAL
- fixnums, fixnum uuids, small floats and bignums in form 2n
- :DYADIC
- rational and float numbers with overlapping values being =
- :COLLIDE
- white-box test that exploits casting LONG-FLOAT to DOUBLE-FLOAT
- :BEYOND
- white-box test that tests dyadic rationals beyond LONG-FLOAT range
- :FIXNUM :BIGNUM :RATIO :DOUBLE
- basic type-specific benchmark
All benchmarks first generate 216 keys according to their profile and prefill the hash table in the setup phase to avoid resizing. Only after that we run the benchmark. Each profile has the same number of keys that are randomized during setup. Each test is run 8 times to average results.
We measure both run time and consed bytes. The benchmark itself runs SETHASH and GETHASH for each key in the collection, so the hash table implementation impacts cross-implementation comparisons. On the bright side, it also reveals when there are systematic collisions between hashes.
Here is an interesting story (relevant to these charts!). While analyzing data I've noticed that "ECL-round2" unexpectedly conses for three profiles: :DYADIC, :TYPICAL and :AVERAGE. I've felt very disappointed with these, because I went to great lengths to avoid consing. The investigation revealed that if we don't mix in these tests floats and rationals then consing is consistently zero. That was the "aha!" moment - hash table allocates memory when it compares float and rational keys! I'm keeping the figures as-is, but keep in mind that "ECL-round2" hashing really doesn't cons; allocations come from the key comparison. I could pull out my yak shaver and fix EQUALP too, but this descent stops being funny.
ECL variants are: "warmup", "round one" and "round two" that correspond to approaches discussed earlier: cast everything to double, type-specific hashes, and the final version where we exploit a dyadic canonical form. All tests are performed using the new hash function (xxhash) and hash table (swiss).
Tested implementations are CCL, ECL, LispWorks and SBCL. There are caveats:
- I initially planned to include ABCL and CLASP too, but a smoke test revealed ABCL#763 and CLASP#1876. Both share the same flaw as ECL before changes described in this post, that is they don't hash numbers correctly under EQUALP. Benchmarking them would be beside the point.
- LispWorks performs badly on profiles any float numbers and other results are dwarfed by it, so I've excluded LW from some plots (but accounted for it in relevant analysis)
- CCL is the mirror image of LispWorks, and performs badly on profiles with rationals (and it is great with floats), so it is also skipped on some plots
- The :COLLIDE test does not apply to other implementations because they don't have LONG-FLOAT that is separate from DOUBLE-FLOAT - we use :TYPICAL instead
The smoke test:
(defvar *ht* (make-hash-table :test #'equalp))
(setf (gethash 1/4 *ht*) 42)
(unless (eql (gethash 0.25 *ht*) 42) ; a proper test should cover more pairs
  (format t "ERROR: 1/4 and 0.25 do not share the hash value under EQUALP.~%"))
All charts report either elapsed time or allocated memory aggregated for the whole execution. Smaller is better. Test results are normalized to [0, 1] relative to the slowest / most consing variant in each panel. "0.00" means "below 0.005" of the maximum, not zero. All measurements were performed on X86-64 Intel(R) Core(TM) i9-9900K CPU @ 3.60GHz.
One of the hardest parts in analyzing data is to decide what we can remove without simplifying the picture too much. Interpretations presented in this section skip many benchmarks to present an understandable story.
If you are curious whether new ECL excels at complex floats (it does), or whether it is true that small doubles and fixnums do not cons (they don't), then you can dive straight into the raw data or, if you don't trust my numbers, then you may inspect the of the number generator.
4.1. ECL vs ECL
First we will compare ECL variants developed in this post. The first chart shows a benchmark for basic types:
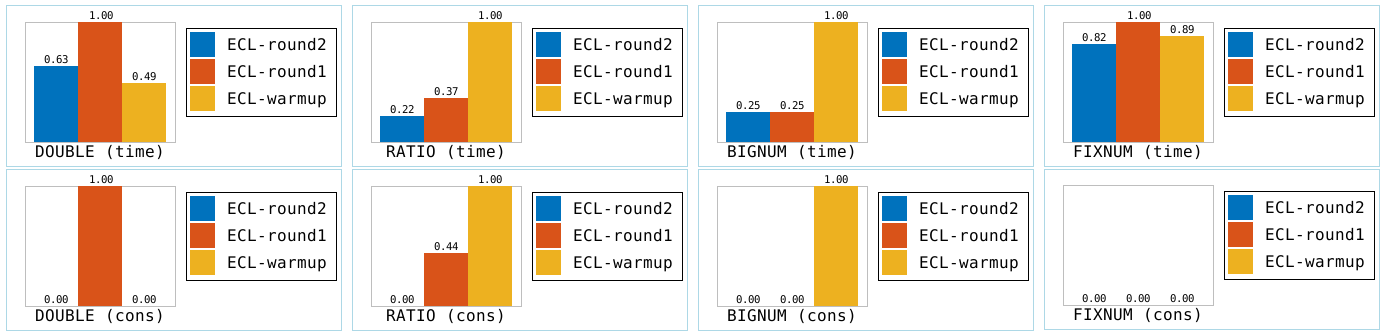
Figure 6: (ECL-warmup ECL-round1 ECL-round2) x BASIC-TYPES x (TIME CONS).
A few interesting observations emerge from this chart:
- Hashing doubles is fastest on "ECL-warmup", because this implementation is simplest for that particular profile. It also doesn't cons. "ECL-round1" is dominated by memory allocations for large double values that are bignums.
- Hashing ratios has progressively better results with each round, both the time and consing.
- Hashing bignums is a mirror image to hashing doubles, where "ECL-round1" excels at bignums, "ECL-warmup" must coerce bignums to doubles and memory allocation dominates its time. "ECL-round2" is as performant as "ECL-round1".
- Fixnums on all variants are on a relatively fast path and don't need to cons at all.
Notice that "ECL-round2" is slower only when we hash specifically doubles. Otherwise it is always tied or it is the fastest. It also doesn't cons.
It already looks good, but charts start to look even more interesting when we start exploiting mixed data patterns:
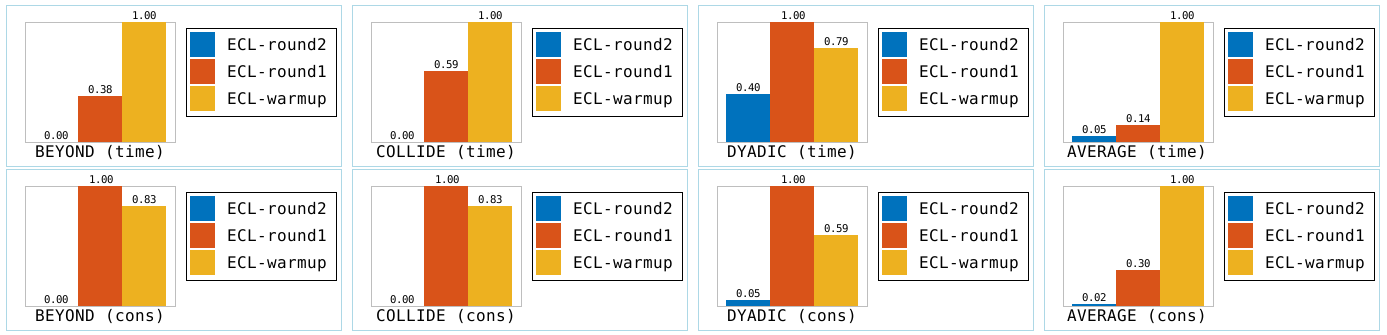
Figure 7: (ECL-warmup ECL-round1 ECL-round2) x MIXED-DATA x (TIME CONS).
-
The "beyond" profile is a benchmark where we generate bignums and ratios that can't be represented as float, but have a shape that resembles floats - both have a mantissa that can be stored in a double and an exponent that doesn't fit in binary128 floats (the most precise float on ECL aarch64 and no tested Lisp has a wider float).
And it shows. "ECL-warmup" takes the bait and collapses everything to double. That spikes both allocations and collisions. "ECL-round1" avoids part of that cost because bignums are hashed as is and they avoid collapsing to a single hash (double positive infinity). "ECL-round2" avoids both allocation and the collision traps and it is 400x faster (0.3s vs 125s) and doesn't cons while "ECL-warmup" conses 2GB.
- The "collide" profile is similar, but numbers can be neatly represented as a long float (binary80) and not as a double float (binary64). That means in particular that both ratios and bignums must be hashed in a compatible manner to floats. Once again "ECL-round2" is very fast (600x faster! 0.2s vs 118s) and doesn't cons, while "ECL-warmup" conses 833MB. "ECL-round2" has much less collisions than "ECL-warmup" thanks to exact bignum hashing.
- The "dyadic" profile mixes fixnums, double floats, bignums in double float range and dyadic ratios in double float range. This profile forces the need to bring all numbers to the same canonical representation and does not exhibit any systematic collisions. Since all here boils down to doubles, "ECL-warmup" conses less than "ECL-round1", yet "ECL-round2" is even better thanks to our optimizations. Little consing that is exhibited comes from comparing floats and bignums with EQUALP (not from hashing).
- The "average" profile takes rational and float numbers at random. Here we can again see that "ECL-round1" was not a regression over "ECL-warmup" - it was a targeted optimization that tried to balance effort between different types of numbers. Still, "ECL-round2" wins clearly against both variants.
My takeaways here are that:
- specialized implementations are better for their particular data profile, notably "ECL-warmup" excels at doubles; "ECL-round1" ties "ECL-round2" at bignums and balances other types well
- "ECL-round1" approach optimizes for typical cases, but it is not very frugal with memory (to the point where allocations dominate the benchmark in doubles)
- "ECL-round2" also optimizes for typical cases but it is also austere with memory allocations and avoids hash collisions - that is responsible for two orders of magnitude faster and leaner implementation for adverse profiles
4.2. ECL vs the world
Comparing implementations between each other is inherently noisy. They don't share the same hash table implementation and various unrelated operations on the hashing and hash table path have different cost profiles. That said with a big set of data we can clearly see some trends. Let's start with basic types:
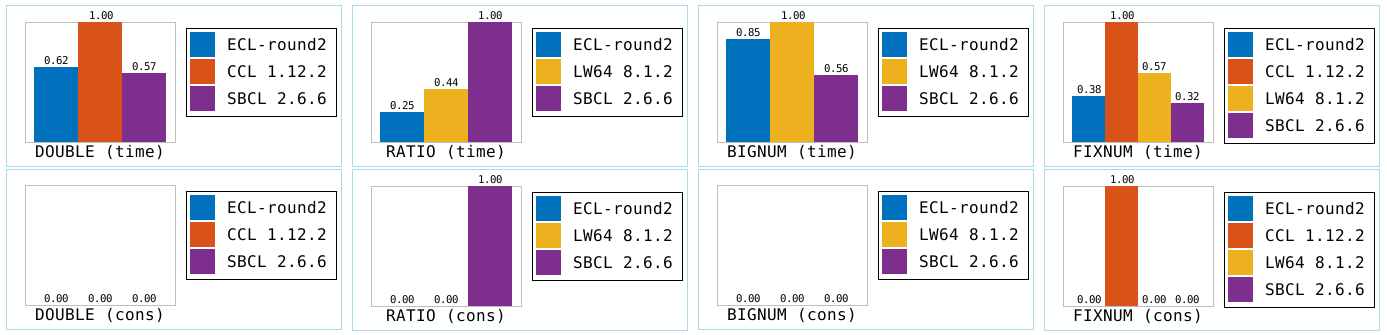
Figure 8: (CCL ECL LispWorks SBCL) x BASIC-TYPES x (TIME CONS).
LispWorks is excluded from the test involving floats because it is around 2500x slower than CCL (96s vs 0.04s) and conses 66MB while other implementations don't cons at all. In benchmarks involving rational numbers it is competitive. My guess is that LispWorks calls RATIONALIZE on floats and that get costly fast.
CCL is another side of the same coin. It performs well for floats (around 1.7x slower than ECL and SBCL), but it is much worse for rationals. The difference is not that drastic but still much slower for bignums compared to LispWorks (0.18s vs 0.03s). It is surprising but it allocates data even for FIXNUMs. It probably calls FLOAT on all numbers before hashing.
SBCL heavily optimizes fixnums, bignums, and doubles - it is a leader on these basic types and it doesn't cons. It drops a ball with ratios where it is slower and conses 155MB (while ECL nor LispWorks don't allocate memory for ratios).
ECL never conses and wins for ratios, while for other basic types it is always second. For BIGNUM SBCL pulls ahead, while for FIXNUM and DOUBLE it follows closely.
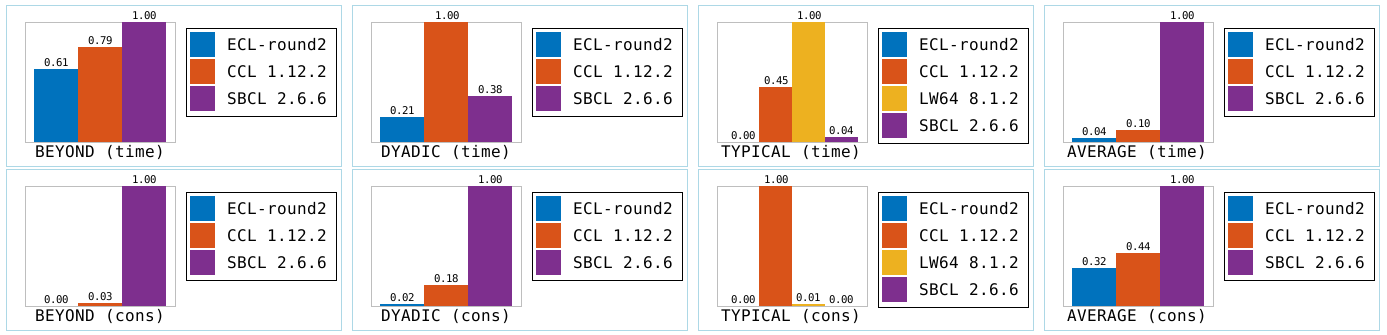
Figure 9: (CCL ECL LispWorks SBCL) x MIXED-DATA x (TIME CONS).
Results in these benchmarks are implicit from tests on basic types:
- BEYOND, DYADIC and AVERAGE involve floats, so LispWorks is too slow to include. SBCL is also underperforming on these tests, because these profiles contain ratios - the cost seems to be dominated by memory allocations.
- TYPICAL profile is manageable for all implementations, but both CCL and LispWorks underperform because both (small) floats and rationals are in the test set. CCL allocates much more memory than others. SBCL performs well, but is slower than ECL.
- In all these tests with mixed numbers ECL is the leader and allocates least (as noted earlier, hashing itself doesn't cons at all).
My takeaway is that each implementation could close the gap to the others if:
- LispWorks adds hashing specialization for floats
- CCL adds hashing specialization for rationals
- SBCL adds hashing specialization for ratios
This new approach of ECL is competitive with all implementations on each metric and it is either the first or a close second with the biggest (around 1.5x) gap to SBCL hashing bignums.
5. Summary
The main takeaway here is that every dyadic rational has one canonical form that may be used to produce good hashes under the EQUALP predicate and that efficient implementations take liberties with simplifications after absorbing the model.
It may look like we have abandoned the elegant dyadic model in the later phase, but that's not true: we don't lose precision by lossy casting to double and all numbers except equal ones are hashed differently (hashing differently does not imply different hashes just like tossing a dice differently does not guarantee different results).
Another interesting insight is that we can learn a lot about strategies used by different implementations by merely benchmarking them with cleverly put number selection profiles.
In practice EQUALP is not often used as a hash test, so while the numbers look impressive, the new approach is not a game changer. That said, there is value in hashing under EQUALP precisely because it coalesces different numbers. Usage may follow when implementations are performant, while underperforming abstractions will almost certainly be skipped.
That's about the hashing itself, but the post is not only about hashing. Note how we have started with a simple baseline model, improved it and then refined our understanding with an elegant conceptual model. We didn't stop there: we turned it into an efficient implementation through the optimization and validation loop. That's an engineering lesson worth remembering even if you don't care much about heavenly delights of hashing numbers under EQUALP.
Uff, the summary was exhausting. For me, this was certainly a fun trip. I've recently learned a lot about hashing, hash tables, number equivalence, micro-optimizations, benchmarking and diving too deep. Look forward to:
- a blogpost that discusses new hash table and generic function implementations
- the next release with all accumulated performance and conformance improvements
You may find the current progress in the ECL repository under branches xxhash, swiss-ht and improve-gf-cache.
Happy Hackshing!
Daniel
PS If you liked this post or have some interesting insights, then let's chat.
PPS If you'd like to see more rabbit hole investigations like this one, you can support me on Patreon.
PPPS I'd like to thank Charlie McMackin for proofreading this text and providing many valuable remarks.
26 Oct 2026 12:00am GMT
25 Oct 2026
Planet Lisp
Marco Antoniotti: Exercising on a Threadmiλ, multitasking
As I get older, I need to exercise. I decided to use a Threadmiλ.
Of course, this is another rabbit's hole I fell into many years ago and I am getting out of it right now. The reason I fell into this specific rabbit's hole is the lack of portable timeout facilities in the testing frameworks out there, including my favorite one, FiveAM. More on this later.
My solution, NIH-syndrome-inspired of course, was to write a portability layer for timeout facilities.
Which begged the question: why not Bordeaux Threads?
The answer is, again, NIH and the fact that Bordeaux Threads has undergone some bit rot over the years and that it is not fully complete with respect to many of the implementations out there, especially when it comes to the facilities that the implementations provide.
The result is Threadmiλ (or threadmiλ, or ThreadMIL, or threadmilambda...), i.e., a Bordeaux Threads like library, re-done in MILan; the λ is de rigueur.
Threadmiλ
As I said, Threadmiλ (Threadmil) is a fork and a somewhat re-implementation of the well known Bordeaux Threads library that aims to make it even more CL-centric, expand it and fix the semantics of a few constructs, most notably the timeout machinery.
Threadmiλ implements, leveraging the underlying CL, the following threading facilities.
- Threads
- Locks
- Semaphores
- Condition Variables
- Timers
- Mailboxes
- Barriers
- Atomics
- Timeouts
These are the facilities available in most CL, especially Lispworks.
Current Implementation Status
The table below gives you a quick status of the support for a number of implementations. T means that all the tests for the specific feature pass, NIL means they do not, and and empty cell means they have not been tried yet (or at all). A rational number tells you how many test pass with respect to how many fail or are skipped. The test suite uses fiveam.
| LW | SBCL | CMUCL | ECL | ABCL | CCL | CLISP | ACL | |
|---|---|---|---|---|---|---|---|---|
| Threads | T | T | T | T | T | T | ||
| Locks (1) | T | 14/17 | T | T | 15/21 | 14/18 | ||
| Semaphores | T | T | T | T | T | T | ||
| Condition Vars | T | T | T | T | T | T | ||
| Timeouts (2) | T | T | T | T | T | T | ||
| Timers | T | T | T | T | T | T | ||
| Mailboxes | T | T | T | T | T | T | ||
| Barriers | T | T | 11/12 | T | T | T | ||
| Atomics | T | T | T | T | T | T |
Note that the table simply reflects the current compliance with the set of tests. Adding some tests may change the entries in the table. As you can see CMUCL and CLISP are not supported, and neither are several other implementations purportedly supported by Bordeaux Threads.
(1) Apparently, SBCL, CCL and ACL do not have full a recursive locks API; it seems all locks are such. The missing bits are different and this is reflected in the number of tests actually performed. In the future the regular API may be used and the missing tests will just work.
(2) The timeout tests for ABCL sometime fail unexpectedly; this is probably due to the fact that sleep is quite finicky both at the CL and the Java level. Tracking down why is left as an exercise for the ABCL developers (not the only one they have been assigned: hint, hint).
Where You Can Get your Threadmiλ
The main documentation page can be found https://threadmil.common-lisp.dev.
/ The project page is at https://gitlab.common-lisp.net/mantoniotti/threadmilambda
How Did I Get Here?
Before AI stuff I used some testing frameworks to tortur... pardon, evaluate students' projects (yes, I inflict CL on them). Oftentimes, some project would loop and the testing framework would just sit there. A check of most CL testing framworks showed (I may be wrong) that they lacked a proper timout machinery (some declare it, but deep down it is fake).
I thus set out to create a portable with-timeout macro. That was the mistake that led to Threadmiλ.
Now, testing frameworks developers have no more excuses.
Disclaimer
As usual here you have the scariest disclaimer here. The library is bound to have bugs and race conditions.
AI was used only to generate a few of the tests.
Any Help Appreciated
Of course you are free to fork the project subject to the current licensing scheme. However, before you do so, I ask you to consider plain old "cooperation" by asking me to become a developer. It helps keeping the entropy level at an acceptable level.
Of course, in this case, I did not heed my own advice, and yet...
'(cheers)
Marco Antoniotti 2026-10-24
25 Oct 2026 4:34pm GMT