21 Oct 2026
 Django community aggregator: Community blog posts
How I decide which Python and Django versions I want to support
How I decide which Python and Django versions I want to support
A recent post on Mastodon got me thinking about what my philosophy for dropping support for old versions of Python and Django is. Here's the post:
🚨 Important Announcement 🚨
Going forward all my packages will only "officially" support maintained #Python versions. Meaning since October only 3.14 and now 3.15.
This has no effect on Django version support.
CVEs will be backported to older 🐍 releases.
I tend to support versions long past their End of Life date. I jokingly said that I should spend time upgrading old websites instead of spending time writing a rationale why not. I don't want to argue for my position, but maybe this post will serve as the place to point people towards when the question arises again in the future.
The short answer: it depends on whether I'm working on a project, on my own machine or on a library.
Projects
When working on projects I'm always updating to the current stable version or even the bleeding edge. I want the projects to be as future-proof as possible and I also want to give early feedback when stuff breaks.
As long as the server software allows it, I'm just going to use uv to install the newest Python version that all the packages I'm using support (or at least ship binary wheels for), because I enjoy not compiling software when deploying too damn much.
Developer workstations
When it comes to developer workstations I don't really have the patience for outdated software. I don't see a reason why developer tooling can't be up to date. This came up recently in the django-debug-toolbar issue tracker. I'm totally fine with requiring an up-to-date version of Python for our pre-commit hooks, for example.
Libraries
The more foundational and widely used a library (potentially) is, the more important it is to me that it supports basically everything which is reasonable.
I'm still using my libraries in older projects myself, so they have to work there. I want to use them in all environments, at least when I'm not paying a big price in terms of language features.
Other people may be stuck on older versions too. People can upgrade their software, but there may be situations (for example in managed hosting environments) where people cannot freely update the underlying managed server software. That isn't necessarily a problem security-wise as long as there are other measures in place protecting those services.
When people use my libraries, I might get additional eyes on the code, and possibly even contributions.
Supporting a large range of Django versions, for example 3.2 (reached EOL on 2024-04-01) up to the current main development branch, can be surprisingly easy when you do not reach too much into Django's internals or depend on features added only recently.
That said, when do I actually drop support for an old version of Python or Django? Generally speaking, I have two reasons:
🌳 Keeping CI time down 🌳
I like pruning the CI matrix so as to not spend too much compute and energy. The exceptions are packages such as django-debug-toolbar and django-tree-queries: they are widely used and have to work on a wide range of Python and Django versions and database engines, so the additional CI runs are worth it.
When I remove a version from the CI matrix I mostly raise the minimum version in the package metadata as well. I almost never use upper bounds for version ranges, but lower bounds I definitely do use.
Using new features, either because I want them or because I need them
Sometimes, I just really want to merge dictionaries using the nice a | b syntax. If this reasoning sounds whimsical to you, it is, but only partially. Programming cannot just be a job, everybody needs to have fun sometimes.
Sometimes, I really need some API or behavior Django has only introduced recently, such as the way bound fields work in forms. For example, form validation didn't go through bound fields before 4.0.
What that means right now
Most of my packages currently require Python 3.10 or newer and Django 3.2 or 4.2 or newer. Some of the less actively developed ones still go back as far as Python 3.8, simply because I haven't had a reason to touch them. Python and Django support are linked: Django 4.2 supports Python 3.8 to 3.12 while Django 6.0 requires Python 3.12, so the oldest Django version I support pretty much decides the oldest Python version worth testing.
What is the downside?
Supporting old versions makes it easier for people to put off upgrading. Some people just don't want to upgrade at all, and my libraries continuing to work on old versions certainly doesn't push them to do it. When they suddenly have to because all hell breaks loose (because of security problems or something like that) it's so much harder: they have a long way to go until they reach supported versions. That said, in my experience that's not a big problem with Django at all. On the other hand, when the projects still use npm packages from 2015… oh my.
The code is also less clean than it could be. Supporting old versions means compatibility shims, and it means not using some of the nicer features newer versions offer.
In the end, both approaches are reasonable, and both have their costs. You should do what brings you more joy.
21 Oct 2026 5:00pm GMT
Django in Space - Loes Crama
🔗 Links
- Loes on LinkedIn
- cosine
- Djangocon EU: How Django is helping to build the biggest X-ray observatory to date - Loes Crama
📦 Projects
📚 Books
- Weapons of Math Destruction by Cathy O'Neil
- Slouching Towards Utopia by J. Bradford DeLong
🎥 YouTube
21 Oct 2026 3:00pm GMT
20 Oct 2026
Django community aggregator: Community blog posts
CRUD: REST without the HTTP
REST as practiced usually arrives wrapped in HTTP - verbs, URLs, status codes. Strip all of that away and a more general principle is left underneath: for any object, we should be able to create it, read it, update it every valid way, and delete it, one at a time or as a member of a collection.
20 Oct 2026 10:00am GMT
16 Oct 2026
Django community aggregator: Community blog posts
Issue 359: Python 3.15 Is Here and Python 3.16 Alpha 1
News
Python 3.15.0 (final) is here!
Python 3.15 is out, with explicit lazy imports (PEP 810), built-in frozendict and sentinel types, UTF-8 as the default encoding, and a JIT that runs 7-12% faster depending on the platform. If you use IDLE or tkinter on macOS 27, read the release notes first: menu dialogs can hang.
Python 3.16.0 alpha 1 is now available
The first of seven alphas for Python 3.16 is out, with features landing until the May 4, 2027 beta and the final release planned for October 5, 2027. Library maintainers are invited to start testing now.
Django Software Foundation
Django Steering Council Meetings - 2026
Notes from the October 5 meeting with the Fellows: the set-returning DEP needs reviewers, every memcached Python client is now defunct, and Python 3.15 support raises questions about makedirs permission semantics. PyPy 8.0 support and the Sovereign Tech Fund's resilience program were also on the agenda.
Wagtail CMS News
We have a stellar group of speakers for Wagtail Space 2026
The schedule is out for this year's online, half-day Wagtail Space, opening with Thibaud Colas's State of Wagtail. Talks cover running Wagtail at scale on Kubernetes, measuring a site's web emissions, agent readiness, and Wagtail Preen, a new codemod CLI.
Updates to Django
Last week we had 26 pull requests merged into Django by 9 different contributors - including a first-time contributor! Congratulations to Abheet for having their first commits merged into Django - welcome on board!
New in Django 6.2:
- The
nowtemplate tag now supports passing a template variable as the format string.
New in Django 6.1:
- To improve accessibility, the admin's breadcrumbs are now rendered as
<li>elements within an<ol>instead of<div>elements. The breadcrumb for the current page is now marked witharia-current="page". - Added compatibility for
oracledb26.0.0+ (#37411). - Fixed a regression in Django 6.1 where the YAML serializer crashed if passed the
sort_keysoption (#37405). - Fixed a regression in Django 6.1 where a
Valueexpression with aNonevalue and an output field other thanJSONFieldcrashed on SQLite when used in a top-levelJSONFieldinlookup (#37403). Using such an expression in anINlookup is likely unintended, since SQLNULLcannot match any value.
Django Fellow Reports
Django Fellow Report - Jacob
Jacob cleared a spike of release blockers for 6.1.2, all but two of them found internally using a model, and added compatibility for python-oracledb 26. He also fixed a YAML serializer crash with sort_keys and landed prep work for multiline template tags.
Django Fellow Report - Sarah
Sarah shipped the October 6 security release (four CVEs plus a follow-up across three versions), the most complex she has done, and reviewed fixes like @non_atomic_requests now recognizing async views. Discussions about contributor sustainability mean Django may sit out next summer's GSoC.
Django Fellow Report - Natalia
Natalia confirmed a low-severity vulnerability and prepared its patch, filed two public hardening tickets (multipart boundaries and response header characters), and paused new HackerOne submissions. She also opened a PR to replace Django's vendored makedirs with os.makedirs() on Python 3.15+.
Sponsored
Reach 4,300+ Engaged Django Developers
Sponsor this newsletter to reach an active community of Python and Django developers.
Articles
Django: set up its test suite with uv
Adam Johnson's alternative to the official contributing setup: one uv pip install -e . -r tests/requirements/py3.txt gets Django and its test requirements into a fresh virtual environment. If pylibmc won't compile, filter it out with grep -v and process substitution, and Django skips only the memcached tests.
Towards Async Transactions in Django
Transactions need ordered queries, but async tasks interleave at every await, so one task's rollback can throw away another's writes. Carlton Gibson lays out the design worked out at the Django on the Med sprints: async with transaction.atomic() gets its own worker thread and connection, with only the opening task allowed to nest. He is aiming for 6.2, and a follow-up post says the asgiref release it depends on is due at the end of October. django-filter 26.2 is also out, adding Python 3.15 and escaping LinkWidget labels by default.
Personal Replacement for Echofeed
With Echofeed winding down, Paul Traylor built his own blog-to-Mastodon pipeline on Django's new tasks framework. His django-feedparser-low package handles feed scraping with ETag and 304 support, and a feed_filter decorator ties a task to an Entry's post_save so each feed can trigger its own processing.
Django Beginners: Part 2
Andrew Miller fleshes out his django.contrib.beginners idea as "guardrails" (stricter, silenceable warnings against common foot-guns) and "scaffolds" (starting points like the registration view django.contrib.auth leaves out), in a package meant to be outgrown. He wants to build it with a group from day one and is looking for collaborators.
Django Day Copenhagen 2026 and Secrets
Efe Oge recaps the talks that stuck with him, from Tom Carrick on rate limiting to Denny on timezones, and the hallway finding behind his own signing talk: most teams hand secret management to Ansible Vault or Kubernetes rather than Django.
Iframes that finally fit their content
Chrome 154 adds frame-sizing: content-height, so an iframe grows to fit its content with one line of CSS instead of postMessage and ResizeObserver plumbing. The catch: the embedded page has to opt in with a responsive-embedded-sizing meta tag naming the origins allowed to size it.
Core Dispatch #11
Six weeks of CPython news: Python 3.15.0 final, new PEPs for None-aware access and coalescing operators, PEP 755 withdrawn in favor of PyPI policy, the inaugural Python Packaging Council election results, and two new core developers.
Podcasts
Django Chat #207: Hiring in 2026 with Jon Gould
Jon Gould is the founder of Foxley Talent, a recruiting agency focused on Python and Django developers. We discuss what he's seeing in the market these days, the benefits of attending Python & Django conferences, and why humans matter more than ever in our new AI age.
Prefer to watch? The full episode is also on DjangoTV.
Videos
Django Day Copenhagen 2026
The October 2 livestream is now split into individual talks on DjangoTV, including keeping secrets secret in Django, timezone-safe Django, pre-commit hooks that catch Django problems early, admin model views and stand-alone pages, maintainable CRUD, and the lightning talks.
Django Job Board
Django roles were light this week, so here are two machine learning openings at HFT Architecture, one senior and one junior, that should appeal to Python and Django developers looking to branch out.
Machine Learning Engineer at HFT Architecture 🆕
Junior Machine Learning Engineer at HFT Architecture 🆕
Projects
pradeeppc/django-permission-tracer
DRF permissions end up spread across permission_classes, @action overrides, get_permissions() and composed expressions. This resolves all of it into an endpoint-to-permission map, traces which operand denied a given request, and flags endpoints an anonymous user can reach, with --fail-on-unprotected for CI.
pradeeppc/django-q-watchdog
When a django-q worker dies mid-task, the task simply vanishes: no failed row, no traceback. This records each task as it starts and heartbeats while it runs, so lost and timed-out tasks land in django-q's own Failed tasks, and a hung one gets reported as frozen.
Sponsor Django News
Reach 4,300+ Django developers every Friday. See sponsorship details and rates.
16 Oct 2026 3:00pm GMT
Django: check version support with norwegianblue
Django projects end up slotting into a bunch of software release cycles: Django itself, Python, database servers, cache servers, and more. It can be hard for us developers to keep track of all of them, with their different support policies and end-of-life dates, and running an unsupported version means missing out on important security or bug fixes.
norwegianblue is a handy command-line tool for checking software support dates. It fetches data from endoflife.date, a community-maintained database of release cycles for hundreds of products, and displays it as a colour-coded table. It's from Hugo van Kemenade, the Python 3.14 and 3.15 release manager, and named after the deceased parrot from Monty Python's infamous Dead Parrot sketch.
Let's look at checking the release cycles for Django, Python, PostgreSQL, and other relevant tools with it.
Install it
norwegianblue provides two commands: norwegianblue and the shorter alias eol. I recommend the alias, since it's easier to type and remember, and will use it throughout this post.
To make both commands available everywhere, install norwegianblue globally. If you use uv, do so with uv tool install:
$ uv tool install norwegianblue
Otherwise, install it with your preferred tool, such as a global pip install or pipx.
Check Django
Run the command without any arguments to see the list of product names it knows about:
$ eol
adonisjs
akeneo-pim
...
Somewhere in that long list are django and python, among others you probably care about. Run the command a product name to see its release cycles, for example:
$ eol django
Here's the output of checking Django's release cycles today, trimmed to the most recent versions:
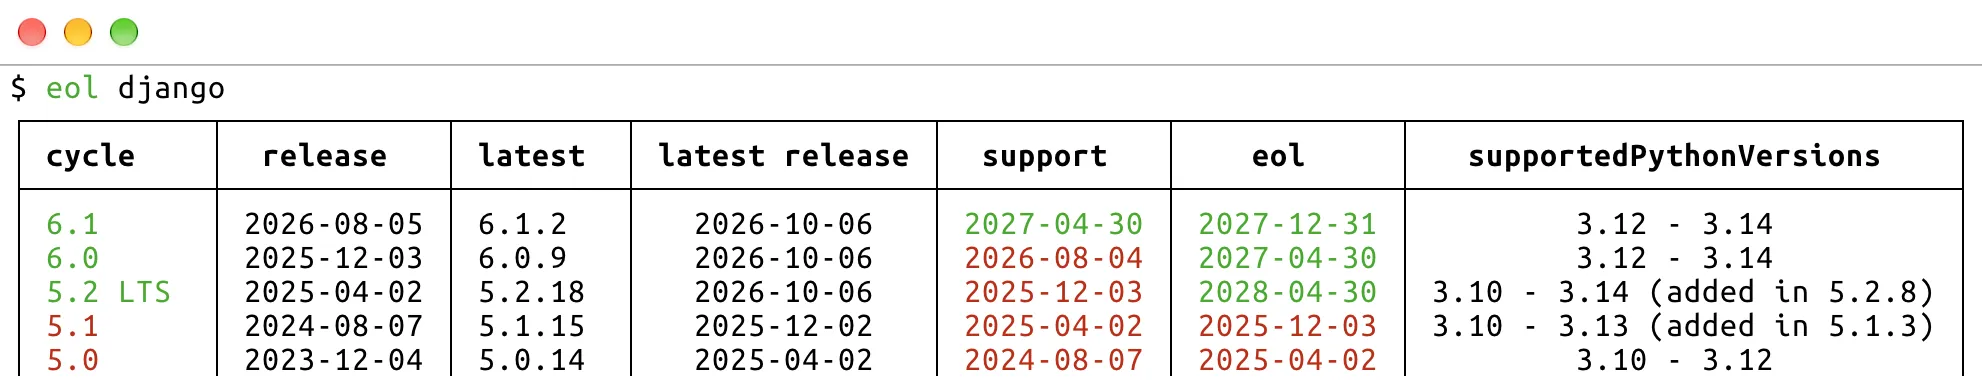
Each row is a feature release, with LTS (long-term support) releases marked. The columns show:
release: when the feature release came out.latestandlatest release: the latest patch version and its release date.support: the end of mainstream support, after which the release only receives security fixes.eol: the end of extended support, after which the release receives no fixes at all.supportedPythonVersions: the range of Python versions that the release supports.
The dates are colour-coded: red for dates in the past, yellow for dates within the next six months, and green for dates further out. The cycle names take the colour of their eol dates, so you can quickly spot unsupported versions.
So, from the above, we can see that Django 6.1, 6.0, and 5.2 are currently supported, with 6.0 recently moving into security-fixes-only mode. Django 5.0 and 5.1 are end-of-life, so if you're still using them, it's time to upgrade! (My tool django-upgrade can help).
Check Python
You also need a supported Python version, which you can check with:
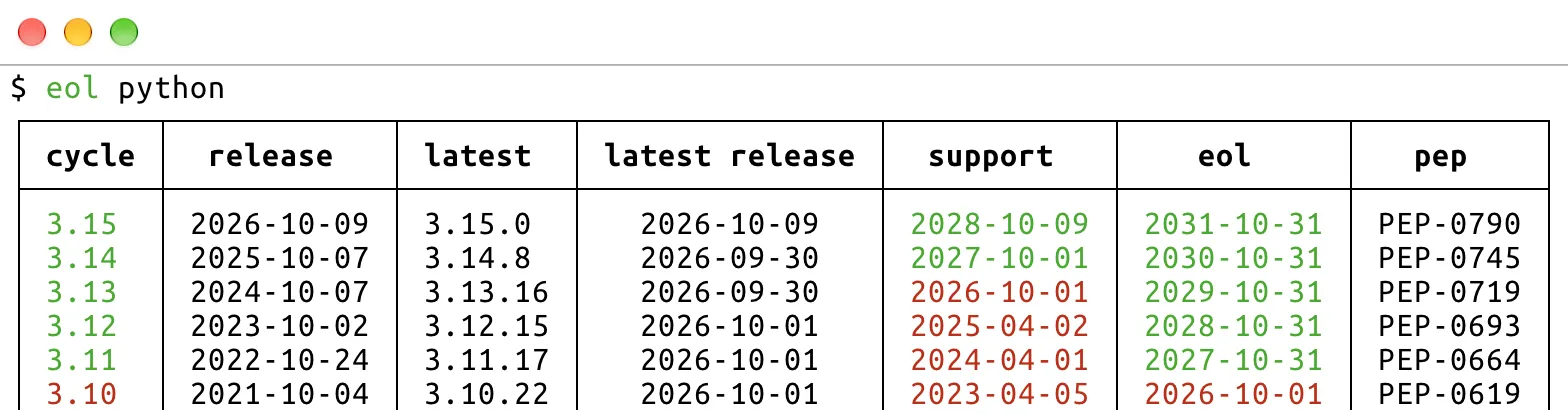
Here, support is the end of bugfix releases, and eol is the end of security releases. The pep column names the PEP containing each version's release schedule, for example PEP-790 for Python 3.15.
Python 3.10 reached its end of life recently, so it's time to upgrade any projects still using it!
Check PostgreSQL
The most popular database for Django projects is PostgreSQL, which you can check with the postgresql product name:
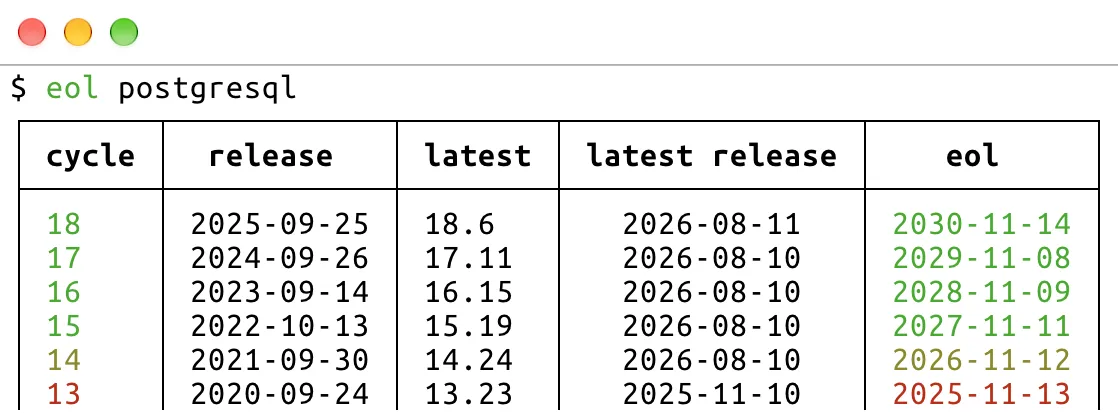
PostgreSQL supports each major version for five years, with no separate end of mainstream support. PostgreSQL 14 reaches its end of life next month, so it shows in yellow, as a warning to upgrade soon.
Django also drops support for old PostgreSQL versions, generally around their end-of-life dates. The Django database docs list the minimum version that each release supports.
Check other products
endoflife.date covers hundreds of products, so you can likely check most of your stack. Django-relevant products include:
- Other databases:
mariadb,mysql,sqlite,oracle-database, andmssqlserver. - Hosted databases:
amazon-rds-postgresql,amazon-rds-mysql,amazon-rds-mariadb,amazon-aurora-postgresql,azure-database-for-postgresql, andheroku-postgres. - Caches and other services:
redis,valkey,memcached, andelasticsearch. - Operating systems and web servers:
ubuntu,debian, andnginx. - Frontend tooling:
nodejs. - Django-based projects:
wagtail.
norwegianblue caches its data for the rest of the day, so repeated runs are fast. It can also output Markdown, reStructuredText, JSON, and other formats, as listed in --help, which may be useful for pasting into documentation or scripting checks.
Fin
Thanks to Hugo for making norwegianblue, and to the endoflife.date contributors for maintaining its data.
That web framework is not dead, nor is it just resting!
-Adam
16 Oct 2026 4:00am GMT
15 Oct 2026
Django community aggregator: Community blog posts
Pycon NL: zero-downtime multi-tenancy in Django - Thiago Bellini Ribeiro
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
Full title: zero-downtime multi-tenancy in Django: from user-centric to organizations-based architecture.
He works for Sendcloud. Originally their code was 2010-style Django. Every business object (Parcel, Order, etc) is linked to a django User. But... users can belong to organisations and organisations should be the ones connected to the business objects. Ok, they moved to a "core" user and "sub" users. But still users could only belong to a single organisation, for instance.
What they actually need is many users per organisation. And also many orgs per user. Roles per membership instead of per user. They designed a new system based upon this.
But: they had around 20 Django apps and 40 models with a link to user_id. How to migrate? The solution was to use a "proxy model". They started an "organisation" model that simply was a differently named Django model, pointing at the same table as the existing user model. This allowed them to keep almost everything the same with only minimal database migrations.
After that, they moved a little bit of functionality over to the new organisation model. Again, a small, minimal database migration.
They did it incrementally. They had all those apps and models to work through. Slowly but surely they got it done. Small steps that are backwards compatible help a lot.
They introduced a mistake-finder: an OrganisationAware mixin that logged direct .user access in production and produced errors in development. This helped turn up usage of the user model that wasn't findable through basic grepping and searching.
They also used libcst, an abstract syntax tree parser for python to go through the entire code and try and find corner cases where the old way of working was used.
In the end, everything was moved over to the real organisation model and the organisation-proxy wasn't needed anymore, so they could remove it. They

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. Of course there's a Hohenzollern-on-a-horse statue near the Hohenzollernbridge! This one is Wilhelm II, the Kaiser during the first world war (who fled to the Netherlands, btw).
15 Oct 2026 4:00am GMT
Pycon NL: what's inside an asyncio event loop? - Taras Kozlov
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
An asyncio event loop is defined by asyncio.AbstractEventLoop. That's a large API with more than 50 public methods, but only three are fundamental. At the lowest useful leve, the loop manages callbacks, i/o and timers.
- We need a way to put events on a queue and a way to grab events from a queue and execute them. call_soon()
- We need timers too, for callbacks that must be run after some time. call_later()
- Sleep only knows about time. Often we want to sleep until the next time, unless a socket becomes ready first. So we need a "sleep" that can be interrupted by I/O readiness. add_reader(), add_writer()
His own example implementation of asyncio for educational purposes is at: https://github.com/tarasko/eduloop , it is only 250 lines. Handy if you want to understand asyncio.
He showed this simple example code, incrementally implementing the points above.
The nice thing about asyncio is coroutines. A coroutine is an extended kind of function that can be paused and resumed. The result is a "future". A future represents an eventual result of an async operation. So: a future is pending until somebody supplies either a result or an exception.
For network connection there's Transport and Protocol.

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. St. Gereon church.
15 Oct 2026 4:00am GMT
Pycon NL: practical software architecture for Python developers - Henk-Jan van Hasselaar
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
First some terminology. Cohesion and coupling for instance.
-
Cohesion means how much the elements in a module belong together. "Belonging together": working towards the same goal or function. Watch out what your answer is: is there an "and" in the sentence. "This module reads data and puts it in the database". That's a sign of lower cohesion.
Cohesion also has to do with your mental load: what can you keep in your head at the same time?
-
Coupling. Basically the blast radius: how much breaks when you change an object.
-
Change. Not often talked about. Architecture is more than diagrams. Architecture actually is making future changes cheaper. No change, no pain.
Loose coupling, high cohesion is good. Tightly coupled, low cohesion is bad.
Python allows us lots of freedom. There is no enforcement of architectural boundaries. You have type hints, but they're not enforced. Python's basic assumption is that we're all reasonable and responsible programmers.
Let's look at an example problem. We have "the internet" that calls "our REST API" that stores stuff in "our database". We start with a single function in our API that queries the database and returns the results. But then we want to uncouple the data and the presentation layer: some ORM around the database table that is called by the view function (=the original API function). All fine. But... when the database changes, the ORM layer changes and then the view function needs to change. Coupling, anyone?
How can we fix this? By having some sort of contract between the layers. A domain model in between. A change in the database means a change in the part of the code that creates the domain object, but the view function is unaffected.
But such a view function often also contains business logic. That often means you're doing some talking to the database anyway. A normal approach is to put that part of the code into some "service" layer. You can also start writing adapters: convert the core domain models to some output format.
Closing remarks:
- Your business rules deserve a home!
- Put them somewhere the outside world can't hurt them.

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. Organ in the St. Aposteln church.
15 Oct 2026 4:00am GMT
Pycon NL: practical observability - Daria Korsakova
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
Full title: stop firefighting: practical observability for Python APIs, workers & jobs. The most important points:
- What does it mean for a system to be observable?
- Does that answer look the same for an API, a worker and a job?
- Metrics tell us something is wrong, but how do we find out what happened and where?
- How do we get the system to tell us, before our users do?
- Where do we actually start without doing everything at once?
They started with a prototype of a new system. They had questions like "does it work" and "is it fast enough". So they added a bit of monitoring: just a couple of logs and some simple graphs. And pushed it to production right away...
What does "observable" mean? It means you can answer questions like: is it up? Is it ready to serve traffic? Is it doing useful work? Is it failing? Is it slow? What changed recently? Which dependency/workload/customer/job/event-type is involved?
Is the answer the same for everything? No. You can have an API that restarts just fine on an error. So: it is up again, no problem. But because of the restart, it might have gotten a new IP address that isn't recognised by something else in your stack. So the API works, but the rest of the app doesn't. (That's a real case that they saw.) Or a nightly database import job might succeed just fine (but there's no new data as an upstream pipeline failed).
Metrics can help you notice problems before they become critical. Like API response times that slowly creep upwards. Time to investigate! Or something really goes wrong and the number of "error 500" messages spikes. Then you have to move from your metrics to the logs. There you can hopefully see what went wrong. If you need to dive deeper, you can start to use tracing (she doesn't recommend activating this right away).
Notifications. There's a sliding scale between "no observability" (the user has to report errors) and "alert on everything" (leading to alert fatigue). She recommends starting with a low number of alerts and slowly working upwards from there.
How to start? Best approach: roll it out in phases.
- Start with basic visibility: health/readiness, structured logging.
- Then workload metrics: request rate, error rate, number of processed jobs.
- Then high-confidence alerts: api not ready and so. "P99" latency. Job queue backlog without progress.
- Then dashboards.
- And last tracing and deeper instrumentation.
She wrote an article about it: part one.

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. Hohenzollern railway bridge plus kathedral.
15 Oct 2026 4:00am GMT
Pycon NL: building resumable Python pipelines - Yuvraj Singh Pathania
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
Full title: fire, forget, regret: building resumable Python pipelines.
If you run a task in an async loop, there's often no reference to the task. So it can be garbage collected! You can solve that by keeping a reference in some list. But even then, the whole process can die. What happens with your task then?
Often you have to re-run the task. He himself is into LLMs, so failed tasks that you have to re-run can become expensive.
BackgroundTasks is part of FastAPI and it works great for spinning off longer running tasks. Real handy, but there is no retry mechanism and no recoverability in case of crashes. "Fire-and-forget".
You can use specific task queues. ARQ, Celery, Dramatiq. In this case, the job itself is safe and can be re-tried. But not the individual steps within the job.
What he wants is durable execution. Write down every step you finish; on restart, skip what is written. It can save you lots of time (and possibly money). It might be simpler to set up than you think.
His code + slides are at https://github.com/batman004/fire-forget-regret

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. Model of the oldest parts of the St. Gereon church.
15 Oct 2026 4:00am GMT
Pycon NL: 3D data science with Python - Sergio Peral
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
Why Python for 3D? It often used to be done in C++. He showed an example in C++ and Python: the Python example was much shorter. But: Python is often only the interface, behind the scenes the library you use is often written in C/C++/Rust/etc.
The library landscape. There are many libraries you can use. Loading and storing: laspy, pdal, pyproj. Arays and speed; numpy, scipy, numba, dask. Processing: open3d, trimesh. Visualisation: pyvista, vtk. Learning: scikit-learn, pytorch3d.
One real pipeline. He used a pointcloud of part of the Jaarbeurs complex (where the conference was taking place), sourced from the Dutch public https://ahn.nl data source. The density is about 18 points per square meter and it uses some Dutch coordinate system ("RD New").
A point cloud is just a set of points in 3D space. You can also represent it as a mesh (3d areas). A "voxel grid" is also often handy: you convert what you're seeing into small stacked cubes.
What you need to do in a project: acquisition, preparation, exploration, analysis, visualisation.
No single library does the whole job. A partial exception is numpy: every step uses numpy vectors internally. He loaded the data with "laspy". Then voxel downsampling with open3d (he took the average of all points in a cubic meter). 700k points turned into 200k points this way: much more manageable. He then did a bit of clustering and colored the clusters by data from a land use database.
Making it fast. Using numpy's array operations is key. Don't iterate over a loop in Python, but let numpy do its work. That way, there's highly optimised compiled C++ code doing the work.
Some takeaways. Think in arrays, not points. Look befor you compute (so: check your data for obvious errors or problems). Make it small first. Let compiled code do the work.
His presentation is at https://github.com/Sloppy1999/pycon-nl-2026-3d-data-science

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. Railway tracks ('linksrheinische') behind the hotel, at the site of the former 'Köln Gereon' goods yard.
15 Oct 2026 4:00am GMT
Pycon NL keynote: sustaining open source for the future - Georgi Ker
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
This year is the first community-organized Pycon NL: hurray!
Most of us use open source as users. It is free! But all those open source projects only exist because someone started it and because someone maintains it.
"Care became contagious": she told the story about someone in Mumbay, India that started to clean up plastic waste that covered the whole beach. He and a 84 year old neighbor. Slowly other people joined in. Then a lot more. Care became contagious!
Python started when Guido van Rossum made a new language in his Christmas holiday.
But projects like this are fragile. The beach cleanup (almost?) stopped after 109 weeks: administrative lethargy, heckling, etc. (She said it stopped, but I guess it almost stopped, as later on she had photos of a clean beach with newly-hatched turtles). If you start a nice open source project, you're probably not thinking my dream is to answer Github issues for the next 20 years.
Sustainability is not endurance. Sustainability is regeneration. Joining a community, but also having the option to leave (just as an example).
Open source is safe. In open source project, code is public, knowledge is shared. A community. The community is the infrastructure. The community is the reason the code is trustworthy.
The Python software foundation holds the trademarks and licenses. Infrastructure like python.org, pypi, the documentation website. It hosts/helps conferences.
Pypi, the Python package index. 81.000 requests per second. And there are only two full-time security people working on it. Seth Larson and Mike Fiedler. We can call them heroes, but we might also look at Python's growth compared to the growth of its human infrastucture.
Our human infrastructure hasn't grown with Python's growth. And AI is making it more urgent. AI can consume whatever the community has to offer or has ever offered. Without giving something back. AI companies capture our value...
Public spaces are not self-maintaining. They need funding and public responsibility.
In 2025, the United Nations published the UN Open Source Principles. Countries are taking note. For example, Germany has the Sovereign Tech Fund, that invests directly in the people behind the code, supporting maintainers, community managers and technical writers.
She started Open community Leadership, helping communities create future contributors and leaders. The foundation is POPCOM: participation (how to join), ownership (how to gain responsibility), purpose (why people stay), connection (how relationships form), opportunity (how contributors grow), mentorship (how communities reproduce).
Regeneration takes people, time and money.
Open source is better together.

Unrelated photo from our Nelen&Schuurmans company trip to Cologne/Köln in Germany. Extreme low water in the Rhine: the 'beach' on the left should be fully submerged.
15 Oct 2026 4:00am GMT
Pycon NL keynote: believe in routes - Marcelo Trylesinski
(One of my summaries of the 2026 one-day Pycon NL conference in Utrecht, NL).
Routes: not every route starts the way people think. Here's his route through life.
You might know Marcelo from uvicorn, fastapi, starlette, logfire, Pydantic AI, MCP Python SDK, httpx2... It started for him in 2017 when he played league of legends for a full semester and failed all courses. This closed his main route: graduating on time and getting the expected job. Instead he got a good-enough job somewhere in Florianópolis (Brazil).
What was your closed route? It might be a degree you didn't finish. A field that changed under you. A job you didn't get. A move.
One thing he wants to talk about: curiosity needs a direction. You might be curious, but where does it get you? You might have a direction (like a degree plus the expected job), but direction alone, what does it get you? But if you have both curiosity and direction: that's nice.
Marcelo was curious in open source. What helped him a lot was to get involved. With open source you can look at issues and start fixing them and slowly getting more and more involved.
In 2020, the web question in python was "Django or Flask". He picked the third option: FastAPI, and started using it for his job. That resulted in bug reports or feature requests from colleagues that he then could fix in FastAPI itself. He even took over maintainership of python-multipart: by asking the not-really-active-anymore maintainer. Marcelo got the maintainership because he was already known in the community through his other open source work.
Asking can chance your path, just like with the maintainership of python-multipart. Likewise, he asked for a job at Pydantic though his open source contacts. And got it! He works for Pydantic ever since.
What can you open if you want to change your route? What can you do? Is it too late to:
- Start contributing to open source?
- Learn a new language?
- Pick up a hobby?
- Change careers?
According to Marcelo, it is never too late. One thing he'd focus on is fun. Have fun with open source, for instance, in his case. It almost started out as his hobby. And he likes AI right now. One of the things he's having fun with right now is zttp, an IO-less HTTP parser for Python with a Zig core. He mentioned that AI helped him experiment. Another project is pgtask, a Postgresql-native durable task queue + workflow engine.
A big part of his personal workflow is to look at his github notifications for all his projects. Just look at one notification (and thus one issue or PR) at the time and to bring it a little step forward, one at a time.
Normally he handled between 300 and 700 pull requests per year. This year it is already above 2500 (due to AI). Like many maintainers, the workload has gone up. He noticed he actually made noticeably fewer releases this year, though.
Maintainance is a form of care. Care and feeding for your projects. Triaging issues, reviewing PRs, saying "no", closing the noise. You're a maintainer, too. Anything that only works because someone shows up. It might be your own life, your family, your club, your project.
Marcelo once got the tip to grow on three tracks at once. Don't ignore any one of them, you need them all:
- Professionally: grow in your job.
- Personally: family, relationships, friends.
- Healthily: exercise and nutrition. Body and mind.
You might notice that one of those three tracks is starting to eat the others. You can't remember the last day without a laptop, for instance. Or you spend a year at home on open source and tell yourself it's fine.
He made a comment about AI. He works on AI tools every day. He still doesn't know where it goes. He knows some of the routes might be closing for you because of AI. As a maintainer, he actually uses AI. He lets AI review pull requests, he lets it write his one pull reuqets. Security advisories. But AI doesn't diminish his enthousiasm and curiosity.
Remember the bring it a little step forward, one at a time he mentioned before? Your route will be different from Marcelo's. But the only thing you need to get further along on your own route is to move a little step forward every time.

Unrelated photo from our `Nelen&Schuurmans <https://www.nelen-schuurmans.nl>`_ company trip to Cologne/Köln in Germany. The salad I had for lunch on Saturday was tasty.
15 Oct 2026 4:00am GMT
14 Oct 2026
Django community aggregator: Community blog posts
Hiring in 2026 - Jon Gould
🔗 Links
- Foxley Talent
- Foxley Talent YouTube
- People or Code show on YouTube and Spotify
📚 Books
- The Infinity Machine by Sebastian Mallaby
- The Concept of Mind by Gilbert Ryle [Carlton]
- The Go-Giver by Bob Burg and Jon Mann
📦 Projects
- FarhanAliRaza/prongs - run just the tests you edited
- justinmayer/django-benchmark - Django performance benchmark profiler
🎥 YouTube
14 Oct 2026 3:00pm GMT
Django Beginners: Part 2
I first wrote about this idea in day 287 where I framed it under the name of django.contrib.beginners. The idea (as a quick reminder) is that if I wondered if we could have a package that added extra warnings or safeguards for beginners that meant they would not make common foot-gun mistakes with Django. I've since expanded on the idea a bit and formalized two concepts that I've called Guardrails and Scaffolds.
Guardrails being those warnings, those limiters that are stricter defaults that prevent beginners from committing those common mistakes when starting with Django that we know to avoid. They can be opinionated, and we can choose whether to turn them on and off, and silence them, or that kind of thing.
Scaffolds on that other, which are pieces of code that at times prevent the rabbit hole or make things easy to get started. A really good example of this is that django.contrib.auth, doesn't ship with a user registration view & url because there are an infinite combinations of what you could do with registration in a project. But that often causes a new developer to jump down the rabbit hole of the auth documentation and become confused. And so the scaffold could be a simple register view and URL that gets included. Let's be clear, these scaffolds are not whole projects, but starting points for specific points in a project.
One key concept for the whole package is that it's supposed to be outgrown. It's something you start using, and then as you hit those walls intentionally and you understand why that warning exists and why you need to disable a check or move code into your project, it's at that point that you start to uninstall the package and install alternatives e.g. take the register view, you install allauth or django-registration as more complete solutions.
However, the core question I've come to recently is whether I could build this package (and I fully intend to build this package!) as I see it, as a valuable aid to the community. But I wonder, due to its nature, once the core infrastructure of the package exists, or even building out the core infrastructure of the package, I wonder if this could be built as a group or as a community or as a smaller team within the community. Rather than a solo contributor maintainer, the default being starting as a group, as a group of people, rather than, and this happens before a line of code is committed. I'm a solo contributor, so I'm just wondering how do I go from an idea with some design documentation to getting people on board, to code being written, committed, reviewed and published.
I see two parts to contribution in this package. First is to build out and maintain the core infrastructure. Second, due to the nature of the package of there being a long potential list of smaller contributions in the forms of new guardrails and new scaffolds. How do I garner those contributions, which then may elevate people up into maintaining the first set, which is the core code that enables them to be used. I don't have any solutions to this. I'm going to start building it when I have some free time (or some free agent time). But I welcome your thoughts and opinions as a community as to what my first or next step should be, and if you're interested, that could be get in touch. But what would that next step be? And I'm thinking partly from asking people to be involved, but also do we have a Discord channel, or server, where we start collaborating on this? How do we create that shared collaboration environment in a disparate community that's physically disparate and can be on desperate online because not everybody hangs out in the same place. I would be curious to hear people's thoughts. Thanks!
P.S. One final point on the package itself, I do intend this to also allow as a place for small changes to be experimented with that could be candidates for core changes in core Django, but don't perhaps warrant a full package in themselves if they are so small and fall with the concepts of the guardrails and scaffolds.
14 Oct 2026 5:00am GMT
13 Oct 2026
Django community aggregator: Community blog posts
`replace()` as an iterator
String.prototype.replace() with a global regular expression and a function has iterated over the interesting parts of a string since 1999, long before array extras like forEach() and filter(). It is rarely the best tool today, but it is still in a lot of code, for historical reasons and for a certain technical beauty. Let's see how it works, what it is good for, and what it costs, so that a replace() whose result goes unused makes sense when we meet it.
13 Oct 2026 10:00am GMT