18 Nov 2026
 Drupal.org aggregator
DDEV Blog: SQL Sync for DDEV: Drush-Style Database Sync for Any SSH Server
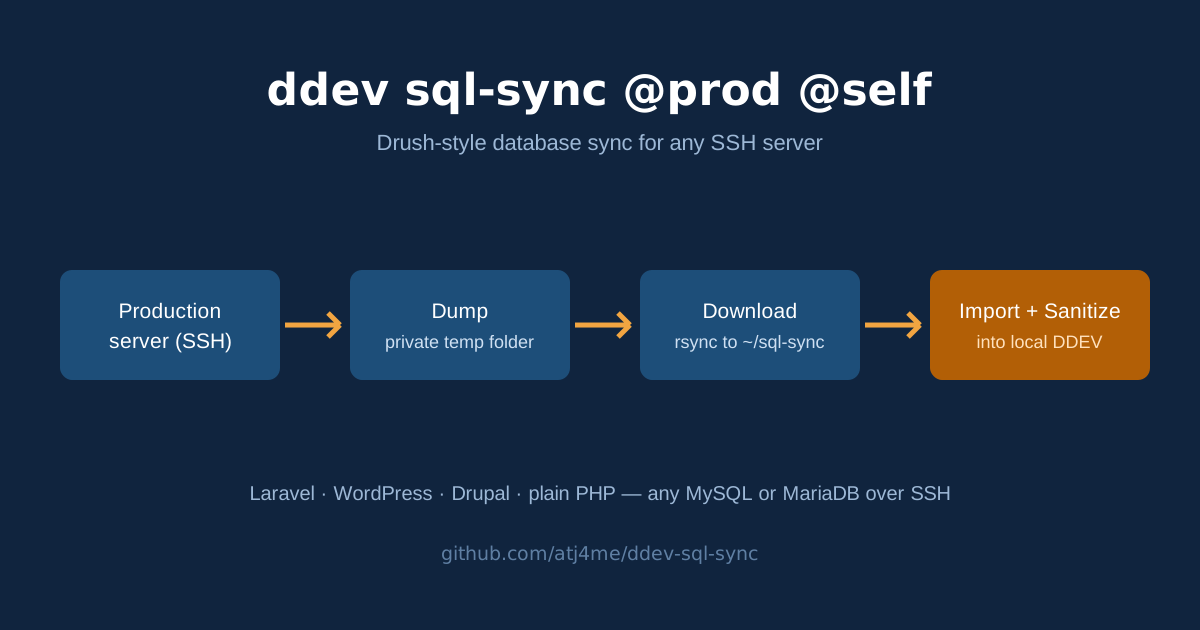
Anyone who has worked with Drupal knows this command:
drush sql-sync @prod @self
One command, and the local site has a copy of the production database.
I use Drush a lot, so I wanted the same thing for my personal projects. They are Laravel, WordPress and plain PHP sites, and they live on all sorts of hosting: shared accounts, VPSs, dedicated boxes - a good number of them running cPanel, which itself runs on shared and dedicated hosting alike. What I had instead was the usual mix of phpMyAdmin exports and one-off scripts that I had to remember each time.
DDEV does have pull providers. The ready-made ones are for hosted platforms like Pantheon and Acquia, but the examples it ships also include an rsync one, for pulling a dump down from a plain server over SSH. I do not want to overstate the gap: that example works. But it is a starting point you adapt, not a finished tool. Every project needs its own provider file, written and kept up to date separately, and sanitize is on you. I kept missing the Drush shape: one aliases file, the same command in every project, and sanitize taken care of. So this add-on is that shape, packaged: ddev-sql-sync.
One thing to state up front: I designed this add-on, and it was built and tested with the help of an AI agent, Ryan (Muse), working under my direction. There is a bit more about that at the end.
Where I use it:
- Refreshing local data. I can bring a local site up to date with production content before I start work on it.
- Debugging with real data. I can reproduce a production issue locally, with user emails and passwords already scrubbed.
- Any server I can SSH into. Shared hosting, a VPS, a dedicated server, with or without cPanel - if it runs MySQL or MariaDB, it works. There is no platform account or API in between.
How it Works
The configuration is one YAML file of named aliases, much like Drush site aliases. A run of ddev sql-sync @prod @self then does four things:
- Dump - SSH to the server and make a database dump in a private temp folder there.
- Download - rsync the dump to a local folder (by default
~/sql-sync), then delete the copy on the server. - Import -
ddev import-dbinto this project. You are asked to confirm first. The current local database is replaced. - Sanitize - scrub user emails and passwords in the local database. On by default.
Note the target in the command. cp, rsync, scp and Drush's own sql-sync all take a source and a destination, so this one does too. @self is the only target it accepts; anything else is refused. The add-on only ever reads from the server, and having the target in the command keeps that in front of you.
Prerequisites
Two things to sort out first:
-
SSH from your own machine. The add-on is a host command. It runs
sshandrsyncon your computer, using your~/.ssh/configand your keys, the same way you would by hand. It does not useddev auth ssh, and nothing SSHes from inside the web container. So this has to work first:ssh your-server-alias 'echo ok'If that asks for a password, set up key login first (
ssh-copy-id). If the host uses a different SSH port, which is common on shared hosting (most cPanel accounts, for instance), put the port in the~/.ssh/configentry for that alias. -
A way to dump the database on the server. If the app has an export tool of its own, the add-on uses that (see Dump strategies below). Otherwise the server needs
mysqldump. You do not have to guess: the--dry-runcheck further down will tell you if it is missing.
You also need DDEV v1.24.10 or later.
Installation
-
Install the add-on:
ddev add-on get atj4me/ddev-sql-sync -
Restart DDEV:
ddev restart
Installing the add-on creates .ddev/sql-sync/aliases.yml from the example that ships with it, if you do not have one yet. Add-on updates never overwrite your aliases.yml, and removing the add-on does not remove it either.
Configuration: .ddev/sql-sync/aliases.yml
This file is the whole configuration:
local:
  dir: ~/sql-sync # where downloaded dumps are kept

prod:
  host: myserver # an ~/.ssh/config alias or a hostname
  user: deploy # optional; ssh target becomes user@host
  root: /var/www/example # the app's path on the server
  tmp: /tmp # optional; temp folder on the server
Define as many aliases as you like (prod, staging, and so on) and pick one per run: ddev sql-sync @staging @self.
Each alias needs two keys, host and root. The optional keys:
| Key | Purpose |
|---|---|
platform: |
laravel, wordpress, drupal or php. Usually unset - see Platforms below. |
options: |
Extra SSH options, e.g. options: -i ~/.ssh/prod_key. |
jump: |
A jump host (bastion) passed to SSH as -J. Prefer ProxyJump in your ~/.ssh/config - that is the durable place; this key is for one-off syncs. |
dump: |
A command on the server whose output is the dump. Replaces the dump strategies below; works for any platform. |
database: |
Explicit database credentials, for setups where the app's config cannot supply them (see below). |
sanitize: |
Path, relative to the project root, to your own SQL file to sanitize with after import. |
Where the database credentials come from
Normally you do not configure any credentials at all. When it is time to dump, the add-on reads them from the app's own config on the server: .env for Laravel, wp-config.php for WordPress, sites/default/settings.php for Drupal.
For setups where that cannot work - a managed database host, or credentials split across files - an alias can pin the values itself:
prod:
  # ...
  database:
    name: example_db
    username: example_user
    password: example_password
    host: 127.0.0.1 # from the app server's perspective
    port: 3306
Any field you leave out falls back to the app's config, field by field. You can pin just the password, or just the host and port for an RDS-style endpoint.
Treat a filled-in
password:as a secret.aliases.ymlsits under.ddev/, which many projects gitignore - check yours - andchmod 600 .ddev/sql-sync/aliases.ymlis a good idea if you use this block. The password is passed to mysqldump through theMYSQL_PWDenvironment variable only, never as a command-line argument, and it is never printed.
Usage
ddev sql-sync @prod @self           # source, then target - like cp / rsync / drush sql-sync
ddev sql-sync @prod @self -y        # skip the confirmation prompt
ddev sql-sync @prod @self --dry-run # preflight checks only - nothing is dumped or imported
| Flag | Meaning |
|---|---|
--sanitize / --no-sanitize |
Sanitize after import (on by default), or skip it. Skipping prints a loud warning: the local database then holds real production emails and password hashes. |
--dump-dir=<path> |
Where the dump is downloaded to (overrides local.dir). |
--no-dump |
Do not make a new dump; fetch the dump file an earlier --no-sync run left on the server. It is verified against its completion marker before anything is imported. |
--no-sync |
Only create the dump on the server and leave it there; do not download, import, or sanitize. |
--dry-run |
Preflight only: check SSH, platform, dump strategy, credentials (the password is never shown), database size and disk space, then print the plan. Takes no dump, imports nothing, and writes nothing on the server. |
-y, --yes |
Do not ask for confirmation. |
-h, --help |
Show help. |
Downloaded dumps are saved as <dump-dir>/<alias>.sql - or <alias>.sql.gz, if the dump turns out to be gzipped - and kept after import, which is handy if you want to import the same dump again. They do contain production data, so delete them when you are done with them: rm ~/sql-sync/*.sql*.
Dump Strategies and Platforms
For each alias, the dump is made in one of these ways, in this order:
dump:override - if the alias sets one, it always wins.- The app's own export tool, run on the server in the app root, if the platform has one and it is installed there. If it is missing, the next strategy is used instead of failing:
- WordPress →
wp db export(WP-CLI) - Drupal →
drush sql-dump - Laravel → there is no native data export (
schema:dumpis structure-only), so Laravel always uses strategy 3.
- WordPress →
mysqldump- with credentials resolved as described above.
The run tells you which strategy it used.
The platform is worked out per alias: the alias's platform: key if you set one, else this project's DDEV type from .ddev/config.yaml (the laravel and wordpress types map to themselves, and every Drupal variant - drupal7 through drupal11 - maps to drupal), else php. Some notes per platform:
- Laravel / any
.envapp - credentials come from<root>/.env, under the usual Laravel key names (DB_DATABASE,DB_USERNAME, and so on). One caution: Bedrock-style WordPress uses different key names in its.env(DB_NAME,DB_USER), so for a Bedrock site, pin at least the name and username in the alias'sdatabase:block. - WordPress (classic) - credentials come from the
DB_*defines in<root>/wp-config.php, or one level up, as WordPress allows. The table prefix is read from the config, so sites with a prefix sanitize properly. - PHP (generic) - DDEV's generic
phptype, and the fallback when nothing else matches. No app export tool, so it always uses mysqldump. Credentials come from<root>/.envif there is one, merged under the alias'sdatabase:block - for a generic app, that block is the expected main source. There is no bundled sanitize: asanitize:file is honoured if you set one, otherwise the run reports that no sanitize ran. - Drupal - dump through Drush when it is available. Otherwise credentials are read from the default
$databasesentry insettings.php. That read is best-effort: a settings file that gets its credentials from the environment may not give them up, and then adump:override or a pinneddatabase:block is the way out. Asanitize:file on the alias, if set, takes precedence overdrush sql-sanitize.
Sanitize
Sanitize runs after the import, and only on the local database:
- Laravel - bundled SQL:
users.emailbecomesuser<id>@example.test,users.passwordbecomes a hash ofpassword,remember_tokenbecomesNULL. - WordPress - bundled SQL on the users table, using the site's actual table prefix: email becomes
user<id>@example.test, password becomesMD5('password'), which WordPress accepts at login and rehashes on its own. - Drupal -
ddev drush sql-sanitizewhen the local project has Drush; otherwise asanitize:file from the alias; if neither exists, the run says so. - Any platform - a
sanitize:file set on the alias is always honoured.
If sanitize is switched on but nothing could actually be applied, the run ends with "completed WITHOUT sanitize" and a non-zero exit code. It does not report success and leave live production data sitting in your local database.
What Happens on the Server
Since this runs against production, here is everything a run does there:
- It reads the app's config file to get the credentials.
- It creates one dump file in a subfolder of the alias's temp folder -
/tmp/ddev-dumpsby default. The folder is mode 700 and the dump mode 600, so on a shared server the other accounts cannot read it. If a run fails partway, the partial dump is removed rather than left behind. - On success, it writes a small completion marker next to the dump with the dump's exact size in bytes. The local side checks that size before trusting the file, including on a later
--no-dumprun, so a truncated dump is never imported as if it were whole. - After the download, it deletes the dump and the marker on the server. If the import itself then fails, the server copy is kept, and the run tells you how to retry with
--no-dump.
That is all. Nothing is written to the app or its database: no cache clears, no migrations, no restarts. Before dumping, the run also estimates the database size and stops if the temp filesystem has less free space than that, because a dump filling the disk is the one realistic way a sync could hurt a small server. If the size cannot be estimated, the run says the check was skipped instead of saying nothing.
Testing Safely
New server, or you would rather be careful? Work up in steps:
ddev sql-sync @prod @self --dry-run- preflight only, as above. You get a result per check, plus the plan, and then it stops.ddev sql-sync @prod @self --no-sync- a real dump, made on the server and left there. Nothing is downloaded or imported.ddev sql-sync @prod @self --no-dump- fetch that dump, verify it against its marker, import and sanitize.ddev sql-sync @prod @self- the full run.
Troubleshooting
- "mysqldump is not installed on this server" - the preflight found no
mysqldumpin the SSH session's PATH and no usable app export tool. Install the MariaDB/MySQL client tools on the server, or give the alias adump:command that makes the dump another way. - Credentials look right but authentication fails - check for a stale
~/.my.cnfon the server, in the sync user's home. A[client]password in that file silently overrides theMYSQL_PWDenvironment variable for MariaDB clients, this tool included. I ran into exactly this in my own testing. - The run asks for an SSH password or hangs - the add-on expects SSH without prompts. Test with
ssh your-server-alias 'echo ok'and fix your key setup first. - "unknown alias" - the name after
@has to match a top-level key inaliases.ymlexactly.
Uninstalling the Add-on
ddev add-on remove sql-sync
This removes the command and the files that came with it. Your aliases.yml and any downloaded dumps are left where they are - delete them yourself if you want them gone.
How This Add-on Was Made
My first instinct is usually a workaround with the tools I already know, and Tailscale and Drush have carried me through more situations than I can count. This one started the same way: a personal project needed its production database locally, and the sync had to suit my workflow. As noted at the top, I designed the add-on and an AI agent built and tested it under my direction. Before it was released, the code went through an independent read-only audit and an end-to-end rehearsal against a container standing in for a production server, and what those turned up was fixed. It is here in case it suits someone else's workflow too.
Additional Resources
- ddev-sql-sync on GitHub: source, issues, and the full README.
- Releases: release notes for every version.
- DDEV add-ons: how add-ons work and how to write your own.
- DDEV hosting providers: how
ddev pulland provider files work in DDEV itself. - rsync.yaml.example: DDEV's shipped example rsync provider - it runs inside the web container after
ddev auth ssh, and pulls a database dump and files tarball that already exist on the server. - Example providers: the
git.yaml.exampleandlocalfile.yaml.exampleexamples that ship alongside the rsync one. - Drush sql-sync: the command this add-on is modelled on.
I hope this helps anyone else who has wanted drush sql-sync for the sites they run outside Drupal. If you run into issues or have suggestions, feel free to open an issue on the GitHub repository.
18 Nov 2026 8:10pm GMT
DDEV Blog: Giving an AI Agent Its Own Linux User (Without Breaking DDEV)
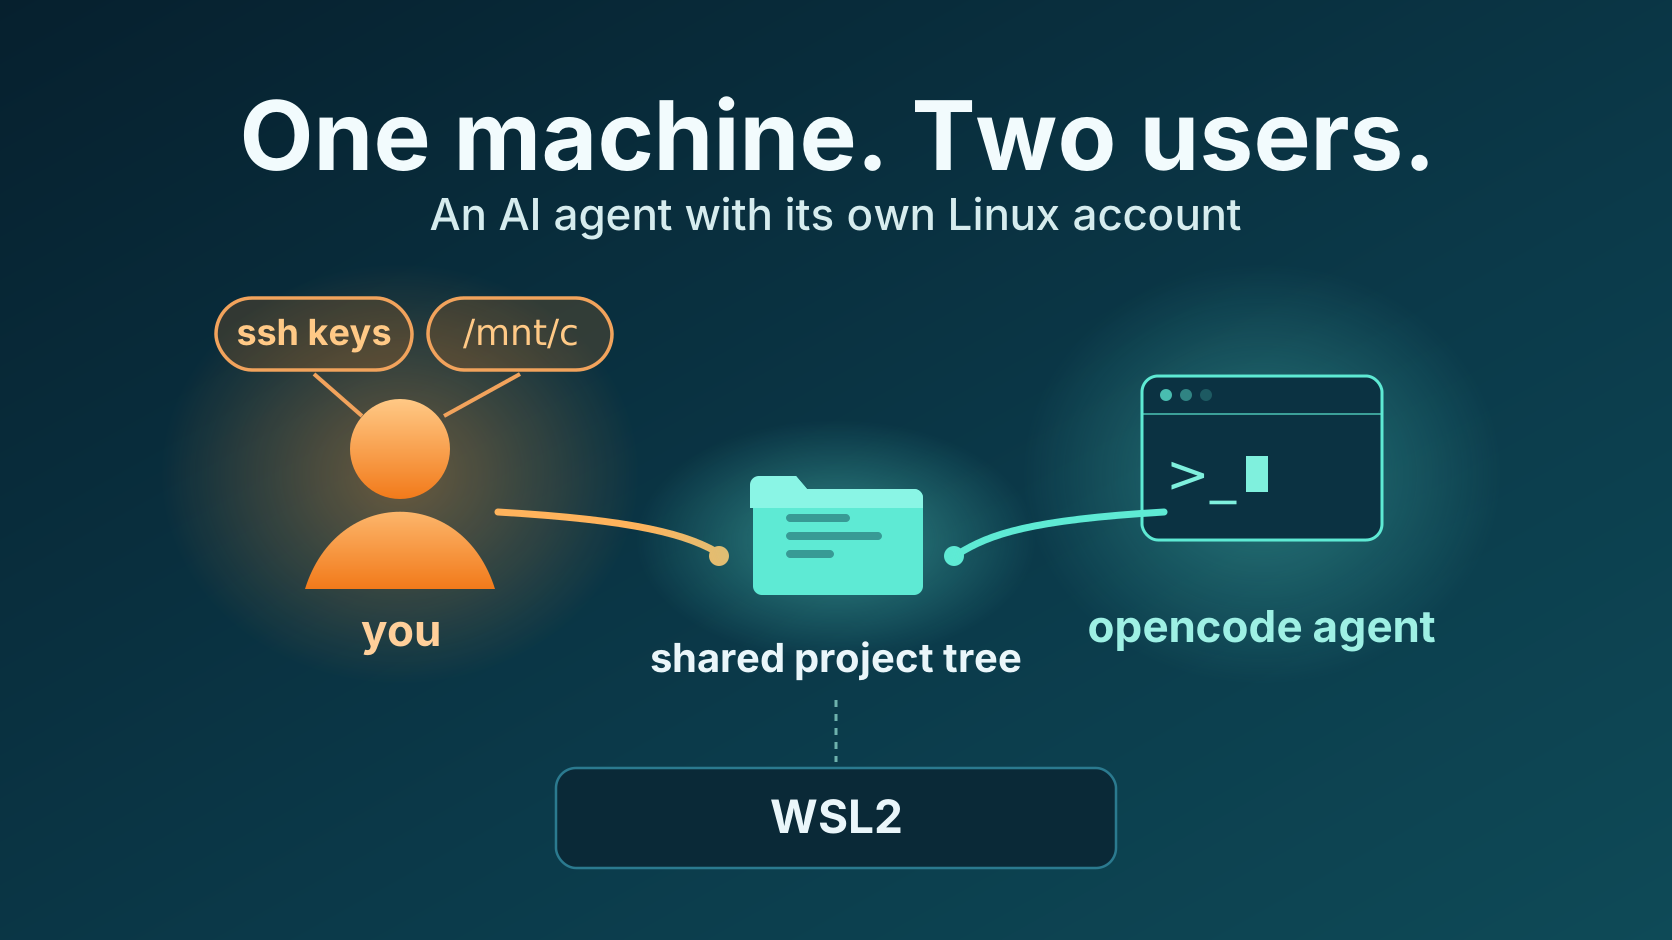
TL;DR: My coding agent runs on my WSL2 machine as its own Linux user, with its own home directory and its own rootless Docker daemon. DDEV runs as that same user, in my terminal and in the agent's. My workflow did not change. This post explains why I did it, what it took, and what broke along the way.
The surprise came quickly: My agent had a terminal open in a client project, about to run ddev composer install, and I wanted to know what it could reach if a task ever went sideways. The answer was: everything. The agent ran as my user, so it could read my SSH keys, push with my Git and gh credentials, reach everything on the Windows side through /mnt/c, and talk to a Docker daemon running as root. Its permission system asked before every Bash command, and I approved commands in five-second intervals, all day. At some point I stopped reading the prompts and clicked allow blindly. That was the moment I knew the agent and I needed a different kind of protection.
What an agent can do to your machine
An agent with a shell can wreck the machine it runs on (delete files, fill the disk), take it over (steal credentials, plant a backdoor, use the Docker socket), write code that does more than the task asked, ship private code and secrets somewhere else, or reach network services it was never meant to touch. Wherever it runs, those risks travel with it.
This post is about the second one: taking over the machine, through everything the agent can reach because it runs as my user. A separate Linux user shrinks exactly that blast radius. It does not stop malicious code from being written or project files from leaving; reviews and network policy are the answers there, and the end of this post is honest about what remains unsolved.
So I turned the question around. Instead of asking what I could withhold from the agent, I asked what the smallest identity is that still lets it do the job.
What an agent inherits when it runs as you
On a typical WSL2 setup, an agent running as your user inherits the blast radius of your account:
- Your home directory: SSH keys,
.gitconfig, credentials files, everything in~/.ddev, including database snapshots and any keys imported withddev auth ssh. - The Docker socket, which on a default rootful installation is root-equivalent.
- Windows interop:
/mnt/cand the ability to run.exefiles. On WSL2, the Linux side reaches straight into Windows; a shell command is all it takes.
Approval prompts don't solve this, because I stopped reading them. They had become background noise long before the agent got productive. Newer agents don't even ask that much: Claude Code has defaulted to auto mode since August 2026, which approves most commands on its own.
The old answer from Unix
Services on a Linux machine have not run as the admin's personal user for decades. www-data, postgres, deploy: every daemon gets a dedicated account with exactly the access it needs, and nobody considers that exotic. It is the default way to run untrusted or semi-trusted software on a shared machine.
An agent that edits my code, runs my tests, and starts my containers is a new coworker on the machine, and coworkers get their own account.
The obvious alternative, especially for DDEV users, is to run the agent inside the web container. I ruled that out, for a DDEV-specific reason. An agent inside the container cannot execute host commands itself, but it does not have to: through the shared project tree it stays writable for the agent, so it can plant a custom command in .ddev/commands/host/ and register it as a hook in .ddev/config.yaml. The next time I start the project, DDEV runs that hook on the host, as my user, with no container around it. The boundary has to hold on the host itself.
The other escape is the cloud: coder.ddev.com runs DDEV in a cloud workspace, not on your machine at all.
So that is what I did: the agent, opencode, now runs as a dedicated opencode user on my WSL2 box, and I kept the rest of the machine mine.
The setup, in four decisions
The whole architecture fits on a napkin:
       WSL2 machine: one machine, two users

  me (uid 1000)                opencode (uid N)
  shell, IDE, git              opencode agent
  browser, Windows interop     DDEV, rootless dockerd
        │                             │
        └──── ddev runs as opencode ──┘
                       ▼
     one DDEV home: /home/opencode/.ddev
     one rootless Docker daemon
     one working tree per project, shared
     through a group (setgid + default ACLs)
One: the agent gets its own user. My home directory is mode 750 and not group-shared, so the agent cannot read my keys or dotfiles. The agent user gets no Windows interop at all: no /mnt/c, no .exe execution. When a task needs to open something in my browser, the agent cannot do it. Only I can run that command, and then it works.
Two: DDEV runs as exactly one user, the agent's. This is the decision that makes or breaks the setup, and it is counterintuitive. DDEV is not multi-user aware; it expects one ~/.ddev, one Docker daemon, one project list. So the agent user owns DDEV. When I type ddev start in my own terminal, a shell function and a small sudoers helper re-exec it as opencode, with the right HOME and DOCKER_HOST. The sudoers file has four rules, all targeting opencode, none targeting root, none running anything as me. The result: ddev list in my terminal and in an agent session show the same projects, docker ps lists the same containers. There is one DDEV home, one daemon, no split-brain.
Three: the Docker backend is rootless and owned by the agent user. DDEV has supported Docker Rootless since v1.25.0 (blog post, docs). The daemon socket lives under /run/user/<uid>/, owned by opencode. The agent can start and stop containers for our projects, but it never touches a root-equivalent socket, because there isn't one on the machine anymore.
Four: we share the working tree through a group, not through an identity. Both users need to read and write the same project files. A shared group with setgid directories, default ACLs, and umask 002 does that. The agent edits a file, I edit the same file, git pull works from both sides, and nothing needs to run as the other person.
What it is like day to day
The agent can do every project task I do: ddev start, ddev composer, make tests, vendor/bin/runTests.sh -s [cgl|phpstan|unit|functional], and commit. It cannot read my SSH keys, cannot reach my home directory, cannot touch Windows, and has no path to root. Browser-opening commands like ddev launch and ddev mailpit still work, but only from my terminal.
The part I did not expect: permissions inside the agent became more meaningful, not less. As long as the agent ran as my user, my answer to every risk was bash: {"*": "ask"}. Every command needed approval, because a single one of them could read my SSH keys in my WSL home directory or on the Windows side. On its own user it cannot get there, so I could flip the rules: allow Bash by default, and ask only for the few sensitive paths, like auth.json. The prompts that remain are the ones worth reading, because they are about the task, not about the keys to the building.
What still hurts
Two UIDs, one working tree: most tools are not designed for that. The concept hangs on group permissions: every file belongs to whoever created it, the agent or me, and the group-write bit decides whether the other one can still write to it. Whenever a tool sets an explicit file mode, it bypasses umask and ACLs, and then a git pull or an edit dies with permission denied until someone re-asserts the group write. These things are solvable. A short find … chmod g+w after the tree-changing commands puts them right, but they will happen, and you should know that going in.
Where the operating system actually protects me is everything outside the project trees. Credentials under /home/dev/private/credentials.json, or on the Windows side under /mnt/c/Users/steffenmaechtel/.ssh/, are unreachable for the agent: a cat fails at the filesystem, no matter which command I approve. Inside the project tree, protection stays soft-only. I deny reads on auth.json in the agent's configuration; if I blindly approve a Bash command like cat auth.json, the content ends up in the prompt anyway. That is deliberate: auth.json holds the credentials for external private Composer repositories, and even that file cannot carry an operating-system deny. ddev composer install runs Composer inside the web container, as the same host UID as the agent, and Composer needs it to reach those repositories. The hard boundary is my home directory. Inside the projects, the agent's own rules and my reading of the prompts do the work.
What this setup protects against, and what it does not
| Risk of an agent with a shell | Covered by this setup? |
|---|---|
| Wrecking the machine | Partly. Your home, the system, and the Windows side survive; disk, CPU, and the project trees stay shared. |
| Taking over the machine | Yes. That is what the separate user, rootless Docker, and the missing Windows interop are for. |
| Writing code that does more than the task asked | No. Reviews and CI are the answer. |
| Exfiltrating code and secrets | Partly. What the agent cannot read, it cannot leak. Project files can still leave. |
| Unwanted network access | No. Nothing here restricts the network. |
Most of these risks are triggered by injected instructions in content the agent reads. An identity boundary does not fix that; it only shrinks what a hijacked agent can reach.
If you want this
This is a WSL2, Linux, and macOS approach. It leans on users, groups, and filesystem ACLs, so it does not carry over to traditional Windows.
You can build the whole thing by hand: useradd, dockerd-rootless-setuptool.sh, recursive ACLs, four sudoers rules, a wrapper script, and a shell function. When I started, I estimated three days, agent-assisted. It took longer than that; there is more to it than a second user and a rootless daemon. That is the reason I packed the result into opencode-permissions-kit (MIT, community project in beta): so nobody else spends a weekend on it.
Resources
- Podman and Docker Rootless in DDEV - how DDEV supports rootless container backends
- Docker Rootless setup in the DDEV docs - installation and requirements
- coder.ddev.com - DDEV in a cloud workspace, an alternative boundary
- opencode - the agent used in this post
- opencode-permissions-kit - the setup from this post, ready to run (MIT, community project in beta)
18 Nov 2026 8:10pm GMT
Security advisories: Drupal core - Moderately critical - Gadget chain - SA-CORE-2026-018
drupalDrupal core contains a chain of methods that could be exploitable when an insecure deserialization vulnerability exists on the site. This so-called "gadget chain" presents no direct threat, but is a vector that can be used to achieve remote code execution if the application deserializes untrusted data due to another vulnerability.
This issue is not directly exploitable.
This issue is mitigated by the fact that in order for it to be exploitable, a separate vulnerability must be present to allow an attacker to pass unsafe input to unserialize().
Install the latest version:
Drupal 11
- If you use Drupal 11.4.x, update to Drupal 11.4.13.
- If you use Drupal 11.3.x, update to Drupal 11.3.22.
- Drupal 11.2.x and below are end-of-life and do not receive security coverage.
Drupal 10
- If you use Drupal 10.6.x, update to Drupal 10.6.22.
- Drupal 10.5.x and below are end-of-life and do not receive security coverage.
- Drew Webber (mcdruid) of the Drupal Security Team
- Alex Pott (alexpott) of the Drupal Security Team
- catch (catch) of the Drupal Security Team
- Lee Rowlands (larowlan) of the Drupal Security Team
- Drew Webber (mcdruid) of the Drupal Security Team
- Stephen Mustgrave (smustgrave), provisional member of the Drupal Security Team
- Jess (xjm) of the Drupal Security Team
- Jess (xjm) of the Drupal Security Team
18 Nov 2026 5:50pm GMT
Security advisories: Drupal core - Critical - Remote code execution - SA-CORE-2026-017
drupalDrupal core ships with an install.php file for installing Drupal core.
Under specific conditions, an attacker can use the installer to attempt to reinstall Drupal. This can lead to a site takeover or remote code execution.
Some exploit paths are mitigated if the web server cannot write to or change permissions on settings.php. In addition to upgrading, the Drupal Security Team recommends securing the Drupal installer after installation.
Discovered by Anthropic's OSS Scanner, as vulnerability ANT-2026-GMRPK0BU.
Drupal Steward protection:
This issue is being protected by Drupal Steward. Sites that use Drupal Steward are already protected from some known attack vectors, but the protection offered will not cover all possible exploits. Sites should upgrade in the near future in case additional attack vectors are discovered.
Install the latest version:
Drupal 11
- If you use Drupal 11.4.x, update to Drupal 11.4.13.
- If you use Drupal 11.3.x, update to Drupal 11.3.22.
- Drupal 11.2.x and below are end-of-life and do not receive security coverage.
Drupal 10
- If you use Drupal 10.6.x, update to Drupal 10.6.22.
- Drupal 10.5.x and below are end-of-life and do not receive security coverage.
Drupal 8 and Drupal 9 have both reached end-of-life.
If you cannot upgrade immediately:
Follow the instructions for securing the Drupal installer to protect your site from attacks.
- Alex Pott (alexpott) of the Drupal Security Team
- Benji Fisher (benjifisher) of the Drupal Security Team
- catch (catch) of the Drupal Security Team
- cilefen (cilefen) of the Drupal Security Team
- David Strauss (david strauss) of the Drupal Security Team
- Lee Rowlands (larowlan) of the Drupal Security Team
- Dave Long (longwave) of the Drupal Security Team
- Drew Webber (mcdruid) of the Drupal Security Team
- Mingsong (mingsong), provisional member of the Drupal Security Team
- Vijay Mani (vijaycs85), provisional member of the Drupal Security Team
- Jess (xjm) of the Drupal Security Team
- Alex Pott (alexpott) of the Drupal Security Team
- Benji Fisher (benjifisher) of the Drupal Security Team
- catch (catch) of the Drupal Security Team
- cilefen (cilefen) of the Drupal Security Team
- David Strauss (david strauss) of the Drupal Security Team
- Greg Knaddison (greggles) of the Drupal Security Team
- Lee Rowlands (larowlan) of the Drupal Security Team
- Dave Long (longwave) of the Drupal Security Team
- Drew Webber (mcdruid) of the Drupal Security Team
- Juraj Nemec (poker10) of the Drupal Security Team
- Pierre Rudloff (prudloff) of the Drupal Security Team
- Angie Byron (webchick) of the Drupal Security Team
- Jess (xjm) of the Drupal Security Team
18 Nov 2026 5:43pm GMT
Acquia.com - Drupal Blog: The Work We Want: AI, Code Directors, and Collective Power
Ethan Marcotte's NEDCamp keynote explores AI, power, and explores how human judgment and collective action shape our tech.
18 Nov 2026 4:11pm GMT
Droptica: Drupal CRM integration for pre-qualified inquiries
 An informed buyer shouldn't have to repeat their research to sales. Drupal CRM integration can connect forms and agent endpoints to your CRM without losing intent, consent evidence, or inquiries during an outage.
18 Nov 2026 4:08pm GMT
The Drop Times: DrupalCamp Spain 2026 Speakers Examine AI Reliability and Human Agency
In Part 2 of the DrupalCamp Spain 2026 speaker series, eight contributors examine where AI-assisted development needs audits, architecture, critical thinking and human decisions.
18 Nov 2026 2:12pm GMT
Gspikes: Association Website Design: Lessons From the 100 Largest US Associations
Association website design lessons from the 100 largest US associations: what their homepages show, where member login breaks, and when Drupal fits.
18 Nov 2026 7:00am GMT
Tag1 Insights: Inside the Pyramid: The Ideal Shape for Drupal’s Test Suite
The Ideal Shape
As we touched on in Speed Up Your Testing with Deuteros, the Drupal test suite is not in an ideal shape. If we consider the distribution of tests among the various Drupal test types (UnitTestCase, KernelTestBase, BrowserTestBase, WebDriverTestBase, and BuildTestBase), we quickly realize that, instead of resembling the Test Pyramid, which relies on a wide majority of lightning-fast Unit tests, we are currently stuck with what I call the Test Spinning Birthday Cake:
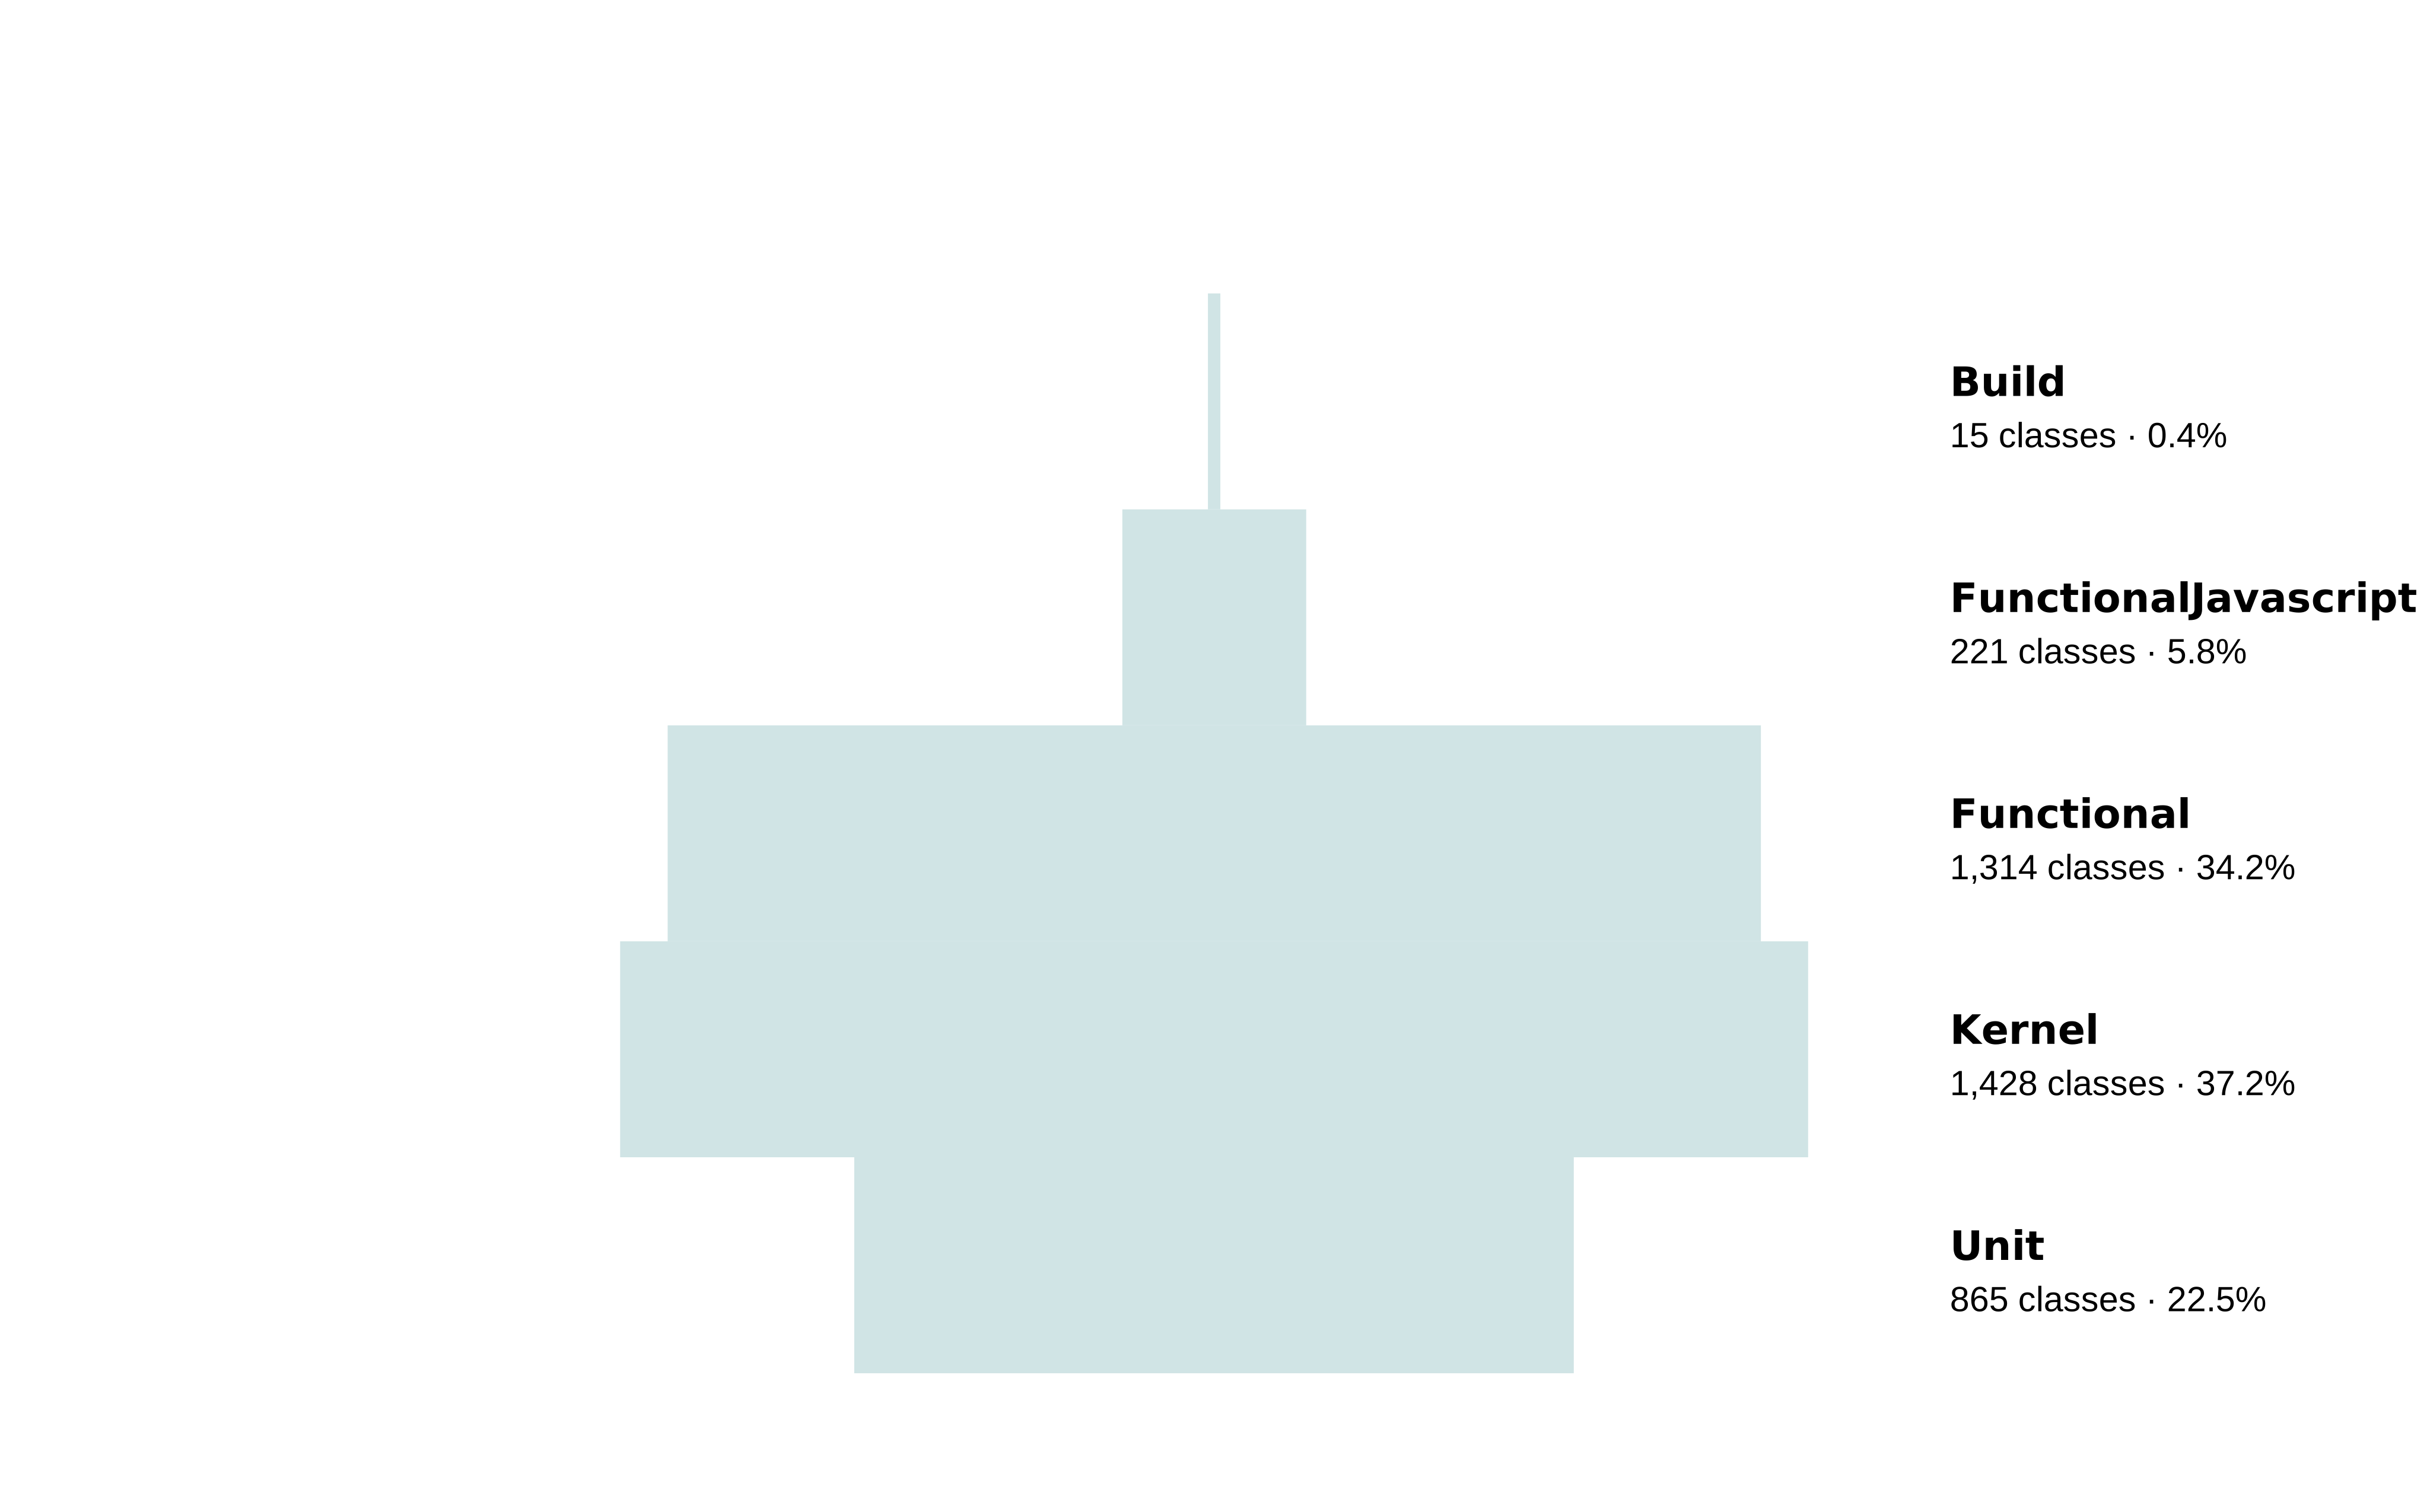
Source: *Test.php files in core/tests and in core modules, profiles, themes and recipes; abstract classes left out. Nightwatch not included.
Running our test suite ended up being either slow or very expensive: as a matter of fact, a significant slice of the Drupal Association's budget currently goes into running CI tests on drupal.org.
How Fast?
For anyone wondering how much faster
UnitTestCasetests are, here is how long it took 1,000 iterations of the same test code to complete, according to the Deuteros benchmarks:
UnitTestCase+ PHPUnit mocks: <1sUnitTestCase+ Prophecy API mocks: <0.5sKernelTestBase+ Entity objects: ~12 minutes
Redundant Redundancy
The main reason for this inefficiency is redundancy: many functional or kernel tests end up covering overlapping functionality, so we test the same code paths over and over.
To make matters worse, we are also dealing with inconsistent granularity: next to a functional test covering an entire form, you can find another functional test only checking that one option of a selector in that form behaves correctly: test coverage for a single bug fix next to that of an entire feature.
This is what I would call explicit redundancy.
However, we also have implicit redundancy, which may come in a few flavors:
- Testing at the wrong level, meaning much higher than the code we actually care about. Say we exercise our code path through a functional test, very far from the class we want to test: that implicitly tests every step between Drupal's bootstrap and our code, that is, the entire stack.
- Enabling modules just to autoload classes. All Drupal tests use a bootstrap script that autoloads the classes of every module, so you can just use them in your test. Enabling a module just to autoload its code exercises the whole module installation pipeline, every time the test runs, for no reason, because that is not what your test is about.
- Needlessly relying on persistence. It is not uncommon to find tests where an entity is saved even though it is only being manipulated as a data object used to pass information around. That alone is a reason people pick kernel tests and, if you do not need persistence, there are much more performant options.
As a consequence, readability suffers as well, since the test's assertions and expectations are often lost among several lines of setup code or other preliminary steps, as those kinds of tests usually require a more complex test environment.
The bottom line is that, speed and costs aside, DX and maintainability are not exactly ideal either.
How Did We Get Here?
Back when we added automated testing, we introduced a test gate mandating test coverage for any change landing in core. No matter whether you were dealing with a brand-new feature or a tiny bug fix, everything had to get test coverage. However, the guidelines stopped there: there was no clear direction about which kind of test to write each time. So people would either pick the route they were most familiar with or piggyback on an existing test.
That is not bad in itself, but it depends on which tests are available. By now we have a lot of tests inherited from the Drupal 7 days, hence an abundance of functional tests, which are among the slowest to run. And many new tests are functional tests as well, for similar reasons.
Right now, even our AI best practices will not encourage you to write Unit tests. Their claim:
"Unit tests, at least in Drupal, are the least useful kind of tests."
Harsh, but that is our current reality, and it is going to be reinforced one AI-generated test at a time.
As far as I can tell, one of the main reasons Unit tests are seen as the least useful is that most Drupal code manipulates entities, and entities are very hard to Unit-test because they bring a lot of baggage. The moment you try to instantiate one in a UnitTestCase test, you find yourself setting up test doubles for half of the Entity system.
The Silver Bullet
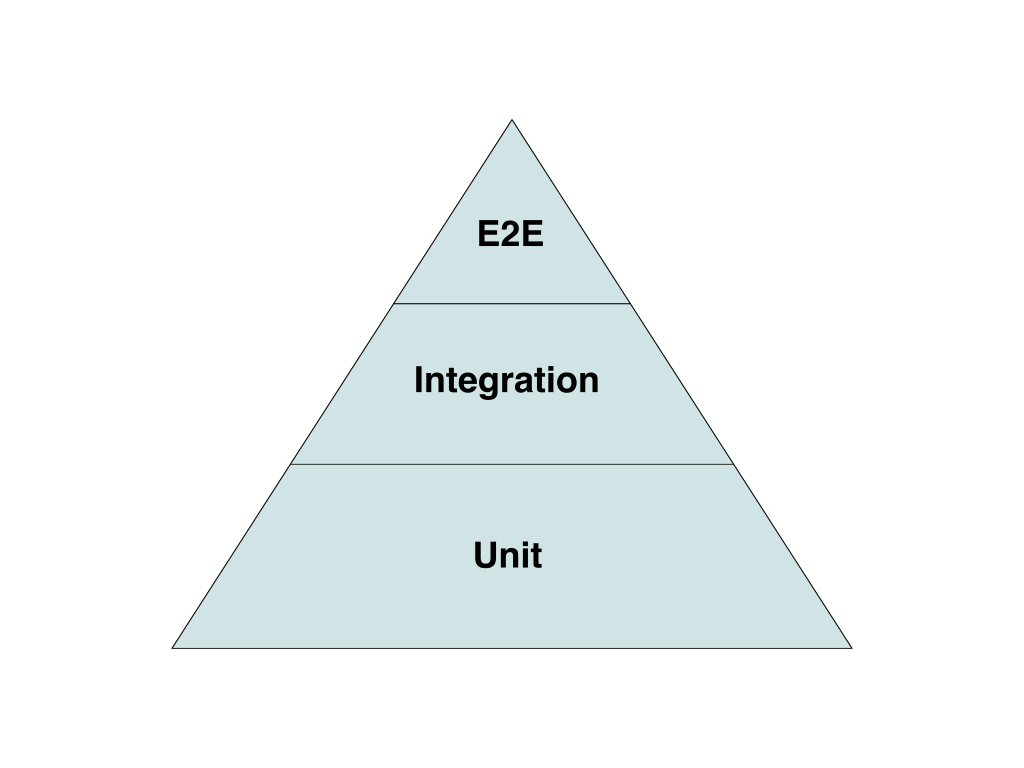
I believe the Test Pyramid can help us address the Drupal test suite's performance issues, by letting us implement most of the coverage via Unit tests, and only rely on kernel and functional tests for very narrow and specific use cases: for instance, to ensure subsystems are correctly wired and that critical scenarios are working properly.
Aside from Speed, if we adopt the Test Pyramid we get more:
- Breadth. If your class method has an if branch, you have two cases to test. Two class methods with an
ifeach, four cases, and so on. Test your classes individually and you are testing two cases at a time. Let them combine and the number of code paths explodes: by the time you get to the top, it is impossible to exercise them all. That is where we are now: there is no way to have exhaustive coverage through the current approach, while the Pyramid would give us much finer-grained coverage at the bottom. - Explicitness. Ever tried debugging a functional test? Most of the time you get an error that doesn't tell you which line to look at. You navigate the codebase, exercise your intuition, maybe spin up a debugger and step through the test at hand, and after a while you may track the issue down to a class. If you were Unit-testing that class, its test would fail and you would know instantly where to look.
Push test coverage down whenever you can and you get all of these advantages, thus improving DX as well. Combine that with clear guidelines on how to shape your module's test suite and Maintainability improves significantly.
To make a long story short, in my opinion this is the shape we should aspire to, the Test Squeezed Skyscraper:
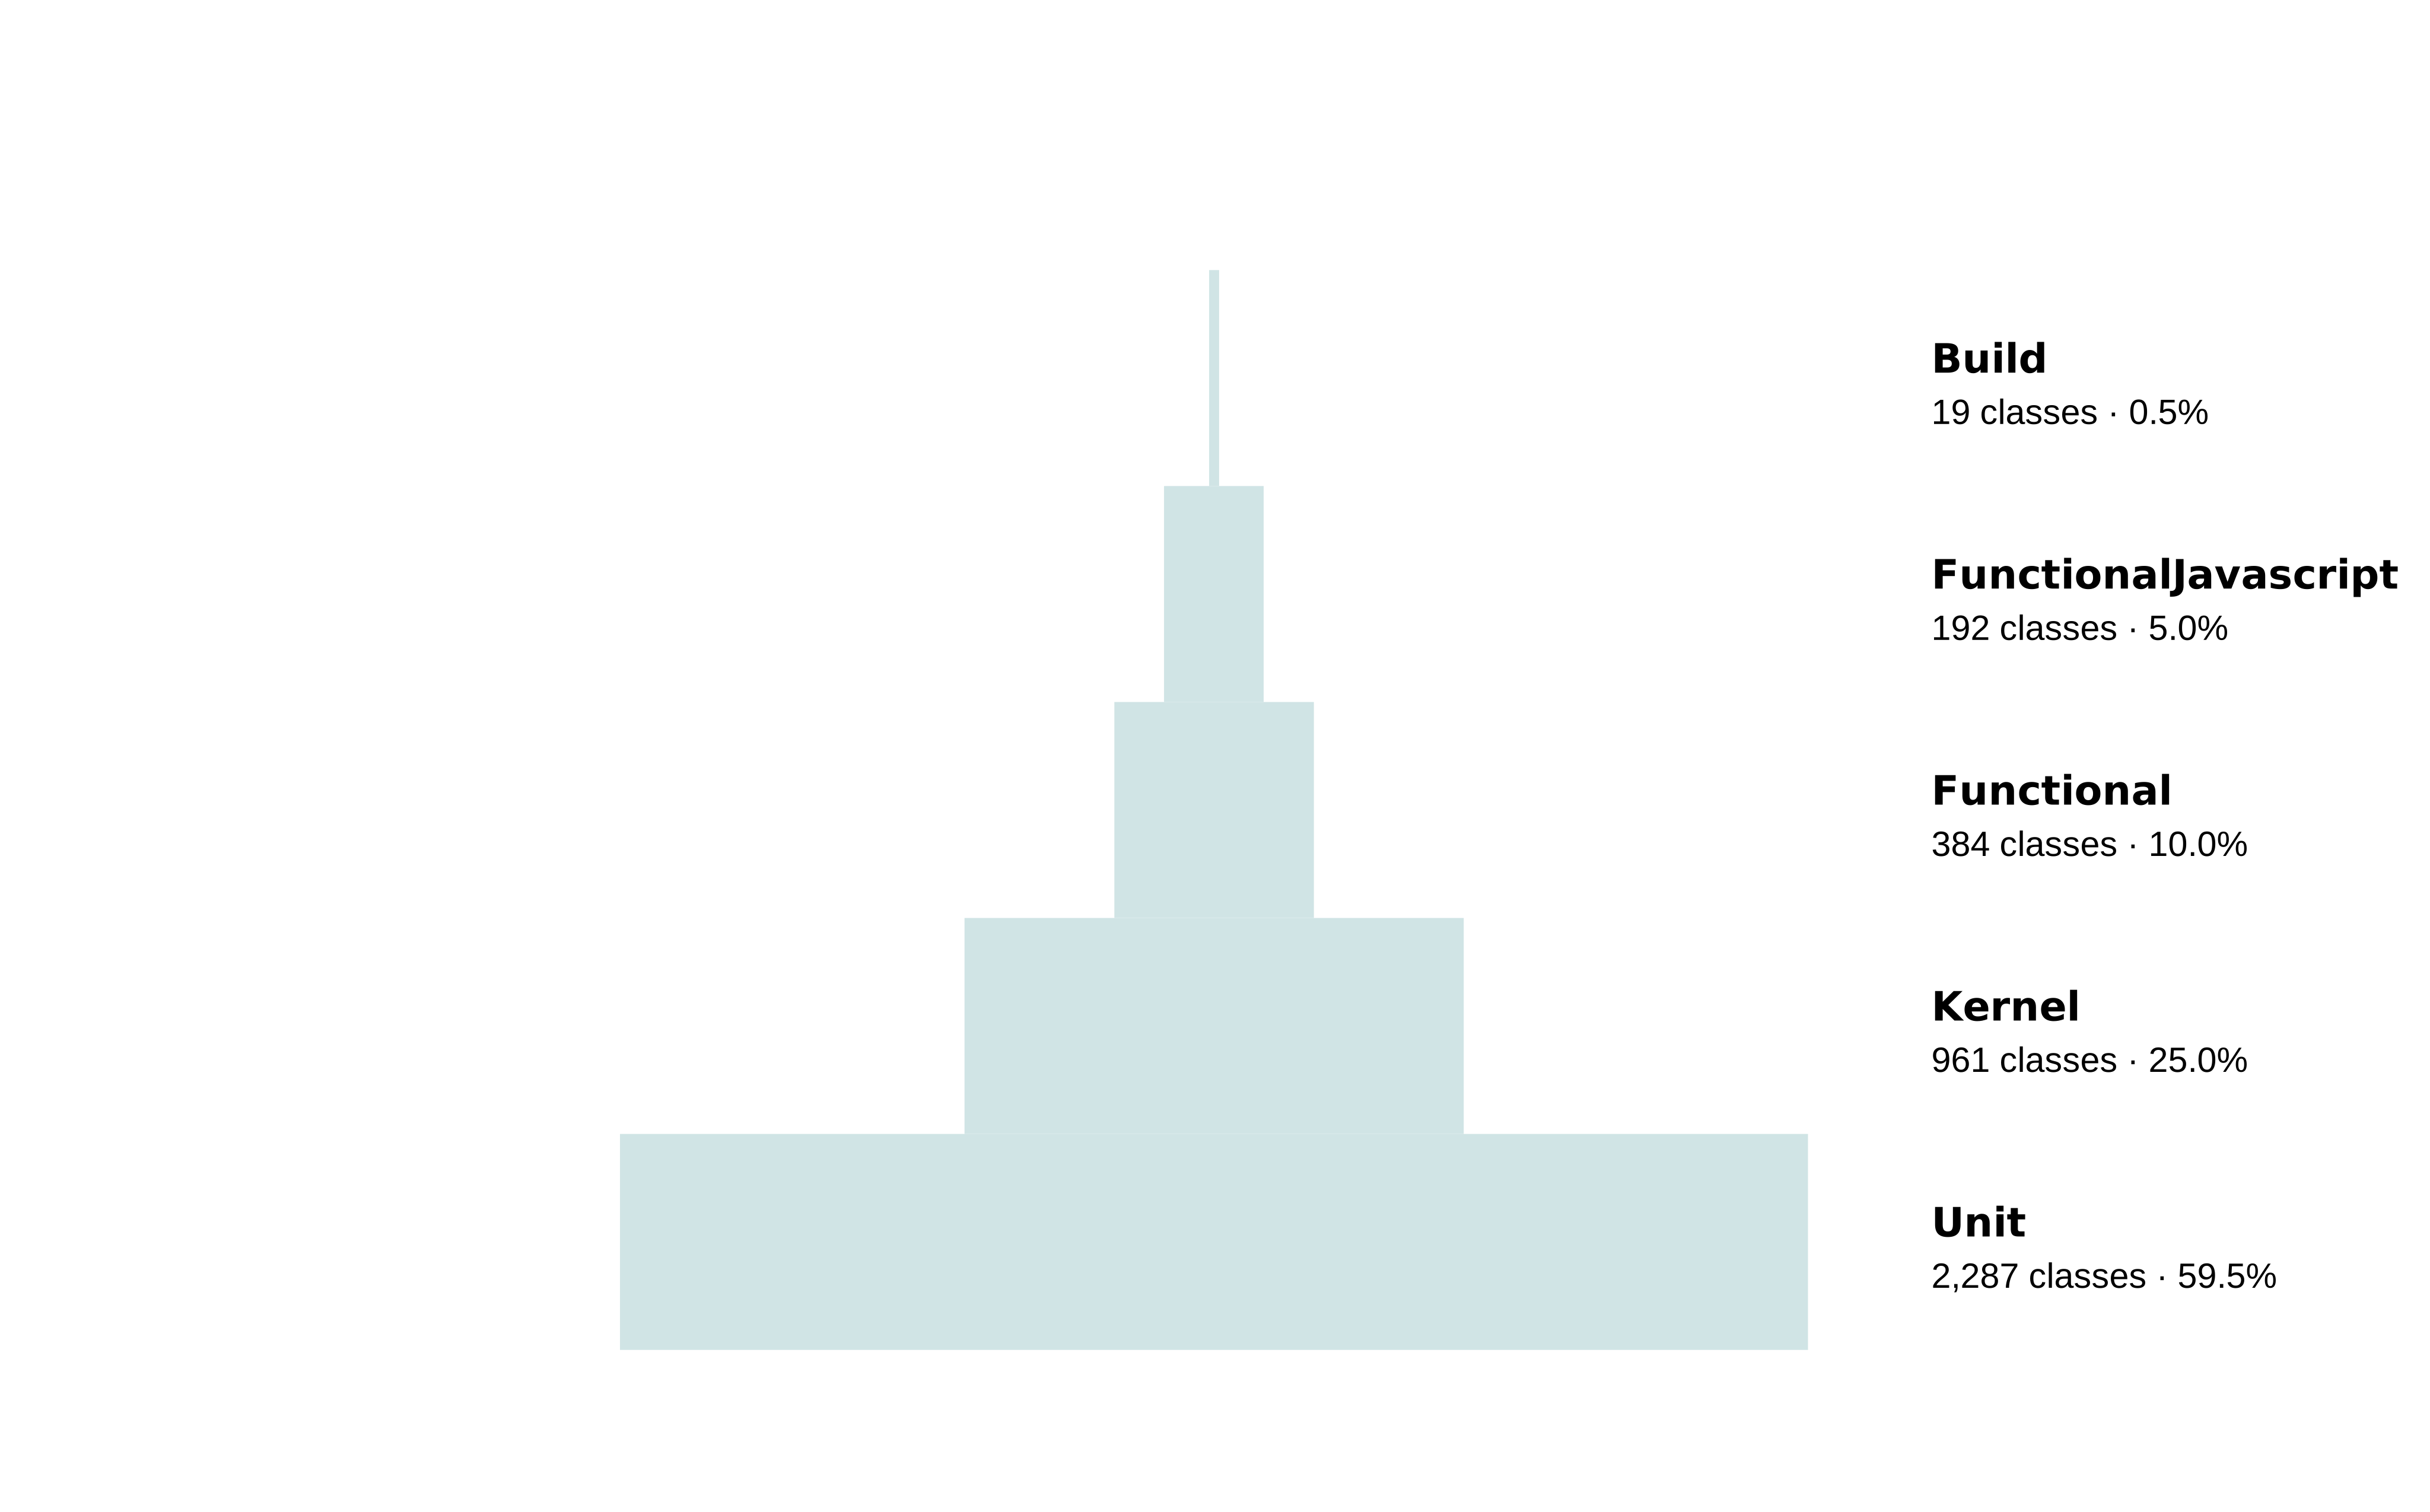
We should aim for something with a very wide base and much thinner upper layers. How much we can actually squeeze remains to be seen, but that is the ideal goal.
The Trap
Did you notice any resemblance between the Pyramid and the Squeezed Skyscraper? They look very similar, but this similarity hides a trap: in practice there is no direct mapping between the layers of our Skyscraper, that is, Drupal's test types, and the levels of the Pyramid. Sure, they are correlated, but there is no hard rule enforcing a mapping between them. In fact, you can:
- Unit-test an individual form builder class in
UnitTestCase, even if it is about the UI. - Write a database Integration test based on
UnitTestCase, not a kernel test. - Test a full request/response cycle End-To-End through a kernel test, not a functional test. This is a recent, very exciting addition.
- Unit-test an object through a functional test - joking, that would take us back to Drupal 7.
To sum up, test levels are not the same as test types. Test types are tools at our disposal for providing coverage. Test levels define the scope of a test:
- End-To-End tests exercise your codebase through its entire scope, which for Drupal means a request/response cycle. They should be the bare minimum needed to cover critical scenarios, like the login flow.
- Integration tests exercise subsystems together, often crossing the process boundary: think of database queries, file system access, API requests. You want as many of these tests as needed to ensure your code is wired together properly.
- Unit tests cover individual behaviors of your codebase, typically targeting a single class. If your code is object-oriented and organized properly, you can do a lot with Unit tests alone.
These days the default assumption is that when implementing an Integration test, we need a kernel test, and when testing something at the UI level, we need a functional test. In a way, I have been suggesting this myself. This doesn't have to be the case.
I think the goal should be to widen the Skyscraper's base: push down towards it as many tests as we can. If we can do an Integration test using UnitTestCase, great. That doesn't mean breaking the rules and using a Unit test where an Integration test is called for. It means we can get a fast test while still getting the coverage we were aiming for.
Up Next
In the next post, I'll cover how to get there and the principles behind the guidelines I'm proposing.
Want a faster, leaner test suite for your Drupal project? Talk to our team.
18 Nov 2026 12:00am GMT
DDEV Blog: Is DDEV Affected by nginx2root?
Several of you have asked whether DDEV is affected by nginx2root, published today by Xint. The research chains five nginx memory-corruption bugs (CVE-2026-123007, CVE-2026-123634, CVE-2026-123633, CVE-2026-121810, and CVE-2026-113425) with an unpatched Linux kernel SCTP flaw. Each nginx bug gives an unauthenticated remote client code execution as the nginx worker, and the kernel bug then takes that worker to root on the host, including out of a Docker container.
The short answer is that normal DDEV use isn't at risk.
Why DDEV isn't exposed
DDEV is normally used for local development, so it isn't reachable by an attacker of this type. If you use DDEV for internet-facing hosting, pay a little more attention, but the reasons below still apply.
The vulnerable nginx features aren't turned on by default. The five CVEs need HTTP/2 on a listener, HTTP/3/QUIC listeners, mirror combined with a resolver and a request-derived proxy_pass, or the mail proxy with auth_http. DDEV's nginx configurations use listen 443 ssl without http2, and use none of the others.
Traefik is in front of nginx. Your browser talks to ddev-router, which handles any HTTP/2 or HTTP/3 and forwards plain HTTP/1.1 to nginx in the web container. The web container's own ports are bound only to 127.0.0.1 unless you've turned on bind_all_interfaces.
The second stage is a kernel bug, and an attacker can only try it after getting code running inside the web container. In DDEV that container already runs your project's own code. On Linux hosts that don't need SCTP, you can block the module:
echo "install sctp /bin/false" | sudo tee /etc/modprobe.d/disable-sctp.conf
This doesn't unload a module that's already loaded. Reboot, or check lsmod | grep sctp, to be sure.
Who should check their setup
The only setup that might be at risk is one with a custom nginx configuration in .ddev/nginx_full/ or .ddev/nginx/ that adds http2, quic, or mirror, and that also exposes the web container directly to an untrusted network. To check a project:
grep -rnE "http2|quic|http3|mirror|resolver" .ddev/nginx_full .ddev/nginx 2>/dev/null
If that finds http2 on, a listen ... http2 or quic listener, or a mirror directive, remove it and ddev restart.
What we're doing
The current ddev-webserver image ships Debian Trixie's nginx 1.26.3-3+deb13u10:
$ ddev exec nginx -v
nginx version: nginx/1.26.3
As of today the Debian security tracker lists that version as vulnerable, with no fixed package yet. Upstream fixed the bugs in nginx 1.31.9 and 1.30.7. The next DDEV release will include a patched nginx in ddev-webserver, as long as Debian has released one by then.
If you want nginx as soon as Debian updates it
You don't have to wait for a DDEV release. Add nginx to webimage_extra_packages in .ddev/config.yaml:
webimage_extra_packages: [nginx]
When DDEV builds the web image, it runs apt-get update and then apt-get install nginx, which upgrades the installed nginx to the newest version in Debian's trixie-security repository. It only takes effect when the image is rebuilt after Debian publishes the update, so once the fixed package is out, rebuild:
ddev utility rebuild
A plain ddev restart isn't enough, because the build step hasn't changed and Docker reuses its cached result. Rebuilding before Debian publishes the fix just reinstalls the current version; today the build reports:
nginx is already the newest version (1.26.3-3+deb13u10).
Check which version you have with ddev exec dpkg -l nginx. If apt-get update fails during the build, for example because the network is down, the build still succeeds and keeps the old nginx, so check the version after rebuilding. Once a DDEV release ships the patched nginx, you can remove the line.
Resources
If you have questions, ask in Discord or open an issue.
18 Nov 2026 12:00am GMT
DDEV Blog: Contributor Training: Advanced coder.ddev.com Usage
coder.ddev.com gives you a DDEV environment in the cloud, with nothing installed on your own machine. Since the announcement it has grown a Drupal issue picker, a freeform template for any DDEV project, and several ways to run Claude Code inside a workspace.
Here's our November 11, 2026 Contributor Training on advanced coder.ddev.com usage:
The slides are available at rfay.github.io/advanced-coder-presentation, with source at github.com/rfay/advanced-coder-presentation.
What coder.ddev.com Is
coder.ddev.com is a free, experimental service built on the open source Coder project. Each workspace is an isolated Docker-in-Docker container (using Sysbox) with DDEV, Docker, Git, VS Code, and Claude Code already installed. The tools run on the server and use the workspace's files and configuration.
It is experimental. There are no guarantees about uptime or data retention, and a workspace that sits idle for 14 days is deleted, so keep your work in Git.
Getting Access
Sign in with GitHub at coder.ddev.com/login. Members of any organization that sponsors DDEV at $100/month or more can sign in directly. Everyone else can open an issue in coder-ddev-com/access-requests with their GitHub username and how they plan to use it. Coder gets read-only access to your email, public profile, and organization membership, not to your code.
The code is all at github.com/ddev/coder-ddev and the docs are at docs.coder.ddev.com, including instructions for hosting it on your own infrastructure.
Three Templates
drupal-core: a clean Drupal core checkout for working on core issues, using amateescu/ddev-drupal-dev.drupal-contrib: any contrib module or theme, using ddev/ddev-drupal-contrib.freeform: your own DDEV projects (or other types of projects), one or many per workspace.
Drupal Contribution With the Issue Picker
The Drupal issue picker is the replacement for the old Gitpod-based DrupalPod. Paste a drupal.org issue URL, issue number, or project name. The picker works out whether it's core or contrib and which Drupal version it needs, checks out the issue fork branch, installs Composer dependencies, and installs the site. Hand someone an issue URL at a contribution day and they get a working site with the branch ready, with no local Docker.
The first creation of a Drupal workspace takes several minutes. Watch the Logs tab, and don't click Cancel at "Confirm and Create"; if something goes wrong, start over in the picker.
Inside the workspace, core is in ~/drupal-core/ and contrib projects are in ~/<project_name>/. The site login is admin / admin, and the usual tools are there:
ddev drush uli
ddev phpunit core/modules/node
ddev phpcs   # also phpstan, eslint
git push issue HEAD
To push to the issue fork, add the workspace's public key (from coder publickey or your SSH keys page) to your drupal.org account.
Getting Into a Workspace
The dashboard gives you VS Code for the Web, a web terminal, and app buttons for the DDEV site, Mailpit, and XHGui. VS Code for the Web is a full VS Code in a browser tab, and its terminal has ddev, docker, git, and claude.
For daily work, I usually prefer local VS Code (VS Code on your machine, connected to the workspace over SSH). Use the "VS Code Desktop" button, coder open vscode my-site, or Remote-SSH to the host my-site.coder after running coder config-ssh. Xdebug works the same as with local DDEV. JetBrains IDEs connect through the Toolbox Coder plugin or Gateway over SSH.
The Coder CLI
brew install coder            # or: curl -L https://coder.com/install.sh | sh
coder login https://coder.ddev.com
coder list
coder create --template freeform my-site
coder stop my-site
coder start my-site
On Windows, use winget install Coder.Coder. See the Coder install docs for other options.
coder ssh gives you a shell, runs a single command, or forwards your SSH agent with -A:
coder ssh my-site
coder ssh my-site -- ddev list
coder ssh -A my-site
When you forward your SSH agent, processes in the workspace, including Claude Code, can ask it to sign with your local keys while it's connected. Leave agent forwarding off unless you need those keys in the workspace. See Git and SSH keys.
coder config-ssh writes entries in ~/.ssh/config so plain ssh, scp, and rsync work against <workspace>.coder. Run it again after creating a new workspace.
coder config-ssh --yes
ssh my-site.coder
rsync -av ./files/ my-site.coder:~/my-site/web/sites/default/files/
Importing a database is an scp followed by ddev import-db:
scp ~/Downloads/dump.sql.gz my-site.coder:~/my-site/
coder ssh my-site -- env -C /home/coder/my-site \
  ddev import-db --file=dump.sql.gz
And exporting is the reverse:
coder ssh my-site -- env -C /home/coder/my-site \
  ddev export-db --file=backup.sql.gz
scp my-site.coder:~/my-site/backup.sql.gz .
The Freeform Template
Freeform runs any DDEV project, as many as you want. When creating the workspace, set the "DDEV project names" parameter (for example shop,blog). Each name must match a DDEV project name exactly, and each gets its own app button, Mailpit, and XHGui. Then, for each project, run ddev coder-setup once, which routes the project through ddev-router so it gets its own hostname without port numbers.
A minimal site, in a workspace whose project names include hello:
mkdir -p ~/hello/public && cd ~/hello
echo '<h1>Hello from coder.ddev.com</h1>' > public/index.html
ddev config --project-name=hello --project-type=php --docroot=public
ddev coder-setup
ddev start
The site is at https://hello--<workspace>--<username>.coder.ddev.com; use the app button or ddev launch. *.ddev.site URLs don't work in the cloud.
Bringing your own project is the same pattern:
git clone https://github.com/your-org/my-site.git ~/my-site
cd ~/my-site
ddev config --project-name=my-site
ddev coder-setup
ddev start
Public sharing is off by default, so workspaces are private. If you turn it on, anyone with the link can reach the site. You can also use ddev share, which works through Cloudflare and shows a QR code for testing on a phone. Change parameters later in Settings → Parameters, then restart the workspace.
Timeouts and Lifecycle
Freeform workspaces auto-stop after 24 hours of inactivity. Check or extend that with coder schedule show my-site and coder schedule extend my-site 2h, or turn auto-stop off in the workspace settings; that may change if usage grows. After 7 idle days you get a warning email, and 7 days after that the workspace is deleted.
Stopping a workspace keeps /home/coder, databases, Docker volumes, and Homebrew packages. It loses running processes, /tmp, and anything installed with apt-get, so install tools with brew or npm -g. To start a DDEV project when the workspace starts, create ~/.coder-startup.sh with these contents:
#!/usr/bin/env bash
cd ~/my-site && ddev start
Run chmod +x ~/.coder-startup.sh so the workspace can run the script on each start.
Claude Code in a Workspace
There are four ways to use Claude Code on coder.ddev.com:
- Run
claudein a terminal. It's already installed. - Install the "Claude Code" extension by Anthropic in VS Code.
- Enable remote control in the workspace settings, and use the session from claude.ai/code or the Claude mobile app.
- On freeform only, run a self-hosted runner so claude.ai/code sessions execute in your workspace.
Log in once with claude; the login persists in your home directory. You need a Pro, Max, Team, or Enterprise plan or an ANTHROPIC_API_KEY, and remote control needs a subscription.
Claude runs in the workspace with the workspace's Docker and DDEV, and your laptop isn't involved. Start it inside tmux new -s claude so the session survives a closed browser tab, or use coder ssh my-site and then cd ~/my-site && claude. A CLAUDE.md that tells Claude to run PHP, Composer, and Drush through ddev saves some back-and-forth.
For remote control, enable it in the workspace settings and restart. The first time, use the "Claude Code" app button to log in and trust the workspace. The session then shows up at claude.ai/code under the workspace name, and claude-here in a project directory switches it to that project. It disconnects after about 10 minutes offline and restarts when the workspace starts or when you click the app button.
The self-hosted runner can't be combined with remote control, so dedicate a freeform workspace to it. Create a self-hosted environment on claude.ai and save its secret:
mkdir -p ~/.claude-runner
cat > ~/.claude-runner/environment-secret   # paste, Enter, Ctrl-D
chmod 600 ~/.claude-runner/environment-secret
The runner handles one to four concurrent sessions; claude-sessions lists them. It rewrites ~/.gitconfig before each session and logs to the claude-runner tmux session and /tmp/claude-runner-N.log.
Claude Code runs as the workspace user and can access that user's files and credentials. Keep permission prompts enabled if you want to review the commands it runs.
What FreelyGive Is Doing With It
The FreelyGive team (featured sponsors of DDEV) joined the session and showed how they use coder.ddev.com for AI agent work. They have agents that browse Drupal modules, look for vulnerabilities, and file security issues with reproduction videos; about 150 of those issues have been verified so far. They also have a one-line installer that sets up DDEV and runs scripts to migrate a site into Drupal CMS, often with a Storybook design system, and they've used a workspace to benchmark Drupal on a Rust port of PHP.
Open topics from the discussion:
- Whether a complex AI workflow should be its own Coder template or a script run in a freeform workspace.
- Adding an app button for a service like phpMyAdmin is easy in a template, but automatic URL mapping for every DDEV service isn't there yet.
- Coder could reduce configuration drift for teams doing the same task repeatedly, such as Drupal 6 to 11 upgrades.
Contributing to coder-ddev
If something about coder.ddev.com annoys you, github.com/ddev/coder-ddev is a good place to fix it. The docs and existing code give you patterns to follow, AI tools handle the codebase well, and each PR build posts links so you can check your changes.
Resources
- Start page: start.coder.ddev.com
- Dashboard: coder.ddev.com
- Docs: docs.coder.ddev.com
- Code and issues: github.com/ddev/coder-ddev
- Access requests: github.com/coder-ddev-com/access-requests
- Help: DDEV Discord and
#ddevin Drupal Slack
Join us for future trainings
- Sign up for the DDEV Newsletter to be informed about future trainings.
- Let us know your tips and tricks in Discord or here in the comments.
Claude Code was used to draft and review this blog.
18 Nov 2026 12:00am GMT
17 Nov 2026
Drupal.org aggregator
Aten Design Group: Comparing Search Options in Drupal
Comparing Search Options in Drupal
Search is one of the most important features of a content-heavy website. Whether visitors are looking for university programs, government services, library resources, or documentation, the ability to find relevant content quickly can make or break their experience.
Drupal offers several approaches to search, ranging from basic database-backed solutions to dedicated search engines, AI-powered search, and third-party platforms. Each comes with different capabilities, costs, and maintenance requirements.
Let's look at the primary options, their advantages and limitations, and where each makes the most sense.
Drupal's native search options
Drupal Core Search
Drupal historically included a Search module that indexed website content directly in its database. It provided basic keyword searching without requiring additional services.
Benefits: Simple to configure, no external infrastructure, and minimal setup.
Drawbacks: Limited control over relevance, filtering, and advanced search functionality. It is not particularly well suited to large or complex content collections.
While Drupal Core Search was deprecated in Drupal 11.5, and removed altogether from Drupal 12, the functionality continues as a contributed module.
Best for: Existing Drupal sites with straightforward search requirements. For new implementations, Search API is generally a better starting point.
Example: A municipal website search demonstrates a straightforward approach to helping residents find public information and services.
Search API with Database Search
Search API is Drupal's most widely used framework for building customized search experiences. It allows developers to define what content gets indexed, configure searchable fields, and integrate results with Drupal Views.
Importantly, Search API is not a search engine itself. It connects Drupal to different search backends.
Its bundled Database Search backend stores the search index in Drupal's existing database, eliminating the need for additional infrastructure.
Benefits: Flexible indexing, control over searchable fields, integration with Views, and support for features such as faceted filtering through additional modules. It can also index more than just Drupal nodes.
Drawbacks: Database-backed searching has limitations around relevance tuning, language processing, and performance at larger scales. Advanced capabilities depend on the backend being used.
Best for: Small to medium-sized Drupal websites that need more control than Core Search provides without the overhead of a dedicated search server.
Example: A content-focused search with page-type filtering demonstrates how a straightforward search interface can help visitors narrow results by content type without an overly complicated experience.
Dedicated search engines
Search API with Apache Solr
Apache Solr is a dedicated, open-source search engine commonly used with Drupal through the Search API Solr module.
Solr moves indexing and searching into a separate service, providing more advanced capabilities than traditional database searching.
For content-heavy Drupal implementations, Search API with Solr is often a strong starting point. It provides considerable flexibility without requiring a proprietary search platform.
Benefits: Strong relevance tuning, faceted navigation, multilingual searching, stemming, synonyms, and the ability to search large collections efficiently. Additional integrations can also support indexing PDFs and other documents.
Drawbacks: Requires a separate Solr service and additional configuration. Index management, search configuration, monitoring, and infrastructure all introduce ongoing maintenance considerations.
Fortunately, several Drupal hosting providers offer managed Solr services, reducing the operational burden.
Best for: Larger Drupal websites with substantial content libraries, complex filters, multilingual requirements, or sophisticated relevance needs.
Example: A large-scale website search with content-type filtering demonstrates how visitors can search across thousands of pages, events, articles, and other content types. Faceted filters help narrow results without requiring separate search interfaces for each content collection.
Elasticsearch and OpenSearch
Elasticsearch and OpenSearch are distributed search engines that offer many capabilities comparable to Solr.
Both can integrate with Drupal through Search API backend modules, though they are separate products with different APIs and licensing models.
Benefits: Powerful full-text search, filtering, scalable indexing, and sophisticated query capabilities. They can also be useful when search extends beyond Drupal into other applications or centralized data platforms.
Drawbacks: Like Solr, they require additional infrastructure and technical expertise. Drupal integration modules vary in maturity and compatibility, making their long-term support an important consideration.
Best for: Organizations already using Elasticsearch or OpenSearch, or projects that need a search platform shared across multiple applications.
For a standalone Drupal website, Solr's mature integration may make it the more straightforward choice. Elasticsearch and OpenSearch become particularly attractive when they align with an organization's existing infrastructure.
Example: A healthcare website search illustrates how search can support content discovery across treatments, physicians, research, and patient information.
AI-powered search in Drupal
Drupal AI Search
The contributed AI Search module brings semantic search capabilities to Drupal through Search API.
Traditional keyword search primarily looks for matching terms. Semantic search uses vector embeddings to identify content related to the meaning of a query, even when the wording differs.
For example, someone searching for "How do I get help paying for college?" might receive relevant financial aid information without needing to search for the exact phrase "financial aid."
AI Search generates embeddings from Drupal content and stores them in a compatible vector database, such as Pinecone, Qdrant, or Milvus. It also supports hybrid approaches that combine semantic search with traditional keyword results from backends such as Solr.
Benefits: Natural-language searching, improved discovery of conceptually related content, and integration with Drupal's existing Search API framework. It can also provide the retrieval foundation for AI assistants and question-answering experiences.
Drawbacks: Requires additional services for generating and storing embeddings, introduces processing and infrastructure costs, and requires careful evaluation of result quality. The contributed module is also relatively new, with its available releases still in alpha as of November 2026.
Best for: Websites where visitors frequently search using questions or imprecise terminology, or organizations exploring conversational search and AI-assisted content discovery.
One important distinction: semantic search does not automatically mean AI-generated answers. Drupal AI Search primarily retrieves relevant content. Producing conversational responses or summaries requires additional functionality, often using retrieval-augmented generation (RAG).
External and managed search services
Google Programmable Search Engine
Google Programmable Search Engine allows websites to embed a Google-powered search experience without maintaining their own search index.
Rather than indexing Drupal entities directly, it relies on Google's search infrastructure to discover and retrieve publicly accessible pages.
Benefits: Relatively simple implementation, minimal infrastructure requirements, and the ability to search across multiple websites.
Drawbacks: Less control over indexing, ranking, and result presentation than a dedicated search platform. Content freshness depends on Google's indexing, and advertising, branding, and customization options vary by offering.
Google also announced changes in 2026. Its site-specific Search Element continues to support up to 50 designated domains, while users of the Custom Search JSON API and certain broader web-search configurations must transition by January 1, 2027.
Best for: Websites with relatively simple public-content search requirements, particularly when searching across multiple domains is desirable and customization is not a priority.
Example: A higher education website using Google-powered search demonstrates how an institution can incorporate an external search engine into its website without maintaining a separate search index.
Cludo and other managed search platforms
Cludo is a commercial search platform designed specifically for website search. Unlike Drupal-specific search backends, it can crawl and index content across multiple websites regardless of the underlying CMS.
Cludo also provides tools for managing search relevance, promoting important results, and analyzing visitor search behavior.
Benefits: Managed infrastructure, cross-site search, search analytics, and administrative tools for adjusting relevance. It can index publicly accessible pages and documents, with APIs available for more specialized integrations.
Drawbacks: Subscription costs, reliance on an external vendor, and potentially less direct integration with Drupal's structured content and access controls. Crawl configuration and indexing frequency require attention.
Best for: Large organizations managing multiple websites or content platforms, particularly when a managed solution and built-in search analytics are priorities.
Example: A municipal website search powered by a managed search platform illustrates how an external search service can provide a dedicated search experience without relying on Drupal's native search infrastructure.
Cludo is not the only option in this category. Platforms such as SearchStax and Algolia also provide managed search capabilities, although their approaches to Drupal integration, indexing, and search administration differ.
How should you choose?
The right solution depends on more than content volume. Before selecting a search platform, consider a few practical questions:
- What needs to be searchable? Drupal content, PDFs, multiple websites, external databases, or some combination?
- How sophisticated should search be? Basic keyword matching may suffice, while extensive content collections may benefit from facets, autocomplete, synonyms, and customized ranking.
- Who will configure and maintain search? Some solutions rely heavily on developer configuration, while others provide interfaces for adjusting relevance and analyzing search behavior.
- What infrastructure and budget are available? Open-source software avoids licensing fees but still requires development and operational support.
- Are there access restrictions? Search must respect content permissions, particularly when indexing protected or unpublished information.
It's also worth considering how search will be evaluated after launch. Popular queries, searches returning no results, and the pages visitors actually select can reveal problems with content organization as well as search configuration.
A more powerful search engine cannot compensate for poorly structured, outdated, or duplicated content.
Final thoughts
For smaller Drupal websites, Search API with Database Search is often sufficient. As content volume and search requirements grow, Search API with Solr provides a mature and flexible approach.
Elasticsearch and OpenSearch are compelling alternatives when they align with existing technical infrastructure. Google Programmable Search remains an option for relatively simple public-site searching, while managed platforms such as Cludo can be especially useful for organizations managing content across multiple websites.
No single approach is right for every project.
The goal isn't to implement the most sophisticated search engine available. It's to select a solution that makes content easier to find, can be maintained over time, and gives the organization appropriate control over the search experience.
17 Nov 2026 6:37pm GMT
The Drop Times: Drupal AI Content Review Alpha Can Overwrite Entire Fields
An AI suggestion may change more of a Drupal page than an editor expects. Tests reveal when the original content remains recoverable.
17 Nov 2026 2:44pm GMT
Specbee: How to make your Drupal content readable by AI Crawlers and LLMs with Markdown Mirror
Serve AI crawlers a clean Markdown version of your Drupal pages. See how the Markdown Mirror module works and how to set it up in 5 steps.
17 Nov 2026 12:13pm GMT
The Drop Times: Why Some Drupal 11 Module Fixes Have Yet to Reach Official Releases
A patch marked ready for review may still leave a Drupal 11 upgrade blocked. Issue histories show why packaged releases, runtime behaviour and maintainer decisions need separate checks.
17 Nov 2026 11:32am GMT
Drupal Association blog: In the Open: Telling Drupal’s story together
In the Open is a weekly series from Drupal Association Interim CEO Tiffany Farriss, sharing what she is hearing across the Drupal community and where the Association is headed. In this episode: why closing the gap between what Drupal can do and what the market knows is urgent, how the new Drupal advocacy program recognizes advocacy with contribution credit, and how it connects to the new Drupal Certified program.
"Advocacy has always happened in our community, but it's really been very scattered and unrecognized."
The following is a transcript of Tiffany's remarks, lightly edited for readability.
Closing the perception gap
Drupal is light years ahead of its reputation. Our software has improved much faster than our story, which leaves a real gap between what modern Drupal can actually do, especially around AI and Drupal CMS, and what the broader market realizes.
I'm Tiffany Farriss, the Interim CEO of the Drupal Association, and this is In the Open, my regular update on what's happening at the Association as we navigate a year of change.
Closing the perception gap is urgent. People increasingly learn about technology from AI assistants, and those assistants learn from the open web. When governments, universities, and enterprises run serious platforms on Drupal quietly without publishing about it, the public record falls behind. Every genuine story about Drupal on LinkedIn, on Reddit, YouTube, or any sort of tech blog improves what both people and AI systems know about our project.
You can't buy that kind of credibility. It comes from real people sharing results that are verifiable and accessible to anyone.
The Drupal advocacy program
That's why we launched the Drupal advocacy program. Advocacy has always happened in our community, but it's really been very scattered and unrecognized. Now, helping people understand what Drupal can do earns contribution credit through the exact same system that recognizes code and other community contributions.
Adoption and education are crucial parts of sustaining open source. A digital public good creates the most value when people actually know what it can do and use it.
Four rules for advocacy
To keep our credit meaningful, we set four clear rules.
First, translation, not amplification. Sharing someone else's post is fine, but the highest value work comes from your own perspective, your industry, your language, speaking to your clients, what you actually know.
Two, crowd surf, not AstroTurf. It's not about repeating someone else's words, it's about what you've done, your experience. And your organization's work is excellent evidence, as long as you're telling Drupal's story and not just pitching your own services. That's great, too. It's just not Drupal advocacy.
Three, proof over claims. Back it up. Whatever you say needs to be something that people can check, whether it's a live site or a working demo or a recorded talk or other data. Let's make it provable.
Four, quality and reach over volume. Ten super thoughtful pieces that reach 3,000 people outside of our community does way more for Drupal than 30 posts that reach the same 300 insiders.
What we saw in month one
We're already seeing what happens when people put this into practice. Thanks to Ryan Witcombe and the DA marketing team standing up this pilot, we reviewed 264 pieces of advocacy from nearly 150 contributors around the globe, in seven languages, in just one month alone.
We've awarded 2,400 contribution credits in that first month to people like John Money, Kai Gertz and Tojio ai Gertz, who took live AI demos onto stages at non-Drupal conferences. There's Ivan Zugec, who published over 100 videos helping newcomers learn about Drupal. And Mike Anello, doing what Mike Anello always does and has done for years. He uses his platform to spotlight and amplify the work of fellow community members.
You can see all 15 standout contributors from month one in the link below.
Advocacy and the new Drupal Certified program
Formalizing this advocacy also directly connects to how we're evolving the Drupal Certified Partner program into the new Drupal Certified program. Instead of a single weighted score, organization profiles will now show three distinct ways that organizations contribute: maker, patron, and advocate.
Drupal is a registered digital public good, and the code is free forever. But running and sustaining the project, for everything that we do beyond the code itself, takes sustained, ongoing operational resources. From the DA, it's roughly $10 per site every year. That doesn't count the roughly $30 or more in community time for ongoing roles like core release management, security coordination, and testing.
The new Drupal Certified program is a public trust registry that recognizes organizations that participate in our Drupal ecosystem in a sustainable way, shouldering their fair share of that ongoing operational load, either directly, or by sponsoring it through the DA, or directly to the community members who already do the work.
Publishing verified sector services and contributions as structured data makes certified organizations easier for AI answer engines and buyers alike to find and to cite. Longer term, it will give procurement teams a simple public ledger to verify whether and how a vendor actually participates in the open source ecosystem for the software solutions they're trying to sell.
It's a message of strength. Drupal is a digital public good, and organizations should choose vendors who sustain it.
How to take part
To keep our momentum going, the Association has set quarterly themes, and on-theme work earns double credit. Our Rotterdam theme is now wrapped up, and the next theme is around our Drupal 12 launch in December, though good Drupal advocacy qualifies year-round. Anything you publish about Drupal in 2026 still counts.
You can submit your work in about a minute at drupal.org/advocacy, or through the workflow in our Promote Drupal channel on Drupal Slack. We award credits monthly, alongside a roundup of the month's best work. So contributors get seen, not just scored, and we're going to be celebrating standout work that's been created as a part of this pilot at DrupalCon Orlando in 2027.
Stewarded open source takes more than just code. It takes infrastructure, it takes security, it takes release management, events, and advocacy, all working together to make sure that the right information is available at the right time to those who are looking for it.
No single organization can educate the market alone. When the Association does the shared groundwork once and recognizes the people who step up, we amplify those individual stories into a network effect. More people see what Drupal can do, more organizations choose it, and more contributors join in to keep our commons strong.
So thank you for helping the world see what Drupal can do, and I'll see you next week, in the open.
Follow the conversation
New episodes of In the Open publish each week. Subscribe on the Drupal Association YouTube channel to follow along.
With thanks to Stephen Cross of Second Signal Media for producing this series.
17 Nov 2026 9:26am GMT