19 Nov 2026
 Fedora People
Fedora Infrastructure Status: Updates and reboots on Fedora infrastructure
19 Nov 2026 10:00pm GMT
Frank Ch. Eigler: visiting starbase
19 Nov 2026 7:49pm GMT
Remi Collet: 🛡️ PHP version 8.2.36, 8.3.37, 8.4.28 and 8.5.13

RPMs of PHP version 8.5.13 are available in the remi-modular repository for Fedora ≥ 43 and Enterprise Linux ≥ 8 (RHEL, Alma, CentOS, Rocky...).
RPMs of PHP version 8.4.28 are available in the remi-modular repository for Fedora ≥ 43 and Enterprise Linux ≥ 8 (RHEL, Alma, CentOS, Rocky...).
RPMs of PHP version 8.3.37 are available in the remi-modular repository for Fedora ≥ 43 and Enterprise Linux ≥ 8 (RHEL, Alma, CentOS, Rocky...).
RPMs of PHP version 8.2.36 are available in the remi-modular repository for Fedora ≥ 43 and Enterprise Linux ≥ 8 (RHEL, Alma, CentOS, Rocky...).
ℹ️ These versions are also available as Software Collections in the remi-safe repository.
ℹ️ The packages are available for x86_64 and aarch64.
⚠️ PHP version 8.1 has reached its end of life and is no longer maintained by the PHP project.
🛡️ These Versions fix some critical security bugs, so the update is strongly recommended.
Version announcements:
- PHP 8.5.13 Release Annoucement
- PHP 8.4.28 Release Annoucement
- PHP 8.3.37 Release Annoucement
- PHP 8.2.36 Release Annoucement
ℹ️ Installation: Use the Configuration Wizard and choose your version and installation mode.
Replacement of default PHP by version 8.5 installation (simplest):
On Enterprise Linux (dnf 4)
dnf module switch-to php:remi-8.5/common
On Fedora (dnf 5)
dnf module reset php
dnf module enable php:remi-8.5
dnf update
Parallel installation of version 8.5 as Software Collection
yum install php85
Replacement of default PHP by version 8.4 installation (simplest):
On Enterprise Linux (dnf 4)
dnf module switch-to php:remi-8.4/common
On Fedora (dnf 5)
dnf module reset php
dnf module enable php:remi-8.4
dnf update
Parallel installation of version 8.4 as Software Collection
yum install php84
And soon in the official updates (thanks to Jitka Plesnik for the updates):
⚠️ To be noticed :
- EL-10 RPMs are built using RHEL-10.2
- EL-9 RPMs are built using RHEL-9.8
- EL-8 RPMs are built using RHEL-8.10
- intl extension now uses libicu78 (version 78.3)
- mbstring extension (EL builds) now uses oniguruma5php (version 6.9.10, instead of the outdated system library)
- oci8 extension now uses the RPM of Oracle Instant Client version 23.26 on x86_64 and aarch64
- A lot of extensions are also available; see the PHP extensions RPM status (from PECL and other sources) page
ℹ️ Information:
- Migrating from PHP 8.2.x to PHP 8.3.x
- Migrating from PHP 8.3.x to PHP 8.4.x
- Migrating from PHP 8.4.x to PHP 8.5.x
Base packages (php)
Software Collections (php83 / php84 / php85)
19 Nov 2026 2:50pm GMT
18 Nov 2026
Fedora People
Adam Price: On Text Editor Related Tools and Their Effects
18 Nov 2026 12:00pm GMT
Fedora Magazine: Hacking Wordle: A New User's Guide to the Power of the Linux Terminal
For new Linux users the terminal can be like the Sphinx, quiet, mysterious, and offering no help to those who do not already speak its language. Here we'll show you how to get comfortable with the terminal by using some common commands to analyze a text file of words used by the popular online game, Wordle.
This analysis has real tasks to work on, giving you hands-on experience with the Linux command line. You'll be able to apply this experience to also work with logs, configuration files, and search for text inside files. These are fundamental skills an experienced user needs. Plus, you'll have some fun with Wordle.
I've Been Living Under A Rock. What's Wordle?
Wordle is an oddly addictive word game hosted by the New York Times. The goal of Wordle is to guess a five-letter word in no more than six guesses. The rules are simple. Guess a five-letter word. Wordle will mark letters that are not used, letters used but in the incorrect location, and letters in the correct location with different colors. Guess another word using the previous word's clues. Keep guessing until you've guessed the word or run out of guesses.
Wordle uses a curated list of words, so not every possible five-letter word can be a Wordle word. Offensive words, words with special characters or spaces, words using non-American spellings, and names (words that should be capitalized) are not used. Only certain plural and past tense words are accepted. Take a look at the full Wordle rules. These word rules narrow down possible Wordle words from some 20,000 dictionary five-letter words to about 2,500 words in the curated list.
Can the tools shown here be used to cheat at Wordle? If you play against others, the answer is yes. Being smart and clever about games is fun. Cheating is not fun....for anyone. Use this power for good only.
The Sphinx Speaks - First Look at the Terminal
If you're new to the terminal, let's take a quick tour. The application that let's you access the terminal from your desktop is a terminal emulator. On Fedora Workstation it is called Terminal. Fedora KDE uses a terminal emulator called Konsole. Open your terminal emulator application, and let's take a look around.
At the top left of the terminal window you see the prompt. The blinking cursor shows you where to type commands. The terminal uses software called a shell to communicate with the operating system. The terminal can use different shells, but we're going to use the default shell used by almost all Linux distributions, bash. You are probably already using bash, but let's confirm. To check your shell, type this command and hit Enter:
user@host:~$ echo $SHELL
/bin/bash
If the response is /bin/bash, you're set. If you get other responses (e.g., /bin/csh, /bin/ksh/, /bin/zsh), you're using a different shell. You may have problems with some of the tools we'll use. You can still follow along and run most of the commands, but you may encounter some issues.
The echo command just tells the terminal to "echo back" the item ($SHELL) to you. The item in question is a variable the system uses to hold the location to the preferred shell of the logged-in user.
Assuming you are using bash on Fedora, your prompt should look something like this:
user@host:~$
On some other Linux distributions, you may see a prompt that looks like this:
[user@host ~]$
Either way, the prompt gives us four pieces of important information:
- The username of the current user in to the terminal. In the example this is "user".
- The hostname of the system. In the example the hostname is "host".
- The current working directory is user's home directory (~). You will see the tilde (~) used frequently in the terminal. It represents the /home/user/ directory. Remember, there's no place like ~.
- The $ at the end tells us we currently have non-root permissions. We're not going to make any system-wide changes, so this is perfect for us. It also indicates the shell is ready for more input.
Put the Terminal to Work - Create a Workspace
Let's make a directory we can store our data in. We'll assume you have a standard desktop install with pre-made folders like Documents, Music, Pictures, Downloads, etc. We're going to put our work in the Documents folder. Inside the Documents folder, we're going to make a new folder called 'wordle'. We use the terms 'folder' and 'directory' to mean the same thing. Old school Linux users prefer 'directory' as that is how they are referred to on the command line. Keep an eye on your prompt to see how it changes when you change directories.
First, change directories (cd) to the Documents directory:
user@host:~$ cd Documents
Now, make a new directory (mkdir) called 'wordle':
user@host:~/Documents$ mkdir wordle
Change directories (cd) to 'wordle':
user@host:~/Documents$ cd wordle
Your new working directory should be /Documents/wordle. Let's confirm that. Tell the terminal to print the name of the current working directory (pwd):
user@host:/Documents/wordle$ pwd
/home/user/Documents/wordle
Knowing which directory the terminal is in is important. The commands you issue will happen inside the current working directory unless you explicitly tell the command to use a different directory. Everything we're going to do should happen inside this directory.
Anytime you need help with a command, type the command followed by a space and --help to get a brief note on the basics of the command. Most linux commands have these flags you can use to modify the basic command. Some flags, like --help, are whole words and prefixed by two dashes. Other flags are just one letter preceded by a single dash. These flags are known as options. Try it with:
user@host:~/Documents/wordle$ pwd --help
You can also try using the --help option with other commands:
mkdir --help
Now that you have your workspace set, we won't show the whole prompt. We'll show only the commands issued, like the one above.
Practice with the --help option as much as you want with the commands we've already used - cd, mkdir, pwd. Warning: If you try
echo --help
Well, see what happens. To get the help text for echo, use:
help echo
If you move out of the directory or close the terminal, you can easily get back to our 'wordle' directory by issuing the command:
cd ~/Documents/wordle
Let's Go Surfing - Finding a Wordle Word List to Analyze
Your Linux system comes with its own dictionary. It is a list of words applications can use to do things like check spelling. Wordle uses a curated word list, so the system dictionary won't be much help. There are many such curated Wordle word lists on the Internet, but you don't need to go searching for one. We've found a good list for you. Just open this link in a new browser tab:
https://raw.githubusercontent.com/Kinkelin/WordleCompetition/refs/heads/main/data/official/shuffled_real_wordles.txt
Take a few moments to study the file in the browser. Note the following things:
- The first line in the file starts with a #, but the rest of the file is five-letter words (all in lowercase) with each word on its own line. That may seem like a waste of visual space, but this is exactly the type of file Linux loves. Word processor documents, spreadsheets, tables, and columns all make the job of reading the file harder for Linux. This simple text file is perfect for us.
- The first line says the file has 2,315 words. Pretty close to the number of curated words used by Wordle.
- The words are not in alphabetical order. That might nag at our human sense of order, but it won't affect the analysis Linux will do.
- What about letter pairs (th, ou)? How often do they come up? In English, letter pairs are called digraphs. If both lettters are vowels, the pair is called a dipthong (shoutout to English teachers everywhere).
Ok, this is a good list. Let's download it into our workspace.
Back to the Terminal!
Click back into the terminal. Make sure you are in the correct workspace, the directory called wordle. Tell the terminal to download the file.
wget https://raw.githubusercontent.com/Kinkelin/WordleCompetition/refs/heads/main/data/official/shuffled_real_wordles.txt
The command wget is a tool for downloading files from web servers. When the command tells you its done, confirm you have the file in the directory with a ls command. The ls command tells the terminal to list files and directories in a directory:
ls
shuffled_real_wordles.txt
We can also look at the contents of the file in the terminal. The cat (from the word catenate) command will do that, but it has a small hitch. See if you can spot it when we run the command:
cat shuffled_real_wordles.txt
As you can see, the cat command just spits out the entire file contents. And since the file has 2,000+ lines, you can't see the whole thing. We should use the less command.
less shuffled_real_wordles.txt
Aha! Now you see the top of the file, but not the end of the file. The less command shows you just one page of the file at a time. If you want to see the next page, just hit the spacebar or the PgDn/PgUp keys. The down/up arrow keys work, too, but only move one line at a time. You can do this as much as you like until you quit less. Move up and down a few pages and lines using the different navigation key options. To quit less, just tap the Q key. By the way, less is known as a pager command, because it shows output in pages.
One more command we want to use to inspect this file is wc or word counter. wc does exactly what its name says -- it counts words in a file. Try it:
 wc shuffled_real_wordles.txt
2316 2335 14000 shuffled_real_wordles.txt
wc displays line, word, and then byte counts. The three numbers match up with our expectations -- 2,315 lines plus a one-line description at the top, for a total of 2,316 lines and 2,335 words. If we want wc to show only lines, use wc -l or for words, wc -w. Try it:
wc -l shuffled_real_wordles.txt
2316 shuffled_real_wordles.txt
wc -w shuffled_real_wordles.txt
2335 shuffled_real_wordles.txt
Use wc --help to see how to count characters. We won't use it here, but it may be good to know.
See how that first sentence is keeping us from exactly matching the number of Wordle words? It's going to confuse Linux, too. We don't want that sentence in our analysis, so let's edit our file and get rid of it.
Terminal, Edit Me a Story
A good practice to follow before we edit a file is to make a copy of it first. That will let us have an original copy. In the terminal, we'll do this with the cp (copy command). In this case, we're going to give the command two filenames -- the original name and the new name. Also, let's give our working copy a shorter name:
cp shuffled_real_wordles.txt words.txt
When we get no messages back, we can assume the command worked.
Now we edit our working file with with nano. Nano is the current default editor in Fedora. There are other editors that can be run in the terminal -- vim, emacs, micro, just to name a few. If you want to use a different editor, that's OK. We'll stick with nano here.
nano words.txt
Once you are in nano, there are two important commands to remember. CTRL+O will write/save the file. Nano will ask you to confirm the name. Hit enter. The second command quits nano -- CTRL+X. If you make changes and try to quit without saving, nano will ask you if you want to save changes to the file (Save modified buffers?). You can press Y, N, or CTRL+C (cancel and return to nano), depending on what you want to do.
Delete that first line. Don't leave any blank spaces between the first word and the top of the file. Save the file and exit nano.
Let's check the wc output now:
 wc -lw words.txt
2315 2315 words.txt
Perfect. 2,315 lines and 2,315 words. See how we combined the -l and -w options? Many commands will let us do this. Keep this in mind as you gain experience with the terminal.
Let the Analyzing Begin!
Analysis is an intimidating word that just means asking questions and finding answers about a thing by breaking that thing down into its component parts. Take another look at our word list and its component parts, letters. What questions could we ask about them? Here are the questions we're going to work on in our analysis.
- What is the total letter frequency in the possible word list?
- What are the most frequent letters at the start of a word?
- What are the most frequent letters at the end of a word?
- What about letter pairs (th, ou)? How often do they come up?
In English, letter pairs are called digraphs. If the letters are both vowels, the pair is called a dipthong (shoutout to English teachers everywhere).
You could easily come up with more questions. Make a note of them. After you get some experience, start hunting for answers on your own. For now, we'll focus on some simple text analysis questions.
I'll Grep You, My Pretty
The grep command's function is simple and powerful. It finds text based on a pattern you give it, and outputs what it finds. It can find exactly what we're looking for, or it can find things that come close to what we're looking for. In fact, grep is going to be the cornerstone of our analysis work, so we should spend some time learning the basics.
You tell grep what you want to find in the file by giving it a pattern or regular expression (also called a regex) and a place to search. Let's say you want to see if the word 'eater' is in our words.txt file. A recommended practice is to put the pattern in quotes, so we'll do that here:
 grep "eater" words.txt
eater
The response shows us grep found 'eater' in the file. Try this one:
grep "eaton" words.txt
grep found nothing so nothing is returned. Remember, Wordle does not use proper nouns, so that makes sense (sorry, Eaton, Ohio).
What if we want to find all of the words with 'eat' in them? Simple enough:
grep "eat" words.txt
treat
wheat
cleat
heath
great
bleat
eater
eaten
cheat
death
sweat
pleat
meaty
Wow! Now we can begin to see the true power of grep.
When we are building our search pattern for grep, we can use special characters called wildcards and anchors. A wildcard is a placeholder for unspecified letters. We can use a dot (.) to represent any single character. The star/asterisk (*) character represents the previous character any number of times, including no character at all. Combine the dot and star (.*) to match any number of any character. Let's try wildcards out to see how they work with grep.
Words with a single character between 'e' and 'at':
grep "e.at" words.txt
begat
elate
Words with any number of (including zero) characters between 'e' and 'at'
grep "e.*at" words.txt
treat
wheat
cleat
heath
great
bleat
eater
eaten
cheat
death
sweat
begat
elate
pleat
meaty
eclat
The "e.*at" pattern matches all of the words the "eat" pattern PLUS begat, elate, and eclat.
Anchors tell grep where we want the search to be focused in a line. We can tell grep to search at the start (^) of the line or at the end of the line ($). This is exactly what we'll need when we check for the most frequent starting and ending letters in our words. Let's search for words with 'eat' at the start of the line in our words.txt file:
grep "^eat" words.txt
eater
eaten
How about words with 'eat' and the end of the line?
grep "eat$" words.txt
treat
wheat
cleat
great
bleat
cheat
sweat
pleat
The grep command has several available options, but we need to be aware of two of them. If you read grep --help, you'll see that grep has a count (-c) option that reports the number of lines matched by the pattern. If a word has two of the same letter, it will match that, but only count the line once.
 grep -c "a" words.txt
909
The grep command found 909 words that contain the letter 'a.'
The second grep option we need is -o, which prints out every match of the pattern it finds. Given a single line with two matches, the grep -o command prints out both matches. Let's see how it works:
grep -o "a" words.txt
a
a
a
.....
That time we asked grep to print out every occurence of a. It did that dutifully, printing out 'a' more times than we want to count. Let's give grep a little help with a pipe. We'll review pipes in greater detail next, but let's just add one to our last command.
grep -o "a" words.txt | wc -l
979
Here, we took our never ending lines of 'a' and sent them to wc to count. We came up with 979 occurrences. So, we can say that the letter 'a' is found in 909 words, but appears 979 times, thanks to repeated letters in words (e.g., alarm).
Say Hello to My Little Friend(s) -- Pipes and Filter Commands
The pipe symbol (|) tells the terminal to start the pipe process. The pipe tells the first command to send its output to the next command. The second command then receives the input, processes it, and spits it out in its own format. The commands and pipes together are called a pipeline. The commands receiving the output are filter commands. Almost any command can be a filter command, but there are a few commonly used filter commands we want to focus on -- sort, uniq, head, column, and tee. Briefly, here's what each does:
- sort orders input. When used with -n, it can sort numbers, and with -r it can do a reverse sort.
- uniq identifies and acts on repeated matches. When used with the -c option, it returns the occurence and the number of times the occurence was found.
- head just displays the first 10 lines of ouput. The command can be adjusted to show a specific number of lines. head has a brother called tail that works on the last lines.
- column formats input into multiple columns. This command is a gem when dealing with a long list of simple outputs.
- tee copies output sent to our display and sends it to another location, like a file. It does not supress the output to the terminal. This helps us capture the output in a more permanent way, while still displaying output in the terminal.
Let's build a pipeline as an example
Say we want the output of one of our grep command to appear in alphabetical order, and we just want to see the first 5 lines.
grep "eat" words.txt | sort | head -5
bleat
cheat
cleat
death
eaten
Remember how the command grep -o "a" words.txt just printed out 'a' repeatedly? We piped the number of lines to wc -l to count the lines. The uniq -c does something similar, with a slightly different output:
grep -o "a" words.txt | uniq -c
979 a
The uniq command has the advantage over wc -l of being able to group together and count matching output. That will let us get the output of a grep command using wildcards while keeping an accurate count of each letter.
Let's count all the letters. We can use the (.) wildcard instead of typing every single letter. We'll add head to the end of our pipeline to keep our terminal tidy:
grep -o "." words.txt | uniq -c | head
1 s
1 c
1 o
1 w
1 l
1 w
1 a
1 g
1 e
1 r
What happened? grep sent the uniq command the data for each line. So, uniq told us the word 'scowl' has one 's', one 'c', etc. We want to know the total occurences for letters in all lines, not just the individual letters. We have to insert a sort to arrange the output of grep by letter before it gets sent to uniq. We'll use head to keep from filling the terminal with so much output:
grep -o "." words.txt | sort | uniq -c | head
979 a
281 b
477 c
393 d
1233 e
230 f
311 g
389 h
671 i
27 j
We're getting warm. We see that the letters are listed alphabetically, rather than by order of frequency. Let's throw in another sort. This one will sort the output by frequency or count. Remember to use a reverse number sort, so the letters are listed by order of their frequency, highest to lowest. This time, we want to see data on all of the letters, so let's replace head with column:
grep -o "." words.txt | sort | uniq -c | sort -nr | column
1233 e   729 t   575 n  393 d   311 g   195 w   29 q
979  a   719 l   477 c  389 h   281 b   153 v   27 j
899  r   671 i   467 u  367 p   230 f   40 z
754  o   669 s   425 y  316 m   210 k   37 x
That's it! We have listed letters in our Wordle words.txt file by order of frequency. Let's store this output in a file with the tee command.
grep -o "." words.txt | sort | uniq -c | sort -nr | column | tee letter-freq.txt
We see in the display the same output as earlier. Check the letter-freq.txt file:
cat letter-freq.txt
Bingo! Question #1 of our analysis is complete!
Now we need to answer questions #2 and #3.
Recall they are:
- What are the most frequent letters at the start of a word?
- What are the most frequent letters at the end of a word?
Since we've already figured out how to get total letter frequency in the file, all we have to do is adjust our grep command to check the first and last letters of each word. As we mentioned before, we can tell grep to do this by using the caret (^) or dollar sign ($) characters in our search pattern. Let's try it first before committing the results to a file.
grep -o "^." words.txt | sort | uniq -c | sort -nr | column
366 s   142 p   111 d   83 w   41 o   23 q   3 z
198 c   141 a   107 m   72 e   37 n   20 k
173 b   136 f   105 r   69 h   34 i   20 j
149 t   115 g    88 l   43 v   33 u   6 y
Too easy! Let's add the output to another file.
grep -o "^." words.txt | sort | uniq -c | sort -nr | column | tee starting-letter-freq.txt
The terminal should display the same output as the previous command but the output is also stored in the file starting-letter-freq.txt.
Now, let's do the ending letters:
grep -o ".$" words.txt | sort | uniq -c | sort -nr | column | tee ending-letter-freq.txt
We now have three files -- letter-freq.txt, starting-letter-freq.txt, and ending-letter-freq.txt -- that answer our first three questions.
Looking For Letter Pairs
In the final part of our analysis, question #4, we want to see which letter pairs are used most frequently. This time, instead of counting each instance of a letter pair, including repeated appearances in a single word, we only want to count the number of words that contain a specific letter pair. Using grep -c, we can create letter pairs once, and then count the number of words that contain that pair. Given that all of our words have only five letters, it's reasonable to conclude that our word count will not be too different from a total letter pair count. The only downside with the word count is that we'll find several letter pairs are not used at all. We can live with that. Let's get to work.
We can make letter pairs right in the terminal, automatically. We'll use a bash function called "brace expansion" to do just that. If you're using a shell other than bash, you'll have to check the documentation to see how your shell does brace expansion.
Brace expansion in bash is designed to generate unique strings given a base string and two or more items in a list. Typically, you'd want to use this to name related files. Here's an example:
 echo {dinner,lunch,breakfast}-menu.txt
 dinner-menu.txt lunch-menu.txt breakfast-menu.txt
A nice feature of brace expansion is that bash understands sequential letter and number braces with a little shorthand trick:
 echo {a..z}
 a b c d e f g h i j k l m n o p q r s t u v w x y z
and
 echo {1..7}
 1 2 3 4 5 6 7
So, bash treats {a..z} as all of the letters of the English alpahabet in order, lowercase, and {1..7} as all numbers 1-7 in order.
How can we apply this to our letter pair problem? Let's try something simple first, like creating all the possible letter pairs that begin with 'a'. How about:
 echo a{a..z}
aa ab ac ad ae af ag ah ai aj ak al am an ao ap aq ar as at au av aw ax ay az
We're on the right track, but we want all letter pairs.
 echo {a..z}{a..z}
aa ab ac ad ae af ag ah ai aj ak al am an ao ap aq ar as at au av aw ax ay az ba bb bc bd be bf bg bh bi bj bk bl bm bn bo bp bq br bs bt bu bv bw bx by bz ca cb cc cd ce cf cg ch ci cj ck cl cm cn co cp cq cr cs ct cu cv cw cx cy cz da db dc dd de df dg dh di dj dk dl dm dn do dp dq dr ds dt du dv dw dx dy dz ea eb ec ed ee ef eg eh ei ej ek el em en eo ep eq er es et eu ev ew ex ey ez fa fb fc fd fe ff fg fh fi fj fk fl fm fn fo fp fq fr fs ft fu fv fw fx fy fz ga gb gc gd ge gf gg gh gi gj gk gl gm gn go gp gq gr gs gt gu gv gw gx gy gz ha hb hc hd he hf hg hh hi hj hk hl hm hn ho hp hq hr hs ht hu hv hw hx hy hz ia ib ic id ie if ig ih ii ij ik il im in io ip iq ir is it iu iv iw ix iy iz ja jb jc jd je jf jg jh ji jj jk jl jm jn jo jp jq jr js jt ju jv jw jx jy jz ka kb kc kd ke kf kg kh ki kj kk kl km kn ko kp kq kr ks kt ku kv kw kx ky kz la lb lc ld le lf lg lh li lj lk ll lm ln lo lp lq lr ls lt lu lv lw lx ly lz ma mb mc md me mf mg mh mi mj mk ml mm mn mo mp mq mr ms mt mu mv mw mx my mz na nb nc nd ne nf ng nh ni nj nk nl nm nn no np nq nr ns nt nu nv nw nx ny nz oa ob oc od oe of og oh oi oj ok ol om on oo op oq or os ot ou ov ow ox oy oz pa pb pc pd pe pf pg ph pi pj pk pl pm pn po pp pq pr ps pt pu pv pw px py pz qa qb qc qd qe qf qg qh qi qj qk ql qm qn qo qp qq qr qs qt qu qv qw qx qy qz ra rb rc rd re rf rg rh ri rj rk rl rm rn ro rp rq rr rs rt ru rv rw rx ry rz sa sb sc sd se sf sg sh si sj sk sl sm sn so sp sq sr ss st su sv sw sx sy sz ta tb tc td te tf tg th ti tj tk tl tm tn to tp tq tr ts tt tu tv tw tx ty tz ua ub uc ud ue uf ug uh ui uj uk ul um un uo up uq ur us ut uu uv uw ux uy uz va vb vc vd ve vf vg vh vi vj vk vl vm vn vo vp vq vr vs vt vu vv vw vx vy vz wa wb wc wd we wf wg wh wi wj wk wl wm wn wo wp wq wr ws wt wu wv ww wx wy wz xa xb xc xd xe xf xg xh xi xj xk xl xm xn xo xp xq xr xs xt xu xv xw xx xy xz ya yb yc yd ye yf yg yh yi yj yk yl ym yn yo yp yq yr ys yt yu yv yw yx yy yz za zb zc zd ze zf zg zh zi zj zk zl zm zn zo zp zq zr zs zt zu zv zw zx zy zz
And there is our letter pair list, all 676 of them.
So how are we going to run all of these through grep? The pipeline commands we used would work, but we would have to manually enter each letter pair as the pattern. We need something to send the output of the brace expansion to grep. And we have just such a solution called a "for loop". Let's take a look at a simple for loop in the terminal:
 for n in {1..5}; do echo $n; done
1
2
3
4
5
What's happening here? We tell bash for each number (n) in the list created by the brace expansion of {1..5}, do the echo command on that number, then finish.
You see that each step in the loop construct is separated by a semicolon. We gave the individual items in the brace expansion a name (n). The n is called a variable, and when we use it again, we refer to it as $n so bash knows it is a variable name.
This is a lot of work going on in one line, so bash allows us to use new lines instead of the semicolons, as shown below. When you hit enter after the first line, bash knows you haven't given it a full command yet, so it goes to the next line, and adds a '>' to the front of the display. When you've given bash a complete command, after you type 'done,' bash goes to work.
 for n in {1..5}
 >do echo $n
>done
1
2
3
4
5
Multiple commands can occur in the loop. We just add them to the list of commands after the 'do', like this:
 for n in {1..5}
 do echo "The number is..."
 echo $n
 done
 The number is...
1
 The number is...
2
 The number is...
3
 The number is...
4
 The number is...
5
As easy as this is to do, it's still a bunch of typing. Any mistakes we make will mean we have to go back and re-type the whole command. We should put it into a file that we can execute without typing the whole thing out.
Welcome to shell scripting!
We could write the script just like we've done in the terminal, but that won't be very readable for humans. Let's use a couple readability tricks for our script. When scripting a for loop, many experienced scripters use this format:
for n in {1..5}; do
echo "The number is..."
echo $n
done
We put the "for" and "do" statements on the same line, separated by a semicolon. This lets the reader see a loop is coming, and keeps the list of commands in the format we would use directly on the command line, one command per line. We also indented each command, so they are nestled between the 'for/do' and 'done' statements.
Now we're ready to create a shell script to count letter pair frequency. Let's create a filename called 'lpcount.sh' The '.sh' at the end is called a filename extension. It will tell the terminal this is a script file.
nano lpcount.sh
Add this text to the file:
 #!/bin/bash
for n in {a..z}{a..z}; do
  pcount=$(grep -c $n words.txt)
  echo $pcount $n
done
Save and close the file with CTRL+O, ENTER, CTRL+X. Next, we have to make the file executable. We do this with the chmod (change file mode bits):
chmod +x ctofive.sh
We have our first script! Don't dismiss the script because of its small size. you'll find other situations where short scripts like these can save you tons of time. Experienced users usually have a collection of these home-made scriptlets or snippets to make their work easier. Let's finish up our analysis by using our new script in a pipeline.
First, we just want to test the script to make sure it works. We'll use the head command in a pipeline so we only get the first 10 lines, rather than all 676.
 ./lpcount.sh | head
 0 aa
 29 ab
 52 ac
 49 ad
 1 ae
 18 af
 26 ag
 2 ah
 47 ai
 2 aj
Perfect! Let's run the command again. This time, we'll do a reverse number sort, format the output into columns and send the output of all 676 letter pair word counts to a file.
Question 4 has been answered! Later, you may want to look for starting or ending letter pairs. We've already done starting and ending single letters, so finding starting and ending letter pairs won't be too difficult.
Summary and Next Steps
We took our first steps into the linux terminal and bash by doing some analysis on a Wordle word list. You can easily apply these skills to other tasks, like log and config file reviews. The techniques used here are useful, but in some cases, not optimal. As you learn bash, you'll find better ways to do the simple things we've done here. You also wrote a small program that does something useful. If I've whetted your appetite to do more text analysis, I recommend you learn a dedicated language like Python or Perl. As powerful as bash scripting is, those two programming languages will outstrip bash in capability and speed very quickly when it comes to text analysis.
18 Nov 2026 8:00am GMT
17 Nov 2026
Fedora People
Guillaume Kulakowski: Migration de Fedora-fr vers Flarum 2 : les coulisses techniques et les nouveautés
17 Nov 2026 5:53pm GMT
Fedora Infrastructure Status: Login issues with Forge & Bodhi
17 Nov 2026 10:00am GMT
16 Nov 2026
Fedora People
Aurélien Bompard: From November 09 to November 15

Across the various Fedora working groups, a major focus this week was the transition between release cycles, heavily featuring post-release cleanup and monitoring for Fedora 45 alongside active planning for Fedora 46, including proposals like the removal of the legacy DNF4 stack. Infrastructure and tooling migrations were another prominent shared theme; multiple teams-including Docs and Gaming-are migrating references from Pagure and GitLab to Fedora Forge, while the Council and FESCo are actively investigating Forgejo-based replacements for the retiring Bugzilla issue tracker. Security and system maintenance also drove significant cross-team collaboration, highlighted by a coordinated infrastructure outage for server updates, the removal of inactive packagers, and widespread vulnerability patching in the Rust and CoreOS groups. Finally, community engagement teams like Mindshare and Ambassadors are aligning their efforts to finalize proposals, funding, and volunteer coordination for major upcoming open-source conferences, particularly FOSDEM 2027 and FOSSASIA 2027.
- Announcements
- Council
- FESCo
- Packaging Committee
- Mindshare
- Fedora Join
- Ambassadors
- Workstation / GNOME
- KDE
- Server
- Infrastructure
- Release Engineering
- Quality
- Websites and Apps
- Design
- Docs
- COPR
- EPEL
- Atomic
- CoreOS
- IoT
- Alternative Images
- AI
- RISC-V
- Gaming
- Perl
- Ruby
- Rust
- Other Discussions
- All contribution opportunities
Announcements
Contributors should be aware of a planned infrastructure outage scheduled for November 19, 2026, at 22:00 UTC, which will last approximately four hours to accommodate server updates and reboots. Additionally, as part of routine maintenance for the Fedora 45 development cycle, 161 users are being removed from the packagers group due to inactivity. For those looking to get more involved, the latest Fedora Podcast (Episode 064) not only discusses the recent Fedora 45 release but also highlights several upcoming engagement opportunities for Fedora 46, including writing release notes, participating in test weeks, and submitting wallpaper ideas.
In broader community news, two new guides have been published to help users enhance their desktop experience. The first outlines a method to install the official Claude Desktop Linux beta on Fedora, utilizing a script to safely extract and run Anthropic's .deb package without root privileges. The second introduces TuxTalk, a free, locally-hosted voice dictation tool for Linux that allows users to dictate text directly into any application, terminal, or document without requiring an account or sending voice data off-device.
Council
This week, the Council addressed trademark usage for a new Fedora-derived distribution called Bibim, clarifying that the Fedora Remix logo is the intended branding for such projects, which led the creators to adopt the Remix guidelines instead of seeking a trademark variance (Trademark question: using the Fedora logo for a Fedora-derived distribution (Bibim)). Additionally, a significant community discussion began regarding the future of Fedora's issue tracking system in light of the upcoming retirement of Red Hat's hosted Bugzilla, with members debating the transition to a Forgejo-based system versus maintaining a community Bugzilla instance (What issue tracker do we want to use for Fedora 90?).
Contribution opportunities
- Contribute to creating a script or packaging solution that simplifies converting a standard Fedora release into a Fedora Remix.
- Help design a specific landing page for Fedora Remix users to encourage upstream contributions.
- Submit concrete proposals, gather requirements, or write user stories for Fedora's future issue tracking system transition.
Learn more about the Council team.
FESCo
This week, FESCo held one meeting and processed numerous tickets, primarily focusing on approving System-Wide and Self-Contained Changes for upcoming Fedora releases. Key discussions centered around the ongoing investigation into replacing Bugzilla, managing the removal of unmaintained NetworkManager VPN plugins, and extending the F45 FESCo election voting period to accommodate the holidays. FESCo also formally set the EOL date for Fedora 43.
Decisions
- The Fedora 43 End of Life was officially set to 2026-12-02.
- Ticket #3703: Approved the change to move the distribution to the RPM v6 package format.
- Ticket #3693: Approved removing NetworkManager-{vpnc,fortisslvpn} from F44 Atomic Desktops, but rejected adding obsoletes in F44.
- Ticket #3708: Agreed to extend the FESCo election voting period to January 5th, leaving the nominations period as is.
- Ticket #3705: Approved a permanent updates policy exception for media processing libraries (live555 and openapv).
- Ticket #3706: Approved a one-time F45 Updates Policy Exception for python-openai.
- Ticket #3701: Approved the LMDB 1.0 Transition.
- Ticket #3700: Approved changing the Libvirt Network Filter default firewall backend to NFTables.
- Ticket #3699: Approved the Libchewing 0.14 update.
- Ticket #3698: Approved the Emacs Package Packaging change.
- Ticket #3697: Transferred ownership of python-authlib to a new co-maintainer under the non-responsive maintainer policy.
Contribution opportunities
- Julita Inca requested a mentor to help them start contributing to Ansible testing in Fedora (Meeting Log).
- Feedback is requested on the draft policy for global CI tests (Ticket #3683).
- Community members are invited to test and provide feedback on the ongoing Bugzilla replacement investigation and staging instances (Ticket #3664).
Learn more about the FESCo team.
Packaging Committee
The Packaging Committee focused this week on updating the Emacs packaging guidelines to support the built-in package management system in recent versions of GNU Emacs. This includes discussing and merging changes that provide new RPM macros and dependency generators for Emacs packages. Additionally, new tickets were opened to discuss allowing Emacs add-ons in RPM subpackages (Issue 1581) and marking up spec templates as source code (Issue 1582).
Decisions
- The committee approved and merged PR#1577 (associated with Issue 1577), which introduces new RPM macros and dependency generators for Emacs packages, with plans to resolve minor formatting and Unicode issues post-merge.
Learn more about the Packaging Committee team.
Mindshare
The Mindshare group focused on upcoming conference preparations and deadlines. Reminders were issued for FOSSASIA 2027, noting the November 19 deadline to update the event wiki and November 29 for talk proposals. Additionally, a final call for financial assistance applications for FOSDEM 2027 was made ahead of the November 15 deadline. Community members also briefly connected regarding attendance at SFSCON 2026.
Decisions
- Future FOSDEM financial assistance requests will transition from using the Wiki to a dedicated application form to better capture budget details and applicant motivations (URL).
Contribution opportunities
- Update the FOSSASIA 2027 Fedora Project Wiki by November 19, 2026, if you plan to attend.
- Submit talk or volunteering proposals for FOSSASIA 2027 on their official website by November 29, 2026.
- Apply for financial assistance to attend FOSDEM 2027 by adding budget request details to the Wiki table by November 15, 2026.
Learn more about the Mindshare team.
Fedora Join
This week, the Fedora Join group received introductions from two new prospective contributors. Fardeen Khan introduced themselves as a developer and Fedora advocate looking for guidance on which teams to join. Lutz Weber also introduced themselves, expressing interest in starting with Quality Assurance (QA) and eventually contributing to the Python SIG and software packaging.
Contribution opportunities
- Guide Fardeen Khan in finding a suitable team to contribute to, utilizing their development and ethical hacking background.
- Welcome Lutz Weber and help them get started with the QA team and the Python SIG.
Learn more about the Fedora Join team.
Ambassadors
This week, the Ambassadors group focused on coordinating Fedora's presence at upcoming major open-source conferences. Reminders were issued for approaching deadlines regarding event proposals, talk submissions, and financial assistance requests for both FOSDEM 2027 and FOSSASIA 2027. Furthermore, community members discussed potential informal meetups at the South Tyrol Free Software Conference (SFSCON).
Contribution opportunities
- Update the FOSSASIA 2027 Fedora Project Wiki by November 19, 2026, to be included in the Fedora Mindshare event proposal.
- Submit talk and volunteer proposals for FOSSASIA 2027 on the official event website by November 29, 2026.
- Apply for FOSDEM 2027 sponsorship and financial assistance by adding budget request details to the Fedora Wiki by November 15, 2026.
Learn more about the Ambassadors team.
Workstation / GNOME
This week, the Workstation / GNOME group addressed several critical system behavior and packaging issues. Key discussions included a bug in GNOME 51's GDM that disables initial fingerprint login-breaking Fedora's authselect and oo7-daemon workflows-and a Btrfs metadata exhaustion issue prompting calls to reconsider auto-balancing defaults. Additionally, users reported a crash in pdftotext when handling certain PDFs, which has been forwarded upstream.
On the ticketing side, the group successfully completed the replacement of gnome-keyring-daemon with oo7-daemon. Active investigations are ongoing regarding automating appstream-data updates and a dependency resolution bug where removing Firefox via GNOME Software inadvertently changes the system's identity to Budgie.
Decisions
- The migration to replace
gnome-keyring-daemonwithoo7-daemonas the default secret service provider was completed and the ticket was closed. (Issue #506)
Contribution opportunities
- Assist with the ongoing effort to automate the generation and updating of
appstream-datato ensure software center metadata remains current. - Contribute to resolving a
dnf5daemon-serverdependency resolution bug where removing Firefox via GNOME Software changes the OS identity to Budgie. - Provide feedback or patches for the downstream GDM fingerprint login issue to help maintain
authselectandoo7-daemonworkflows.
Learn more about the Workstation / GNOME team.
KDE
This week, the KDE group focused on resolving user-reported issues with recent Plasma updates and discussing future package replacements. Community members actively addressed a shutdown hang bug in Plasma 6.8 by providing unofficial fixes via COPR and pull requests for Qt, while also testing an unofficial build of Plasma 6.8.3. Additionally, discussions clarified the removal of X11 sessions in Fedora 44 and the expected weekly cadence for automated Discover updates on Kinoite. On the development front, new requests for enhancements (RFEs) were filed to replace kwalletmanager with KeepSecret and to remove live-system-only packages during Plasma Setup to save disk space. The ongoing effort to replace kwallet with oo7-daemon was deferred for KDE due to integration challenges.
Decisions
- The replacement of kwallet with oo7-daemon has been deferred for KDE variants due to integration issues and a lack of time (URL).
Contribution opportunities
- Test the unofficial COPR for KDE Plasma 6.8.3 on Fedora 44 and 45 and report any issues in the forum thread.
- Test the Qt 6.11.2 COPR containing the cherry-picked fix for the Plasma 6.8 shutdown hang issue on Fedora 44 and 45 (URL).
Learn more about the KDE team.
Server
The Server working group met this week to discuss ongoing projects and potential changes for the upcoming Fedora 46 release. Key discussions centered around the 'Strengthening Server Updates' project, which was postponed to allow for further testing, and the future of Single Board Computer (SBC) images. Additionally, a community member published a comprehensive and highly successful test report detailing the upgrade path from Fedora 44 Server to the Fedora 45 release on a 2010-era machine, confirming excellent stability with no regressions.
Decisions
- The working group agreed to evaluate switching the Single Board Computer (SBC) image to GPT/EFI and dropping Raspberry Pi 3 support for Fedora 46. (URL)
- The group decided to keep NetworkManager for the time being rather than switching to systemd-networkd, citing issues with split DNS on virtual machine hosts and its utility in home lab setups. (URL)
- Working group members agreed to catch up on outstanding tasks for the Strengthening Server Updates project and revisit the topic on November 25, 2026. (URL)
Contribution opportunities
- Help is needed to test the procedures for the Strengthening Server Updates project and start a post-installation how-to style article.
- Contributors with image building experience are invited to assist in evaluating and implementing the switch of the SBC image to GPT/EFI, which involves updating kiwi definitions.
Learn more about the Server team.
Infrastructure
This week, the Infrastructure team focused heavily on resolving service disruptions and preparing for an upcoming mass upgrade. Bodhi experienced significant load and timeouts due to aggressive scrapers, prompting the team to implement mitigations like blocking specific RSS endpoints and deploying a Valkey backend for caching. The team also addressed sporadic 404 errors for jQuery on the Fedora Forge caused by Varnish mis-caching, and resolved IPA replication issues after an OS upgrade on ipa01.
Additionally, a planned outage for mass updates and reboots was scheduled for November 19th, which will involve upgrading several servers to Fedora 45. The team also investigated a sophisticated phishing campaign targeting mailing list administrators and welcomed several new contributors to the group.
Decisions
- A planned outage for mass updates and server reboots is scheduled for 2026-11-19 at 22:00 UTC, which will temporarily affect many contributor services.
- The team deployed a Valkey backend and blocked specific RSS endpoints to mitigate aggressive scraping that was taking Bodhi offline.
- A dedicated DNS zone for
packages.redhat.comwas added to allow RDU vmhosts to use external DNS servers. - Inactive packagers from the F45 cycle will be removed and their packages orphaned as per the Inactive Packagers policy.
Contribution opportunities
- Help is needed to refactor external HTTP checks in Zabbix to include proxies and dependencies. This is a good opportunity for contributors interested in learning Zabbix.
- Assistance is requested to configure ELN Monitoring to report to the #eln Matrix room, which is a beginner-friendly task for those wanting to learn Ansible.
- The team is looking for help to replace the deprecated oauth-proxy image used in the fas2discourse-operator.
Learn more about the Infrastructure team.
Release Engineering
The Release Engineering team focused on post-release cleanup for Fedora 45, including resolving an issue with missing torrents for several Labs ISOs that were absent at release time. The team also addressed an out-of-date Fedora 45 COSMIC Atomic reference and handled routine package unretirements and SCM requests, while monitoring and unsticking the package signing service. Additionally, preparations for the Fedora 43 End of Life have begun.
Decisions
- Fedora 43 End of Life is officially set for December 2, 2026, aligning with FESCo and existing policies (Meeting, Ticket #13588).
Contribution opportunities
- Releng is seeking feedback and impact checks for the F46 Change proposal to remove DNF4, libdnf, and libmodulemd, specifically regarding tooling like critpath.py.
- Feedback is requested on a proposed enhancement to track build-time dependencies in orphan reports to help downstream tools differentiate between runtime and build-time broken dependencies.
Learn more about the Release Engineering team.
Quality
The Quality team monitored the recent release of Fedora 45, noting a smooth rollout with no major regressions, which was corroborated by a detailed community server test on older hardware. The team is now transitioning focus to Fedora 46, reviewing upcoming system-wide changes, and continuing to document common issues for Fedora 45. Additionally, the KDE Plasma 6.8 test days were launched and actively promoted across the community.
Decisions
- Christopher Boni volunteered to send out the call for upcoming Test Days (Meeting log).
- Bug 2538553 was published to the Fedora 45 Common Issues, while bugs 2560255 and 2537131 are being held for further investigation before publication (Ticket #952).
Contribution opportunities
- Participate in the KDE Plasma 6.8 Test Days running from 2026-11-09 to 2026-11-15 by testing and submitting results.
- Help is requested to investigate a navigation test failure in openQA where
os-autoinstfails to recognize screen changes during Tux Racer gameplay (Ticket #954).
Learn more about the Quality team.
Websites and Apps
This week, the Websites and Apps team discussed the future of Fedora Magazine's hosting, prompted by a potential end of WP Engine support by the end of 2027. Conversations explored migrating from WordPress to a static site generator (like Nuxt or Hugo) paired with Decap CMS, or potentially using Discourse as a backend, though challenges remain regarding content conversion and comment integration. In the forums, a user reported that Fedora's wifi login detection domain is on the HSTS preload list, breaking captive portal detection, and suggested using a dedicated, independent domain. Additionally, the team handled a new collaborator request and tracked a deprecation warning for the @comark/nuxt module in the fedora-websites-3.0 repository.
Contribution opportunities
- Help is needed to explore and draft a strawman proposal for migrating Fedora Magazine off WP Engine to a static site or alternative CMS before the end of 2027.
- Contributors can assist in resolving the @comark/nuxt module deprecation warning in the fedora-websites-3.0 repository.
- Feedback and solutions are welcome on the forum discussion regarding the Fedora wifi login detection domain breaking due to HSTS preloading.
Learn more about the Websites and Apps team.
Design
This week, the Design team received a new request to create a "Fedora loves GNOME" sticker for distribution at upcoming conferences such as FOSDEM. Additionally, ongoing work continued on the community involvement poster, with the contributor using AI-generated feedback to identify and resolve typography, spacing, and alignment issues. In the background, several automated repository actions failed in the design/backgrounds repository, and the weekly team meeting appears to have been cancelled.
Contribution opportunities
- A graphic designer is needed to create a print-ready PDF for a "Fedora loves GNOME" sticker to be distributed at events like FOSDEM.
- Contributors can help troubleshoot and fix the failing
Update README.mdautomated actions across multiple branches in the design/backgrounds repository.
Learn more about the Design team.
Docs
This week, the Docs team focused heavily on migrating infrastructure references from the sunset Pagure and GitLab to Fedora Forge. This massive cleanup spanned multiple repositories, resulting in updated team documentation, build scripts, templates, and Quick Docs. The migration also resolved a bug in the translated builds by pointing the asciidoc-keywords repository to Forge. Additionally, discussions are underway to establish a Quay organization for hosting the team's CI container images.
In other content updates, the kernel testing patches guide was substantially reworked to use grubby and custom build IDs, making it safer and easier for users to manage test kernels. The team also prepared for Antora 3.2 by fixing malformed navigation entries, and updated the release notes to reflect that oo7 is delayed and not in F45, while adding a new note for Bash Color Prompt 1.0 in F46.
Decisions
- The 'How to edit files on the Pagure Web UI' guide has been officially retired and replaced with the Fedora Forge guide.
- The
oo7feature for KDE has been delayed and will not be included in the Fedora 45 Release Notes. - The default branch for
site-builderand related translation scripts has been officially switched tomain, and the legacyprodbranch will be deleted (Ticket 77, Ticket 58). - The kernel testing guide has been updated to recommend using
grubbyand custombuildids instead of overwriting existing packages, preventing conflicts with standard Fedora updates (Ticket 1087).
Contribution opportunities
- Team Decision Needed: Determine the future of the Publish RPMs on Copr Quick Doc, as its example repository was lost in the Pagure sunset.
- Team Decision Needed: Clarify what permissions the docs-admin and docs FAS groups grant on Forge to update the team charter.
- Contributor Opportunity: Help perform a full script sync for
docsbuilder.shto update it to the new Forge docs-template script format (Ticket 72). - Contributor Opportunity: Assist in replacing the remaining GitLab references with Fedora Forge in the team documentation.
- Contributor Opportunity: Help replace legacy
{partialsdir}includes withpartial$syntax in Quick Docs.
Learn more about the Docs team.
COPR
This week, the COPR team successfully executed a planned infrastructure outage to update machines to the latest packages. The outage was brief, and services were quickly restored. In discussions, the team addressed intermittent Bodhi outages affecting builds and identified an ongoing issue where internal messaging changes at Red Hat have broken the Fedora review bot. Additionally, the team clarified that some group-owned projects that missed the initial Pulp migration will be queried and migrated once the current batch of owners is finished. Maintainers also provided guidance on packaging non-crates.io Rust applications, clarifying the scope of rust2rpm.
Decisions
- Executed a planned infrastructure update for COPR on November 12, 2026, temporarily halting build queue processing and Frontend/Web-UI task acceptance (Mailing List).
- Group-owned projects that missed the initial Pulp migration will be migrated in a final sweep after the last batch of individual owners is completed (Matrix Chat).
- Deferred modifying the PR input schema to a follow-up PR, opting to merge the current PR as-is to maintain stability for both string and list variants (Matrix Chat).
Contribution opportunities
- Help improve the Fedora documentation for packaging non-crates.io Rust applications, specifically by making the manual .spec file template more prominent for inexperienced packagers.
- Investigate and help resolve the bazelisk build failure on Rawhide, which currently fails despite building locally.
Learn more about the COPR team.
EPEL
The EPEL team successfully completed the retirement of EPEL 10.2 and switched EPEL 10.3 to build against the newly released RHEL 10.3. Additionally, an EPEL 9.8 archive snapshot was created in response to the RHEL 9.9 release.
Other activities included delivering an RPM packaging workshop at the Texas Linux Fest, ongoing efforts to package Mailman 3 and Incus for EPEL 10, and closing the investigation into ffmpeg CVE-2025-59734 as it could not be reproduced.
Decisions
- The EPEL 10.2 release has been officially retired, and EPEL 10.3 has been switched to build against RHEL 10.3.
- The pull request to fix ffmpeg CVE-2025-59734 in EPEL 10 was closed because the vulnerability could not be reproduced.
Contribution opportunities
- A packager is needed to take up the stalled EPEL 10 request for gparted so that volunteer contributors can be added as collaborators.
- Help is requested to bring mailman3 to EPEL 10 to assist Releng in moving mailman to RHEL 10 infrastructure.
Learn more about the EPEL team.
Atomic
During this week, the Atomic group focused heavily on system update mechanisms, configuration management, and security. A recurring theme was the handling of file merges and updates across different system directories (/etc vs /var), specifically addressing how to safely regenerate certificates, crypto-policies, and appstream caches during system finalization or boot. Other significant activities included resolving a stalled update pipeline for the Fedora Cosmic-Atomic image and addressing compatibility issues with the new RPM v6 package format in rpm-ostree. The group also initiated discussions on improving the security of sealed images against CVE-2026-121876 by restricting auto-mounted partitions, and continued tracking the long-term goal of migrating away from nss-altfiles.
Decisions
- Fixed the stalled Fedora Cosmic-Atomic updates by correcting the release engineering scripts, allowing users to receive the latest nightly builds and updates.
- Determined that the rpm-ostree installation failure for RPM v6 packages (like Google Chrome 157) is an upstream issue; users are advised to use Flathub or hold back the update as a workaround (Ticket 138).
- Decided to run /etc-only updates (such as ca-certificates, crypto-policies, dconf, and SELinux) in advance at finalization time to avoid boot delays, while acknowledging that /var-dependent updates like mandb and appstream cannot be pre-run (Ticket 145).
Contribution opportunities
- Investigate and define default restrictive systemd image policies for sealed images to mitigate CVE-2026-121876.
- Help design a migration path and build images to transition away from nss-altfiles to standard systemd-sysusers or JSON records (Ticket 87).
Learn more about the Atomic team.
CoreOS
This week, the CoreOS group held a meeting to review the Fedora 46 Release Schedule, noting that Rawhide development has begun and that change proposals requiring mass builds or system-wide changes are due in December. In community discussions, a proof-of-concept for live kernel takeover on Fedora bootc using kmorph was shared, demonstrating a potential path forward for rebootless kernel updates.
Ticket activity was high, with 17 tickets addressed. Notable resolutions include a fix for a systemd-journald failure on ppc64le, the rollout of a patch for the CVE-2026-98432 TCP use-after-free vulnerability across multiple streams, and the resolution of an rpm-ostree package download issue in Konflux hermetic builds. Ongoing discussions include a proposed adjustment to the end-of-year release schedule to accommodate holidays and resolving SELinux denials for podman-remote socket connections.
Decisions
- The community agreed to migrate the automated engineering newsletter repository to the official CoreOS organization (Issue #2240).
Learn more about the CoreOS team.
IoT
This week, the IoT group addressed a system upgrade issue where a user was unable to perform further updates after upgrading to Fedora 45 due to a missing GPG public key. The problem was traced to an outdated GPG key path in the ostree remote configuration that had not been automatically replaced during the upgrade. The user successfully resolved the issue by manually updating the path to the correct directory.
Decisions
- The maintainers decided to close the GPG public key upgrade issue as an isolated incident, leaving the ticket available as a reference for any other community members who might experience the same configuration problem (Issue #143).
Learn more about the IoT team.
Alternative Images
The Alternative Images group met on November 12 to discuss the status of this quarter's image releases, which are currently delayed due to the setup of a new omni repository for RISC-V. The team expects to release the standard images shortly and is actively developing bootable aarch64 raw images for CentOS Stream 10. Additionally, the group noted that kiwi has been updated to version 11.x in EPEL 10, which integrates the stackbuild and boxbuild plugins directly into the core. In broader news for the Linux community, the CentOS ISA SIG is building a Fedora Omni kernel monthly to ensure compatibility across almost any RISC-V machine. The group also plans to triage their migrated GitLab issues to clear out older, closed items.
Decisions
- The CentOS ISA SIG decided to create an omni repository for RISC-V, which will include a Fedora Omni kernel built monthly to support a wide range of RISC-V hardware (Meeting Log).
- The group decided to roadmap the production of both live media and raw disk images for RISC-V for a future quarter, pending the availability of necessary EPEL packages (Meeting Log).
- It was decided to formally retire the
kiwi-boxed-pluginandkiwi-stackbuild-pluginpackages in EPEL 10, following the EPEL Retirement Policy, as their functionality is now integrated into the core of kiwi 11.x.
Learn more about the Alternative Images team.
AI
This week, the AI group saw activity across package reviews and AI tooling. A contributor proposed a review swap for a stack of packages including parrotia (a local transcription tool using Whisper) and its dependencies, python-darkdetect and python-customtkinter. In the Matrix channel, discussions covered the Fedora AI contribution policy regarding LLM usage in source code, an AI skill for converting Markdown to Gutenberg-ready print, and a fix for a ROCm upgrade issue between Fedora 44 and 45. Additionally, a new package review request was opened for agent-skills.
Contribution opportunities
- A contributor is seeking a package review swap and a sponsor for three packages: python-darkdetect, python-customtkinter, and parrotia (link).
- Testing and karma are requested for a fix addressing the Fedora 44 to 45 upgrade issue with ROCm (link).
- A package review is requested for agent-skills (link).
Learn more about the AI team.
RISC-V
The Fedora RISC-V group spent significant effort debugging a severe CPU lockup issue specific to the SpacemiT K3 SoC when building Rust with the RVA23 target for ELN (Ticket 40). After extensive testing, contributors identified that the lockup occurs when the CPU speculatively fetches instructions from unmapped code pages. A reliable workaround was found by increasing the page fault size (echo 2097152 > /sys/kernel/debug/fault_around_bytes), allowing multi-core Rust builds to complete successfully.
In other developments, a bug in the GCC build system's multilib configuration causing incorrect rva23u64 target paths was identified. The team also investigated KVM guest initialization failures on the K3 SoC when using QEMU with -cpu max (Ticket 39), noting that -cpu host with EDK2/OVMF bypasses the crash. Additionally, the Titan devicetree was merged into a maintainer tree, paving the way for full usability with the generic v7.5 kernel, and a workaround for a Titan EDK2 boot bug was confirmed.
Decisions
- Implemented a temporary workaround to increase
fault_around_bytesto 2 MiB on K3 builders to prevent CPU lockups during Rust compilation (Ticket 40). - Identified that the
target-lexiconcrate in several Rust packages (e.g.,keylime,tss-esapi) needs to be bumped to at least version 0.13.5 to properly support the RVA23 target. - Determined that QEMU KVM guests on the K3 SoC currently require
-cpu hostand EDK2/OVMF to boot successfully, as-cpu maxcauses instant initialization failures (Ticket 39).
Contribution opportunities
- Help is needed to update the
target-lexiconcrate dependencies in various Fedora Rust packages (such askeylimeandtss-esapi-sys) to support RVA23. - Contributors with access to JTAG hardware for the SpacemiT K3 (e.g., CoM260) are encouraged to help capture low-level CPU traces to find the root cause of the speculative fetch lockups.
- Assistance is welcome in testing and refining the QEMU/KVM ACPI boot combinations across different RISC-V hardware platforms to document what virtualization configurations work reliably.
Learn more about the RISC-V team.
Gaming
The Gaming group focused on infrastructure and documentation updates this week. Specifically, they completed a migration effort to update repository links and workflows, transitioning references from Pagure to the new Fedora Forge. This included updating the issue tracker links and refining the README with instructions for the Forge PR workflow and site-builder previews. Migrate links from Pagure to Fedora Forge
Learn more about the Gaming team.
Perl
This week, the Perl group primarily focused on package updates and architecture support. Steve Traylen submitted and merged multiple pull requests to update perl-SQL-Abstract to version v2.000003 and bump the EPEL 8 build post-unretire. Additionally, Emmanuel Seyman reported that perl-Algorithm-BloomFilter is failing to build on i686 systems, prompting discussions about dropping support for that architecture.
Decisions
- Exclude the i686 architecture for the
perl-Algorithm-BloomFilterpackage due to unresolved build failures, unless a fix is provided. Discussed in this thread. - Update the
perl-SQL-Abstractpackage to v2.000003 and bump the EPEL 8 build post-unretire, as seen in PR #11 and PR #10.
Contribution opportunities
- Help resolve the build failure for
perl-Algorithm-BloomFilteron i686 hosts to prevent the architecture from being excluded, as noted in this thread.
Learn more about the Perl team.
Ruby
Development for Ruby 4.1 is ongoing, with recent efforts focused on rebuilding the gem ecosystem and addressing Fail To Build From Source (FTBFS) issues against the latest snapshot. A significant change in Ruby 4.1 is the removal of net/pop and net/ftp from the default bundled gems. This removal breaks rubygem-mail and, recursively, Ruby on Rails (RoR) related packages. To mitigate this, a review request for rubygem-net-pop has been submitted. Additionally, maintainers have identified priority FTBFS issues that need resolution, specifically for rubygem-mysql2 and rubygem-ruby-libvirt, which block other major packages like RoR and Vagrant. Upstream Ruby has already fixed the rubygem-ffi FTBFS issue.
Decisions
- Maintainers decided not to fix the FTBFS issue for
rubygem-narrayduring the Ruby 4.1 migration, as it is an old package and lacks dependent packages.
Contribution opportunities
- Review or swap-review the new
rubygem-net-poppackage to help fix Ruby on Rails dependencies. - Help resolve the FTBFS issue for
rubygem-mysql2(testsuite failures), which blocks Ruby on Rails packages. - Help migrate
rubygem-ruby-libvirtto the TypedData API to fix its FTBFS status, which currently blocksvagrant-libvirt.
Learn more about the Ruby team.
Rust
This week, the Rust SIG focused heavily on security updates and package cleanups. Major efforts included rebuilding numerous packages to address security advisories in the zstd, zstd-safe, and quick-xml crates, as well as filing bugs for packages statically linking a vulnerable bundled sqlite. Additionally, the group discussed the challenges of packaging crubit for Chromium builds, ultimately advising against shipping the unstable rustc-dev in Fedora, and successfully concluded the retirement of outdated gtk-rs-core and gtk4-rs compatibility packages.
Decisions
- The group decided against shipping rustc-dev in Fedora or RHEL due to its reliance on unstable APIs, which impacts the Chromium build process. Alternatives like bundling Rust sources or pre-generating bindings were recommended (URL).
- Outdated compatibility packages for gtk-rs-core v0.20 and gtk4-rs v0.9 were officially retired from Rawhide after confirming they were no longer in use (URL).
- Stable branches of msedit will diverge from Rawhide and remain at version 1.x to bypass a test failure on s390x, leaving the Rawhide package temporarily affected by the zstd vulnerability (URL).
Contribution opportunities
- Maintainers of packages statically linking sqlite (such as flare-im, nodejs-pnpm12, task, and vaultwarden) need to update their packages to address CVE-2026-119375 (URL).
- Help is needed to port older packages relying on quick-xml v0.38 and v0.37 to the secure v0.41 release, which may require working directly with upstream developers due to default behavior changes (URL).
- The msedit maintainer has an opportunity to fix an s390x test failure on Rawhide to allow the package to receive the latest zstd security updates (URL).
Learn more about the Rust team.
Other Discussions
- Fedora Package Review Process reimagined - Jakub Kadlčík proposed and prototyped a reimagined package review process using an intermediate forge repository and pull requests, gathering feedback on the approach.
- From F45 onwards: Fedora-maintained (self-updating) hardening... - Chris introduced a Fedora-maintained, self-updating kernel hardening feature for F45 aimed at general use cases, which can be enabled with a single command.
- Proposal: Arborists SIG - Gordon Messmer proposed the Arborists SIG to develop branch management software that mirrors upstream releases in dist-git, aiming to streamline container builds.
- How can I contact the crypto team? - Steven Emelander from the AWS-LC and s2n-tls teams responded to feedback regarding their configuration scheme, expressing willingness to collaborate with the community.
- F46 Change Proposal: Remove DNF4 Stack and Modularity (system-wide) - On the devel-announce list, Aoife Moloney announced a proposal to remove the legacy DNF4 software stack and Modularity from Fedora 46.
- Packaging proposal: whatsapp-desktop - Abdallah Shehawey provided a refreshed source-only application snapshot for
whatsapp-desktopand discussed dependency handling, while seeking an application reviewer and packager sponsor. - Arch specific deps of subpackage in noarch package - Miroslav Suchý encountered a build failure when a noarch package had an architecture-specific dependency, which was resolved by using
BuildArch: noarchalongsideExclusiveArch: noarch x86_64 aarch64. - Packages with uninitialized git repositories (no commits) - Samyak Jain noted several package repositories with no initial commits that fail branching operations, prompting discussions on specific cleanups or deletions for the empty repos.
- Minimizing locale support in fedora-minimal container images - Marián Konček proposed removing non-English locale files from
fedora-minimalcontainer images to save space, sparking a discussion on existing locale filtering configurations. - Logwatch and systemd timers - Frank Crawford discussed moving the Logwatch package from using cron to systemd timers, noting that rsyslog might be a better fit for large systems while OpenTelemetry is increasingly preferred.
- Other discussions included guidance on packaging a userspace DMA-BUF library, a dnf upgrade error on protobuf conflict, questions about Logwatch and systemd timers, a report on Btrfs metadata exhaustion, a user support request regarding KDE Plasma Desktop mouse issues, adding F45 to repology, linking codeberg.org to Bugzilla, handling Meson abbreviated build logs, the upcoming EPEL 10.2 retirement, a Fedora Copr Outage on the buildsys list, the inactive packagers removal on the devel-announce list, a planned infrastructure outage on the devel-announce list, and a non-responsive maintainer check for vda.
Orphaning Packages
- Dominik 'Rathann' Mierzejewski orphaned the xorg-x11-drv-amdgpu package as they switched to Wayland; it was briefly claimed by Leigh Scott before being orphaned again.
- Michael J Gruber announced the intent to orphan portmidi, noting a switch to portmidi2 is overdue.
Package Updates
- On the devel-announce list, Aoife Moloney posted about the Libical4 update, and Michel Lind coordinated the final rebuilds to land it in Rawhide.
- Adrian Reber announced the libcdio 2.4.0 update in Rawhide, which includes SONAME bumps for libcdio, libiso9660, and libcdio++.
- Mattia Verga announced that python-dateutil 4.0.0 is coming to Rawhide, un-deprecating the package as upstream has become active again.
- Dominik 'Rathann' Mierzejewski announced a mac SONAME bump for Monkey's Audio Codec to version 13.46.
- Shawn W Dunn notified the list of a SONAME update for libfm-qt when version 2.5.0 hits Rawhide.
- Gwyn Ciesla announced an Angelscript SONAME bump for version 2.39.0.
New Contributor Introductions
- Alexey Savchkov introduced themselves as a DevOps engineer interested in adopting orphaned C/C++ packages like
ptlandusbsniff, and asked about using short vs. full git commit hashes in spec files. - Kanishk Bansal introduced themselves with a focus on security, submitting a rebase of
expatto fix several CVEs, and expressed interest in automating CVE triage. - Igor Bispo introduced themselves as the upstream author of ParrotIA, seeking a sponsor to package it and its Python dependencies for Fedora.
All contribution opportunities
Developers and scripters can tackle a variety of language-specific and system-level challenges across the project. Rust developers are needed to port packages to quick-xml v0.41 and address CVE-2026-119375 in statically linked SQLite packages. Ruby developers can help fix FTBFS issues for rubygem-mysql2 and migrate rubygem-ruby-libvirt to the TypedData API, while Perl experts can resolve an i686 build failure for perl-Algorithm-BloomFilter. Web and scripting contributors can resolve a @comark/nuxt module deprecation, fix failing automated actions in the design repository, or update the docsbuilder.sh script to the new Forge format. Additionally, system-level programmers can assist with a dnf5daemon-server bug or provide patches for a GDM fingerprint login issue.
For those with RPM packaging experience, there are numerous opportunities to review new submissions or adopt orphaned software. Contributors can provide package reviews for agent-skills, rubygem-net-pop, or ParrotIA and its dependencies. Experienced packagers can also adopt orphaned packages like xorg-x11-drv-amdgpu and portmidi, take over a stalled EPEL 10 request for gparted, or help bring mailman3 to EPEL 10 to assist Release Engineering.
Quality assurance and infrastructure enthusiasts are highly encouraged to participate in testing and system maintenance. Testers can join the KDE Plasma 6.8 Test Days, evaluate an unofficial Plasma 6.8.3 COPR, or provide karma for a ROCm upgrade fix. OpenQA experts are needed to investigate a Tux Racer navigation test failure. On the infrastructure side, beginners can learn Ansible by configuring ELN Monitoring for Matrix, while those interested in Zabbix can help refactor external HTTP checks. Contributors with image-building experience can also assist the Server team in updating kiwi definitions to switch the SBC image to GPT/EFI.
Finally, non-code contributions are vital for documentation, design, and community growth. Graphic designers can create a print-ready PDF for a "Fedora loves GNOME" sticker or design a landing page for Fedora Remix. Writers can draft a migration proposal for Fedora Magazine, write a post-installation guide for Strengthening Server Updates, or update legacy syntax in Quick Docs. Community veterans can also provide mentorship by guiding newcomers like Fardeen Khan and Lutz Weber, or by helping Julita Inca get started with Ansible testing.
16 Nov 2026 9:51am GMT
Fedora Magazine: Dictate into any app on Fedora with TuxTalk
TuxTalk is a free voice dictation tool for Linux. You hold a key, talk, and let go. What you say appears wherever your cursor is located: a document, an email, a chat box or a terminal. The speech model runs on your own computer, so your voice never leaves it and there is no account to create. This is provided under the MIT license and the code is on GitHub.
This article walks through installing it on Fedora Workstation or Fedora KDE Plasma Desktop, what the first run changes on your system and why, using it day to day, and removing it if you wish.
Before you start
You need a working microphone and a 64-bit Fedora install on x86_64. No graphics card is required. The default speech model is fast on an ordinary processor, and if you have an NVIDIA, AMD or Intel graphics chip, TuxTalk can use it through Vulkan.
TuxTalk isn't in the Fedora repositories and there's no Copr build. You install the RPM from the project's GitHub releases page and check it against the checksum file published with it.
Install the RPM
Download both tuxtalk-0.23.1-1.x86_64.rpm and SHA256SUMS.txt from the latest release at https://github.com/ronb1964/TuxTalk/releases into the same folder. Then check the RPM against the checksum file:
$ cd ~/Downloads
$ sha256sum -c --ignore-missing SHA256SUMS.txt
tuxtalk-0.23.1-1.x86_64.rpm: OK
If it says anything other than OK, delete the file and download it again. Then install it with dnf, which also pulls in the few system libraries it needs:
$ sudo dnf install ./tuxtalk-0.23.1-1.x86_64.rpm
dnf warns that it skipped the OpenPGP check for the package. This is because the RPM isn't signed with a key and why the checksum step, indicated above, matters.
The package installs into /opt/talktype (the folder kept the app's old name so upgrades replace files in place), adds a tuxtalk command, and puts TuxTalk in your applications menu.
Installing on Atomic Desktops
For Silverblue and the other Fedora Atomic desktops, download the AppImage from the same release page indicated above (see the Assets section). Make it executable and run it:
$ chmod +x TuxTalk-v0.23.1-x86_64.AppImage
$ ./TuxTalk-v0.23.1-x86_64.AppImage
What the first run changes
Start TuxTalk from your applications menu. The first-run screen looks at your graphics card and your language and recommends a setup. The default is NVIDIA's Parakeet model, which covers English and 24 other European languages. If you need another language, OpenAI's Whisper covers 99 of them. Either one downloads once and then works offline.

The first run also asks for your admin password once, to set up two things:
- The hotkey helper. On Wayland an ordinary program cannot detect keys pressed in other windows, so TuxTalk needs help to notice F8. A small helper program runs as a systemd service, tuxtalk-hotkeys, and it's the only part of TuxTalk that reads the keyboard. It doesn't run as root. It runs as a throwaway user (systemd's DynamicUser) whose only extra right is the input group, with no network, no access to home folders, a read-only system and no way to gain more privileges. It only reports hotkeys, never what you type: F-keys and the few other keys that never type anything, Right Ctrl or Right Alt on their own, or a key held together with two of Ctrl, Alt and Super. Letters, numbers and Enter are never reported. And it only reports them to the user who's at the screen. The file it runs sits in a root-owned folder, /usr/local/libexec/tuxtalk, so nothing you run as yourself can change it.
- A udev rule that gives /dev/uinput to the user at the screen, the same way Steam's rule does for game controllers. TuxTalk uses it to type, through its own virtual keyboard. A program can press keys with /dev/uinput, but it can't read them.
A restart is not needed. You can look at the helper yourself:
$ systemctl status tuxtalk-hotkeys
$ systemd-analyze security tuxtalk-hotkeys
The second command rates it 0.6, "SAFE".
On Fedora Workstation, TuxTalk also offers to install its GNOME Shell extension, which puts its menu in the top bar. GNOME only loads a new extension after you log out and back in once. On KDE Plasma it shows a tray icon instead.
Dictate
Click where you want the text to go, hold F8, say what you want, and let go. A moment later the text appears. If you'd rather not hold a key for a long dictation, tap F9 to start and tap it again to stop.
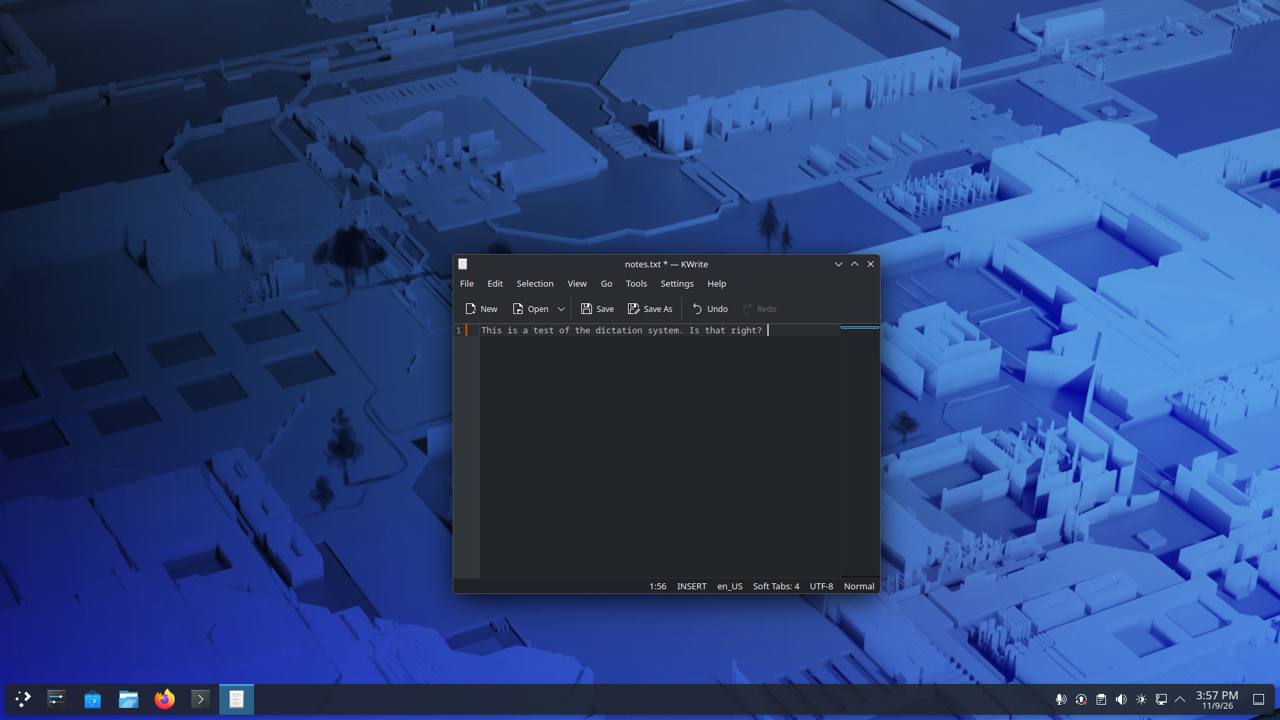
A few things that make it more useful:
- Say punctuation and it appears: "comma", "period", "question mark", "new paragraph".
- Say an email address the way you'd say it out loud. "john at gmail dot com" comes out as john@gmail.com.
- In a terminal it leaves off the capital letter and the period, so a dictated command is ready to run.
- Names and terms it keeps getting wrong go in Your Words in Preferences, spelled your way. Or say "fix that word" right after a dictation.
- For hands-free use, turn on the double-tap option under Preferences → General. Then double-tap F9, talk as long as you like, and it stops by itself when you stop talking.
If your F-keys need the Fn key, Preferences → General also offers Right Ctrl, Right Alt, Scroll Lock or Left Ctrl+Space.
There's more in TuxTalk Labs under Preferences → Advanced. Each feature in this menu is off until you turn it on. The newest feature is running the desktop by voice: opening apps, snapping windows, and a numbered mouse grid you can click with by voice.
Remove TuxTalk
Open Preferences, go to Updates & Backup and click Uninstall TuxTalk…. It asks for your password once and removes everything it set up: the program, the hotkey helper, the udev rule, the downloaded models and the GNOME extension. Your settings are retained unless you tick the box to delete them as well. If TuxTalk won't open, the same thing can run from a terminal:
$ tuxtalk --uninstall
Removing only the package with sudo dnf remove tuxtalk takes the hotkey helper with it, but leaves your settings and the downloaded models in your home folder.
Feedback
TuxTalk is a hobby project, and it gets better when people tell me what doesn't work for them. Questions, problems and ideas are welcome in the Discussion section in the GitHub project at: https://github.com/ronb1964/TuxTalk/discussions
A note on how this was made:
I can't write code. TuxTalk is written by Claude, Anthropic's AI, and I test it and use it every day. I do my best to make sure the code is held to a standard a human developer can respect. Claude also helped me draft this article. I went through it and changed it to sound more like me, and I've checked every step in it. (Assisted-by: Claude)
16 Nov 2026 8:00am GMT
Fedora Badges: New badge: F50 i18n Test Day Participant !
16 Nov 2026 7:52am GMT
Fedora Badges: New badge: F49 i18n Test Day Participant !
16 Nov 2026 7:51am GMT
Fedora Badges: New badge: F48 i18n Test Day Participant !
16 Nov 2026 7:50am GMT
Fedora Badges: New badge: F47 i18n Test Day Participant !
16 Nov 2026 7:50am GMT
Fedora Badges: New badge: F46 i18n Test Day Participant !
16 Nov 2026 7:49am GMT
Fedora Badges: New badge: Fedora 50 CoreOS Test Day !
16 Nov 2026 6:38am GMT
Fedora Badges: New badge: Fedora 49 CoreOS Test Day !
16 Nov 2026 6:38am GMT