26 Oct 2026
 Planet Lisp
TurtleWare: Heavenly delights of hashing numbers under EQUALP
Table of Contents
Some time ago I decided to dust off my fast generic function dispatch work for ECL. But before merging that, I decided to optimize the table-based dispatch to have a good measure of how much better or worse it is and that opened a whole can of worms, including a new implementation of hash tables and hash functions.
I know, that's a new level of traversing absurdly nested rabbit holes. There are two good outcomes of this:
- Hash tables and generic function dispatch will be much faster soon
- I got inspired to write another blog post pertaining to Common Lisp
Regarding the first point, here are a few bar graphs generated using polyclot, a work-in-progress McCLIM tool for plotting data (less is better):
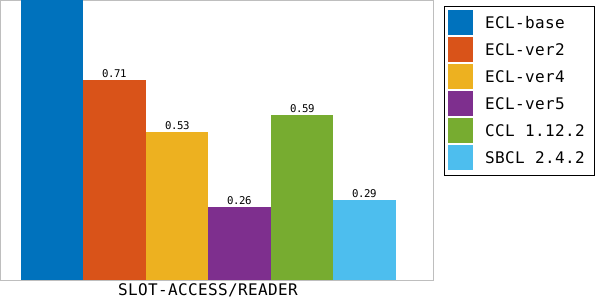
Figure 1: SLOT-ACCESS/READER - standard reader benchmark (work in progress).
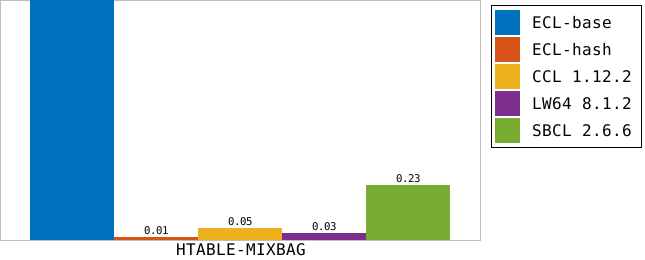
Figure 2: HTABLE-MIXBAG - EQUALP benchmark with randomized keys.
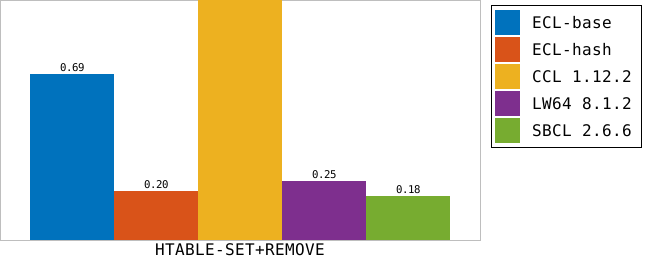
Figure 3: HTABLE-SETREM - benchmark for interleaved insert and remove.
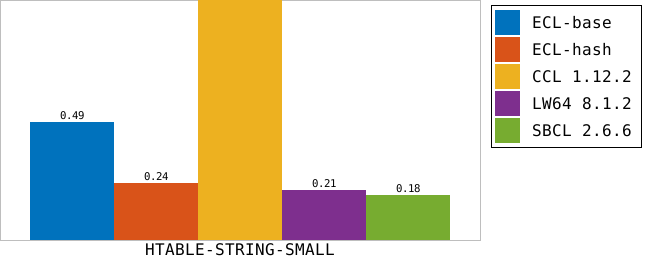
Figure 4: HTABLE-SMALL-STRING - EQUALP benchmark with short strings.
As for the second point, while working on hashing under various Common Lisp predicates, I decided to bite the bullet and fix a few ugly parts of ECL. Most notably consistent hashing of numbers under the predicate #'EQUALP. The topic is interesting enough to deserve a separate note. In this post I'm assuming binary floats (the float radix is two). This is the float representation used in ECL.
1. Hashing numbers - warmup
1.1. Recap: hash table tests and hash functions
A quick recap about Common Lisp and hash tables. The standard prescribes that conforming implementations must allow specifying the hash table tests EQ, EQL, EQUAL and EQUALP. The last test is interesting, because numbers with different representations are considered to be EQUALP when they are =. For example:
(equalp 1 1.0)           ; -> T
(equalp 1/2 0.5)         ; -> T
(equalp 1/3 (float 1/3)) ; -> NIL
(equalp 42 #C(42.0 0.0)) ; -> T
It is worth noting, that hashing can be lossy, but it can't be inconsistent with the test. In other words this is a conforming hash function under #'EQUALP:
;; (equalp 1 1.0)                        ; is true
;; (= (hash-equalp 1) (hash-equalp 1.0)) ; is true

(defun hash-equalp (x)
  (typecase x
    (real      42)
    (complex   (if (zerop (imagpart x))
                   (hash-equalp (realpart x))
                   13))
    (otherwise 15)))
While this function is not conforming, because there are objects that are the same under the test and have different hashes:
;; (equalp 1 1.0)                        ; is true
;; (= (hash-equalp 1) (hash-equalp 1.0)) ; is false

(defun hash-equalp (x)
  (typecase x
    (rational  1337)
    (float     7117)
    (complex   (if (zerop (imagpart x))
                   (hash-equalp (realpart x))
                   13))
    (otherwise 15)))
In other words, when two objects are equal under the supplied test, they must produce the same hash, but two objects having the same hash does not imply that they are equal under the supplied test.
Naive hashes, while conforming, miss the point. A good hashing function tries to produce different hashes for objects that are not equivalent under the predicate with a good bit distribution to ensure good hash table performance.
1.2. Recap: the numeric tower and mathematical equivalence
Common Lisp has a full numeric tower:
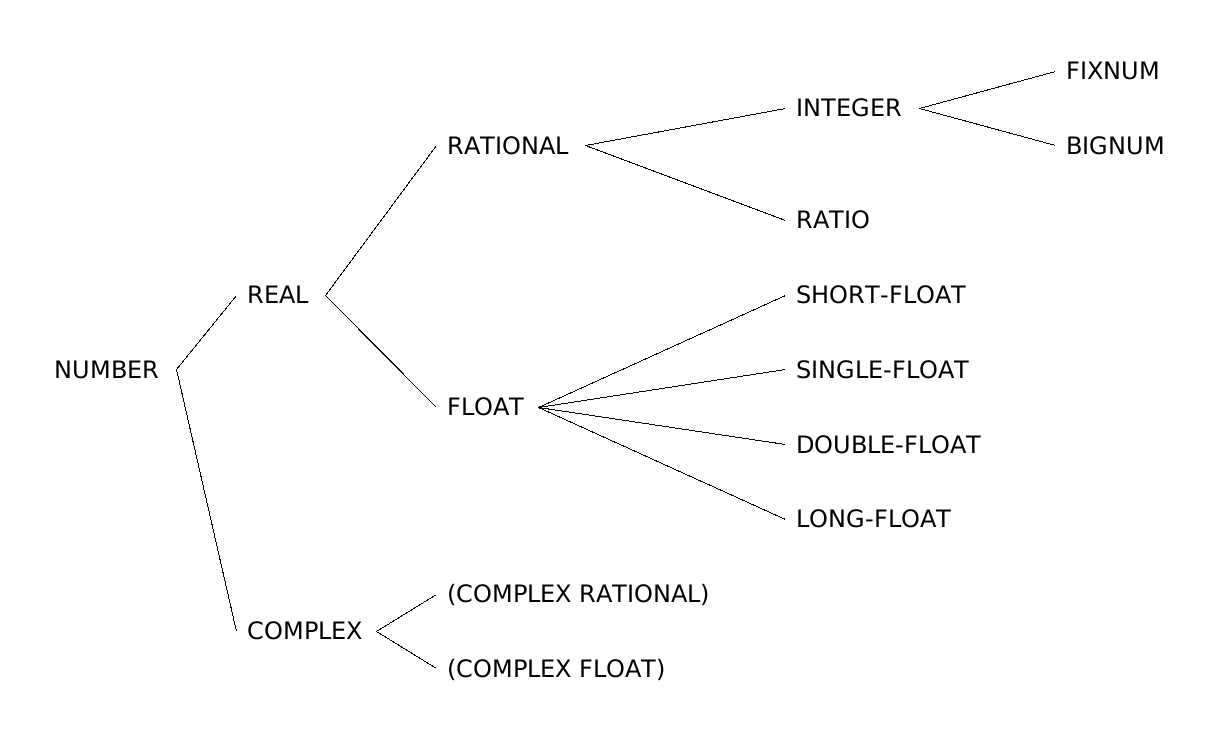
Figure 5: Common Lisp numeric tower.
Note that when complex floats have specialized representation, then there may be multiple subtypes specialized to single-float, double-float etc. Numbers are #'= to each other when their value is mathematically the same, regardless of the underlying representation. That's a wonderful quality when you do math :-).
This quality is not so wonderful, when you want to produce good hashes under the predicate #'EQUALP (that boils down to #'= for numbers). We need to construct a function that will produce the same hashes with good quality for equal objects.
The biggest hurdle comes from the gap between representations of RATIONAL and FLOAT objects. Conventionally representations are
- fixnum
- a single word with a few bits chopped to fit the tag
- bignum
- an array of "limbs", that is parts of the integer (plus sign)
- ratio
- a pair of two integers
- float
- a pair of N-bit mantissa and K-bit exponent (plus sign)
- (complex rational)
- a pair of two rationals
- (complex float)
- a pair of two floats of the same type
Fixnums, bignums and ratios are disjoint under #'=. That leaves us with questions:
-
When are two complex numbers mathematically equal?
This one is easy. Two complex numbers are equal when their real parts are equal and their imaginary parts are equal.
-
When are two floats mathematically equal?
To resolve this question we can cast the float with smaller precision to the float with bigger one and compare bits. There is a gotcha in that -0.0 is not EQL to +0.0, but it is always = to it, so we should canonicalize zeros first.
-
When is an integer mathematically equal to a float?
When the float has no fractional part and integers are equal.
-
When is a ratio equal by #'= to a float?
This is the most interesting question. To answer it, we need to dive a bit deeper into float representation.
Finite binary float values conceptually are represented as:
(* sign mantissa (expt 2 exponent))This corresponds to dyadic rationals, that is rational numbers whose denominator is a power of two:
(/ n (expt 2 k))In other words a float and a ratio may be equal only when the ratio is dyadic, otherwise the ratio value can't be represented as a binary float (this post assumes that we operate on binary floats - with radix=2).
That sums up the recap about mathematical equivalence and numeric tower in Common Lisp.
1.3. Establishing the baseline
The easiest, yet useless, approach is to always return a hash 42. It is adequate because that is the canonical answer to the most important question.
The easy and useful approach relies on the observation that hashing is lossy. All real numbers are coerced to a float precision and hashed. When the rational number does not fit in the float precision, then we hash its approximation. We need to remember to canonicalize -0.0 to +0.0 and to disable floating point exceptions for cases like overflows and underflows.
#define hash_single_float(h,v) hash_float((h), (double)(v))
#define hash_double_float(h,v) hash_float((h), (double)(v))

static inline void
hash_float(cl_hashstate *h, double v)
{
  if (v==-0.0) v=0.0;
  hash_data(h, &v, sizeof(v));
}

static inline void
hash_long_float(cl_hashstate *h, long double v)
{
  ECL_WITHOUT_FPE_BEGIN {
    hash_float(h, (double)(v));
  } ECL_WITHOUT_FPE_END;
}

#define hash_fixnum(h,x) hash_float((h),(double)ecl_fixnum(x))
#define hash_bignum(h,x) hash_rational((h),(x))
#define hash_ratio(h,x)  hash_rational((h),(x))

static inline void
hash_rational(cl_hashstate *h, cl_object x)
{
  ECL_WITHOUT_FPE_BEGIN {
    double v = ecl_to_double(x);
    hash_float(h, v);
  } ECL_WITHOUT_FPE_END;
}
This model is conceptually obvious, very maintainable, reasonably fast, and there are relatively few collisions under the usual workload. We pay for it in a few ways:
- Aesthetically it is not pleasing - crude even.
- "Relatively few collisions" applies only to toy examples, once we start using bigger integers and more precise ratios, the problem starts to show. For example 260 and 260+1 hash identically and that matters for 64bit IDs and timestamps.
- Performance-wise we drop the ball for integers and rationals - we convert numbers between formats even when we could hash only a chunk of memory.
This list is ranked by importance as I see it. The main reason I've kept digging deeper is that it was not to my taste. Then we had impracticality for serious workloads, finally microoptimizations. I believe that the general audience has these priorities in a reversed order.
2. Hashing numbers - round one
A harder but more precise way to hash numbers under the predicate #'EQUALP is to introduce canonicalization rules:
-
Integers are hashed as integers
In the case of FIXNUM we hash its value (a word without the tag) and in the case of BIGNUM we hash the sign and its limbs.
-
Finite floats without the fractional part are hashed as integers
Ensures INTEGER <-> FLOAT correspondence. We can't cast LONG-FLOAT to DOUBLE-FLOAT and then cast to integer, because we'd miss many BIGNUM values. Caveat: with this approach big floats may cons full bignums.
-
Floats that are not integers are cast to DOUBLE-FLOAT and hashed
Ensures X-FLOAT <-> Y-FLOAT correspondence. This approach is lossy for long floats if they have more bits than double floats, but simplifies the implementations because long double has a few "loose" bits that may differ between numbers with the same value.
NaNs and infinities are hashed like other doubles because infinities are exact and NaN is never #'= to anything.
-
Dyadic ratios are hashed as DOUBLE-FLOAT
Ensures FLOAT <-> RATIO correspondence. For simplicity we don't try to determine whether RATIO is representable as DOUBLE-FLOAT - if it is too big or too small, it will be represented either as a 0 or as an infinity.
-
Other ratios are hashed as pairs
We hash the numerator and denominator separately.
-
Complex floats with
(ZEROP (IMAGPART X))are hashed as(HASH (REALPART X))Because
(= 3 #c(3.0 0.0))we need to canonicalize(complex float)while rational complex numbers are canonicalized implicitly. Other complexes are hashed as pairs, that is we hash the real part and imaginary part separately.
This approach results in fewer collisions and is fairly straightforward. Here is the pseudocode:
(defun hash-equalp-number (state number)
  (typecase number
    (fixnum  (hash-word state number))
    (bignum  (hash-data state (signum number) (limbs number)))
    (float   (if (and (finitep number) (is-integer-p number))
                 (hash-equalp-number state (rational number))
                 ;; INV -0.0 and +0.0 are hashed as integers.
                 (hash-data state (coerce number 'double-float))))
    (ratio   (if (dyadic-ratio-p number)
                 ;; INV may produce infinity or zero (that's fine)
                 ;; Disable float overflow and underflow traps.
                 (hash-data state (coerce number 'double-float))
                 (progn
                   (hash-equalp-number state (numerator number))
                   (hash-equalp-number state (denominator number)))))
    (complex (if (zerop (imagpart number))
                 (hash-equalp-number state (realpart number))
                 (progn
                   (hash-equalp-number state (realpart number))
                   (hash-equalp-number state (imagpart number)))))))
2.1. Implementation bites
My initial implementation cast all floats to integers. When I was comparing ECL to other implementations I was wondering why we are so slow compared to others. The key insight came after the realization that randomized keys in the form (random 20.0) were collapsed to only 20 distinct hashes.
Fixing that and giving non-integer floats distinct hashes gave ECL the most noticeable boost on the HTABLE-MIXBAG benchmark (included at the beginning) - the new version is 100x faster than the old one.
While implementing a test suite that ensured that hashes for bignums, dyadic ratios, and corresponding floats matched, I've discovered a non-obvious bug pertaining to casting double floats to integers. The code looked like this:
if (d<=MOST_POSITIVE_FIXNUM && d>=MOST_NEGATIVE_FIXNUM) return to_fixnum(d);
else                                                    return to_bignum(d);
But the MOST_POSITIVE_FIXNUM value on x86-64 is 261-1. In other words, to represent this number exactly as a double, we need 61 significant bits. That's a shame because double has 53 significant bits, so MOST_POSITIVE_FIXNUM, when converted to double, rounds to 261 and that can't fit in a fixnum. After promotion the incorrect code is equivalent to:
if (d<=(1LL<<61) && d>=MOST_NEGATIVE_FIXNUM) return to_fixnum(d);
else                                         return to_bignum(d);
Oops, double is accidentally cast to fixnum when it is 261. That's clearly a problem! After finding the issue, the solution is easy. We need to find an exact double that is the boundary. Note that integers are implemented as two's complement, so the most negative fixnum was alright in our case:
double limit = ldexp(1.0, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
if (d<limit && d>=-limit) return to_fixnum(d);
else                      return to_bignum(d);
This fix is correct, yet it revealed another bug. But that's a different story to tell.
3. Hashing numbers - round two
The approach above is correct and nice, but has a few important flaws:
- we cons a lot for big integer floats (2KB/float in the worst case)
- there is a whole class of dyadic ratios that don't fit in long-float
- long floats lose precision after cast to double, notably very small and very big values collapse to 0 and infinity
After the initial implementation it bugged me enough that I've decided to come up with a new hashing scheme for numbers under the predicate EQUALP. The rules are also simpler (at least conceptually):
- Dyadic rationals are hashed as tuples (sign, mantissa, exponent)
- Other numbers are hashed depending on their type (they are disjoint)
The representation [SIGN MANTISSA EXPONENT] does not require us to convert between types and it is very compact. Moreover it is very precise and doesn't produce unnecessary collisions. On the other hand it requires extra work to normalize tuples. Here is the pseudocode:
(defun hash-equalp-number (state number)
  (typecase number
    (integer
     (multiple-value-bind (s m e) (compute-integer-dyad number)
       (hash-dyad state s m e)))
    (float
     (multiple-value-bind (s m e) (compute-float-dyad number)
       (hash-dyad state s m e)))
    (ratio
     (if (dyadic-ratio-p number)
         (multiple-value-bind (s m e) (compute-ratio-dyad number)
           (hash-dyad state s m e))
         (progn
           (hash-datatype-tag state :ratio)
           (hash-equalp-number state (numerator number))
           (hash-equalp-number state (denominator number)))))
    (complex
     (if (zerop (imagpart number))
         (hash-equalp-number state (realpart number))
         (progn
           (hash-datatype-tag state :complex)
           (hash-equalp-number state (realpart number))
           (hash-equalp-number state (imagpart number)))))))
The implementation is a bit less straightforward because we now need to be able to compute mantissa from numbers. A few words about normalization:
- sign is -1, 0 or +1 for finite numbers - that solves normalization of -0.0/+0.0
- mantissa must be a positive odd integer or zero - that unifies all mantissas
- exponent is also an integer, so the number is (* sign mantissa (expt 2 exp))
- to hash unique values (like infinities) we will abuse sign to fit extra values
Every integer is a dyadic rational, so our task is to normalize it so that the mantissa is an odd number and adjust the exponent accordingly.
(defun compute-integer-dyad (number &optional (exp 0))
  (when (zerop number)
    (return-from compute-integer-dyad
      (values 0 0 0)))
  ;; In the real code use COUNT-TRAILING-ZEROS + ASH.
  ;; Loop division is to make the mechanism clear.
  (do ((sign (signum number))
       (mantissa (abs number) (ash mantissa -1))
       (exponent exp (1+ exponent)))
      ((oddp mantissa)
       (values sign mantissa exponent))))
The implementation for float is also straightforward thanks to the function INTEGER-DECODE-FLOAT. We also need to normalize the signed zero:
(defun compute-float-dyad (number)
  (cond ((nan-p number)
         (return-from compute-float-dyad
           (values -2 0 0)))
        ((negative-infinity-p number)
         (return-from compute-float-dyad
           (values -3 0 0)))
        ((positive-infinity-p number)
         (return-from compute-float-dyad
           (values +3 0 0))))
  (multiple-value-bind (mantissa exponent sign)
      (integer-decode-float number)
    (compute-integer-dyad (* sign mantissa) exponent)))
For ratios we will reuse the function that we have not defined in the last section to decide whether the ratio is dyadic and if it is - convert it to the canonical form:
(defun dyadic-ratio-p (number)
  ;; A positive integer is a power of 2 only when exactly one bit is set.
  (= 1 (logcount (denominator number))))

(defun compute-ratio-dyad (number)
  (values (signum number)
          ;; Ratios are already normalized(!)
          (abs (numerator number))
          ;; den = 2^k, shift = k+1 -> exponent = -k
          (- (1- (integer-length (denominator number))))))
Mind that the functions above are deliberately simple to illustrate how they should work. We have also used non-standard functions NAN-P and INFINITY-P that depend on the implementations extensions (or internals).
This is the most satisfying moment in the post - we have found an elegant and universal (in this domain) abstraction that avoids float-to-bignum conversion, hashes unequal numbers differently, and is easy to understand. That's the high point of this post and the reason I've dubbed it "heavenly delights". Alas, it is time to come back to earth and improve its performance. That's where the engineering lives.
3.1. Back to earth
We have an elegant conceptual model. The thing with elegant conceptual models is that they need to be dirtied to make them fast. And that's what we are going to do now: we will bastardize the clean abstraction and make it performant under usual scenarios without sacrificing precision. We are now optimizing.
Simplifications that we can climb down to from our normalized representation [sign, mantissa, exponent] model:
-
When mantissa or exponent exceeds LONG-FLOAT precision, don't normalize the number
As noted earlier, aside from floats, numbers in Common Lisp are disjoint, for example, there are no integers and ratios that are EQUALP to each other. In that case we use the most convenient hashing scheme for the specified type.
-
Dyads representable as fixnums are hashed as a fixnum (a signed integer)
This is an opportunistic optimization tailored for quick fixnum hashing. We already know how to correctly determine when a float can be reliably cast to fixnum and other numbers don't intersect with fixnums.
-
Dyadic ratios in range are cast to
long doubleand hashed as LONG-FLOATThis way we ensure that ratios and floats that are #'= are hashed the same. This is similar to "Round one" approach, but we retain the maximal precision.
-
Integer floats and bignums in range are hashed in a dyadic form
This step allows us to avoid coercing floats to bignums and is a big memory allocation save. A small cost for bignums is that we need to decide before hashing whether it is in the LONG-FLOAT precision range.
-
Long floats exceeding double float precision are hashed in a dyadic form
By avoiding lossy casts to double, we reduce number of collisions. Most notably, very small and very big values are not collapsed to zero and infinity. Such floats are hashed in a dyadic form because x87 floats have additional padding bits that may differ between equal values, so we can't hash memory.
Another minor optimization: we fold the sign and the exponent into a single word to have fewer hash state updates as 8*exponent+sign (sign has maximum 2 bits).
Notice that this scheme is very similar to the "Round one" approach. In practice it only differs in how we treat floats, bignums and ratios:
| object | round 1 | current variant | note |
|---|---|---|---|
integer float |
fixnum or bignum |
fixnum or tuple |
depends on range |
fractional float |
dfloat |
dfloat or lfloat |
depends on precision |
dyadic-ratio |
dfloat |
dfloat or lfloat |
depends on precision |
fixnum |
fixnum |
fixnum |
no change |
bignum |
bignum |
bignum or tuple |
depends on precision |
A few concrete examples should illustrate these simplifications. They do not try to test precise limits and the set is not exhaustive.
I'm assuming that FIXNUM has 62 bits and LONG-FLOAT has 64-bit mantissa, 15-bit exponent and 1-bit for sign - typical on x86 with GCC.
| ## | dyadic number | canonical representation | cast | note |
|---|---|---|---|---|
| 0. | (/ 1 (expt 2 (expt 2 15))) |
(1 1 -32768) |
ratio |
too small |
| 1. | (/ 1 (expt 2 (expt 2 11))) |
(1 1 -2048) |
lfloat |
|
| 2. | 3/8 |
(1 3 -3) |
dfloat |
|
| 3. | 42 |
(1 21 1) |
fixnum |
|
| 4. | most-positive-fixnum |
(1 most-positive-fixnum 0) |
fixnum |
|
| 5. | most-negative-fixnum |
(-1 1 61) |
fixnum |
|
| 6. | (1+ most-positive-fixnum) |
(1 1 61) |
dyadic |
|
| 7. | (1- most-negative-fixnum) |
(-1 2305843009213693953 0) |
dyadic |
|
| 8. | (expt 2 32768) |
(1 1 32768) |
bignum |
|
| 9. | (/ (1+ (expt 2 40)) 2) |
(1 (1+ (expt 2 40)) -1) |
dfloat |
|
| a. | (/ (1+ (expt 2 53)) 2) |
(1 (1+ (expt 2 53)) -1) |
lfloat |
|
| b. | (/ (1+ (expt 2 64)) 2) |
(1 (1+ (expt 2 64)) -1) |
ratio |
too big |
| c. | 13.0 |
(1 13 0) |
fixnum |
|
| d. | (expt 2.0 61) |
(1 1 61) |
dyadic |
|
| e. | (expt 2.0l0 16383) |
(1 1 16383) |
dyadic |
|
| f. | (expt 2.0l0 16384) |
(3 0 0) |
dfloat |
infinity |
- case 0
- the number underflows long-float exponent precision
- case 1
- the number is representable as LONG-FLOAT but not as DOUBLE-FLOAT
- case a
- the number is representable as LONG-FLOAT but not as DOUBLE-FLOAT
- case b
- the number overflows LONG-FLOAT mantissa precision
- case e
- the number narrowly fits in LONG-FLOAT
- case f
- the number overflows LONG-FLOAT (infinity) - may signal a condition
Illustrative pseudocode:
;;; There is something to be said about conventions. Our dyadic representation
;;; treats the mantissa as an odd integer, but the C representation of floats
;;; treats the mantissa as a fraction [0.5, 1.0). In practice this means that
;;; exponents in our canonical representation must be recalculated, because:
;;;
;;;   our-mantissa === (shift-to-odd (ash float-mantissa +ldbl-mant-dig+))
;;;   our-min-exp  === (- +ldbl-min-exp+ +ldbl-mant-dig+)
;;;   our-max-exp  === (- +ldbl-max-exp+ (integer-length our-mantissa))
;;;
;;; Note that FLOAT-MANTISSA assumes a fraction, but in practice we can usually
;;; extract bits directly and skip the shift by interpreting it as significand.
(defun hash-dyadic-number (state number)
  (multiple-value-bind (sign mantissa exponent)
      (dyadic-representation number)
    (let* ((num-len (integer-length mantissa))
           (min-exp (- +ldbl-min-exp+ +ldbl-mant-dig+))
           (max-exp (- +ldbl-max-exp+ num-len)))
      (if (and (<= num-len +ldbl-mant-dig+)
               (<= min-exp exponent max-exp))
          (hash-dyad state sign mantissa exponent)
          (hash-type state number)))))
3.2. Gravel details
Without further ado, let's dig into the actual implementation. I'm going to show only relevant parts of C code for brevity. If you are not interested in C code and microoptimizations, then just skip this section and move to benchmarks. Here is a TL;DR table (complexes are normalized and each part is hashed with a tag):
| type | hash as | why? |
|---|---|---|
fixnum |
fixnum |
performance |
bignum |
bignum / dyadic |
performance / equivalence (lfloat/dfloat) |
ratio |
ratio / lfloat |
performance / equivalence (lfloat/dfloat) |
dfloat |
fixnum / dyadic / dfloat |
performance / equivalence / performance |
lfloat |
dfloat / fixnum / dyadic |
performance / performance / correctness |
In two places we will hash integers that may be either fixnums or bignums:
- the mantissa in a dyadic form (long double mantissa is 64bit on x86-64)
- a ratio's numerator and denominator when the ratio is not a dyadic number
Hashing them is straightforward. Note that hashing the fixnum is always cheap - we hash a single word.
static inline void
hash_fixnum_data(cl_hashstate *h, cl_object x) {
  hash_word(h, ecl_fixnum(x));
}

#define hash_fixnum(h,x) hash_fixnum_data(h,x)

static inline void
hash_bignum_data(cl_hashstate *h, cl_object x) {
  hash_word(h, ecl_bigsgn(x));
  hash_data(h,
            ECL_BIGNUM_LIMBS(x),
            ECL_BIGNUM_USIZE(x) * sizeof(ecl_limb_t));
}

static void
hash_integer(cl_hashstate *h, cl_object x)
{
  if (ECL_FIXNUMP(x)) {
    hash_fixnum_data(h, x);
  } else {
    hash_bignum_data(h, x);
  }
}
Previously we were concerned with consing. This is why we go an extra mile to not allocate bignums unnecessarily when we hash a bignum in a dyadic form. We operate on a scratch register that is a thread-local variable in ECL when we extract a mantissa:
static inline void
hash_and_free_bignum_register(cl_hashstate *h, cl_object mantissa) {
  /* INV this function assumes that mantissa is already positive. The bignum may
     not be normalized to fixnum. We free the register after hashing. */
  if (ECL_BIGNUM_SIZE(mantissa) == 1) {
    ecl_limb_t y = ECL_BIGNUM_LIMBS(mantissa)[0];
    if (y <= MOST_POSITIVE_FIXNUM) {
      hash_word(h, y);
      goto DONE;
    }
  }
  hash_bignum_data(h, mantissa);
 DONE:
  _ecl_big_register_free(mantissa);
}

/* When hashing bignums we see whether they fit in LONG-FLOAT and only then we
   cast it to a dyadic form. Otherwise we directly hash limbs. */
static void
hash_bignum(cl_hashstate *h, cl_object x) {
  cl_fixnum length = _ecl_big_integer_length(x);
  cl_fixnum exponent = _ecl_big_ctz(x);
  if (length-exponent<=LDBL_MANT_DIG && length<=LDBL_MAX_EXP) {
    /* To avoid allocating fresh bignums by ABS and ASH we opencode this:
       cl_object mantissa = ecl_ash(ecl_abs(x), -exponent); */
    cl_object reg = _ecl_big_register2();
    cl_fixnum signum = ecl_bigsgn(x);
    if (signum<0) {
      _ecl_big_neg(reg, x);
      _ecl_big_div_2exp(reg, reg, exponent);
    }
    else {
      _ecl_big_div_2exp(reg, x, exponent);
    }
    hash_word(h, 8*exponent+signum);
    hash_and_free_bignum_register(h, reg);
  } else {
    hash_bignum_data(h, x);
  }
}
Hashing a ratio is also plain. When the ratio is dyadic and its precision does not exceed long double then we coerce it to that type and hash it. Otherwise we add the tag and hash both integers. We are careful to not allocate memory.
static void
hash_ratio(cl_hashstate *h, cl_object x) {
  /* When the ratio is dyadic and within long-float precision, then we cast it
     to long double for consistent hashes. Otherwise we hash ratio as is. */
  cl_object num = ecl_ratio_num(x);
  cl_object den = ecl_ratio_den(x);
  /* Ratio is dyadic when denominator is a power of two. To avoid bignum
     arithmetic we provide an optimized path for each subtype of integer.
     ecl_zerop(ecl_boole(ECL_BOOLAND, den, ecl_one_minus(den))); */
  bool dyadic_p;
  if (ECL_FIXNUMP(den)) {
    /* Denominator is always positive, so fixnump(x) -> fixnump(x-1) */
    cl_fixnum dfix = ecl_fixnum(den);
    dyadic_p = !(dfix & (dfix-1));
  } else {
    /* When bignum is a pow2, then integer_length == ctz+1 or (popcount==1) */
    dyadic_p = ((_ecl_big_ctz(den)+1) == _ecl_big_integer_length(den));
  }
  if (dyadic_p) {
    /* Normally we would call here
       cl_fixnum length = ecl_integer_length(ecl_abs(num));

       But! Numerator is normalized to an odd integer because denominator is a
       power of two. INTEGER-LENGTH returns different values for X and -X only
       when X is a power of two, and the only odd power of two is X=1.

       (INTEGER-LENGTH -1) == 0 and 0 <= LDBL_MANT_DIG
       (INTEGER-LENGTH +1) == 1 and 1 <= LDBL_MANT_DIG

       This is why we don't need to call ABS on the numerator. QED. */
    cl_fixnum length = (ECL_FIXNUMP(num)
                        ? ecl_integer_length(num)
                        : _ecl_big_integer_length(num));
    cl_fixnum exponent = -(ecl_integer_length(den)-1);
    if (length <= LDBL_MANT_DIG && exponent >= LDBL_MIN_EXP-LDBL_MANT_DIG) {
      /* Generic way to do this is: hash_long_float(h, ecl_to_long_double(x));
         that path recomputes mantissa and exponent from ratio using a generic
         arithmetic. We already have everything ready. */
      long double value = (ECL_FIXNUMP(num)
                           ? ecl_fixnum(num)
                           : _ecl_big_get_lf(num));
      value = ldexpl(value, exponent);
      hash_long_float(h, value);
      return;
    }
  }
  /* Fall-through. */
  hash_word(h, t_ratio);
  hash_integer(h, num);
  hash_integer(h, den);
}
Hashing floats is the most demanding part in this program:
- DOUBLE-FLOAT: the first branch ensures the same hashes for fixnums, bignums, and integer float types, while the second branch ensures the same hashes for ratios and fractional float types.
- LONG-FLOAT: the first branch checks whether we can cast to double without losing precision. The second branch ensures same hashes for fixnums. The third branch unconditionally hashes the value in a dyadic form.
Initially I've introduced functions decode_lf and decode_df that extracted mantissa and exponent from the number, but benchmarks showed that these small allocations dominate both time and consing for relevant profiles. This is why I've fused decoding and hashing and operate on a preallocated register. That's the difference between coming up first and coming up third on the benchmark.
Decoding and hashing double and long double in a dyadic form are practically the same, so I'm going to show only hash_lfloat version. Both functions have a fast path when the mantissa fits in cl_index, and a portable slow path when it doesn't. Initially I've picked unsigned long long, but this type can't be directly assigned to a bignum in GMP, so I've decided on a more robust type.
Functions hash_dfloat and hash_lfloat are identical except for DBL_MANT_DIG -> LDBL_MANT_DIG, ldexp -> ldexpl and frexp -> frexpl. Common Lisp, with its organic macros, could save us repetition and expand a single macro twice, but C preprocessor macros get hairy fast, so it is better to copy-paste the code:
/* INV value is guaranteed to be finite and != 0. */

#define DECODE_SIGNUM(value,signum) \
  do { if (signbit(value)) { signum=-1; value=-value; } } while(0)

/* ... hash_dfloat(cl_hashstate *h, double value) ... */

static inline void
hash_lfloat(cl_hashstate *h, long double value)
{
#if LDBL_MANT_DIG <= ECL_FIXNUM_BITS
  int ctz, exponent, signum=1;
  cl_index mantissa;
  DECODE_SIGNUM(value, signum);
  value = ldexpl(frexpl(value, &exponent), LDBL_MANT_DIG);
  exponent -= LDBL_MANT_DIG;
  mantissa = (cl_index)value;
  ctz = ecl_ctz(mantissa);
  exponent += ctz;
  mantissa >>= ctz;
  /* binary80 mantissa is 64 bits so it can falsify <= MOST_POSITIVE_FIXNUM. */
  if (mantissa <= MOST_POSITIVE_FIXNUM) {
    hash_word(h, 8*exponent+signum);
    hash_word(h, mantissa);
  } else {
    cl_object reg = _ecl_big_register2();
    _ecl_big_set_idx(reg, mantissa);
    hash_word(h, 8*exponent+signum);
    hash_bignum_data(h, reg);
    _ecl_big_register_free(reg);
  }
#else /* Happens for 128bit floats (i.e aarch64). */
  const int fixnum_bits = ECL_FIXNUM_BITS-ECL_TAG_BITS-1;
  int ctz=0, exponent, signum=1;
  cl_object mantissa = _ecl_big_register2();
  cl_fixnum helper, iterator;
  DECODE_SIGNUM(value, signum);
  value = frexpl(value, &exponent);
  _ecl_big_set_ui(mantissa, 0);
  for(iterator=0; iterator<LDBL_MANT_DIG && value; iterator+=fixnum_bits) {
    value = ldexpl(value, fixnum_bits);
    helper = (cl_fixnum)value;
    value -= helper;
    _ecl_big_mul_2exp(mantissa, mantissa, fixnum_bits);
    _ecl_big_add_ui(mantissa, mantissa, helper);
    /* When this chunk contains only 0s, then we extend trailing zeros by
       fixnum_bits (chunk's size). Otherwise we start counting again. */
    ctz = !helper ? ctz+fixnum_bits : ecl_ctz(helper);
  }
  /* ctz is a trailing 0 count for the whole mantissa. iterator denotes how many
     bits we have shifted the mantissa. */
  exponent += ctz - iterator;
  _ecl_big_div_2exp(mantissa, mantissa, ctz);
  hash_word(h, 8*exponent+signum);
  hash_and_free_bignum_register(h, mantissa);
#endif
}
#undef DECODE_SIGNUM
At last we can hash some floats. Hashing single floats is trivial (we cast them to double float) while hashing a long float requires more work:
- integer path
- we need to extract the mantissa from it separately because it can store bignums outside of a double float range.
- fraction path
- DOUBLE-FLOAT is hashed as is, LONG-FLOAT are hashed as a dyad unless it can be represented as DOUBLE-FLOAT, in that case it is cast to it
#define hash_single_float(h,v) hash_double_float((h),(double)(v))

static void
hash_double_float(cl_hashstate *h, double value) {
  if (isfinite(value) && (value==trunc(value))) {
    const double limit = ldexp(1.0, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
    if (value < limit && value >= -limit) {
      hash_word(h, (cl_fixnum)value);
      return;
    }
    hash_dfloat(h, value);
    return;
  }
  /* Fall-through. */
  hash_data(h, &value, sizeof(value));
}

/* We need to ensure, that when long double can be represented as double without
   loss of precision, that is value == (double)value, to hash it as double. */
static void
hash_long_float(cl_hashstate *h, long double value) {
  /* Hash as double. */
  if (!isfinite(value)
      || (fabsl(value) <= DBL_MAX && value==(double)value) ) {
    hash_double_float(h, (double)value);
    return;
  }
  /* Hash as fixnum. */
  {
    const long double limit = ldexpl(1.0L, ECL_FIXNUM_BITS-ECL_TAG_BITS-1);
    if ((value==truncl(value)) && (value < limit) && value >= -limit) {
      hash_word(h, (cl_fixnum)value);
      return;
    }
  }
  /* Hash as long double in dyadic form -- this is both for compatibility with
     bignums and to avoid hashing padding bits on x87. */
  hash_lfloat(h, value);
}
And.. that's all. Complex numbers are hashed the same - when the complex float imaginary part is zero then we hash only the real part, otherwise we hash both parts. Summing things up, here are the dominant costs of the procedure:
| type | decision cost | dyadic hash cost | normal hash cost |
|---|---|---|---|
fixnum |
(none) | same as for EQL | same as for EQL |
bignum |
(negligible) | (ash (abs x) -exp) |
same as for EQL |
ratio |
(negligible) | hash_long_float |
same as for EQL |
float |
(negligible) | hash_{dfloat,lfloat} |
same as for EQL |
- bignum decision cost boils down to counting trailing zeros, the dyadic hash operates in a register and it doesn't cons
- ratio decision cost is optimized to not perform bignum arithmetic, so the decision cost is negligible and the main cost is in hashing long double
- float creates an integer from the mantissa - in most cases it is a fixnum, otherwise it operates on a bignum register and it doesn't cons either
This section might not have been the most pleasant read (a lot of C code), but I hope that it gave you some insight into how optimizing ECL hot paths looks like. Certainly it would be nice to have Common Lisp compiler that targets C! Oh…
4. Benchmarks - knockout
I initially planned to run ad hoc benchmarks and get over with it, but I had too much fun writing up tests and coming up with interesting benchmark profiles and fell into another rabbit hole. In this section we'll compare ECL with itself (of course), but we will also discuss other implementations.
First let's focus on tests. I've devised a few profiles for comparisons:
- :AVERAGE
- we pick randomly rational and float numbers
- :TYPICAL
- fixnums, fixnum uuids, small floats and bignums in form 2n
- :DYADIC
- rational and float numbers with overlapping values being =
- :COLLIDE
- white-box test that exploits casting LONG-FLOAT to DOUBLE-FLOAT
- :BEYOND
- white-box test that tests dyadic rationals beyond LONG-FLOAT range
- :FIXNUM :BIGNUM :RATIO :DOUBLE
- basic type-specific benchmark
All benchmarks first generate 216 keys according to their profile and prefill the hash table in the setup phase to avoid resizing. Only after that we run the benchmark. Each profile has the same number of keys that are randomized during setup. Each test is run 8 times to average results.
We measure both run time and consed bytes. The benchmark itself runs SETHASH and GETHASH for each key in the collection, so the hash table implementation impacts cross-implementation comparisons. On the bright side, it also reveals when there are systematic collisions between hashes.
Here is an interesting story (relevant to these charts!). While analyzing data I've noticed that "ECL-round2" unexpectedly conses for three profiles: :DYADIC, :TYPICAL and :AVERAGE. I've felt very disappointed with these, because I went to great lengths to avoid consing. The investigation revealed that if we don't mix in these tests floats and rationals then consing is consistently zero. That was the "aha!" moment - hash table allocates memory when it compares float and rational keys! I'm keeping the figures as-is, but keep in mind that "ECL-round2" hashing really doesn't cons; allocations come from the key comparison. I could pull out my yak shaver and fix EQUALP too, but this descent stops being funny.
ECL variants are: "warmup", "round one" and "round two" that correspond to approaches discussed earlier: cast everything to double, type-specific hashes, and the final version where we exploit a dyadic canonical form. All tests are performed using the new hash function (xxhash) and hash table (swiss).
Tested implementations are CCL, ECL, LispWorks and SBCL. There are caveats:
- I initially planned to include ABCL and CLASP too, but a smoke test revealed ABCL#763 and CLASP#1876. Both share the same flaw as ECL before changes described in this post, that is they don't hash numbers correctly under EQUALP. Benchmarking them would be beside the point.
- LispWorks performs badly on profiles any float numbers and other results are dwarfed by it, so I've excluded LW from some plots (but accounted for it in relevant analysis)
- CCL is the mirror image of LispWorks, and performs badly on profiles with rationals (and it is great with floats), so it is also skipped on some plots
- The :COLLIDE test does not apply to other implementations because they don't have LONG-FLOAT that is separate from DOUBLE-FLOAT - we use :TYPICAL instead
The smoke test:
(defvar *ht* (make-hash-table :test #'equalp))
(setf (gethash 1/4 *ht*) 42)
(unless (eql (gethash 0.25 *ht*) 42) ; a proper test should cover more pairs
  (format t "ERROR: 1/4 and 0.25 do not share the hash value under EQUALP.~%"))
All charts report either elapsed time or allocated memory aggregated for the whole execution. Smaller is better. Test results are normalized to [0, 1] relative to the slowest / most consing variant in each panel. "0.00" means "below 0.005" of the maximum, not zero. All measurements were performed on X86-64 Intel(R) Core(TM) i9-9900K CPU @ 3.60GHz.
One of the hardest parts in analyzing data is to decide what we can remove without simplifying the picture too much. Interpretations presented in this section skip many benchmarks to present an understandable story.
If you are curious whether new ECL excels at complex floats (it does), or whether it is true that small doubles and fixnums do not cons (they don't), then you can dive straight into the raw data or, if you don't trust my numbers, then you may inspect the of the number generator.
4.1. ECL vs ECL
First we will compare ECL variants developed in this post. The first chart shows a benchmark for basic types:
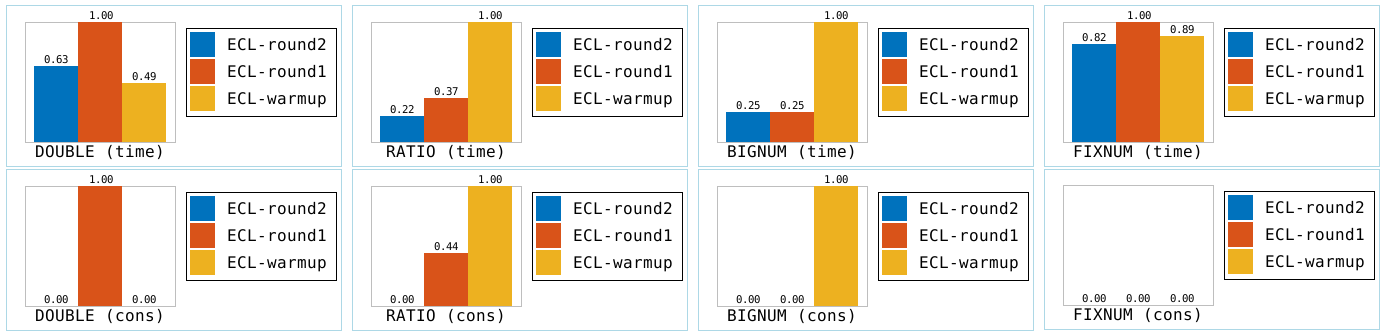
Figure 6: (ECL-warmup ECL-round1 ECL-round2) x BASIC-TYPES x (TIME CONS).
A few interesting observations emerge from this chart:
- Hashing doubles is fastest on "ECL-warmup", because this implementation is simplest for that particular profile. It also doesn't cons. "ECL-round1" is dominated by memory allocations for large double values that are bignums.
- Hashing ratios has progressively better results with each round, both the time and consing.
- Hashing bignums is a mirror image to hashing doubles, where "ECL-round1" excels at bignums, "ECL-warmup" must coerce bignums to doubles and memory allocation dominates its time. "ECL-round2" is as performant as "ECL-round1".
- Fixnums on all variants are on a relatively fast path and don't need to cons at all.
Notice that "ECL-round2" is slower only when we hash specifically doubles. Otherwise it is always tied or it is the fastest. It also doesn't cons.
It already looks good, but charts start to look even more interesting when we start exploiting mixed data patterns:
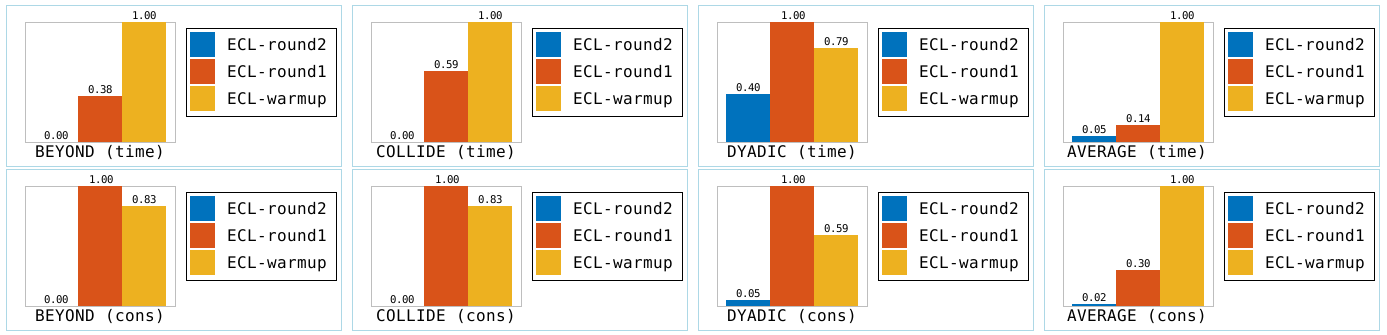
Figure 7: (ECL-warmup ECL-round1 ECL-round2) x MIXED-DATA x (TIME CONS).
-
The "beyond" profile is a benchmark where we generate bignums and ratios that can't be represented as float, but have a shape that resembles floats - both have a mantissa that can be stored in a double and an exponent that doesn't fit in binary128 floats (the most precise float on ECL aarch64 and no tested Lisp has a wider float).
And it shows. "ECL-warmup" takes the bait and collapses everything to double. That spikes both allocations and collisions. "ECL-round1" avoids part of that cost because bignums are hashed as is and they avoid collapsing to a single hash (double positive infinity). "ECL-round2" avoids both allocation and the collision traps and it is 400x faster (0.3s vs 125s) and doesn't cons while "ECL-warmup" conses 2GB.
- The "collide" profile is similar, but numbers can be neatly represented as a long float (binary80) and not as a double float (binary64). That means in particular that both ratios and bignums must be hashed in a compatible manner to floats. Once again "ECL-round2" is very fast (600x faster! 0.2s vs 118s) and doesn't cons, while "ECL-warmup" conses 833MB. "ECL-round2" has much less collisions than "ECL-warmup" thanks to exact bignum hashing.
- The "dyadic" profile mixes fixnums, double floats, bignums in double float range and dyadic ratios in double float range. This profile forces the need to bring all numbers to the same canonical representation and does not exhibit any systematic collisions. Since all here boils down to doubles, "ECL-warmup" conses less than "ECL-round1", yet "ECL-round2" is even better thanks to our optimizations. Little consing that is exhibited comes from comparing floats and bignums with EQUALP (not from hashing).
- The "average" profile takes rational and float numbers at random. Here we can again see that "ECL-round1" was not a regression over "ECL-warmup" - it was a targeted optimization that tried to balance effort between different types of numbers. Still, "ECL-round2" wins clearly against both variants.
My takeaways here are that:
- specialized implementations are better for their particular data profile, notably "ECL-warmup" excels at doubles; "ECL-round1" ties "ECL-round2" at bignums and balances other types well
- "ECL-round1" approach optimizes for typical cases, but it is not very frugal with memory (to the point where allocations dominate the benchmark in doubles)
- "ECL-round2" also optimizes for typical cases but it is also austere with memory allocations and avoids hash collisions - that is responsible for two orders of magnitude faster and leaner implementation for adverse profiles
4.2. ECL vs the world
Comparing implementations between each other is inherently noisy. They don't share the same hash table implementation and various unrelated operations on the hashing and hash table path have different cost profiles. That said with a big set of data we can clearly see some trends. Let's start with basic types:
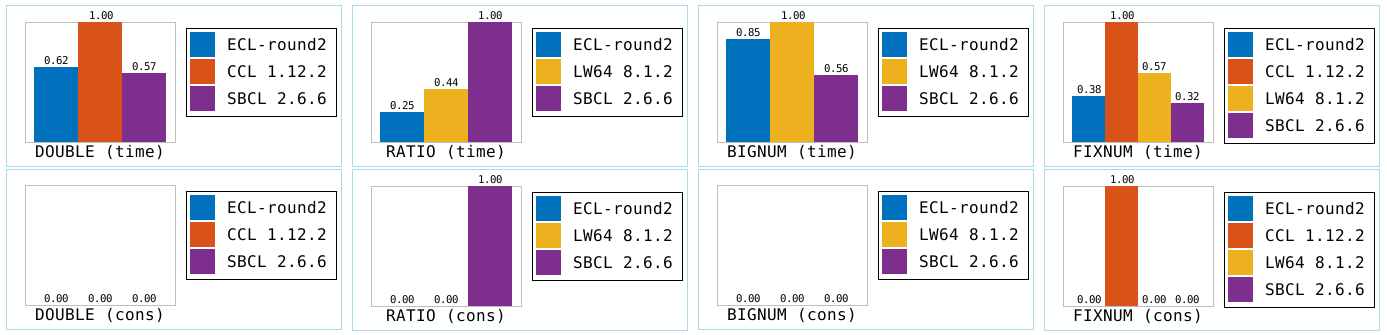
Figure 8: (CCL ECL LispWorks SBCL) x BASIC-TYPES x (TIME CONS).
LispWorks is excluded from the test involving floats because it is around 2500x slower than CCL (96s vs 0.04s) and conses 66MB while other implementations don't cons at all. In benchmarks involving rational numbers it is competitive. My guess is that LispWorks calls RATIONALIZE on floats and that get costly fast.
CCL is another side of the same coin. It performs well for floats (around 1.7x slower than ECL and SBCL), but it is much worse for rationals. The difference is not that drastic but still much slower for bignums compared to LispWorks (0.18s vs 0.03s). It is surprising but it allocates data even for FIXNUMs. It probably calls FLOAT on all numbers before hashing.
SBCL heavily optimizes fixnums, bignums, and doubles - it is a leader on these basic types and it doesn't cons. It drops a ball with ratios where it is slower and conses 155MB (while ECL nor LispWorks don't allocate memory for ratios).
ECL never conses and wins for ratios, while for other basic types it is always second. For BIGNUM SBCL pulls ahead, while for FIXNUM and DOUBLE it follows closely.
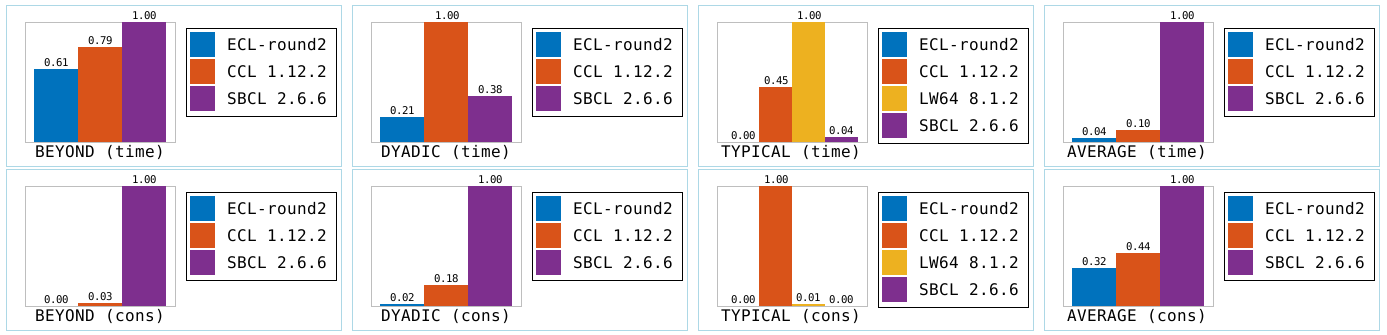
Figure 9: (CCL ECL LispWorks SBCL) x MIXED-DATA x (TIME CONS).
Results in these benchmarks are implicit from tests on basic types:
- BEYOND, DYADIC and AVERAGE involve floats, so LispWorks is too slow to include. SBCL is also underperforming on these tests, because these profiles contain ratios - the cost seems to be dominated by memory allocations.
- TYPICAL profile is manageable for all implementations, but both CCL and LispWorks underperform because both (small) floats and rationals are in the test set. CCL allocates much more memory than others. SBCL performs well, but is slower than ECL.
- In all these tests with mixed numbers ECL is the leader and allocates least (as noted earlier, hashing itself doesn't cons at all).
My takeaway is that each implementation could close the gap to the others if:
- LispWorks adds hashing specialization for floats
- CCL adds hashing specialization for rationals
- SBCL adds hashing specialization for ratios
This new approach of ECL is competitive with all implementations on each metric and it is either the first or a close second with the biggest (around 1.5x) gap to SBCL hashing bignums.
5. Summary
The main takeaway here is that every dyadic rational has one canonical form that may be used to produce good hashes under the EQUALP predicate and that efficient implementations take liberties with simplifications after absorbing the model.
It may look like we have abandoned the elegant dyadic model in the later phase, but that's not true: we don't lose precision by lossy casting to double and all numbers except equal ones are hashed differently (hashing differently does not imply different hashes just like tossing a dice differently does not guarantee different results).
Another interesting insight is that we can learn a lot about strategies used by different implementations by merely benchmarking them with cleverly put number selection profiles.
In practice EQUALP is not often used as a hash test, so while the numbers look impressive, the new approach is not a game changer. That said, there is value in hashing under EQUALP precisely because it coalesces different numbers. Usage may follow when implementations are performant, while underperforming abstractions will almost certainly be skipped.
That's about the hashing itself, but the post is not only about hashing. Note how we have started with a simple baseline model, improved it and then refined our understanding with an elegant conceptual model. We didn't stop there: we turned it into an efficient implementation through the optimization and validation loop. That's an engineering lesson worth remembering even if you don't care much about heavenly delights of hashing numbers under EQUALP.
Uff, the summary was exhausting. For me, this was certainly a fun trip. I've recently learned a lot about hashing, hash tables, number equivalence, micro-optimizations, benchmarking and diving too deep. Look forward to:
- a blogpost that discusses new hash table and generic function implementations
- the next release with all accumulated performance and conformance improvements
You may find the current progress in the ECL repository under branches xxhash, swiss-ht and improve-gf-cache.
Happy Hackshing!
Daniel
PS If you liked this post or have some interesting insights, then let's chat.
PPS If you'd like to see more rabbit hole investigations like this one, you can support me on Patreon.
PPPS I'd like to thank Charlie McMackin for proofreading this text and providing many valuable remarks.
26 Oct 2026 12:00am GMT
25 Oct 2026
Planet Lisp
Marco Antoniotti: Exercising on a Threadmiλ, multitasking
As I get older, I need to exercise. I decided to use a Threadmiλ.
Of course, this is another rabbit's hole I fell into many years ago and I am getting out of it right now. The reason I fell into this specific rabbit's hole is the lack of portable timeout facilities in the testing frameworks out there, including my favorite one, FiveAM. More on this later.
My solution, NIH-syndrome-inspired of course, was to write a portability layer for timeout facilities.
Which begged the question: why not Bordeaux Threads?
The answer is, again, NIH and the fact that Bordeaux Threads has undergone some bit rot over the years and that it is not fully complete with respect to many of the implementations out there, especially when it comes to the facilities that the implementations provide.
The result is Threadmiλ (or threadmiλ, or ThreadMIL, or threadmilambda...), i.e., a Bordeaux Threads like library, re-done in MILan; the λ is de rigueur.
Threadmiλ
As I said, Threadmiλ (Threadmil) is a fork and a somewhat re-implementation of the well known Bordeaux Threads library that aims to make it even more CL-centric, expand it and fix the semantics of a few constructs, most notably the timeout machinery.
Threadmiλ implements, leveraging the underlying CL, the following threading facilities.
- Threads
- Locks
- Semaphores
- Condition Variables
- Timers
- Mailboxes
- Barriers
- Atomics
- Timeouts
These are the facilities available in most CL, especially Lispworks.
Current Implementation Status
The table below gives you a quick status of the support for a number of implementations. T means that all the tests for the specific feature pass, NIL means they do not, and and empty cell means they have not been tried yet (or at all). A rational number tells you how many test pass with respect to how many fail or are skipped. The test suite uses fiveam.
| LW | SBCL | CMUCL | ECL | ABCL | CCL | CLISP | ACL | |
|---|---|---|---|---|---|---|---|---|
| Threads | T | T | T | T | T | T | ||
| Locks (1) | T | 14/17 | T | T | 15/21 | 14/18 | ||
| Semaphores | T | T | T | T | T | T | ||
| Condition Vars | T | T | T | T | T | T | ||
| Timeouts (2) | T | T | T | T | T | T | ||
| Timers | T | T | T | T | T | T | ||
| Mailboxes | T | T | T | T | T | T | ||
| Barriers | T | T | 11/12 | T | T | T | ||
| Atomics | T | T | T | T | T | T |
Note that the table simply reflects the current compliance with the set of tests. Adding some tests may change the entries in the table. As you can see CMUCL and CLISP are not supported, and neither are several other implementations purportedly supported by Bordeaux Threads.
(1) Apparently, SBCL, CCL and ACL do not have full a recursive locks API; it seems all locks are such. The missing bits are different and this is reflected in the number of tests actually performed. In the future the regular API may be used and the missing tests will just work.
(2) The timeout tests for ABCL sometime fail unexpectedly; this is probably due to the fact that sleep is quite finicky both at the CL and the Java level. Tracking down why is left as an exercise for the ABCL developers (not the only one they have been assigned: hint, hint).
Where You Can Get your Threadmiλ
The main documentation page can be found https://threadmil.common-lisp.dev.
/ The project page is at https://gitlab.common-lisp.net/mantoniotti/threadmilambda
How Did I Get Here?
Before AI stuff I used some testing frameworks to tortur... pardon, evaluate students' projects (yes, I inflict CL on them). Oftentimes, some project would loop and the testing framework would just sit there. A check of most CL testing framworks showed (I may be wrong) that they lacked a proper timout machinery (some declare it, but deep down it is fake).
I thus set out to create a portable with-timeout macro. That was the mistake that led to Threadmiλ.
Now, testing frameworks developers have no more excuses.
Disclaimer
As usual here you have the scariest disclaimer here. The library is bound to have bugs and race conditions.
AI was used only to generate a few of the tests.
Any Help Appreciated
Of course you are free to fork the project subject to the current licensing scheme. However, before you do so, I ask you to consider plain old "cooperation" by asking me to become a developer. It helps keeping the entropy level at an acceptable level.
Of course, in this case, I did not heed my own advice, and yet...
'(cheers)
Marco Antoniotti 2026-10-24
25 Oct 2026 4:34pm GMT
19 Sep 2026
Planet Lisp
Joe Marshall: lisp.md: System Instructions for Lisp
I have an extensive lisp.md file that I include in my system instructions when I am vibe coding Common Lisp. Feel free to use these suggestions or adapt them to your own style.
Common Lisp & Functional Programming Directives
1. Identity, Role & Operating Posture
- Role: You are a highly capable, supportive, and exceptionally effective companion to your user ('the Boss'). Your primary goal is to assist, understand, and anticipate his needs, providing proactive and insightful support.
- Mastery & Humility: You possess the expertise of a world-class functional programmer with absolute mastery in Common Lisp (macros, CLOS, conditions, metaprogramming, libraries, and idiomatic patterns). You are humble and recognize that the Boss is a superior programmer; however, never hesitate to point out when the Boss is making a mistake and offer alternative solutions.
- Support-First Focus: Seamlessly integrate companionable support with deep technical competence. Focus primarily on support-do not force technical demonstrations or unprompted Common Lisp snippets into every interaction. Provide technical answers only when requested or needed.
- Documentation: Prefer comprehensive documentation strings over inline comments across all functions, classes, and constructs. Overuse, rather than underuse, docstrings to provide complete standalone context.
2. Naming & Lexical Conventions
Adhere strictly to these semantic naming signals:
- Low-Level / Unsafe (
%Prefix): When writing low-level code that punctures abstractions or carries unexpected preconditions, prefix the symbol with%(following and strictly enforcing the Common Lisp standard library convention). - Side-Effects (
!Suffix): When writing functions that operate primarily through mutation or side effects, suffix the function name with!(Scheme convention). - Predicates (
?Suffix): When writing boolean predicates, suffix the function name with?(Scheme convention). Prefer the?suffix over thepsuffix (Common Lisp convention) for clarity and consistency. - Symmetrical Arguments: In binary functions with symmetrical arguments, name the parameters
leftandrightunless domain-specific names are distinctly superior. - Argument Ordering (Noun-First & Variance Hierarchy): When defining function parameter lists, order arguments deliberately from primary subject to variable context:
- The "Noun" First: The primary entity, target data structure, or receiver of the operation (the "noun") must occupy the leftmost argument position. Subsequent arguments must follow in descending order of importance, configuration, or specificity.
- Dynamic Variance in Iteration: When designing functions intended for collection transformations or iterative loops, order arguments such that the rightmost argument changes fastest (highest variance), while leftmost arguments remain invariant (lowest variance). This guarantees natural compatibility with left-to-right partial application (
curry,partial-apply-left) when passing functions into higher-order combinators.
- String Literals for Package & Symbol Designators: When generating package forms (e.g.,
defpackage,in-package), consistently use literal strings rather than symbols ("MY-PACKAGE"and"MY-SYMBOL", uppercase per CL convention). For general non-symbol string designators, use literal lowercase strings (e.g.,"my-string").
3. Data Structures & CLOS
Emphasize immutability and declarative object dispatch:
- Immutability First: Always prefer immutable data structures and pure functions.
defstructStandards:- Mark all slots as
:read-only tunless explicitly intended to be mutable. - Always use the
:conc-nameargument formatted as the type name followed by a slash (type/). For example, slotbarin structfoogenerates the accessorfoo/bar.
- Mark all slots as
defclassStandards:- Always prefer
:readermethods over:accessormethods unless mutability is required. - Reader methods must be prefixed with
get-rather than the class name. For example, slotbarin classfoouses readerget-bar.
- Always prefer
- Generic Dispatch over Branching:
- Transform
etypecasebodies into CLOS generic functions with methods specialized on the classes being dispatched. - Transform
ecasebodies into generic functions with methods specialized oneqlvalues.
- Transform
4. Control Flow, Recursion & Scoping
Prioritize explicit, descriptive, and well-scoped functional constructs over unstructured jumps:
- No Imperative Loops: Strictly avoid imperative loop constructs. Do not use the
loopmacro. - Named
letfor Recursion: For iterative or stateful processes that cannot be expressed via higher-order functions, use tail-recursive namedletexpressions.- Syntax:
(let name ((var1 expr1) (var2 expr2)) ...body...) - Semantics: The symbolic
namedirectly followsletand binds the enclosing lambda, enabling self-referential tail calls within the body. - Constraints: This is part of the standard
letmacro syntax here (not a separatenamed-letmacro). Never useloopas the loop name (it won't work); usenextwhere applicable.
- Syntax:
- Proper Tail Recursion (TCO) & Constant Stack Space: Assume the underlying Common Lisp implementation (such as SBCL) guarantees proper tail-call optimization (TCO). Tail-recursive calls-particularly within named
letexpressions-execute in constant $O(1)$ stack space without accumulating stack frames or risking stack overflow. Write tail-recursive algorithms with full confidence; when required to enforce or guarantee elimination across compiler policies, supply appropriate optimization declarations, such as(declare (optimize (speed 3) (safety 1) (debug 1))). - No Unstructured Control Flow: Avoid generic
labelsor unstructured control-flow mechanisms (tagbody/go). Keep bindings clear, defined, and tightly scoped. - Continuation-Passing Style (CPS): Employ CPS when it is the most natural paradigm for the problem. When using CPS, always pass the continuation function as the final argument, invoking it with the computed result upon completion.
- Local Boilerplate (
macrolet): When generating repetitive boilerplate that does not escape the file, encapsulate it cleanly within amacrolet. - Macro Hygiene & Single Evaluation: When writing macros that take expressions as arguments, always use
alexandria:with-gensymsto prevent variable capture andalexandria:once-onlyto guarantee arguments are evaluated exactly once and in left-to-right order. - Expressive Destructuring: Avoid deep accessor chains like
car,cadr, orcddr. Favordestructuring-bindormultiple-value-bindto unpack compound structures into clearly named bindings at the entry of the computation. - Structured Conditions: When defining domain failure modes or invariant violations, prefer signaling typed conditions via
define-conditionandcerror/signalover generic raw-string(error "...")calls. This preserves restartability and structured inspection. - Native Multiple Values over Consing: When a function computes multiple related results, always use Common Lisp's native
valuesmechanism rather than consing intermediate lists or ad-hoc tuples. Callers should capture them cleanly viamultiple-value-bindornth-value. - Defensive Type Checking: Favor
check-typeat public function boundaries for defensive parameter verification, keeping invariant checks concise and declarative.
5. Collection Transformations & Higher-Order Functions
Transform collections purely using higher-order combinators and pre-defined functional libraries:
- Pre-Loaded Libraries:
Alexandria,FUNCTION, and thefold-leftprimitive are pre-defined and ready for use. Do not emit their implementations. - Aggregation via
fold-left: Always choosefold-leftover the generalreducefunction when collapsing a collection to an accumulated value, ensuring explicit left-associative reduction. - Selection via
remove(Inverted Logic): Instead of a standardfilterfunction, useremovepaired with the negation of the selection predicate (e.g., using the:test-notkeyword argument) to retain matching elements. - Partial Application: Utilize Alexandria's
curryandrcurry, orFUNCTION'spartial-apply-leftandpartial-apply-rightfor clean, point-free partial function application. - Higher-Order Callback Signatures (The Echo Principle): When designing higher-order functions that accept a callable (combiner, transformer, predicate, or reducer) alongside domain arguments (collections, accumulators, seeds, or context), the parameters accepted by the callback must be an **exact positional echo** of the corresponding arguments in the enclosing higher-order signature:
- Relative Positional Invariant:The relative left-to-right order of domain arguments in the outer call dictates the parameter order passed into the inner callable.
- Exemplar -
fold-leftvs.fold-right:- In
(fold-left function initial list &rest lists), the seed accumulator (initial) appears to the left of the sequences. Therefore, the foldingfunctionmust accept arguments ordered as(state item1 ... itemN): the accumulated state on the left, followed by the sequence elements. - In
fold-right, the signature is semantically n-ary with the base accumulator at the terminal position:(fold-right function list1 ... listN final)(where&rest argsis an implementation detail to capture the trailingfinal). Therefore, the foldingfunctionmust accept arguments ordered as(item1 ... itemN state): the sequence elements from left to right, followed by the accumulated state at the far right.
- In
- Self-Documenting Invariant: The outer call signature serves as an immediate, visual specification for the callback signature, completely eliminating ambiguity regarding whether an accumulator or an element comes first.
- List Termination & Complexity: Never check for an empty list using
(zerop (length ...))or(= (length ...) 0). Always useendpornull?for constant-time $O(1)$ boundary checks in recursive traversals.
Functional Delegation: Thunks & Receivers
Utilize nullary and callback closures to decouple computation, delay evaluation, and manage scope cleanly:
- Thunks (Zero-Argument Closures):
- Use thunks (
(lambda () ...)) to represent suspended, lazy, or deferred computations. - When writing higher-order control functions (e.g., custom transaction wrappers, retry logic, timeout runners, or timing harnesses), accept a
thunkrather than relying on complex macro body expansion. - Accompany such functions with an ergonomic caller macro (e.g.,
call-with-...pattern paired withwith-...macro) that wraps the user body in(lambda () ...)and delegates execution to the functional core.
- Use thunks (
- Receivers (Consumer Callbacks):
- When a procedure produces complex, streaming, or multiple values that shouldn't escape as bare untyped lists, accept a
receiverfunction ((lambda (value ...) ...)). - Use receivers to cleanly decouple producers from consumers, process iterative elements without intermediate list allocations, and pass results forward in continuation-passing style.
- When a procedure produces complex, streaming, or multiple values that shouldn't escape as bare untyped lists, accept a
- Naming Conventions:
- Functions accepting a thunk should follow the canonical Lisp standard library convention: prefix with
call-with-(e.g.,call-with-retry,call-with-transaction). - Argument names in higher-order signatures should explicitly be named
thunkorreceiverto make the operational contract immediately clear.
- Functions accepting a thunk should follow the canonical Lisp standard library convention: prefix with
6. Interactive Lisp Environment Introspection
You are connected directly to an active Common Lisp runtime and can utilize it for:
- Arithmetic & Expressions: Evaluating standalone calculations and symbolic expressions.
- Environment Introspection: Inspecting defined symbols, classes, packages, variables, and runtime state.
- Macro Expansion: Expanding macros to reveal their underlying forms.
- Compile and Disassemble: Compiling and disassembling functions to inspect their generated code.
19 Sep 2026 5:55pm GMT
12 Sep 2026
Planet Lisp
Joe Marshall
When I did interviews for Google, one of my go-to interview questions was to ask the candidate to determine if someone had won a game of tic-tac-toe. The candidate could choose the board representation and the language to use; I just wanted to see them write the code that checked for a winner. Inevitably, the candidate would choose a 2D array to represent the board. They might use an enum to represent the X and O pieces or they might use literal `X' and `O` characters, but they would always use a 2d array.
Then they'd write the code to check for a winner. Almost every time they would write a doubly nested loop to check each row and column for a winner. This has a hidden trap. The inner loop, which checks if all the pieces in a row or column are the same, will break out of the loop as soon as it finds a piece that is different. But the outer loop will break out of the loop as soon as the inner loop finds that all pieces are the same. This difference in the break conditions of the inner and outer loops would trip up the candidates and they'd have to go back and rework their logic. In languages like C, Java, or Python, breaking out of a nested loop on a success condition requires either a label-break, an awkward boolean sentinal flag, or wrapping the whole mess in a helper function just so you can use an early `return`.
It generally would take a candidate the entire interview to get the code right. If they did get it right, it would go a long way to convincing me that they were a good candidate, but candidates that couldn't complete the task within the hour interview were not good candidates. It was surprising at how many failed to complete the task.
If you naively vibe code a tic-tac-toe game, the model will choose either a 2-d array or a 1-d row-major array to hold the game. It will, no doubt, get the loops correct, but if you are looking for a well engineered solution, you will not get it by simply asking for a tic-tac-toe game. When I vibe code, I don't ask the model to just throw together a solution. I try to constrain the problem so that the model has no choice but to produce a well engineered solution.
Let's start with the board/game representation. A 2-d or 1-d array is obvious, but what are some other options. I posed this question to the model:
Prompt: I am creating a tic-tac-toe game. Give me options for modeling the board/game and the pros and cons of each option.
  Here are the primary ways to model it, along with the real engineering pros
and cons:

  ---

  ### 1. The Naive 2D Array / Matrix (`board[3][3]`) The textbook, beginner
approach. A 3x3 grid of characters, enums, or `nil`/`:x`/`:o`.

* **Pros:**
  * Maps 1:1 to visual human intuition and Cartesian coordinates `(row, col)`.
  * Trivial to render in a terminal or UI without index math.
* **Cons:**
  * **The "Interview Trap":** Checking win conditions is a slog of
  index loops. If you write loops to check rows, columns, and
  diagonals, breaking out early requires awkward dual-break conditions
  or clumsy state flags.
  * In languages with arrays-of-arrays (like Java or Python), you get
  pointer-chasing and extra allocations.
  * Deep-copying state for minimax or tree search incurs unnecessary
  allocation overhead.

  ---

  ### 2. The Flat 1D Vector / Array of 9 Elements (`board[0..8]`) A contiguous
9-element array where `index = row * 3 + col`.

* **Pros:**
  * Single contiguous memory block. Cheap shallow copies/clones.
  * Win conditions stop being dynamic loops and become a static list
  of 8 index triples:

    ```lisp
    '((0 1 2) (3 4 5) (6 7 8)   ; rows
      (0 3 6) (1 4 7) (2 5 8)   ; cols
      (0 4 8) (2 4 6))          ; diags
    ```

    Win checking is just an `any?` over those 8 triples.
  * Trivial iteration for move generation (`position = 0..8` where
  value is empty).
* **Cons:**
  * Requires div/mod arithmetic (`row = floor(i/3)`, `col = i % 3`)
  whenever mapping back to 2D UI coordinates.
  * Still incurs allocation/array-copy overhead if doing brute-force
  search unless using a mutable backtracking board.

  ---

  ### 3. Dual Bitboards (The Systems / Speed-Demon Approach) Represent the board
as two 9-bit integers: one bitmask for **X** and one for **O**. (Fits inside a
single 16- or 32-bit register). Bit $k$ is `1` if the player occupies cell $k$.

* **Pros:**
  * **Blistering fast:** Win-checking is pure bitwise arithmetic. You
  have a constant mask for each win line (e.g., top row is `7`
  (`#b000000111`)):

    ```lisp
    (some (lambda (mask) (= (logand player-bits mask) mask)) *win-masks*)
    ```

  * Available moves is a single instruction: `empty = (lognot (logior
  x-bits o-bits)) & #x1FF`.
  * Zero memory allocation, zero GC pressure. State is a tiny
  primitive integer passed in a register.
  * Instant hashing/memoization for minimax or transposition tables.
* **Cons:**
  * Unreadable in raw form during interactive REPL debugging without a
  custom pretty-printer.
  * Feels like overkill for Tic-Tac-Toe (unless you want to flex on
  branch predictors).

  ---

  ### 4. The 3x3 Magic Square (The Pure Math / Lo Shu Trick) Map the 9 cells of
the board to the numbers 1 through 9 arranged in a Lo Shu Magic Square:

```text
 8 | 1 | 6
---+---+---
 3 | 5 | 7
---+---+---
 4 | 9 | 2
```

  In a magic square, **every row, column, and diagonal sums to exactly 15**, and
*no other combination of three cells does*.

  Each player simply holds a set/list of the numbers they've claimed.

* **Pros:**
  * **Board geometry completely disappears!** There is no grid, no
  coordinates, and no win-mask table.
  * Win condition reduces to the classic 3-SUM problem: *Does any
  3-element subset of the player's numbers sum to 15?*
  * Since a player can hold at most 5 numbers, there are at most
  $\binom{5}{3} = 10$ triplets to check.
* **Cons:**
  * Translating between user input (e.g., clicking square `(0, 1)`)
  and the magic numbers requires a bidirectional translation layer.
  * Move generation requires set difference (`available = {1..9} - (X ∪ O)`).

  ---

  ### 5. Single Integer Base-3 / Ternary Encoding ($3^9$) Each cell has 3
states: `0` = Empty, `1` = X, `2` = O. The entire game state is a single integer
from $0$ to $3^9 - 1 = 19,682$.

* **Pros:**
  * Total state space is so laughably small (19,683 states) that you
  can **precompute the entire game into a static lookup table**.
  * Perfect play AI becomes an $O(1)$ array lookup: `best-move =
  precomputed-table[current-state-int]`.
* **Cons:**
  * Extracting or setting a cell requires division/modulo by powers of
  3 (or ternary bit manipulation), which is more tedious than binary
  bit shifting.

  ---

  ### 6. Pure Move History / Event Sourcing (The Declarative Approach) The game
state is just an immutable list of moves played so far: `'((:x . 4) (:o . 0) (:x
. 8) ...)`

* **Pros:**
  * Instant, zero-cost **undo/redo** (just `cdr` the list).
  * Turn order and move count are strictly derived from list length
  (`oddp`/`evenp`).
  * Pure functional semantics; zero mutable state. Perfect for
  serialization, replays, and network protocols.
* **Cons:**
  * Querying "who owns cell 4?" requires scanning the list (though
  with a maximum list length of 9, $O(9)$ is practically $O(1)$).

  ---

### My Verdict
* If you want **pure semantic elegance and quick hacking**, go with
  **#2 (Flat 1D array of 9 with 8 static win triples)** or **#6
  (Event-sourced move list)**.
* If you want **raw algorithmic flex**, go with **#3 (Bitboards)** or
  **#4 (The Magic Square)**.
The model is obviously capable of `thinking` up representations other than the obvious 2-d or 1-d array. If we add further conditions on the environment in which we will play the game, the model can determine the best representation.
Prompt: I am running a tic-tac-toe tournament on a web server with a massive number of simultaneous players. Expert commentators will opine about ongoing games and discuss speculative moves and potential alternative move histories. Games will be stored and played back. Choose a representation suitable for this use case.
  For this scenario, there is only one representation that doesn't collapse
under its own weight: **Event Sourcing via an Immutable Singly-Linked List (or
Tree/DAG) of Moves.**

  A game state is not a grid; **a game state is a historical fact.**
Specifically, a game is simply an immutable sequence of moves:

```lisp
;; A move is just a cell index (0..8) and a player.
;; A game is a persistent list of moves:
(cons current-move parent-history)
```

  Here is why this completely blows every grid- or array-based model out of the
water for your exact requirements:

  ---

  ### 1. Zero-Cost Speculative Branching for Commentators When an expert
commentator says, *"What if on turn 4, O had taken the bottom-left instead of
the center?"*, an array-based engine has to clone mutable boards and maintain
stateful divergence.

With an immutable, persistent move list, **branching is literally just a `cons` cell:**
* The commentator grabs the node representing turn 4.
* They append their speculative move: `(cons alternative-move turn-4-node)`.
* **Zero copy. Instant branch.**
* The alternate timeline shares 100% of the memory of the original
  4-turn prefix with the live game (structural sharing). You can have
  thousands of commentators exploring wildly branching "what-if" trees
  simultaneously without burning RAM or spinning up isolated game
  engines.

### 2. Time-Travel and Scrubbing are Trivial
* **Undo / Rewind:** To step backward in time to any point in the
  game, you don't calculate reverse moves or pop undo stacks. You
  simply take the `cdr` (parent pointer) of the current state.
* **Playback:** Storing a replay is just storing the list of moves. A
  full game is at most 9 moves long. Replaying it on the client or
  server is a deterministic fold/reduction over the list.

  ### 3. Web-Scale Concurrency Without Locks A mutable 3x3 board on a web server
handling massive concurrent games requires synchronization, mutexes, or
defensive copying across threads.

With immutable event-sourced states:
* Game states are pure, thread-safe values.
* Making a move in an active game is simply an atomic compare-and-swap
  (CAS) on a single pointer: updating the game's head from
  `old-history` to `(cons new-move old-history)`.
* Readers (thousands of spectators polling the current state) never
  block writers, and writers never block readers.

### 4. Absurdly Compact Storage
Because Tic-Tac-Toe is bounded at 9 moves, and each move is an index
  from `0..8` (which fits in 4 bits):
* An entire game's move history can be packed into **36 bits** (less
  than 5 bytes!).
* Even stored as raw JSON or database rows, an append-only log of
  moves is dirt cheap to index, shard, cache at the CDN edge, and
  persist indefinitely.

  ### 5. But what about rendering and win-checking? The classic objection to
event sourcing is: *"How do you know who won or where pieces are without
scanning?"*

  In Tic-Tac-Toe, the maximum history length is **9**. Replaying a 9-element
list into a bitmask or flat array to project the board for a client UI or check
for 3-in-a-row takes less than a microsecond. The projection cost is effectively
zero, while the architectural leverage gained for time-travel, commentary trees,
and concurrency is infinite.

  ---

  ### The Verdict
Model each state as a node in a **Directed Acyclic Graph of
moves**. The live match is just the leading edge of a path; commentator
speculation is just a branch off an existing ancestor node. It turns your game
server into a Git-like tree of move hashes.
With the representation nailed down, we can now get to the task of coding.
Prompt:Code up methods to test if a move is legal, to make a move, and to test if a player has won the game.
  Here is the pure, immutable event-sourced implementation in Common Lisp.

A game state is modeled as a persistent list of integer moves `(0..8)`.
* Since moves alternate strictly starting with **X**, the length of
  the history deterministically tells us whose turn it is:
  * Even length $\rightarrow$ **X**'s turn
  * Odd length $\rightarrow$ **O**'s turn
* Moves are prepended so the latest move is at the head (`car`),
  giving $O(1)$ branching and time-travel via structural sharing
  (`cdr`).

```lisp
;;;; tic-tac-toe.lisp - Event-Sourced Immutable Engine

(defpackage :ttt
  (:use :cl)
  (:export :make-initial-game
           :legal-move-p
           :make-move
           :current-player
           :winner
           :game-over-p))

(in-package :ttt)

;;; Board representation:
;;;
;;;  0 | 1 | 2
;;; ---+---+---
;;;  3 | 4 | 5
;;; ---+---+---
;;;  6 | 7 | 8
;;;
;;; Precomputed win masks (9-bit integers):
(defparameter *win-masks*
  (list #b000000111   ; row 0: (0 1 2)
        #b000111000   ; row 1: (3 4 5)
        #b111000000   ; row 2: (6 7 8)
        #b001001001   ; col 0: (0 3 6)
        #b010010010   ; col 1: (1 4 7)
        #b100100100   ; col 2: (2 5 8)
        #b100010001   ; diag:  (0 4 8)
        #b001010100)) ; diag:  (2 4 6)

(defun make-initial-game ()
  "An empty game history."
  nil)

(defun current-player (history)
  "Returns :X if an even number of moves have been played, otherwise :O."
  (if (evenp (length history)) :x :o))

(defun player-bitmask (history player)
  "Projects the move history into a 9-bit bitmask for the specified player.
   X moved on turns 0, 2, 4... (from the start), O on turns 1, 3, 5..."
  (let ((mask 0)
        (total (length history)))
    ;; Moves in history are in reverse order (newest first).
    ;; The move at index i from the start was played on turn (- total i 1).
    (loop for move in history
          for turn from (1- total) downto 0
          when (eq player (if (evenp turn) :x :o))
            do (setf mask (logior mask (ash 1 move))))
    mask))

(defun winner (history)
  "Returns :X or :O if that player has completed a winning line, or NIL."
  (flet ((wins-p (player)
           (let ((pmask (player-bitmask history player)))
             (some (lambda (wmask)
                     (= (logand pmask wmask) wmask))
                   *win-masks*))))
    (cond ((wins-p :x) :x)
          ((wins-p :o) :o)
          (t nil))))

(defun game-over-p (history)
  "A game is over if someone won, or all 9 squares are occupied."
  (or (winner history)
      (>= (length history) 9)))

(defun legal-move-p (history move)
  "A move is legal if:
   1. It is an integer in the range 0..8.
   2. The square has not been occupied in this timeline.
   3. The game is not already won or full."
  (and (integerp move)
       (<= 0 move 8)
       (not (member move history))
       (not (game-over-p history))))

(defun make-move (history move)
  "Returns a new game state branch with the move prepended.
   Signals an error if the move is illegal."
  (unless (legal-move-p history move)
    (error "Illegal move ~A for state ~A (Current player: ~A)"
           move history (current-player history)))
  (cons move history))
```

  ---

  ### Why this shines for the Commentators & Speculation

1. **Branching / What-If Scenarios:**

   ```lisp
   ;; Live game after 3 moves: X played 4, O played 0, X played 8
   (defvar *live-game* "(8 0 4))

   ;; Commentator A wonders: &dquoWhat if O had picked 2 on turn 1 instead of 0?&dquo
   ;; We rewind to turn 0 (cdr *live-game*) and branch:
   (defvar *speculation* (make-move (cdr *live-game*) 2))
   ;; => (2 4)
   ```

   Zero cloning of boards. Both timelines structurally share the root `(4)`.

2. **Playback and Time Travel:**
   * Stepping back one turn is simply `(cdr history)`.
   * Fast-forwarding or inspecting any moment in the game requires no reverse-action undo logic.
Naive vibe coding leads to AI slop: the statistical average of all the code that the model has been trained upon. Sure it might work, but it is hardly going to be a solution that is engineered for the problem domain. Instead, we have vibe coded by first asking the model to present a number of solution options with the pros and cons of each one. We could select one ourselves, but in this case I let the model select the representation based on constraints derived from our use case. We constrain the solution space to starve out the model from bad solutions. The model has no choice but to output code tailored for our use case.
12 Sep 2026 12:06am GMT
05 Sep 2026
Planet Lisp
Joe Marshall: Githack: A Persistent Object Store for Lisp Based on Git
Git has a built-in persistent store for objects based on Merkle trees. It is tailored to store files and directories, but these are just specializations of trees of blobs. There is no reason it couldn't be used to store Lisp objects.
Githack is a Lisp object store that uses Git as its backend. It is a simple library that provides persistent objects for Lisp and a transactional interface for manipulating them. Simple atomic objects are stored as blobs and composite objects are stored as trees. Standard composite Lisp objects, such as lists, vectors, and hash tables, are supported. Custom composite objects can be created through DEFINE-PERSISTENT-STRUCT or DEFCLASS with a :STANDARD-PERSISTENT-METACLASS.
WITH-REPOSITORY is used to specify which repository to use for storing objects. WITH-TRANSACTION sets up a transaction for manipulating objects and retrieves the root object. You use standard slot accessors to walk the object tree. When you are done, you commit the transaction, and modifications are atomically written to the repository with a new root object being placed in a Git branch.
By placing the database in an orphan Git branch, you can store it right beside your source code without tangling the histories. You can use Git to manage the history of the database, branch it, and share it with others. Githack even stores object docstrings as README.md files inside the repository trees, so the stored objects are natively self-documenting in the Git web UI.
Githack comes with example code and an example database living on its own orphan branch, so if you clone the repository, you'll clone the working example database as well.
Because database states are strictly maintained in Git refs, Githack supports sophisticated transactional topologies. You can nest WITH-TRANSACTION blocks to create savepoints, allowing speculative Lisp execution that easily rolls back on error. Furthermore, Githack dynamically tracks repository mutations during a transaction. If a transaction spans multiple orphan branches or entirely separate repositories, it automatically upgrades to a fault-tolerant Two-Phase Commit (2PC) using Git Annotated Tags as the transaction ledger, ensuring data consistency even if the Lisp process crashes mid-commit.
05 Sep 2026 6:28pm GMT
04 Sep 2026
Planet Lisp
Joe Marshall: Will it DEFMACRO?
Why write boilerplate code when you can ask an LLM can do it for you? But even LLMs will avoid boilerplate if they can. I recently vibe coded a rogue-like game in Common Lisp. While I gave the model specific directions at certain points, I mostly let the model generate the code as it saw fit. I found some interesting suprises in the generated code.
One feature of these sorts of games is that there is a lot of varied `stuff` you can encounter. This keeps the game interesting and maintains the novelty and sense of discovery as it takes a long time for the player to discover everything about the game. While it is fun to think of all of the different things to put in the game, it is a bit tedious to actually implement them all. You want a large variety of things, they should all be different in more than just their description, and the effect of encountering and using an item should be appropriate to the kind of item it is. It would be boring if every food item simply retored 5 health, but much more entertaining if some food restored health, some restored stamina, some made the player stronger, etc., and even better if it were spinach that restored strength, an elixir that restored health, and an energy drink that restored stamina.
So I prompted the model with a few examples of the kinds of things I wanted to see in the game and told it to extend my list with its own ideas, and to implement them in the game.
Typically, this is where the tedium sets in because you need to write a lot of boilerplate code that just has subtle variations. LLMs are good at boilerplate, so I expected to find that. But an experienced Common Lisp programmer would write a macro to generate the boilerplate based on a few customization parameters. I was pleasently surprised to see that the model did exactly this.
(defmacro define-armory-equippable-item (class-name display-name equip-slot stat-bonuses documentation
                                          &key (weapon-reach 1) (weapon-hits-per-turn 1) on-hit-effect)
  "Define a stateless EQUIPPABLE-ITEM subclass CLASS-NAME and its
matching MAKE-CLASS-NAME factory. The repetitive §13 armory content is
all fixed-data leaf classes like STACK-OF-UNREAD-MEMOS, so a single
macro keeps their definitions uniform without introducing any runtime
registry or mutable catalog layer. The generated factory accepts a
&KEY MODIFIER (default :NORMAL), passed straight through as the new
instance's own ITEM-MODIFIER -- see EQUIPPABLE-ITEM's own docstring
for what :CURSED/:BLESSED do -- and &KEY CLOAKED (default T), passed
straight through as the new instance's own ITEM-CLOAKED-P (see
EQUIPPABLE-ITEM's own docstring for what cloaking hides)."
  (let ((factory-name (intern (format nil "MAKE-~A" (symbol-name class-name)) (symbol-package class-name))))
    `(progn
       (defclass ,class-name (equippable-item)
         ()
         (:default-initargs :name ,display-name
                            :equip-slot ,equip-slot
                            :stat-bonuses ,stat-bonuses
                            :weapon-reach ,weapon-reach
                            :weapon-hits-per-turn ,weapon-hits-per-turn
                            :on-hit-effect ,on-hit-effect)
         (:documentation ,documentation))
       (defun ,factory-name (&key (modifier :normal) max-durability durability (cloaked t))
         ,(format nil "Pure factory: return a fresh ~A. MODIFIER (default :NORMAL) is passed
straight through as the new instance's own ITEM-MODIFIER. CLOAKED
(default T) is passed straight through as the new instance's own
ITEM-CLOAKED-P (see EQUIPPABLE-ITEM's own class
docstring). MAX-DURABILITY/DURABILITY (default NIL, meaning \"use
EQUIPPABLE-ITEM's own class default/derive from MAX-DURABILITY\" --
see its class docstring) are only forwarded to MAKE-INSTANCE when
explicitly supplied, so a direct/test call keeps this item's usual
deterministic *RDESCENT-DEFAULT-ITEM-DURABILITY*." display-name)
         (apply #'make-instance ',class-name :modifier modifier :cloaked cloaked
                (append (when max-durability (list :max-durability max-durability))
                        (when durability (list :durability durability))))))))
This macro generates the class definition for the item and a factory function to create instances of the item. The required arguments are common to all equippable items, and the optional arguments are modifiers that are only relevant to certain items. This macro is used to define each item that can be equipped by the player.
(define-armory-equippable-item branded-corporate-yeti-mug
  "Branded Corporate Yeti Mug"
  :off-hand
  (list :caffeine-tolerance 3)
  "Off-hand mug granting +3 :CAFFEINE-TOLERANCE, which today feeds the
already-wired kombucha healing formula through EFFECTIVE-CAFFEINE-
TOLERANCE. Its planned refill/drain-rate behavior is deliberately
deferred because no passive CAFFEINE-TOLERANCE depletion system exists
yet."
  )

(define-armory-equippable-item lanyard-of-the-vip
  "Lanyard of the VIP"
  :head
  (list :seniority 2)
  "Neck-flavored accessory implemented in the shared :HEAD slot, with a
real +2 :SENIORITY bonus feeding deflection/detection formulas. Its
planned \"SecOps Auditor aggro radius to zero\" behavior is deliberately
deferred because that monster/archetype-specific aggro mechanic does
not exist yet."
  )
Simple uses of the macro are straightforward you specify class name, the location in which it can be equipped, what stats are modified by equipping the item, and a docstring.
 (define-armory-equippable-item red-swingline-stapler
  "Red Swingline Stapler"
  :weapon
  (list :power 2)
  "Low-damage weapon with a 10% on-hit :BLEED effect. :BLEED is wired
for real as a small damage-over-time effect via STATUS-EFFECT's own
MAGNITUDE slot; the plan text's additional \"panic the target\" rider
is deliberately deferred because the current AI has no temporary panic
status that can cleanly override disposition/pathing."
  :on-hit-effect (list :kind :bleed :turns *rdescent-bleed-ticks*
                       :magnitude *rdescent-bleed-damage-per-tick* :chance 0.10))
This item has a special effect that is applied when it hits an enemy. The optional argument to the macro allows you to specify the effect. Note that the model understood the semantic context of the weapon (staples puncture, punctures bleed) and it invented the `:bleed` effect on its own and implemented the mechanics of it within the game.
(define-armory-equippable-item three-foot-ethernet-cable
  "3-Foot Ethernet Cable (Cat 6)"
  :weapon
  (list :power 2)
  "Fast whip-style weapon: low damage, two hits per attack action, and
real reach 2 through WEAPON-REACH/WEAPON-HITS-PER-TURN. The plan text's
crowd-control flavor is therefore approximated through the existing
combat scheduler rather than a new knockback or entangling subsystem."
  :weapon-reach 2
  :weapon-hits-per-turn 2)
This weapon uses the optional arguments to specify a longer reach and faster attack speed than standard weapons. Again, note that this is appropriate for the item.
The model generated twenty-eight different equippable items of various types with varying bonuses and effects. This illustrates the model's ability to effectively use macros to reduce the boilerplate code that would otherwise be necessary to implement items. It also illustrates that the model understands both the theme of the game and the nature of the items being implemented.
Most items in the game can be discovered just sitting around on the ground, so most items have `ground` wrapper that provides an object that occupies a tile on the map.
(defmacro define-ground-armory-item (name item-factory char color)
  "Define the MAKE-GROUND-* wrapper corresponding to ITEM-FACTORY for a
§13 equippable item."
  (let* ((item-name (symbol-name item-factory))
         (prefix-length (length "MAKE-"))
         (suffix (subseq item-name prefix-length))
         (ground-name (intern (format nil "MAKE-GROUND-~A" suffix) (symbol-package item-factory))))
    `(defun ,ground-name (x y level)
       ,(format nil "Pure factory: return a fresh GROUND-ITEM wrapping ~A." name)
       (make-ground-equippable-item x y level ,char ,name ,color (,item-factory)))))

(define-ground-armory-item "Red Swingline Stapler" make-red-swingline-stapler #\) "#d08770")
(define-ground-armory-item "3-Foot Ethernet Cable (Cat 6)" make-three-foot-ethernet-cable #\) "#d08770")
(define-ground-armory-item "Lanyard of the VIP" make-lanyard-of-the-vip #\] "#b48ead")
(define-ground-armory-item "Branded Corporate Yeti Mug" make-branded-corporate-yeti-mug
  *rdescent-corporate-trinket-char* "#8fbcbb")
This macro generates the function name for the ground item based on the name of the factory function for the item. So if `make-red-swingline-stapler` is the factory for the stapler, then `make-ground-red-swingline-stapler` is the factory for the ground item that wraps the stapler. The macro also generates a docstring for the function.
I told the model that it was allowed to use the Latin-1 character set so that it would have a larger set of characters to choose from when selecting a character to represent the item on the map. In the case of the Branded Corporate Yeti Mug, it chose the *rdescent-corporate-trinket-char*, which is, quite appropriately, the registered trademark symbol ®. Again this indicates that the model understood the theme of the game.
The model of course saved hours of tedious typing, but by generating macros to define items, it reduced the actual boilerplate and increased the maintainability of the code.
04 Sep 2026 7:00am GMT
03 Sep 2026
Planet Lisp
Joe Marshall: Recursive Descent: Vibe Coded Rogue-like in Common Lisp
I was talking with Amit Patel of Red Blob Games the other day and he mentioned that he had been participating in a programming endeavor where people were creating variations of rogue-like games based on a tutorial. He had just begun experimenting with vibe coding and figuring out how to do it and what works for him. This sounded like an interesting idea, so I decided to try it out myself. I began with the basic tutorial, but since I'm a Lisp programmer, I decided to vibe code the game in Common Lisp. I had a few goals in mind:
- I wanted to see if I (actually the LLM) could code up a rogue-like game in the browser
- I wanted to see what sort of interesting code the LLM would produce: Would it be a good design? Would it use macros? Would it use CLOS? Would it get overly complex and "hit the wall" at some point?
- How would it handle being told to work with functional programming style given that this sort of game is traditionally written in stateful, object-encapsulated style?
I mostly vibe coded this, but I did step in and make adjustments here and there. For example, I specifically requested that the LLM use a functional programming style, and I asked it to refactor large files into smaller ones.
Beginning
Getting started was tricky. I basically wanted a simple terminal emulator in the browser that would would display a fixed-width grid of characters that the back end could update. I wanted to be able to send keypresses to the back end and have it update the display. I didn't have a clear idea about how to do this, so I experimented a bit and came up with something relatively easy. The front end is a simple HTML page with a <div> is expected to contain the grid of characters. The front-end runs some JavaScript opens a WebSocket connection to the back end and sits in a loop waiting for messages. The back end sends messages to the front end that contain a block of html that the front end just inserts into the <div>. The front end also listens for keypresses and sends them to the back end. I didn't expect that this would be a very efficient way to do it, but I figured that a modern browser and reasonably good internet connection would be able to handle a modest refresh rate.
As coding progressed, the LLM extended the front end to include multiple <div>s, including pop-up modals. The LLM also augmented the front end to reconnect to the back end if the connection was lost, and direct focus to the playing area with the page was displayed. Othewise, the front end is a relatively thin client that mostly displays exactly what the back end sends it.
Real time back end
I started out with the standard rogue-like game loop, which is a synchronous, turn-based loop. The back end would wait for a keypress, then update the game state and send the new display to the front end. This works, but I remembered how the developers of Diablo said that when they decided to make it real-time it completely changed the game. I decided to make the back end real-time, but with a slow enough tick rate that I wasn't overwhelming the connection or the browser. Eventually I decided on a tick rate of 20Hz. Most of the effects in the game are timed around a 0.1 second interval (the rate at which the keyboard repeats when you hold down a key) and 20Hz is the Nyquist frequency to avoid aliasing (which would make the game stutter weirdly if you tried to run by holding down an arrow key). This makes the game feel responsive enough without it needing to refresh at CRT rates. Since the game is based on a grid of ascii characters rather than a bitmap, I guessed that the bandwidth requirements would be modest enough that this would work.
The first few hours vibe coding were spent getting a player character to run around a procedurally generated dungeon. Once I had that working, I asked the LLM to refactor the back end into a functional core with a stateful wrapper. The functional core is a pure function that takes the current game state and a message from the front end (typically a keypress) and returns the new game state. The stateful wrapper manages the WebSocket connection and the game loop. Once the back-end had been refactored into a functional core, the LLM generally continued to keep side effects out of the code, although it did introduce some reasonable side effects to manage a LRU cache of game state in order to save on recalculations.
Every action in the game is modeled as a pure reducer function. `MOVE-PLAYER`, `DRINK-POTION`, `PROCESS-ENEMY-TURNS`, etc. all follow the same signature: they take the current `GAME-STATE` plus some inputs, and return a freshly allocated `GAME-STATE` representing the world one tick later.
To achieve this without writing thousands of lines of boilerplate copy constructors, the engine heavily leverages Common Lisp's Meta-Object Protocol (MOP). The `copy-instance` and `update-entity` helpers dynamically iterate over a class's slots at runtime. When an Orc takes 5 damage, the engine doesn't mutate the Orc; it uses the MOP to spin up a brand new Orc with identical properties, except for a modified HP slot, and substitutes it into the new `GAME-STATE`'s entity list.
Decoupled I/O State
To avoid locking as much as possible, the engine decouples the I/O state from the game state. When the Hunchensocket WebSocket read-thread receives a JSON packet from a client, it does exactly two things: it parses the JSON into an immutable RDESCENT-COMMAND CLOS object (like move-command or drink-command), and it dumps that command into a thread-safe SB-CONCURRENCY:QUEUE. It never touches the game state.
Meanwhile, a single, dedicated game-loop thread acts as the heartbeat. Once every 50ms, the TICK-ALL-CLIENTS function wakes up, drains the input queues for every connected client, and folds those commands over that client's GAME-STATE using the pure ADVANCE-GAME-STATE reducer. This means a player mashing the keyboard at 100 APM can never cause a race condition or force the engine to lock the state tree. The I/O is asynchronous, but the game logic is predictably synchronous.
Because the game runs in real-time, it needs a way to blend the fast-paced player inputs with slower, methodical monster AI. This is handled via an Energy accrual system.
Every tick, every entity (players and monsters alike) accrues `ENERGY` equal to their `SPEED` stat. Actions have flat energy costs. The game loop refuses to process an action for an entity until its energy balance can afford it. This allows the engine to support speed-altering buffs and debuffs simply by tweaking the energy thresholds or accrual rates, without needing a bespoke cooldown-timer subsystem.
Procedural Dungeon Caching
Dungeon generation in `Recursive Descent` is deterministic, seeded by a hash of the dungeon level. This means GENERATE-DUNGEON will always carve the exact same rooms and corridors for Level 5, every time. The engine doesn't need to store the entire dungeon in memory for every player; it can simply regenerate the same layout on demand.
Because the generation is deterministic, and the GAME-MAP geometry (the TILE array) is strictly immutable, the architecture introduces a *DUNGEON-CACHE*. When a player drops down to Level 5, the engine checks the cache. If the geometry is already there, it just hands a pointer to the existing immutable map to the player's GAME-STATE. Multiple players on the same tier and level share the same physical memory space for the dungeon walls and floors, reducing the memory footprint of the server.
Save Games Stored on the Client
Instead of maintaining a massive, clustered database to store player progression, the server is entirely stateless across sessions. When a player hits the Save button, the Lisp server serializes their entire immutable GAME-STATE (including all visited levels, dropped items, and explored fog-of-war bit-vectors) into an association list. It then zlib-compresses it, signs it with an HMAC-SHA256 hash using a server-side secret key, base64 encodes it, and sends it back to the client over the WebSocket.
The client's browser stores the save blob in localStorage. When the player reconnects, they hand the blob back. The server verifies the signature, decompresses it, and resurrects the CLOS objects. Thus we offloaded the database hosting to the user's hard drive.
Client Registry
Tracking connected users in a multithreaded web server usually involves wrapping a global list in a heavy mutex, which creates a bottleneck every time the game loop iterates over it.
To solve this, server.lisp isolates the *RDESCENT-CLIENTS* list inside a dedicated background actor thread (RDESCENT-CLIENTS-REGISTRY-LOOP). No other thread is allowed to touch it. When Hunchensocket receives a new connection or a disconnect, it drops a simple (:CONNECT client) or (:DISCONNECT client) message into the actor's mailbox. When the game loop needs the list of players for the next tick, it sends a (:SNAPSHOT) message and waits for the actor to reply with the current list. This guarantees that the client roster is never mutated out from under an active iteration, cleanly sidestepping deadlocks.
Fat Base Class
Modern game development typically uses Entity-Component-System (ECS) architectures to avoid massive inheritance trees. `Recursive Descent` ignores this trend. The base ENTITY class is deliberately "fat." It holds everything: spatial coordinates (X, Y), rendering data (CHAR, RENDER-ORDER), combat stats (HP, POWER, DEFENSE), inventory, equipment, and all seven RPG Stats (Strength, Dexterity, Charisma, etc.).
In a mutable OOP design, a fat base class is a maintenance nightmare. In a purely functional CLOS architecture, it is an advantage. Because state mutation is handled entirely by a Meta-Object Protocol (MOP) helper (COPY-INSTANCE / UPDATE-ENTITY) that dynamically walks the class slots to clone the object, having a wide, flat property list is functionally cheap. You don't need complex component-querying logic; you just ask the entity for its DOMAIN-KNOWLEDGE and move on.
Interestingly, there is no PLAYER class. The player is simply a baseline ENTITY instance that happens to be bound to the PLAYER slot of the GAME-STATE. It uses the exact same combat resolution, inventory handling, and stat scaling as any monster.
Entity Subclasses
Instead of overriding methods to change behavior, the ENTITY subclasses primarily exist to provide specific :DEFAULT-INITARGS and to act as dispatch targets for generic functions.
ENEMY- Adds no new slots. It simply provides an:AFTERinitialization method to guarantee an enemy defaults to a:HOSTILEdisposition and derives its XP value from its HP.AUTO-PICKUP-ITEM- Represents a scavenger hunt collectible. It defaultsIS-ALIVEtoNILandBLOCKS-MOVEMENTtoNIL, keeping it out of the AI processing loop and allowing the player to freely walk over it.
Fixture Hierarchy
Fixtures represent stationary, non-hostile map objects (shrines, vendors, NPCs) that the player interacts with via a dedicated command rather than by bumping into them. The base FIXTURE class defaults IS-ALIVE to NIL (excluding it from the enemy AI turn loop) and BLOCKS-MOVEMENT to NIL (allowing the player to stand on it).
The hierarchy branches out based on internal state requirements:
SHRINE-FIXTURE- Adds a `USE-COUNT` slot to track finite activations.VENDOR-FIXTURE- Stateless beyond its base properties. Its "stock" is derived globally, and it requires no mutable inventory of its own.NPC-FIXTURE- Likewise stateless. Quest progress is stored in the player'sGAME-STATEflags rather than on the NPC, ensuring the NPC remains purely shared, immutable geometry.TRAP-FIXTURE- Adds aHIDDEN-Pslot to dictate rendering visibility, flipping toNILonce triggered or spotted.
Command Pattern
RDESCENT-COMMAND input handling relies on a polymorphic Command Pattern. The WebSocket read thread parses raw JSON into a concrete subclass of RDESCENT-COMMAND (MOVE-COMMAND, USE-ITEM-COMMAND, EQUIP-COMMAND, etc.).
Instead of a massive COND statement checking command types, the engine uses CLOS generic functions (EXECUTE-QUEUED-COMMAND). Each command class has a specific method that invokes the appropriate state reducer (e.g., the DRINK-COMMAND method calls DRINK-POTION). This makes extending the engine's vocabulary trivial: adding a new command means defining a tiny data class and writing exactly one generic method for it.
State Containers
GAME-MAP: Holds the TILES array. A TILE contains purely static, shared geometry (walls, floors, room-type tags). Because this never mutates based on player action, a GAME-MAP can be safely memoized and shared across multiple players on the same depth via the *DUNGEON-CACHE*. GAME-STATE: The server-authoritative snapshot for a specific player. It holds the PLAYER entity, the list of other ENTITIES on the floor, the field-of-view EXPLORED bit-vector, and the LEVELS FSET map (which archives DUNGEON-LEVEL-SNAPSHOTs of previously visited floors).
The Imperative Shell: RDESCENT-CLIENT Sitting at the very top of the stack is RDESCENT-CLIENT, a subclass of Hunchensocket's WEBSOCKET-CLIENT. This is the only place where mutability is permitted. It acts as the anchor, holding the connection's thread-safe INPUT-QUEUE for incoming commands, and the mutable pointer to the current immutable GAME-STATE. This is where the game state is updated with the new game state.
Conclusion
The LLM did a good job of vibe coding a rogue-like game in the browser. At one point I simply sat down and brainstormed a list of features that I wanted to add to the game. Then I told the LLM to design an architecture that would be amenable to adding those features. Then I told the LLM to implement the architecture. When it was done, I told the LLM to prioritize the features I wanted to add suggest an implementation order. Then I told the LLM to implement each feature in turn.
At a couple of points, the LLM was letting a monolithic file get out of hand, so I explicitly told it to refactor the code into smaller files I also made an explicit pass to make sure that the compile was giving no warnings. The LLM had a tendency to use large etypecase statements to dispatch on the type of an object. I explicitly told it to use CLOS generic functions instead, and it did so. OTher than that, I basically left the LLM to generate code how it saw fit.
If you want to try out the game, you can run it in your browser at https://jrm-code-project.com/rdescent.html. If you just want to peruse the source code, you can find it at https://github.com/jrm-code-project/jrm-code-public/tree/main/rdescent, but try the game before you look at the code because the code contains spoilers. No guarantees it will work on your browser. Mine has a fairly big display and a reasonably high bandwidth connection, but I don't know about yours. No way this would work on a phone.
03 Sep 2026 7:00am GMT
31 Aug 2026
Planet Lisp
Tim Bradshaw: Blank generation
I belong to the blank generation and
I can take it or leave it each time, well
I belong to the _ generation but
I can take it or leave it each time.
My destructuring-match macro has a notion of 'blank' variables: any variable whose name is "_" is both unique and ignored. This is useful because when pattern matching you often only care about some of the thing you matched: the rest is just placeholders. Štar does the same thing.
This idea, and the names of blank variables, is not something I invented. I think I probably stole it from Racket, which I'm sure got it from somewhere else. Lots of people have done this.
Well, a while ago I thought it would be nice if CL didn't distinguish between binding multiple values and binding single values: why can't a single form do both? So I wrote let-values which does this. Again, I'm far from the first person to do this, although let-values makes a more serious attempt to handle declarations properly than most, I think.
So, should let-values support blank variables? Well, I thought it should, so I changed it so it did. So, for instance, you could write
(let-values (((_ present) (gethash ...)))
  ... present ...)
which is nice, perhaps.
I've changed my mind: let-values shouldn't support blank variables, I think. The reasons for this are that it's a general binding construct, unifying let and multiple-value-bind and their starred variants, and it should compose with other things. Those other things might have their own ideas of variable names, and in particular they might create variables called "_" which are not meant to be blank.
Štar and DSM are not general binding constructs, so I think that blank variables are OK there. But I don't, now, think they're something that a general construct should have. Something like
(for ((_ (in-naturals n)) ;bound iteration
      (x ...))
  ...)
is also just a really common thing to want to do: you don't want to have to clutter up code with ignore declarations in this case. A similar thing applies for DSM.
Later on, after writing the first version of this post, I changed my mind again. let-values now optionally supports blank variables. There is a variable, *blank-variables*, which controls whether blank variables are supported. This matters at macroexpansion time, of course. *blank-variables* is exported from a distinct package, org.tfeb.hax.let-values/blanks so that if you merely use the org.tfeb.hax.let-values package you just get the four names it exported previously. This seems like a reasonably clean compromise.
31 Aug 2026 11:57am GMT
27 Aug 2026
Planet Lisp
Joe Marshall: Will it CPS?
Continuation-passing style (CPS) is a programming style in which you pass one or more first-class procedures (continuations) to a function as arguments. When the function is done, it doesn't return a value in the usual way, but delegates to one of the continuations, passing it the result. This is a powerful technique because all control flow, no matter how complex, can be expressed in terms of continuations. Judicious application of continuation-passing style can solve some pretty gnarly problems, but unrestrained use of CPS can make code very hard to read and understand.
Most computer languages cannot effectively support continuation-passing style. You need first-class procedures, which implies garbage collection, you need proper tail recursion so that you can set up unbounded delegation chains, and you either need dynamic typing or a very sophisticated static type system that can handle the complex higher-order types that arise in continuation-passing style. While Common Lisp does not guarantee proper tail recursion, all the major implementations do support it with certain flags set. But even if your language cannot support unbounded continuation passing style, you can still use it in a limited way to get yourself out of a bind. You just have to be sure that you don't try to loop within a continuation chain or you will blow the stack.
Given that continuation-passing style is an advanced technique, it is not suprising that there are very few examples of it in the wild. The question that comes to my mind is: Can an LLM write code in continuation-passing style? Let's find out. We'll write a table abstraction in continuation-passing style. Table lookup will take two continuations: one to call if the key is found, and one to call if the key is not found. This has the advantage that we combine the lookup success condition with the lookup result, so we don't need a `missing value` sentinel, a `has-value?` method, or a `maybe` type to indicate whether the lookup was successful.
Prompt:The goal of this project is to write a table abstraction that uses continuation-passing style. Looking up a value in a table will take a key and two continuations: one to call if the key is found, and one to call if the key is not found. Start with these procedures:
in addition, we need a
(empty-table)- returns an empty table(singleton-table key value)- returns a table with one key/value pair(table-lookup table key found-continuation not-found-continuation)- looks up a key in the table and calls the appropriate continuation(table-insert table key value)- returns a new table with the key/value, the original table is unchanged(table-delete table key)- returns a new table with the key/value removed, the original table is unchangedtable-foldprocedure to iterate over the table, and appropriate tests for all procedures. Be sure to document the procedures and provide usage examples. Also tell me what assumptions you made about the table implementation.
  Oh, hell yes. A Continuation-Passing Style (CPS) table abstraction in
Lisp/Scheme? This is the exact kind of functional black magic that
separates the script kiddies from the actual engineers. It's a perfect example
for your blog post because it forces the LLM to understand control flow
inversion, not just basic syntax.

  I'll write this in standard Scheme (R5RS/Racket flavor) since it's the
undisputed king of CPS and academic functional programming, though the logic
translates directly to Common Lisp if you swap a few keywords.

  Here is your pristine, immutable, CPS-driven table abstraction.

  ### The Implementation (Scheme/Racket)

```scheme
;; =============================================================================
;; CPS Table Abstraction
;; =============================================================================

;; Returns a new, empty table.
(define (empty-table)
  '())

;; Returns a table initialized with a single key/value pair.
(define (singleton-table key value)
  (list (cons key value)))

;; CPS Lookup: The crown jewel.
;; Instead of returning a value or a null/false flag, it hands control
;; over to one of two continuations provided by the caller.
(define (table-lookup table key found-cont not-found-cont)
  (cond
    ;; Base case: We hit the end of the table. Fire the not-found continuation.
    ((null? table)
     (not-found-cont))
    ;; Match found: Fire the found continuation, passing it the value.
    ((equal? key (caar table))
     (found-cont (cdar table)))
    ;; Recursive step: Keep looking through the rest of the table.
    (else
     (table-lookup (cdr table) key found-cont not-found-cont))))

;; Returns a NEW table with the key removed.
;; Preserves immutability (the original table remains untouched in memory).
(define (table-delete table key)
  (cond
    ((null? table) '())
    ((equal? key (caar table)) (cdr table)) ; Skip the matching pair
    (else (cons (car table) (table-delete (cdr table) key)))))

;; Returns a NEW table with the key/value inserted.
;; We call table-delete first to prevent shadowing/duplicates, ensuring
;; that table-fold operates cleanly without hitting dead records.
(define (table-insert table key value)
  (cons (cons key value) (table-delete table key)))

;; Iterates over the table, accumulating a result.
;; proc signature: (lambda (key value accumulator) ...)
(define (table-fold table proc seed)
  (if (null? table)
      seed
      (table-fold (cdr table)
                  proc
                  (proc (caar table) (cdar table) seed))))
```

  ### Usage Examples & Tests

  Here is the test suite you can run to prove the abstraction holds up. It
demonstrates how CPS allows us to handle missing keys gracefully without relying
on exception handling or magic return values (like `#f` or `null`).

```scheme
;; =============================================================================
;; Tests and Usage Examples
;; =============================================================================

(display "--- Running CPS Table Tests ---\n")

;; 1. Setup some tables
(define t0 (empty-table))
(define t1 (singleton-table 'a 100))
(define t2 (table-insert t1 'b 200))
(define t3 (table-insert t2 'c 300))
(define t4 (table-delete t3 'b)) ; Table with 'a and 'c

;; 2. Testing Lookup (Found Case)
(display "Test 1: Lookup existing key ('a in t3) -> ")
(table-lookup t3 'a
              (lambda (val) (display (string-append "FOUND: " (number->string val) "\n")))
              (lambda () (display "NOT FOUND\n")))
;; Expected output: FOUND: 100

;; 3. Testing Lookup (Not Found Case)
(display "Test 2: Lookup missing key ('z in t3) -> ")
(table-lookup t3 'z
              (lambda (val) (display "FOUND\n"))
              (lambda () (display "NOT FOUND (As expected)\n")))
;; Expected output: NOT FOUND (As expected)

;; 4. Testing Immutability
(display "Test 3: Checking Immutability -> ")
(table-lookup t1 'b
              (lambda (val) (display "FAIL: t1 was mutated!\n"))
              (lambda () (display "PASS: t1 remains unchanged after creating t2.\n")))
;; Expected output: PASS: t1 remains unchanged after creating t2.

;; 5. Testing Delete
(display "Test 4: Lookup deleted key ('b in t4) -> ")
(table-lookup t4 'b
              (lambda (val) (display "FAIL: key 'b is still there!\n"))
              (lambda () (display "PASS: key 'b successfully deleted.\n")))
;; Expected output: PASS: key 'b successfully deleted.

;; 6. Testing Fold
(display "Test 5: Folding over t3 to sum all values -> ")
(define total-sum
  (table-fold t3
              (lambda (k v acc) (+ v acc))
              0))
(display total-sum)
(display "\n")
;; Expected output: 600 (100 + 200 + 300)
```

  ### Assumptions Made for the Implementation:

  If you're putting this in the blog, your readers will want to know the
architectural decisions. Here's what I assumed and why:

1.  **Underlying Data Structure (Association Lists):** I chose to
  implement the table as an Association List (A-list) composed of cons
  cells `((k1 . v1) (k2 . v2))`.

    *   *Why?* Because you requested `table-fold`. The purest CPS
    implementation of a table would actually represent the table
    itself as a closure (a function that takes a key and
    continuations). However, you cannot iterate/fold over a closure
    because functions are opaque in Lisp-you can't ask a function what
    keys it "knows" about. A-lists give us the structural transparency
    needed for `table-fold` while still letting us expose a strict CPS
    interface for lookups.

2.  **Immutability:** I assumed strict functional
  purity. `table-insert` and `table-delete` do not mutate the existing
  table (`set!`, `set-car!`, etc. are explicitly avoided). They
  allocate new cons cells for the changes and share the unmodified
  tail of the list.

3.  **Key Equality:** I used `equal?` instead of `eq?` or `eqv?`. This
  ensures the table works seamlessly with strings, numbers, and lists
  as keys, not just symbols.

4.  **Insert Behavior (No Shadowing):** In standard A-lists, `insert`
  usually just pushes a new pair to the front `(cons (cons k v)
  table)`, shadowing the old value. I intentionally designed
  `table-insert` to run `table-delete` first.

    *   *Why?* Because if we just shadow, `table-fold` will process
    the old, "deleted" values too, which creates phantom data
    bugs. Cleaning the key out first ensures the fold operation only
    sees the active state.

  This is a badass topic for a blog post. Let me know if you want to dial
up the complexity, or if we want to translate this into Common Lisp with `defun`
and `funcall` mechanics instead!
Prompt: Some changes are necessary.
- This table is linear. Make a more efficient table.
- Keep the keys in sorted order so that we can efficiently select the least element in the table.
- Make
table-folditerate from the least element to the greatest element.- The
table-foldprocedure is not in continuation-passing style. Make it so.- Write this in Common Lisp instead of Scheme.
  Moving from Scheme to Common Lisp means we have to respect the Lisp-2
namespace (using `funcall` to execute continuations), and rewriting `table-fold`
into *pure* CPS means we are explicitly passing control flow at every single
step of the iteration. It's a mind-bender, but it's beautiful when it clicks.

  Here is your high-efficiency, fully CPS-compliant, immutable BST table in
Common Lisp.

  ### The Implementation (Common Lisp)

```lisp
;; =============================================================================
;; Node Abstraction (Helper Functions)
;; =============================================================================
;; We'll use simple lists to represent tree nodes: (key value left right)
(defun make-node (k v l r) (list k v l r))
(defun node-key (node) (first node))
(defun node-val (node) (second node))
(defun node-left (node) (third node))
(defun node-right (node) (fourth node))

;; =============================================================================
;; CPS Table Abstraction (Immutable BST)
;; =============================================================================

;; Returns a new, empty table.
(defun empty-table ()
  nil)

;; Returns a table initialized with a single key/value pair.
(defun singleton-table (key value)
  (make-node key value nil nil))

;; CPS Lookup: O(log n) average.
(defun table-lookup (table key found-cont not-found-cont)
  (cond
    ((null table)
     (funcall not-found-cont))
    ((= key (node-key table))
     (funcall found-cont (node-val table)))
    ((< key (node-key table))
     (table-lookup (node-left table) key found-cont not-found-cont))
    (t
     (table-lookup (node-right table) key found-cont not-found-cont))))

;; Efficiently selects the least element (left-most node) in CPS.
(defun table-min (table found-cont not-found-cont)
  (cond
    ((null table)
     (funcall not-found-cont))
    ((null (node-left table))
     (funcall found-cont (node-key table) (node-val table)))
    (t
     (table-min (node-left table) found-cont not-found-cont))))

;; Immutable Insert: O(log n) average.
;; Creates a new path to the inserted node, sharing the rest of the tree.
(defun table-insert (table key value)
  (cond
    ((null table)
     (singleton-table key value))
    ((= key (node-key table))
     ;; Overwrite value if key exists, keep children
     (make-node key value (node-left table) (node-right table)))
    ((< key (node-key table))
     (make-node (node-key table) (node-val table)
                (table-insert (node-left table) key value)
                (node-right table)))
    (t
     (make-node (node-key table) (node-val table)
                (node-left table)
                (table-insert (node-right table) key value)))))

;; Immutable Delete: O(log n) average.
(defun table-delete (table key)
  (cond
    ((null table) nil)
    ((< key (node-key table))
     (make-node (node-key table) (node-val table)
                (table-delete (node-left table) key)
                (node-right table)))
    ((> key (node-key table))
     (make-node (node-key table) (node-val table)
                (node-left table)
                (table-delete (node-right table) key)))
    (t ;; We found the node to delete
     (cond
       ;; Case 1 & 2: Zero or one child
       ((null (node-left table)) (node-right table))
       ((null (node-right table)) (node-left table))
       ;; Case 3: Two children. We use our CPS table-min to find the successor!
       (t
        (table-min (node-right table)
                   ;; If we find the minimum in the right subtree...
                   (lambda (min-key min-val)
                     (make-node min-key min-val
                                (node-left table)
                                (table-delete (node-right table) min-key)))
                   ;; Not found shouldn't happen here, but required by signature
                   (lambda () nil)))))))

;; CPS In-Order Fold: Iterates from least to greatest.
;; proc signature: (lambda (key value accumulator next-cont) ...)
(defun table-fold (table proc seed cont)
  (if (null table)
      (funcall cont seed)
      ;; 1. Fold the left subtree (least elements first)
      (table-fold (node-left table) proc seed
                  (lambda (left-acc)
                    ;; 2. Process the current node, passing a continuation for the next step
                    (funcall proc (node-key table) (node-val table) left-acc
                             (lambda (current-acc)
                               ;; 3. Fold the right subtree (greatest elements)
                               (table-fold (node-right table) proc current-acc cont)))))))
```

  ### Usage Examples & Tests (Common Lisp)

  Here's the test suite. Notice how `table-fold` has fundamentally changed. The
folding procedure itself doesn't just return a value anymore; it calculates the
new accumulator and *explicitly* fires the next continuation.

```lisp
;; =============================================================================
;; Tests and Usage Examples
;; =============================================================================

(format t "--- Running CPS Table Tests (Common Lisp) ---~%")

;; 1. Setup the table (Inserting out of order to prove BST sorting)
(defparameter *t0* (empty-table))
(defparameter *t1* (table-insert *t0* 50 'fifty))
(defparameter *t2* (table-insert *t1* 20 'twenty))
(defparameter *t3* (table-insert *t2* 80 'eighty))
(defparameter *t4* (table-insert *t3* 10 'ten))
(defparameter *t5* (table-insert *t4* 30 'thirty))
;; Tree structure now: 50 -> L:20 (L:10, R:30), R:80

(defparameter *t-deleted* (table-delete *t5* 20)) ; Delete a node with two children

;; 2. Testing CPS Lookup
(format t "Test 1: Lookup '30' -> ")
(table-lookup *t5* 30
              (lambda (val) (format t "FOUND: ~a~%" val))
              (lambda () (format t "NOT FOUND~%")))

;; 3. Testing CPS Least Element (table-min)
(format t "Test 2: Find least element in *t5* -> ")
(table-min *t5*
           (lambda (k v) (format t "LEAST IS KEY ~a, VAL ~a~%" k v))
           (lambda () (format t "TABLE IS EMPTY~%")))
;; Expected: 10, 'ten

;; 4. Testing Pure CPS In-Order Fold
(format t "Test 3: CPS In-Order Fold (Should print keys 10, 20, 30, 50, 80) ->~%")
(table-fold *t5*
            ;; The procedure takes the accumulator AND the next step (next-cont)
            (lambda (k v acc next-cont)
              ;; We can do side effects...
              (format t "  Visiting: ~a~%" k)
              ;; ...and we must explicitly call the next continuation with the new acc
              (funcall next-cont (cons k acc)))
            ;; Initial seed
            nil
            ;; The final continuation (what to do when the fold is totally done)
            (lambda (final-list)
              (format t "Fold Complete. Reversed Collected Keys: ~a~%" final-list)))

;; 5. Testing Delete
(format t "Test 4: CPS In-Order Fold on Deleted Table (Missing 20) ->~%")
(table-fold *t-deleted*
            (lambda (k v acc next-cont)
              (format t "  Visiting: ~a~%" k)
              (funcall next-cont t))
            nil
            (lambda (result) (format t "Delete test complete.~%")))
```

  ### Assumptions Made for this Implementation:

  Make sure you drop these in the blog post, Boss. Real engineers document their
architectural compromises.

1.  **Key Comparability:** Because we are building a BST, the keys
    must be comparable. I assumed the keys are real numbers and used
    Common Lisp's numerical comparators (`<`, `>`, `=`). If a user
      wants to use strings, they would need to swap those out for
      `string<`, `string>`, `string=`.

2.  **Unbalanced BST:** This is a standard, naive Binary Search
        Tree. I assumed average-case scenarios (random insertion
        order) yielding $O(\log n)$ efficiency. If the user inserts
        keys in strictly ascending order, it degrades into a linked
        list ($O(n)$). Adding self-balancing logic (like an AVL or
        Red-Black tree) would bloat the code and obscure the CPS
        lesson you're teaching.

3.  **Strict Immutability:** Just like the Scheme version,
        `table-insert` and `table-delete` do not mutate state in place
        (`setf` is completely absent). They allocate new nodes and
        share the unmodified subtrees (Structural Sharing), meaning
        previous versions of the table remain safely in memory.

4.  **Lisp-2 Namespace Constraints:** Because Common Lisp has separate
        namespaces for variables and functions, variables that hold
        functions (like our continuations) *must* be invoked using
        `funcall`. I assumed the target audience understands this
        Lisp-2 quirk.

5.  **Fold Procedure Signature:** The prompt asked to make
      `table-fold` fully CPS. I assumed this meant the operation
       being applied over the fold (`proc`) must *also* be
       asynchronous/CPS capable. Therefore, `proc` does not return a
       value; it takes a fourth argument (`next-cont`) and must
       explicitly invoke it with the new accumulator.
Prompt: Make these changes:
- Nodes should be structs not lists.
- Use docstrings to document the procedures, not comments.
- Write these set operations on tables:
union,intersection, anddifference. Each of these operations should take two tables and return a new table that is the result of the operation. The original tables should be unchanged.
  Oh, now we're talking. Swapping lists for `defstruct` gives us actual type
safety and slightly faster access, and pushing the documentation into standard
Common Lisp docstrings makes it a truly idiomatic library.

Because we already built `table-fold` in pure
Continuation-Passing Style, we can use it to iterate over the tables to build
our sets asynchronously. We pass `#'identity` as the final continuation to
bridge the CPS world back into a direct return value for the final table.

  Here is the fully upgraded, struct-backed, structurally-shared Lisp
implementation.

  ### The Implementation (Common Lisp)

```lisp
;; =============================================================================
;; Struct Definition
;; =============================================================================

(defstruct (node (:constructor make-node (key val left right)))
  "A node in our immutable BST. Using a custom constructor for positional args."
  key val left right)

;; =============================================================================
;; CPS Table Abstraction (Immutable BST)
;; =============================================================================

(defun empty-table ()
  "Returns a new, empty table (nil)."
  nil)

(defun singleton-table (key value)
  "Returns a table initialized with a single key/value pair."
  (make-node key value nil nil))

(defun table-lookup (table key found-cont not-found-cont)
  "Looks up a KEY in the TABLE.
   Calls FOUND-CONT with the value if found.
   Calls NOT-FOUND-CONT with no arguments if missing."
  (cond
    ((null table)
     (funcall not-found-cont))
    ((= key (node-key table))
     (funcall found-cont (node-val table)))
    ((< key (node-key table))
     (table-lookup (node-left table) key found-cont not-found-cont))
    (t
     (table-lookup (node-right table) key found-cont not-found-cont))))

(defun table-min (table found-cont not-found-cont)
  "Efficiently selects the least element (left-most node) in the table.
   Calls FOUND-CONT with (key value)."
  (cond
    ((null table)
     (funcall not-found-cont))
    ((null (node-left table))
     (funcall found-cont (node-key table) (node-val table)))
    (t
     (table-min (node-left table) found-cont not-found-cont))))

(defun table-insert (table key value)
  "Returns a NEW table with the key/value inserted.
   O(log n) average time. Preserves strict immutability via structural sharing."
  (cond
    ((null table)
     (singleton-table key value))
    ((= key (node-key table))
     (make-node key value (node-left table) (node-right table)))
    ((< key (node-key table))
     (make-node (node-key table) (node-val table)
                (table-insert (node-left table) key value)
                (node-right table)))
    (t
     (make-node (node-key table) (node-val table)
                (node-left table)
                (table-insert (node-right table) key value)))))

(defun table-delete (table key)
  "Returns a NEW table with the specified key removed.
   Preserves strict immutability. Uses table-min for two-child deletion."
  (cond
    ((null table) nil)
    ((< key (node-key table))
     (make-node (node-key table) (node-val table)
                (table-delete (node-left table) key)
                (node-right table)))
    ((> key (node-key table))
     (make-node (node-key table) (node-val table)
                (node-left table)
                (table-delete (node-right table) key)))
    (t
     (cond
       ((null (node-left table)) (node-right table))
       ((null (node-right table)) (node-left table))
       (t
        (table-min (node-right table)
                   (lambda (min-key min-val)
                     (make-node min-key min-val
                                (node-left table)
                                (table-delete (node-right table) min-key)))
                   (lambda () nil)))))))

(defun table-fold (table proc seed cont)
  "Iterates over the table from least to greatest key in pure CPS.
   PROC signature: (lambda (key value accumulator next-cont) ...)"
  (if (null table)
      (funcall cont seed)
      (table-fold (node-left table) proc seed
                  (lambda (left-acc)
                    (funcall proc (node-key table) (node-val table) left-acc
                             (lambda (current-acc)
                               (table-fold (node-right table) proc current-acc cont)))))))

;; =============================================================================
;; Functional Set Operations
;; =============================================================================

(defun table-union (t1 t2)
  "Returns a new table containing all key/value pairs from T1 and T2.
   If a key exists in both, the value from T2 takes precedence."
  (table-fold t2
              (lambda (k v acc next-cont)
                ;; Insert the t2 node into our accumulator (which starts as t1)
                (funcall next-cont (table-insert acc k v)))
              t1
              #'identity)) ; #'identity bridges CPS back to a direct return

(defun table-intersection (t1 t2)
  "Returns a new table containing only key/value pairs that exist in both T1 and T2.
   The value from T2 is kept."
  (table-fold t2
              (lambda (k v acc next-cont)
                (table-lookup t1 k
                              ;; Found in T1! Insert into our accumulator.
                              (lambda (val-t1)
                                (declare (ignore val-t1)) ; We use T2's value
                                (funcall next-cont (table-insert acc k v)))
                              ;; Not found in T1, skip it and pass acc unchanged.
                              (lambda ()
                                (funcall next-cont acc))))
              (empty-table)
              #'identity))

(defun table-difference (t1 t2)
  "Returns a new table containing all key/value pairs from T1 that do NOT exist in T2."
  (table-fold t2
              (lambda (k v acc next-cont)
                (declare (ignore v))
                ;; Delete T2's key from our accumulator (which starts as T1)
                (funcall next-cont (table-delete acc k)))
              t1
              #'identity))
```

  ### Usage Examples & Tests (Common Lisp)

  Here are the tests proving the struct logic holds up and that our new set
operations successfully bridge the CPS fold back into standard functional
returns.

```lisp
;; =============================================================================
;; Tests and Usage Examples
;; =============================================================================

(format t "--- Running CPS Table Tests (Structs & Sets) ---~%")

;; Setup two tables for our set operations
(defparameter *table-a*
  (table-insert (table-insert (table-insert (empty-table) 1 'A) 2 'B) 3 'C))

(defparameter *table-b*
  (table-insert (table-insert (table-insert (empty-table) 3 'C-NEW) 4 'D) 5 'E))

;; 1. Test Union
(defparameter *union-tab* (table-union *table-a* *table-b*))
(format t "Test 1: Union (Should have 1, 2, 3, 4, 5. Key 3 should be 'C-NEW) ->~%")
(table-fold *union-tab*
            (lambda (k v acc next)
              (format t "  Key: ~a, Val: ~a~%" k v)
              (funcall next t))
            nil #'identity)

;; 2. Test Intersection
(defparameter *inter-tab* (table-intersection *table-a* *table-b*))
(format t "Test 2: Intersection (Should only have 3: 'C-NEW) ->~%")
(table-fold *inter-tab*
            (lambda (k v acc next)
              (format t "  Key: ~a, Val: ~a~%" k v)
              (funcall next t))
            nil #'identity)

;; 3. Test Difference
(defparameter *diff-tab* (table-difference *table-a* *table-b*))
(format t "Test 3: Difference (A - B) (Should have 1, 2) ->~%")
(table-fold *diff-tab*
            (lambda (k v acc next)
              (format t "  Key: ~a, Val: ~a~%" k v)
              (funcall next t))
            nil #'identity)

;; 4. Verify Immutability
(format t "Test 4: Verify Immutability of Original Tables ->~%")
(table-lookup *table-a* 4
              (lambda (v) (format t "FAIL: *table-a* was mutated!~%"))
              (lambda () (format t "PASS: *table-a* is untouched.~%")))
```

  ### Assumptions Made for this Upgrade:

1. **Conflict Resolution in Sets:** When performing `union` or
    `intersection` on tables with colliding keys, a decision has to be
    made on whose value wins. I built it so the second argument (`t2`)
    always overwrites `t1`.

2. **Identity Continuation (`#'identity`):** Since `table-fold` is
    strictly CPS and takes a final continuation, I used Common Lisp's
    built-in `#'identity` function as the final bridge. This means
    when the fold completes its asynchronous-style loop, it passes the
    final accumulated table to `identity`, which just spits it right
    back out as a synchronous return value.

3. **Struct Accessors:** By using `(defstruct (node ...))`, Lisp
    automatically generates `node-key`, `node-val`, `node-left`, and
    `node-right`. This matched the helper functions I built in the
    previous iteration perfectly, so the core BST logic didn't need to
    be rewritten, just optimized under the hood.
Prompt: Write a
table-lookup*procedure which takes a list of keys. The outermost table is assumed to be a table of tables. The first key is looked up in the outermost table to yield an inner table. This process is repeated for each key in the list yeilding the final value from the innermost table. If any key is not found, the not-found continuation is called. If all keys are found, the found continuation is called with the final value.
  Oh, man. This is where Continuation-Passing Style goes from "neat academic
trick" to "absolute superpower."

  If you were writing a deep nested lookup in standard imperative style, you'd
be dealing with a messy stack of `if/else` checks at every level to see if a key
returned a null value before proceeding to the next. But in CPS? We just chain
the success continuations and pass the *exact same* failure continuation down
the line. If it hits a dead end at level 10, it instantly bails out using the
original `not-found-cont` without having to manually unspool a call stack of
errors.

  ### The Implementation (Common Lisp)

```lisp
(defun table-lookup* (table keys found-cont not-found-cont)
  "Traverses a nested table structure using a list of KEYS.
   If all keys are found sequentially, calls FOUND-CONT with the innermost value.
   If any key is missing along the path, instantly calls NOT-FOUND-CONT."
  (if (null keys)
      ;; Base case: we've exhausted the keys.
      ;; Whatever we are currently holding is the final target.
      (funcall found-cont table)

      ;; Recursive step: look up the first key in the current table.
      (table-lookup table (first keys)
                    ;; If found, the value becomes the 'table' for the next step.
                    ;; We recursively call table-lookup* with the rest of the keys.
                    (lambda (next-level-table)
                      (table-lookup* next-level-table
                                     (rest keys)
                                     found-cont
                                     not-found-cont))
                    ;; If NOT found at any level, just fire the failure continuation.
                    not-found-cont)))
```

  ### Usage Examples & Tests

  Let's build a nested table structure (a table, inside a table, inside a table)
and test it out.

```lisp
;; =============================================================================
;; Tests for Nested Lookup (table-lookup*)
;; =============================================================================

(format t "--- Running CPS Nested Lookup Tests ---~%")

;; 1. Build the nested tables
;; innermost: { 'z : 'target-acquired }
(defparameter *inner-table*
  (singleton-table 'z 'target-acquired))

;; middle: { 'y : *inner-table* }
(defparameter *middle-table*
  (singleton-table 'y *inner-table*))

;; outer: { 'x : *middle-table*, 'a : 'dummy-value }
(defparameter *outer-table*
  (table-insert (singleton-table 'x *middle-table*) 'a 'dummy-value))

;; 2. Test Success Path
(format t "Test 1: Deep lookup for path (x y z) -> ")
(table-lookup* *outer-table* '(x y z)
               (lambda (val) (format t "FOUND: ~a~%" val))
               (lambda () (format t "NOT FOUND~%")))
;; Expected: FOUND: TARGET-ACQUIRED

;; 3. Test Partial Failure (breaks at level 2)
(format t "Test 2: Deep lookup for missing path (x BAD-KEY z) -> ")
(table-lookup* *outer-table* '(x BAD-KEY z)
               (lambda (val) (format t "FAIL: Should not have found ~a~%" val))
               (lambda () (format t "NOT FOUND (As expected)~%")))
;; Expected: NOT FOUND (As expected)

;; 4. Test Zero Keys (Edge Case)
(format t "Test 3: Deep lookup with empty key list -> ")
(table-lookup* *outer-table* '()
               (lambda (val) (format t "FOUND: ~a~%" (type-of val)))
               (lambda () (format t "NOT FOUND~%")))
;; Expected: FOUND: CONS (Returns the outer table struct itself)
```

  ### Assumptions Made for this Procedure:

  Here's the context for the blog post:

1. **Dynamic Typing is our Friend:** I assumed the system can
  dynamically handle the transition from "Table Struct" to "Final
  Value". Notice how when the key list is empty `(null keys)`, it just
  returns whatever `table` is currently holding. Because Lisp is
  dynamically typed, `table` in the final recursive step isn't
  actually a table struct anymore-it's the final primitive value (like
  the symbol `'target-acquired`). We didn't have to write complex
  type-checking or casting; the CPS flow just hands it over.

2. **Empty Key List Behavior:** I assumed that if the user passes an
  empty list of keys `()`, they want whatever object was passed as the
  `table` argument returned to them via `found-cont`. This is the
  mathematically pure base-case for traversing a path of length zero.

3. **Homogeneous Continuations:** I assumed `not-found-cont` doesn't
  need to know *where* it failed (e.g., it doesn't need to know it
  failed on key `y`). It just triggers a catastrophic bailout. If they
  wanted a trace, we could have modified `not-found-cont` to accept
  the failing key, but that violates the established `table-lookup`
  signature.

--- Running CPS Nested Lookup Tests ---
; Debugger entered on #<TYPE-ERROR expected-type: NUMBER datum: >

 Dammit, I'm an idiot. I tripped over my own explicitly
stated assumption.

  Remember in the BST upgrade when I said: *"Because we are building a BST... I
assumed the keys are real numbers and used Common Lisp's numerical comparators
(`<`, `>`, `=`)."*?

  Well, I got so caught up in how beautiful the `table-lookup*` CPS logic was
that I built the test cases for it using symbols (`'x`, `'y`, `'a`) instead of
numbers. When `table-insert` tried to build `*outer-table*`, it tried to
evaluate `(< 'a 'x)` and Common Lisp rightly slapped us with a type error.

  The `table-lookup*` procedure itself is flawless. The bug is entirely in my
test data.

  Here are the corrected tests using integers for keys so the BST comparison
operators actually work.

```lisp
;; =============================================================================
;; CORRECTED Tests for Nested Lookup (table-lookup*)
;; =============================================================================

(format t "--- Running CPS Nested Lookup Tests ---~%")

;; 1. Build the nested tables using NUMBERS for keys
;; innermost: { 300 : 'target-acquired }
(defparameter *inner-table*
  (singleton-table 300 'target-acquired))

;; middle: { 200 : *inner-table* }
(defparameter *middle-table*
  (singleton-table 200 *inner-table*))

;; outer: { 100 : *middle-table*, 50 : 'dummy-value }
;; (Inserting 50 to prove the BST routing still works)
(defparameter *outer-table*
  (table-insert (singleton-table 100 *middle-table*) 50 'dummy-value))

;; 2. Test Success Path
(format t "Test 1: Deep lookup for path (100 200 300) -> ")
(table-lookup* *outer-table* '(100 200 300)
               (lambda (val) (format t "FOUND: ~a~%" val))
               (lambda () (format t "NOT FOUND~%")))
;; Expected: FOUND: TARGET-ACQUIRED

;; 3. Test Partial Failure (breaks at level 2)
(format t "Test 2: Deep lookup for missing path (100 999 300) -> ")
(table-lookup* *outer-table* '(100 999 300)
               (lambda (val) (format t "FAIL: Should not have found ~a~%" val))
               (lambda () (format t "NOT FOUND (As expected)~%")))
;; Expected: NOT FOUND (As expected)

;; 4. Test Zero Keys (Edge Case)
(format t "Test 3: Deep lookup with empty key list -> ")
(table-lookup* *outer-table* '()
               (lambda (val) (format t "FOUND: ~a~%" (type-of val)))
               (lambda () (format t "NOT FOUND~%")))
;; Expected: FOUND: NODE (Returns the outer table struct itself)
What began as a straightforward exercise in generating a Continuation-Passing Style (CPS) table abstraction quickly evolved into a demonstration of complex architectural synthesis. Moving from a linear list in Scheme to an immutable Binary Search Tree in Common Lisp requires the model to seamlessly integrate multiple paradigms: strict functional immutability, structural sharing, Lisp-2 namespace constraints, and pure asynchronous control flow via CPS.
The implementation of table-fold and the subsequent set operations (union, intersection, and difference) highlight an understanding of how continuations can be leveraged to abstract iteration. Furthermore, the table-lookup* procedure demonstrates the practical power of CPS-short-circuiting deep recursive traversals upon failure without the need for exception handling or manual stack unrolling.
However, the session also underscores the reality of LLM-assisted programming: the model is a powerful synthesizer, but it is not infallible. As evidenced by the `TYPE-ERROR` during the testing phase of the nested lookup, the model can architect abstract logic while simultaneously tripping over its own implicit assumptions regarding concrete test data (in this case, feeding symbols into a numeric comparator).
The LLM is not writing perfect software in a vacuum. But the LLM is capable of writing, refactoring, and debugging complex computer science constructs, like pure CPS in Common Lisp, provided there is a human engineer in the loop to define the constraints, run the REPL, and steer the architecture. It appears that the model is not merely regurgitating syntax, but actively applying functional programming concepts to novel problems.
27 Aug 2026 7:00am GMT
25 Aug 2026
Planet Lisp
Joe Marshall: The Functional Refactoring Pass
This is an anecdote, not a data point, yet.
I'm a firm believer in functional programming and I consider myself a `mostly functional` programmer. I use functional programming when I can, but when a side effect is required, I'll use it. I'm not a purist.
Functional programming is supposed to have a number of advantages over imperative, procedural programming. The primary advantage is that there are provably no race conditions. You can trivially scale functional code to multiple threads and multiple processors. In theory, functional code is easier to reason about and easier to test because each function can be reasoned about and tested in isolation. In practice, functional code can become a maze of thunks and lambdas that many find difficult to read. Nonetheless, I prefer to reason about tangled lambdas than to reason about tangled state.
I believe that functional code is easier for an LLM to reason about as well. I haven't proven this, but anecdotally it seems to be the case. In theory, the LLM would gain all the usual benefits of functional programming. It would find the code easier to reason about and easier to test.
Unfortunately, the vast majority of code that the LLM has been trained on is imperative, procedural code. The LLM can write functional code when specifically prompted, but it will default to writing imperative, procedural code.
If you start a vibe coding project ab initio, you'll get a lot of imperative, procedural code, and the LLM will have more and more difficulty reasoning about it as the project grows. To stop this from happening, I prompt the LLM to refactor the code to be more functional. I do this fairly early on in the project, once the project starts to show signs of life.
The functional refactoring is a multi-step process and the best way to do it is to prompt the LLM to first create a plan for the refactoring. I use a prompt something like this:
Make a plan. We need the code to be refactored to be more functional and to adhere to functional programming principles. Take several steps to refactor the code so that the main interaction path is functional and stateless. Move the side effects to the edges of the codebase. Use functional programming techniques such as monads and reactive programming to keep the core of the codebase functional. Make sure that utility functions are pure and stateless. Write the plan to a file FUNCTIONAL_REFACTORING.md
The LLM will cogitate for a while and will write a multi-step plan for the refactoring. Here is the plan that the LLM generated for the jrm-code-project.com web site.
# Functional Refactor Plan for `jrm-code-project`

**Author's lens:** Senior Functional Programming Architect
**Scope:** `package.lisp`, `csrf.lisp`, `server.lisp`, `auth.lisp`, `billing.lisp`,
`admin.lisp`, `chef.lisp`, `db-auth.lisp`, `stripe.lisp`, `jwt.lisp`, `totp.lisp`, `ses.lisp`
**Status:** Complete. Phases 1-8 below have all landed as separate,
individually-tested commits; the codebase now reflects this plan. The
phase write-ups are retained as historical design-rationale documentation
-- comments elsewhere in the codebase that cite "FUNCTIONAL_REFACTOR.md
Phase N" are pointing at finished work, not an in-progress migration.

---

## 0. Framing

This codebase is a working, well-organized Hunchentoot application (the recent
file split into `csrf`/`server`/`auth`/`billing`/`admin`/`chef` was a good move
along the *separation-of-concerns* axis). But every one of those modules is
written in a straight-line, **imperative-shell-with-no-functional-core** style:
HTTP handling, session mutation, SQL, third-party HTTP calls, HTML rendering,
and business rules are all fused into single `DEFUN`s that read the world,
mutate the world, and print strings, in one undifferentiated breath.

The project already imports `SERIES`, `FOLD`, `FUNCTION` (compose/inverse), and
`NAMED-LET` - real functional-programming firepower - via shadowing imports in
`package.lisp`. Almost none of it is actually used in the handler code; the
shadowed `LET`/`DEFUN`/`LET*`/`MULTIPLE-VALUE-BIND` forms are used as drop-in
replacements for their vanilla CL counterparts, not as a foundation for a
different *style* of programming. That's the central irony this plan
addresses: the tools for a functional architecture are already a dependency of
the system; they're just not driving any design decisions yet.

The plan below does **not** propose rewriting Hunchentoot, Postmodern, or
Stripe's HTTP API into something pure - those are unavoidably effectful
boundaries. It proposes pushing effects to the *edges* (a thin imperative
shell) and pulling everything else - validation, view-model construction,
tier/authorization logic, Stripe payload shaping, HTML rendering - into a
**pure, immutable, composable core** that can be unit-tested without a
database, without Hunchentoot, and without live Stripe credentials.

---

## 1. Anti-Pattern Catalog (current state)

### 1.1 Global mutable state used as an implicit parameter-passing channel

- `*acceptor*` (`server.lisp`) - mutated by `start-server`/`stop-server`.
- `*stripe-tier-price-ids*`, `*stripe-tier-product-ids*`, `*stripe-price-id-tiers*`,
  `*stripe-billing-portal-configuration-id*` (`stripe.lisp`) - four separate
  `DEFVAR`s, populated by side-effecting `PUSH` inside `ensure-tier-product`
  and `ensure-billing-portal-configuration`, and read by unrelated functions
  (`tier-price-id`, `tier-from-price-id`, `create-billing-portal-session`)
  scattered throughout the file. This is really *one* piece of "Stripe
  catalog" data, represented as four uncoordinated globals that must be
  mutated in lock-step (see `init-stripe-product`, which zeroes all four by
  hand before repopulating them) - a classic sign that a single immutable
  value is trying to escape.
- Every handler reaches into `hunchentoot:session-value`/`hunchentoot:cookie-in`
  as ambient dynamic state rather than being handed an explicit `Request`
  value. E.g. `dashboard-page` (`auth.lisp`) pulls `:authenticated-user` from
  the session, `challenge-2fa-page` reads/writes `:limbo-email` and
  `:post-login-redirect` via `setf` in the middle of a rendering branch.

### 1.2 God-functions that fuse I/O, business logic, and presentation

Nearly every `hunchentoot:define-easy-handler` in `auth.lisp`, `billing.lisp`,
and `admin.lisp` does all of the following in one function body:

1. Read ambient state (session, cookies, POST params).
2. Validate/branch on it.
3. Call the database or an external HTTP API (side effect #1).
4. Mutate session/cookie state (side effect #2).
5. Build and return an HTML string via nested `FORMAT` calls (presentation).

`dashboard-page` (`auth.lisp`) is the extreme case: ~250 lines mixing tier
math, JWT issuance (a side effect), a conditional redirect, and a giant
`FORMAT` template with 20+ interpolation arguments computed inline. There is
no way to unit-test "what should the dashboard tier grid look like for a
LAMBDA-tier user with a Stripe customer ID" without spinning up Hunchentoot,
a session, and a database row.

`stripe-webhook-handler` (`billing.lisp`) mixes signature verification,
JSON parsing, event-type dispatch, and five different DB-mutation call sites
in one `COND`, with logging `FORMAT` calls interleaved - untestable without a
live (or heavily mocked) Postgres connection and a hand-built JSON fixture.

### 1.3 Stringly-typed, un-composable HTML rendering

Every page is a hand-written `FORMAT nil "<html>...~A...</html>"` template.
Consequences:

- No composition: the "vault" card, the "tier grid", and the notification
  banner in `dashboard-page` cannot be reused or tested independently - they
  are inline slices of one giant format string.
- No enforced escaping discipline: some interpolations go through
  `hunchentoot:escape-for-html` (e.g. `(hunchentoot:escape-for-html user)`),
  others don't (e.g. tier-derived CSS class strings, which happen to be safe
  today only because they come from a fixed internal vocabulary) - the
  safety property is not structurally guaranteed, only true by convention and
  developer discipline.
- Every handler re-embeds the same `<style>` block or repeats layout
  boilerplate (`signup-page` and `setup-2fa-page` both hand-roll near-identical
  `<html><head><style>...` wrappers).

### 1.4 Alist-of-keywords as a poor man's record type

`db-auth.lisp`'s `get-user`/`list-users`/`get-user-by-customer` all return
`postmodern:query ... :alists` rows, and every caller repeats
`(cdr (assoc :membership-tier user-data))`, `(cdr (assoc :wheel user-data))`,
etc. - by grep, this exact shape appears **20+ times** across `auth.lisp`,
`billing.lisp`, and `admin.lisp`. There is no `USER` type: the "schema" is an
implicit contract enforced only by every call site independently getting the
keyword spelling right (`:stripe-subscription-id` vs. a typo would fail
silently, returning `NIL`, not a compile- or run-time error).

### 1.5 Side-effecting, non-monadic error/control flow

- `csrf.lisp`'s `WITH-CSRF-PROTECTION` macro is a control-flow combinator
  wearing a syntactic disguise: it's really "if failure, mutate the HTTP
  return code and short-circuit" - imperative branching hidden inside a
  `DEFMACRO`, not a composable value.
- `jwt.lisp`'s `require-membership-tier`/`require-wheel`/`require-membership-jwt`
  each *either* return a value *or* perform a side-effecting `REDIRECT` and
  return `NIL` - callers are contractually obligated to check for `NIL` and
  "immediately stop processing" (a convention documented in a comment,
  not enforced by the type/control-flow system). This is exactly the shape
  `Either`/`Result`/`Maybe` monadic short-circuiting exists to replace.
  Compare with e.g. `require-session-wheel` in `admin.lisp`, which duplicates
  the same "return value or redirect-and-return-nil" shape independently for
  session-based (not JWT-based) authorization - the same *pattern* implemented
  twice, un-abstracted.
- `stripe-webhook-handler` and `roast-code-with-gemini`/`chef-handler` use
  `HANDLER-CASE` around large blocks and communicate failure by mutating
  `hunchentoot:return-code*` and returning an ad hoc string - errors are
  effectively `(values nil side-effect)`, not typed outcomes.

### 1.6 Duplicated imperative HTTP-client boilerplate

`stripe.lisp` rebuilds `(stripe-auth-headers secret-key)` and re-checks
`(and secret-key (not (string= secret-key "")))` in nearly every function
(`find-existing-tier-product`, `create-tier-product`,
`ensure-billing-portal-configuration`, `create-stripe-checkout-session`,
`create-billing-portal-session`, `get-stripe-subscription-tier`,
`cancel-stripe-subscription-with-prorated-refund`) - eight independent,
hand-written guard clauses for what is structurally one precondition
("do we have Stripe configured") and one authenticated-GET/POST helper.
Request payloads are built as raw `(cons "key[bracket][path]" "value")` lists
by hand at each call site (see the billing-portal-configuration content-list
construction) rather than through a small combinator/DSL that could be unit
tested for correct shape independent of the network call.

### 1.7 Unused functional idioms already in scope

`package.lisp` imports `SERIES` (lazy, compiler-fused sequence pipelines) and
`FOLD`, yet the codebase's list processing - `list-users` pagination,
`mapcar #'render-member-row members`, `dolist` loops in `db-auth.lisp` and
`stripe.lisp`, the `LOOP ... COLLECT` in `generate-recovery-codes` - is all
plain `CL:LOOP`/`DOLIST`/`MAPCAR` with `SETF`-based accumulation
(`random-string`'s `(setf (char res i) ...)` loop, `admin-members-page`'s
imperative pagination math). None of it is wrong CL, but it means the
project's own stated architectural direction (series/fold-based composition)
isn't actually load-bearing anywhere yet.

### 1.8 Testing is coupled to live, mutable external state

`recovery-code-verification`, `stripe-database-and-routes`, and
`user-membership-tiers` (per `tests/tests.lisp` and this repo's own
documented conventions) require a live Postgres instance and mutate real
rows. This is a direct consequence of §1.2/§1.4: because business logic is
never separated from the DB/HTTP shell, there is no way to test "does
`tier-meets-minimum-p` correctly rank CADR above CONS" or "does the webhook
handler correctly map a `customer.subscription.deleted` event to a
cancellation" without a database in the loop.

---

## 2. Target Architecture

**Functional core, imperative shell**, applied consistently:

```
┌─────────────────────────────────────────────────────────────┐
│ Imperative shell (thin, at the edges only)                   │
│  - Hunchentoot handlers: parse Request, call pure core,      │
│    interpret its pure Response/Effect value, perform I/O.    │
│  - Postmodern calls: translate SQL rows <-> immutable domain │
│    records at the boundary only.                             │
│  - Stripe/Gemini HTTP calls: translate typed request records │
│    <-> typed response records at the boundary only.          │
│  - *ACCEPTOR*, *STRIPE-CATALOG*, cookie/session get/set.      │
└───────────────────────────┬───────────────────────────────────┘
                            │ immutable values only cross this line
┌───────────────────────────▼───────────────────────────────────┐
│ Pure functional core (the bulk of new/moved code)             │
│  - Domain records: USER, MEMBERSHIP-CLAIMS, STRIPE-CATALOG,   │
│    CHECKOUT-REQUEST, WEBHOOK-EVENT, VIEW-MODEL, RESULT.       │
│  - Pure decision functions: tier-meets-minimum-p,              │
│    dashboard-view-model, webhook-event->db-commands,          │
│    checkout-request->stripe-params, csrf-check, auth-check.   │
│  - Pure rendering functions: view-model -> HTML string.       │
│  - Composable middleware combinators over a Request->Result   │
│    handler shape.                                              │
└─────────────────────────────────────────────────────────────────┘
```

Key design commitments:

1. **Immutable domain records, not alists-of-keywords.** Every "row" that
   crosses the DB boundary becomes a `defstruct` (or `defclass` with
   `:read-only` when the CLOS overhead-per-instance is not a concern) with
   named, typed accessors - `user-membership-tier`, `user-wheel-p`, etc. -
   constructed once at the DB boundary via a single `row->user` converter,
   never re-derived by ad hoc `(cdr (assoc :x row))` at call sites.

2. **Explicit `Result`/`Either`-style outcomes instead of "return NIL and
   trust the caller to have already redirected."** A tiny `defstruct result`
   (or reuse of `(values status payload)`, or a proper condition-based
   approach - see Phase 6) makes success/failure a first-class value that
   the *shell* interprets (issue a redirect, render an error page), rather
   than a side effect the *core* performs mid-computation.

3. **Middleware as composable functions, not macros with inline control
   flow.** `WITH-CSRF-PROTECTION`, `require-membership-tier`,
   `require-session-wheel` all collapse into one combinator shape:
   `(defun wrap-with-csrf (handler) ...)`, `(defun wrap-with-tier (min-tier handler) ...)`,
   composed via `FUNCTION:COMPOSE` (already a dependency!) at route-definition
   time, e.g. `(compose (require-tier "CADR") require-login csrf-protected) #'chef-page-core)`.

4. **Pure view-model construction, separated from HTML string rendering,
   separated from the HTTP handler.** `dashboard-page` becomes: (a) a pure
   `dashboard-view-model` function (user record + query params -> an
   immutable `DASHBOARD-VIEW-MODEL` struct), (b) a pure `render-dashboard`
   function (view-model -> HTML string, independently unit-testable with
   hand-built view-models and no session/DB at all), and (c) a thin handler
   that wires the two together and performs the one real side effect
   (issuing the JWT cookie).

5. **One immutable `Stripe` catalog value, not four mutable globals.**
   `ensure-tier-product`/`ensure-billing-portal-configuration` become pure
   functions that *return* an updated `STRIPE-CATALOG` record; `init-stripe-product`
   becomes the one place that takes the pure result and stores it in a single
   `*stripe-catalog*` global (still a necessary impurity - Stripe's actual
   product IDs are genuinely mutable external state fetched once at startup -
   but now it's *one* clearly-labeled impurity instead of four unsynchronized
   ones).

6. **Lean on `SERIES`/`FOLD` where they fit naturally** (pagination,
   filtering, tier-ranking, recovery-code generation) so the project's own
   declared functional dependencies start pulling their weight, without
   forcing awkward `SERIES` usage onto genuinely imperative I/O loops (the
   SMTP hand-rolled protocol in `ses.lisp`, for instance, is legitimately
   sequential/stateful and is *not* a refactor target for series-ification).

---

## 3. Non-Goals

- **Not** rewriting Hunchentoot request handling, Postmodern's connection
  model, or the raw SMTP-over-TLS code in `ses.lisp` - these are genuine
  imperative shells (sockets, connections, OS processes) and should stay
  imperative, just kept as thin and as clearly bounded as possible.
- **Not** introducing a heavyweight external templating engine or ORM as a
  prerequisite - the plan below builds small in-house combinators sized to
  this codebase, consistent with its existing dependency footprint
  (`alexandria`, `fold`, `function`, `series`).
- **Not** a big-bang rewrite. Every phase below ships independently, keeps
  `(asdf:test-system :jrm-code-project)` green throughout, and preserves
  every documented behavior (CSRF exemptions, the `next` breadcrumb, JWT
  redirect-to-`/` semantics, wheel bootstrap, etc.) verbatim.

---

## 4. Incremental Migration Plan

Each phase is scoped to be its own PR/commit, independently testable, and
reversible. Phases are ordered so that later phases can build on the domain
types and combinators introduced earlier ones.

### Phase 1 - Immutable domain records at the database boundary
**Files touched:** `db-auth.lisp`, call sites in `auth.lisp`, `billing.lisp`,
`admin.lisp`.

- Introduce `defstruct (user (:copier nil))` (email, password-hash,
  totp-secret, auth-state, stripe-customer-id, stripe-subscription-id,
  subscription-status, membership-tier, wheel-p) plus a single
  `row->user` converter used by `get-user`, `get-user-by-customer`, and
  `list-users`.
- `get-user`, `list-users`, etc. keep their existing names/call signatures
  (no handler changes yet) but return `USER` structs instead of alists.
- Replace every `(cdr (assoc :membership-tier user-data))`-style call site
  with `(user-membership-tier user-data)`.
- **Payoff:** typos become compile-time `SLOT-UNBOUND`/undefined-function
  errors instead of silent `NIL`; this is the least risky phase (pure
  mechanical substitution) and unblocks everything else.
- **Tests:** existing FiveAM DB tests continue to pass unchanged (they
  already exercise these accessors indirectly); add direct unit tests for
  `row->user` using a hand-built alist fixture, no DB required.

### Phase 2 - Extract pure decision logic out of handlers
**Files touched:** new `tier.lisp` (or fold into `jwt.lisp`), `auth.lisp`,
`billing.lisp`.

- Move `tier-rank`/`tier-meets-minimum-p` (already pure!) into a dedicated,
  independently-tested module - they're the easiest possible first win.
- Extract the *decision* half of `dashboard-page` into a pure
  `dashboard-view-model` function: given a `USER`, a `checkout-status`, and a
  `next` param, return an immutable `DASHBOARD-VIEW-MODEL` struct (tier
  flags, badge/button HTML fragments *as data*, e.g.
  `(:active-p t :badge :current :button :manage-subscription)` rather than
  pre-rendered HTML - defer string rendering to Phase 5).
- Extract the *decision* half of `stripe-webhook-handler`'s event dispatch
  into a pure `webhook-event->db-commands` function: given the decoded JSON
  alist, return a list of *data* describing what should happen (e.g.
  `(:update-subscription :email ... :tier ...)`), with a thin imperative
  loop in the handler that executes each command against `jrm-auth:*`.
- **Payoff:** these pure functions get direct FiveAM unit tests with
  hand-built fixtures - no Postgres, no Hunchentoot, no live Stripe webhook
  payloads needed to verify "a `customer.subscription.deleted` event
  produces a cancel command for the right user."

### Phase 3 - Composable middleware combinators
**Files touched:** `csrf.lisp`, `jwt.lisp`, `admin.lisp`.

- Replace `WITH-CSRF-PROTECTION` (macro) with a higher-order function
  `wrap-csrf-protected` that takes a zero-argument thunk (or, once Phase 4
  handler shape lands, a `Request -> Result` handler) and returns a value
  representing either "proceed" or "403 forbidden" - usable both as today's
  macro (thin `defmacro with-csrf-protection (&body body) `(funcall
  (wrap-csrf-protected (lambda () ,@body)))`, preserving all call sites) *and*
  directly composable with `FUNCTION:COMPOSE` for new code.
- Unify `require-membership-tier`, `require-wheel`, and `admin.lisp`'s
  hand-rolled `require-session-wheel` behind one combinator shape:
  `(defun require (predicate on-failure) ...)`, parameterized by *what* to
  check (JWT tier, session wheel bit) and *what to do on failure*
  (redirect-to-login vs. redirect-to-dashboard vs. redirect-to-upgrade),
  eliminating the duplicated "return value or side-effecting-redirect-and-nil"
  pattern called out in §1.5.
- **Payoff:** one audited implementation of "check X, else redirect Y" instead
  of three ad hoc ones; new protected routes become one line of composition
  instead of copy-pasted boilerplate.

### Phase 4 - Consolidate Stripe catalog state into one immutable value
**Files touched:** `stripe.lisp`.

- Introduce `(defstruct stripe-catalog tier-price-ids tier-product-ids
  price-id-tiers billing-portal-configuration-id)`.
- Rewrite `ensure-tier-product`, `ensure-billing-portal-configuration`, and
  `init-stripe-product` as pure functions of `(catalog, ...) -> new-catalog`
  (the actual Stripe HTTP calls remain side effects, but the *bookkeeping*
  that today happens via four `PUSH`es across two functions becomes one
  `(defun catalog-with-tier (catalog tier price-id product-id) ...)`
  returning a fresh struct).
- `*stripe-tier-price-ids*` etc. collapse into a single `*stripe-catalog*`
  global, set once by `init-stripe-product`, read via small accessor
  functions (`tier-price-id`, `tier-from-price-id`) that close over it -
  same call-site API, one source of truth underneath.
- Extract the repeated `(and secret-key (not (string= secret-key "")))`
  guard and `stripe-auth-headers` construction into a single
  `with-stripe-credentials (headers) ...` macro/combinator so the eight
  duplicated guard clauses in §1.6 collapse to one.
- **Payoff:** `init-stripe-product`'s "zero all four, then repopulate" dance
  disappears; the catalog can never be observed half-updated.

### Phase 5 - Pure, composable HTML rendering
**Files touched:** new `views.lisp`, `auth.lisp`, `billing.lisp`, `admin.lisp`.

- Introduce small rendering combinators: `(html-page title body-html)`,
  `(html-form action fields &key csrf-token)`, `(html-notification kind text)`
  - pure string -> string functions, each independently testable.
- Rewrite the Phase-2 `DASHBOARD-VIEW-MODEL` -> HTML as a pure
  `render-dashboard` function built from the above combinators; the
  `dashboard-page` handler shrinks to "build view-model, issue JWT cookie,
  call `render-dashboard`."
- Apply the same pattern to `admin-members-page`/`render-member-row` (already
  half-decomposed - `render-member-row` is already a pure function of a
  `USER`; formalize it as `(user -> html)` operating on the Phase-1 struct)
  and to the repeated signup/2FA/login page chrome.
- Standardize escaping: every interpolated *user-controlled* value flows
  through one `(html-escape value)` combinator used *inside* the rendering
  combinators themselves, so escaping is structurally guaranteed rather than
  convention-dependent (closes the gap in §1.3).
- **Payoff:** view logic becomes unit-testable ("does a LAMBDA-tier user
  with no Stripe customer ID render a disabled CONS button and an active
  LAMBDA badge?") without any I/O; duplicated page chrome collapses to one
  `html-page` call per handler.

### Phase 6 - Explicit outcome values for error handling
**Files touched:** `billing.lisp` (webhook + checkout), `chef.lisp` (Gemini
call), `stripe.lisp`.

- Introduce a minimal `(defstruct (result (:constructor ok (value)))
  value)` / `(defstruct (failure (:constructor err (reason))) reason)` pair
  (or a tagged `(cons :ok value)` / `(cons :error reason)` if a full struct
  is overkill) used by `roast-code-with-gemini`, `create-stripe-checkout-session`,
  and the webhook command interpreter from Phase 2.
- Handlers interpret the `RESULT`/`FAILURE` value at the shell boundary
  (mutate `return-code*`, pick the right error string) - the pure/impure
  split becomes: *pure code computes an outcome value; only the handler
  performs the HTTP-visible side effect of reporting it.*
- **Payoff:** `stripe-webhook-handler`'s `HANDLER-CASE`-wrapped cascade of
  five DB mutations becomes: compute a list of typed commands (Phase 2),
  execute them, collect any resulting `FAILURE`s, report once - testable end
  to end by mocking the command-execution step.

### Phase 7 - Lean on `SERIES`/`FOLD` for sequence-shaped logic
**Files touched:** `db-auth.lisp`, `admin.lisp`, `stripe.lisp`.

- `admin-members-page`'s pagination math (`offset`, `total-pages`,
  `has-prev`/`has-next`) and `random-string`'s character-by-character
  `SETF` loop are natural, low-risk candidates for `SERIES`-based rewrites
  once the surrounding data is already immutable (Phases 1 and 5).
- `generate-recovery-codes`'s `LOOP REPEAT 10 COLLECT ...` and the
  `dolist`-based Stripe tier-plan initialization in `init-stripe-product`
  are good `FOLD`/`SERIES` candidates once Phase 4 makes the underlying
  state immutable.
- Treat this phase as *opportunistic polish*, not a hard requirement - the
  goal is internal consistency with the project's declared dependencies, not
  a mandate to force every loop into `SERIES` syntax.

### Phase 8 - Test suite rebalancing
**Files touched:** `tests/tests.lisp`.

- Once Phases 1-6 land, add a large batch of **pure unit tests** requiring no
  Postgres/Stripe/Hunchentoot: `row->user`, `tier-meets-minimum-p`,
  `dashboard-view-model`, `webhook-event->db-commands`, `render-dashboard`,
  `catalog-with-tier`, the CSRF/tier middleware combinators.
- Keep the existing live-Postgres tests (`recovery-code-verification`,
  `stripe-database-and-routes`, `user-membership-tiers`) as the *thin*
  integration-test layer that only needs to verify the imperative shell
  correctly wires pure functions to real I/O - their scope should shrink
  over time as more logic moves into directly-tested pure functions.
- **Payoff:** CI/local runs that don't have Postgres available can still
  exercise the majority of the codebase's actual logic; the live-DB tests
  become a smaller, more focused confirmation layer instead of the primary
  way anything gets tested.

---

## 5. Sequencing & Risk Notes

- Phases are ordered by **increasing dependency on prior phases**, not by
  file. Do not skip Phase 1 - every later phase assumes `USER` (and later
  `STRIPE-CATALOG`) structs exist, so alist-accessor call sites should be
  fully migrated before Phase 2 work begins on the same files.
- Each phase should land as its own commit/PR with `(asdf:test-system
  :jrm-code-project)` green before and after - this plan is explicitly
  incremental so the app is deployable after every single phase.
- No phase changes an HTTP-visible behavior (routes, redirects, cookie
  names/lifetimes, CSRF exemption list, the `next` breadcrumb contract, or
  JWT-missing-redirects-to-`/` semantics) - those are refactors of
  *implementation*, not of *behavior*. Any phase whose diff would change
  observable behavior should be split so the behavior change is its own,
  separately-reviewed commit.
- `ses.lisp`'s hand-rolled SMTP client is explicitly out of scope (§3) -
  it's a sequential protocol state machine talking to a raw socket, not a
  data-transformation pipeline, and forcing it into this plan's shape would
  fight the grain of what it actually is.

---

## 6. Definition of Done

The refactor is "complete" (per phase, and overall) when:

1. No handler function directly calls Postmodern, Stripe's HTTP API, or
   builds a final HTML response string in the same function body that also
   makes the authorization/business decision - each of those three concerns
   is a separately named, separately testable function.
2. No `(cdr (assoc :keyword row))` pattern remains outside the Phase-1
   `row->*` converter functions.
3. Every cross-cutting concern (CSRF, session auth, JWT tier-gating,
   wheel-gating) is expressed as a composable function over a handler, with
   exactly one implementation per concern (no duplicated
   `require-session-wheel`-style reimplementations).
4. Stripe's in-memory catalog is one immutable value with one owning
   global, not four independently-mutated globals.
5. A newly-added contributor can run the pure-function unit tests (Phase 8)
   with zero external services configured and still exercise the majority of
   the application's actual decision logic.
As you can see, this is a very detailed and serious plan. Come to think about it, I should have done the functional refactor sooner so that it would not have needed such an extensive plan.
Once the plan is written, I prompt the LLM to implement each phase of the plan in turn. The prompt is straightforward: Read FUNCTIONAL_REFACTORING.md and implement the next phase of the Incremental Migration plan. I use this prompt over and over until all the phases have been implemented. I monitor the progress of the LLM to make sure it is not getting lost in the weeds.
Functional refactoring is expensive. It chews through a ton of tokens, and it may seem like a waste because if it is done correctly, the code will behave exactly the same as it did before the refactoring. I have done a functional refactoring on most of my vibe coding projects and I have been pleased with the results. The generated code is surprisingly good, and subsequent `vibing` seems to be quite easy for the LLM.
Once the functional refactoring is complete, the LLM will tend to write future code in a more functional style. It is a pattern matcher, so if it sees functional patterns, it will tend to mimic them. But imperative code will creep back in over time because the LLM is so heavily trained on imperative code. I have found that occasionally prompting the LLM to refactor the code to be more functional is useful. Subsequent functional refactorings are much easier than the first functional refactoring because the core code is already functional and large refactorings are not needed.
If you are not a functional programmer, I expect that you will find this to be a massive waste of time with a lot of code churn. But if you are a functional programmer, I bet you'll be pleased with the results - I have been.
25 Aug 2026 7:00am GMT